The Reve API is here. Build with the world's best 4k image model – right in your own pipelines and agents.
For the first time, the layout model behind Reve is yours.
Released just a month after Reve 2.0, Reve 2.1 brings a real jump in visual intelligence and reasoning.
It lands 2nd overall, and remains the world's top 4K model, from an independent lab training on 10x fewer GPUs.
https://t.co/uuJqQ4NAXu
BREAKING: Reve 2.0 by @reve is now 2nd overall on Image Arena with an Elo of 1354.
Reve 2.0 establishes a 34 point Elo gap above GPT-Image 1.5 by @OpenAI in 3rd place.
With this release, Reve is now the top independent foundation image model lab.
Congratulations to the @reve team on this accomplishment!
Language made such a big impact on visual generative models because it balances three things at once: it's intuitive to use, expressive enough to describe complex scenes, and compact enough to condition on efficiently and at scale.
But that doesn't make natural language the perfect specification tool for images. It's vague, spatially meaningless, and incomplete — some visual specifics can only be approximated in words, never fully specified.
While going straight from text to visuals was a giant leap, this paradigm will not hold. Perhaps, it already doesn't. Today, we introduce Reve 2.0, a model with a dedicated intermediate representation — layout — that sits between user intent and finished image. Layout is structured and hierarchical: it explicitly specifies objects, their positions, sizes, colors, spatial relationships and more. You can read it, understand it, edit it, control it — and so can agents.
Layout is code for image.
Today we launched Reve 2.0! We built it from the ground up with a completely new architecture.
All visual generative models today use text as intermediate representation, leveraging Large Language Models to plan their outputs before rendering any pixels.
Natural language is expressive, but it is ambiguous. Ambiguity is the enemy of control.
Two years ago, we made a different bet. We replaced text with a better, code-like semantic representation — a layout.
Layout is the reason we can compete with models trained on 10× our compute. It opens up a whole new world of precise, non-verbal visual control.
Very proud of the Reve team for this incredible achievement!
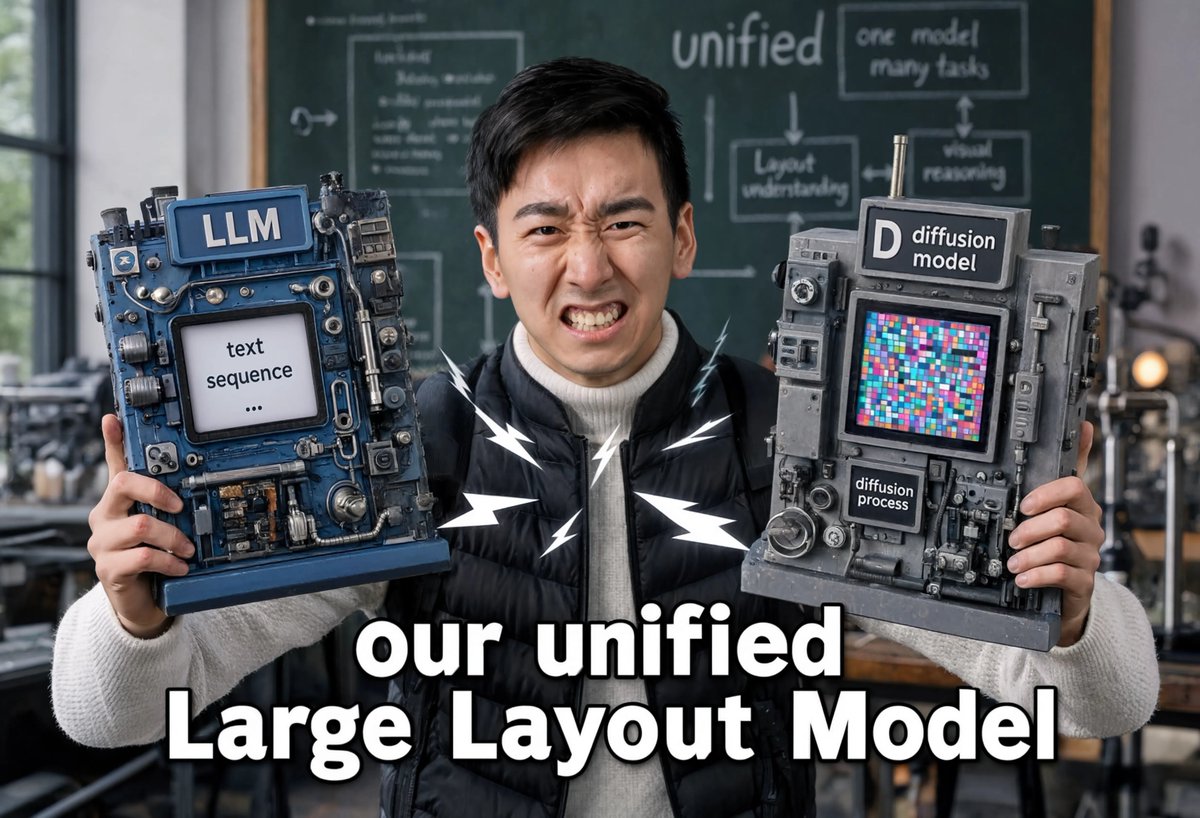
Competing with model giants with 10x more resources, how did we do it? Introducing Unified Layout Models.
We designed a new structured data format for images, based on hierarchical region conditioning. We call this "layouts". Think of it as SVG for pixels.
I joined @reve because I believed in the vision, and now I'm so proud to share that we have the #2 image model in the world, beating Nano Banana, and with a fraction of the GPUs our competitors use. We're a lean and mean, and we're just getting started.
I’ve always believed text prompts for image generation to be a bug, not a feature. Reve 2.0 fixes that. By making Large Layout Models a reality, we deliver the intuitive, hands-on control needed to make image generation truly useful, usable, and fun. So proud of our team!