Ok, that’s enough. I’ll try @[email protected].
Many good and ethical reasons to leave, but it’s the daily performance of utter mediocrity by Musk that does it for me.
He’s not funny, he’s not kind, he’s not clever, he’s not creative. I don’t owe him any of my attention.✌️
Let's assign CAP to the cabinet of curiosities: https://t.co/bvofLtIebw
If you’re an experienced distributed systems person teaching new folks about trade-offs in your space, please don’t start with CAP. Tons of more interesting, more instructive, trade-offs.
So here's a story of, by far, the weirdest bug I've encountered in my CS career.
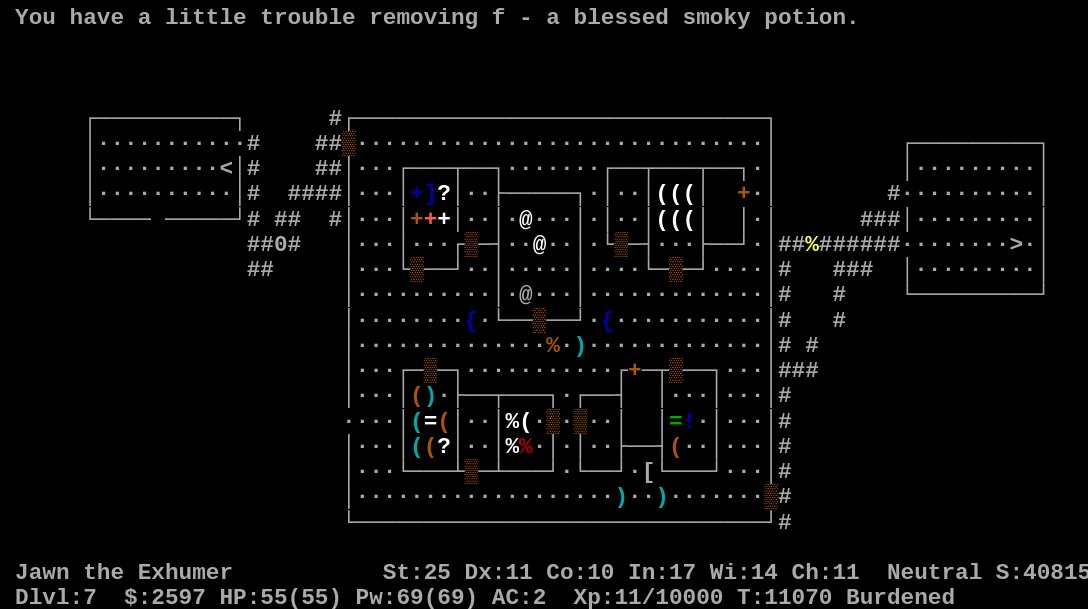
Along with @maciejwolczyk we've been training a neural network that learns how to play NetHack, an old roguelike game, that looks like in the screenshot. Recenlty, something unexpected happened.
@gwenshap TLDR: warm up scripts in dev read a channel’s history to warm some JIT caches by exercising common codepaths.
A message in a dev channel triggered a DB issue by requiring a large number of DB calls in order to be formatted correctly.
But! We only fetch the last 100 msgs. So..
I just fixed a DB overload problem at Slack (in dev) by manually typing 100 one-word messages into a channel, in case you were wondering what “senior” engineers do all day.
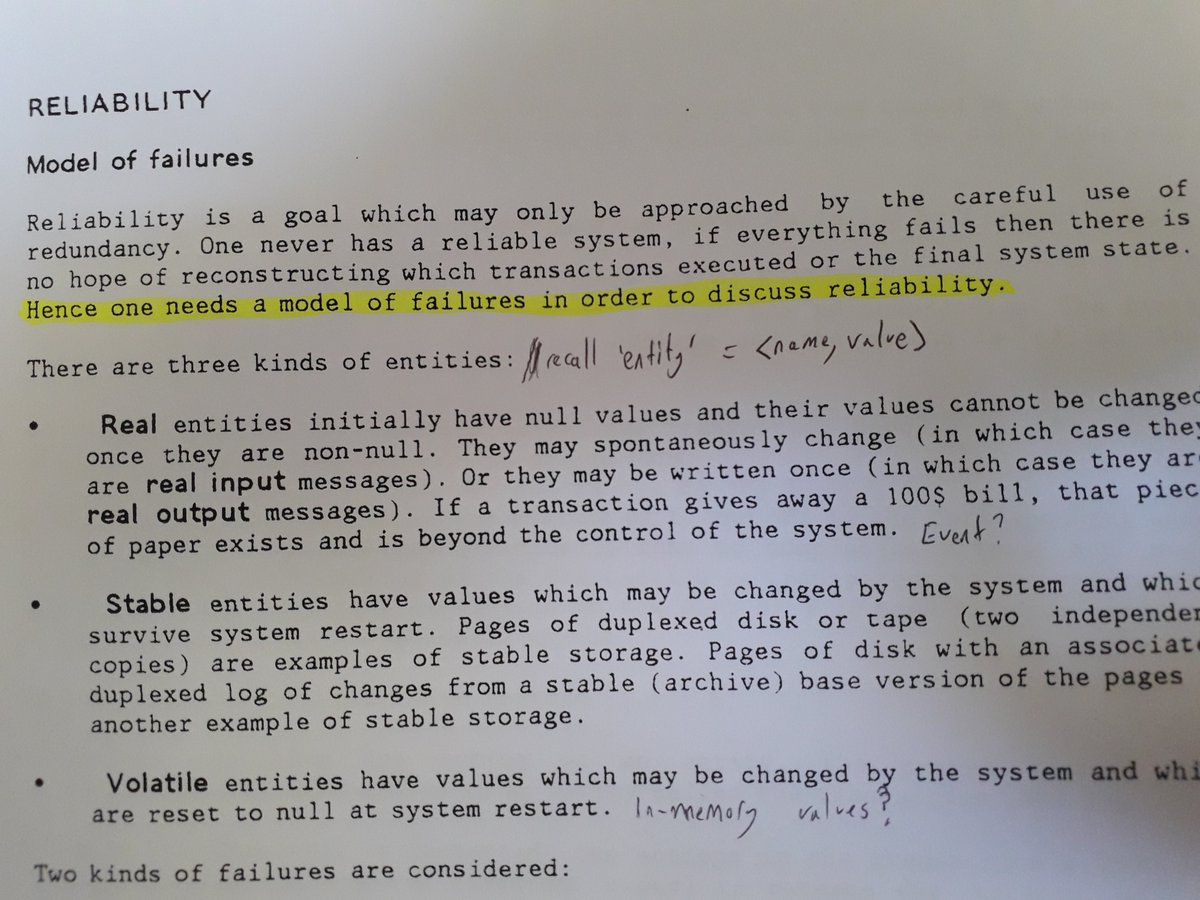
Fault models are like threat models and reliability is only meaningful with respect to a fault model.
Can’t read a dist sys paper without someone defining a system, or fault, model.
The P in CAP is actually a fault model.
You ever see the same term pop up in a few places and think "hmmm"?
@TigerBeetleDB often talks of "fault models". Wonder if theres more to this idea than I think.
(Paper is "A Transaction Model", Jim Gray, IBM Research Laboratory 1980)
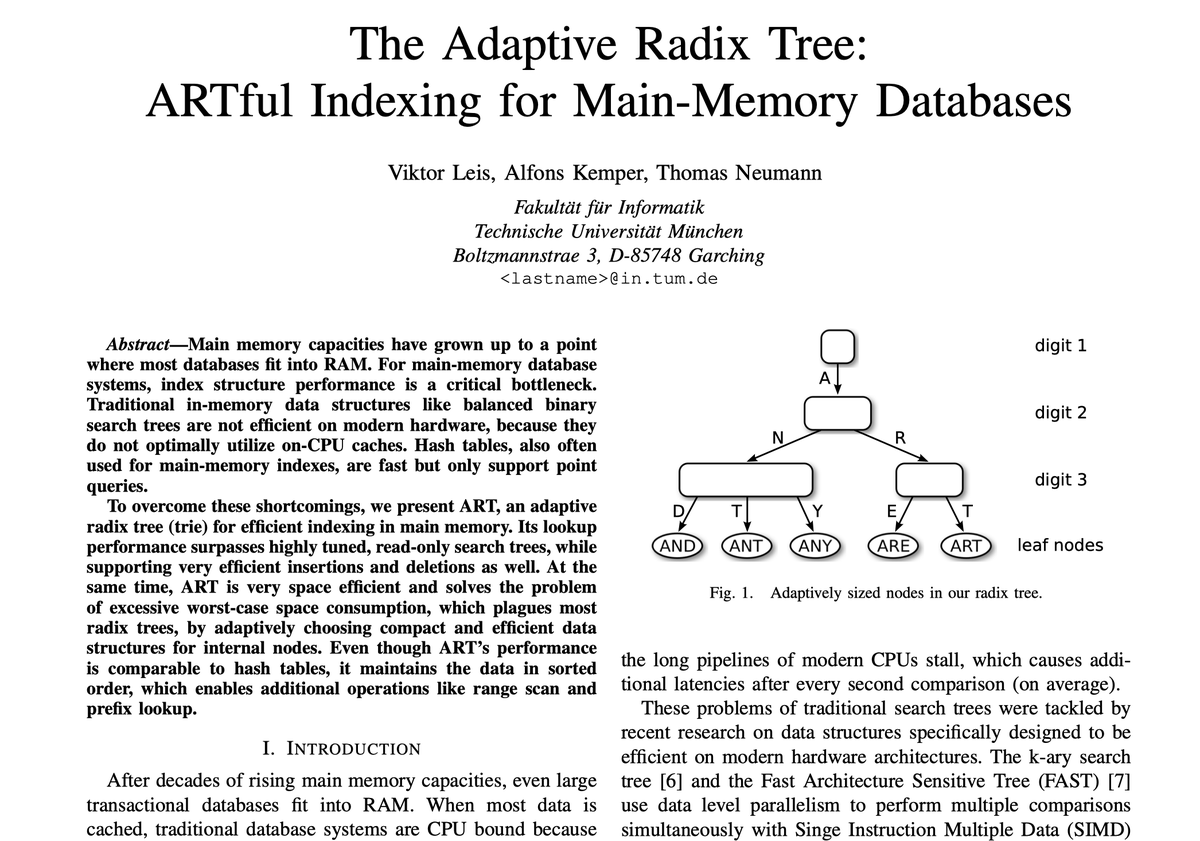
I wrote up Adaptive Radix Tries a few years ago, including details of how the the adaptations facilitate CPU-efficient search implementations:
https://t.co/YX4vD0viBT
Reading the Adaptive Radix Tree paper - Having the realisation that trie is such an underrated data structure. Wondering why we should use any other data structure for in memory database indexes.
Here are some rough notes from the paper ..
Tree based indexes (e.g. binary search tree or b-tree needs special care for cache friendliness, are expensive for updates and can show pipeline stall for branch misprediction.
Hash based indexes are great for point queries, not so for range queries, are expensive to grow with O(n) complexity for reorganisation.
Tries have O(k) complexity where k is the size of the key, which means independence from n (that is a HUGE plus). The trie height can be controlled through the span s of the radix tree and is usually smaller than the height of a binary search tree. Hence search can be faster - O(k) compared to O(k lg n) in BSTs. One problem with tries is they can have higher space consumption compared to trees. But ART manages this through variable sized data structures for inner nodes and leaves.
The paper is a great read ..