A few people understandably asked for the receipts here/how I would fix the eval/what embedding models are better.
If you keep the same queries and docs, compare to stronger embedding models, and use GPT 5.6 luna + blitzrank to rank order the top 100 documents given every document returned in the top 100 by any embedding model (or bm25) in the comparison, you get a very different result.
With enough queries, you don't really have to believe that luna's ordering is perfect, just high enough signal to help provide a rank ordered preference for these kinds of queries.
You can use a stronger llm if you want, improve the diversity of the queries, use more realistic docs (no 1k token chunk cutoff) as well but I doubt fixing those things would change the conclusion about the performance of the two open source late interaction models shown in the image (I added Iso-ModernColBERT).
I've also used fastplaid here for late interaction retrieval to side step a discussion about how accurate MUVERA is for each model. FastPLAID recall should be good enough that it's not the issue and it allows us to look at the effects of quantization.
voyage-context-4 dominates the agreement@20 vs storage space pareto frontier and is also the highest performing model on this eval (and most of my evals...)
you can also evaluate the pareto frontier through the cost of embedding inference. I've just made up some numbers here for the late interaction models bc they're not available via api. You could probably lower the inference cost further if you wanted. The others are priced at real api pricing when that is available.
there's nothing special about agreement@20 here. It's just a reasonable quick metric when you're using a search agent, the conclusion doesn't change of you pick ndcg, recall, or other @ values.
generally, I'd say the mLateOn model is doing better on this eval than other times I've benchmarked it. It typically underperform voyage-4-nano for me. Interestingly, the medical fine tune is under performing the base model on this eval.
@lateinteraction@ContextualAI LLM architectures responding to market demand? wild
This reminds me of the contextual vs parametric knowledge assessment mentioned here
https://t.co/W6rgjxYgw7
one of the more insightful conversations on ML-based IR I've heard- love the focus on problem-framing and the step backs that @lateinteraction takes at various points. Nice work getting this out @CShorten30
Hey everyone! I am BEYOND EXCITED to publish our interview with Omar Khattab (@lateinteraction) from @stanfordnlp! 🔥
Omar delivers remarkably clear explanations of DSPy and ColBERT, as well as views on the state of AI! I hope you find this useful! 🎙️
https://t.co/6kmlcItT4v
my current thinking on the vector db debate:
foundation model lab sherlocking and increasing context length were never the issue for the $235m invested in vector db companies this year
it’s the existing SQL and NoSQL databases so easily adding vector support that slash the TAM, since data gravity dominates for 90% of heavy usecases
vector db cos must innovate and lead on features/DX/perf or die trying
@langchain@MongoDB Parent/child relationships are only the beginning! You could model this recursively with $graphLookup, query multiple vectors for a single document and merge results together, and do so much more within the document model. More coming soon!
@dmythro It's likely that disk reads are what is causing the issue here- if you prewarm your cache with some representative queries to load the HNSW graph into memory you should see regular subsecond performance similar to other vector search engines.
E2E RAG and dedicated foundational models for search would be huge unlocks for information retrieval. Highly recommend listening to this insightful conversation from the Weaviate folks!
Beyond excited to publish our newest Weaviate Podcast with @Nils_Reimers! 🎙️🎉
Nils is one of my favorite people in the world to discuss Search with! Discussion topics include Cohere's Rerankers, Metadata, Long Doc Embeddings, RAG, and more!📚
https://t.co/SVG4lAgJnD
@deliprao The animosity is often motivated by self interest- it’s not perfect but is basically the Airflow of orchestrating LLM apps and good for getting projects started
@saranormous Is it maybe possible that these providers don’t want embeddings to be smaller because it means smaller HNSW graphs to index and query, meaning less $?
Vector search at scale needs more creative solutions than large graphs that are mostly stored in memory
@bernhardsson Extra weird when it’s software engineers proposing it on twitter but the project isn’t maintained at all - GitHub is the real PR agency
https://t.co/A0tuRAKlHu
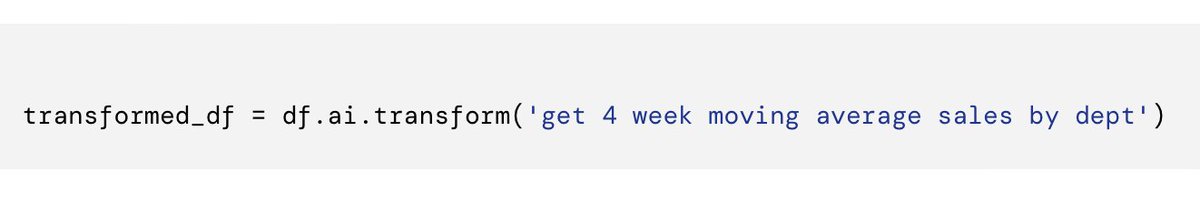
One of my favorite announcements: English SDK for @ApacheSpark! No more need to remember weird syntax, just chain transformations in natural language with the familiar Spark API. So many fun examples.
https://t.co/4JNfwPEElp
🍀LangChain x Mongo🍀
At today's developer conference @MongoDB announced their vector search offering
Excited to share that we've already got integrations with this up and running! s/o to `P-E-B` (python) and `floomby` (javascript) for adding
Blog: https://t.co/UdxZI0hgF8