Advice for AI engineers 💡
A small Visual Language Model fine-tuned on your custom dataset is as accurate as GPT-5...
... and costs 50 times less
For example, LFM2.5-VL-1.6B by @liquidai running locally at full speed with llama.cpp ↓
I’ve implemented SVMs three times in my life — first in MATLAB as a grad student, again in C++ during my postdoc, and finally by hand ✍️ as a professor who needed to truly understand it well enough to teach it. If you’re curious, here’s my full 19-step walkthrough: https://t.co/Ed5P1bFYFi
----
100% original, made by hand ✍️
Join 52K+ readers of my newsletter: https://t.co/fFt8roc8D9
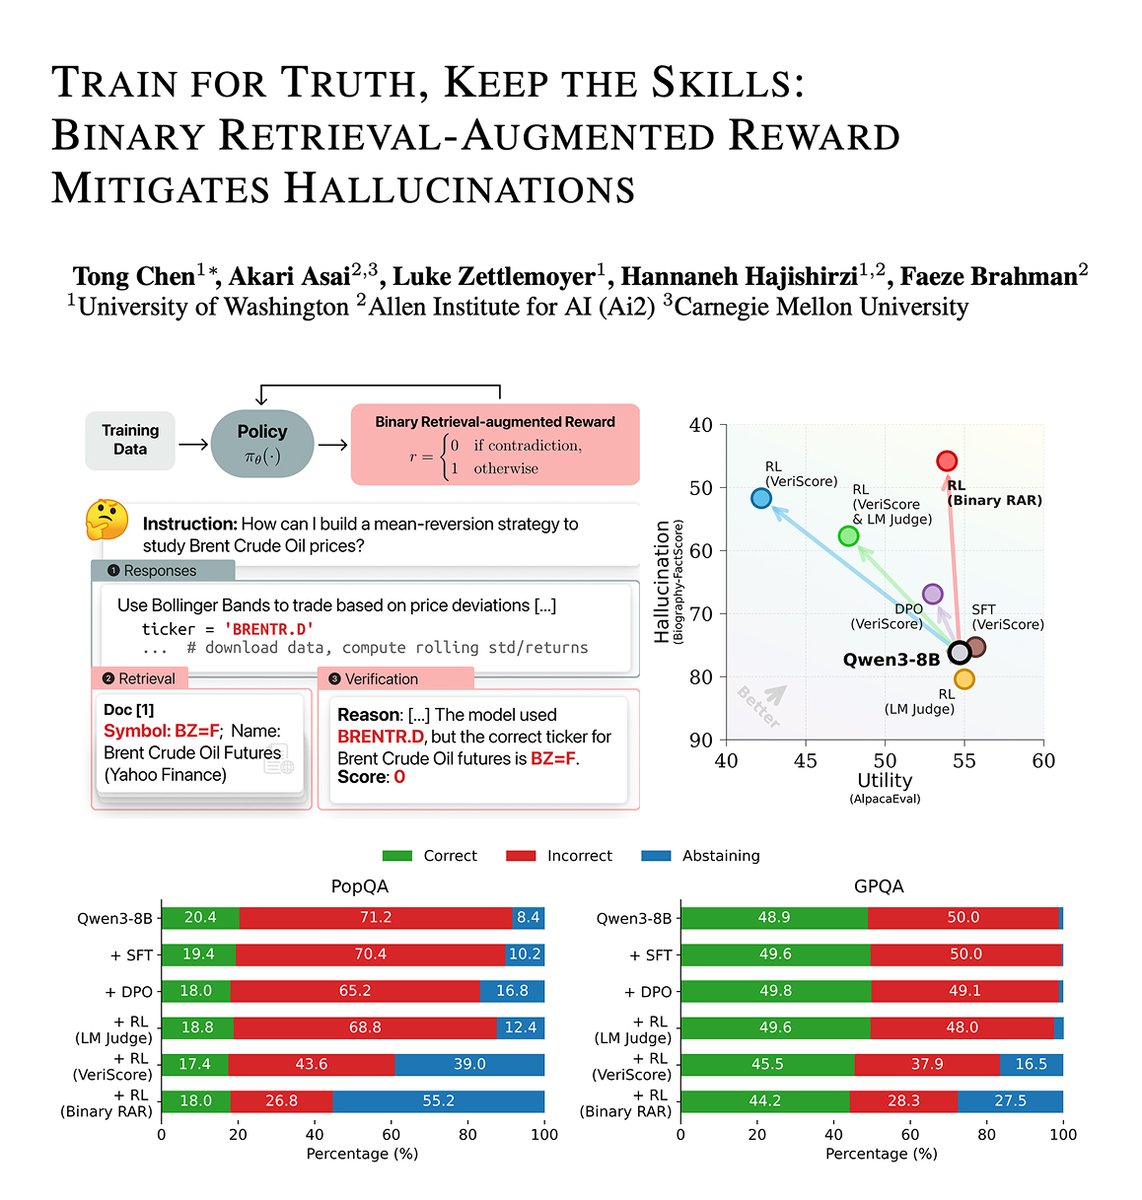
OpenAI's blog (https://t.co/VeNI85798G) points out that today’s language models hallucinate because training and evaluation reward guessing instead of admitting uncertainty. This raises a natural question: can we reduce hallucination without hurting utility?🤔
On-policy RL with our Binary Retrieval-Augmented Reward (RAR) can improve factuality (40% reduction in hallucination) while preserving model utility (win rate and accuracy) of fully trained, capable LMs like Qwen3-8B.
[1/n]
Chart OCR just got a major upgrade with our new experimental "agentic chart parsing" feature in LlamaParse 📈🧪
Most LLMs struggle with converting charts to precise numerical data, so we've created an experimental a system that follows contours in line charts and extracts values. Automate chart analysis without spending hours manually correcting extracted values.
Try it now in LlamaParse: https://t.co/JHWRvwd93B
Everyone's building RAG systems.
But most can't read a simple diagram.
Traditional RAG only retrieves text. But what if your knowledge base includes PDFs with charts, technical diagrams, or infographics?
That's where ✨Multimodal RAG✨ comes in.
Here's what's happening:
Instead of just text embeddings, your vector database stores embeddings of both text 𝗮𝗻𝗱 visuals. When you query the system, it retrieves relevant images alongside text passages.
Then, a Vision Language Model (VLM) processes both modalities to generate a response that actually "sees" your documents.
This works because multimodal embedding models create a joint embedding space where similar concepts across text and images are close together. A chart showing revenue growth and text describing "increasing sales" end up near each other in vector space.
Models making this possible:
Embedding models:
- llama-nemoretriever-colembed
- jina-embeddings-4
- ColPali
VLMs for generation:
- gemini-2.5-pro
- gpt-5
- qwen3-vl
- claude-sonnet-4.5
- command-a-vision
The result? Your RAG system can finally handle real-world documents that mix text with visuals.
Dive into Advanced RAG Techniques with this free ebook: https://t.co/WlzfZSrJoW