What an amazing day! Presented a poster at @PyTorch Conference: how we optimised the RLM paper with pre-fix caching & batched Sub calls with @vllm_project
And a full house for our Pytorch Conference talk on running LLMs using Executorch on Android!
New chips are shipping faster than ever before, but the ecosystem is being held back by having to rewrite and then re-debug the same code over & over again.
@clattner_llvm CEO and Co-founder at @Modular and EVP of Advanced AI Software & Platforms at @Qualcomm, will deliver a keynote at PyTorch Conference North America about an open software platform for heterogeneous compute powered by Mojo and MAX.
PyTorch has always been the place where the best models come together, and now there's a way to get those models onto all kinds of hardware.
If you're interested in Al and compute, join us at the PyTorch Conference in San Jose, CA. Register now: https://t.co/jBApW8ocHQ
#PyTorchCon
Monthly API credits are now available on Max and Team plans: $100 on Max 5x, $200 on Max 20x, and up to $500 pooled on Team. Use them on any Claude model.
How it works and full terms: https://t.co/qmWL6xV8GT
Day 4/
We have improved steering to be instant, leading to the model now reacting much faster to adjustments you make, allowing you to course-correct direction in realtime and not have the model waste effort.
Also releasing GPT-6.1 Sol ultrafast. The two work very well together.
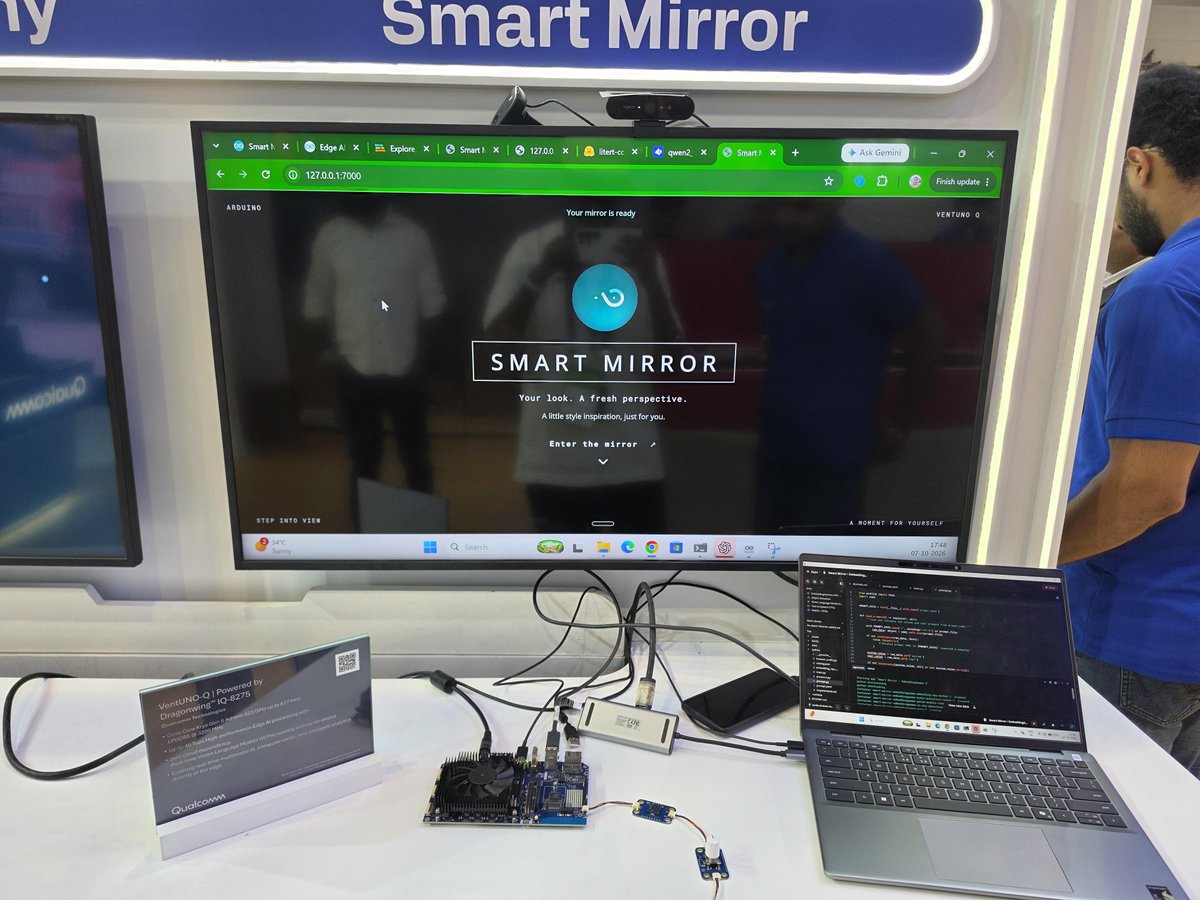
Power of Local AI 😍 Running a custom Smart Mirror Demo application with @arduino Ventuno Q powered by a @Alibaba_Qwen 2.5 VL 7B model to describe what you wear, @googlegemma EmbeddingGemma 2 model for multi-modal vector search to find similar dresses, PiperTTS all targeting the @Qualcomm_Dev NPU on the Ventuno Q at IMC 2026.
Stand in front of the mirror - and get recommendations on how to improve your outfit and get recommendations on other clothing options you can try all offline.