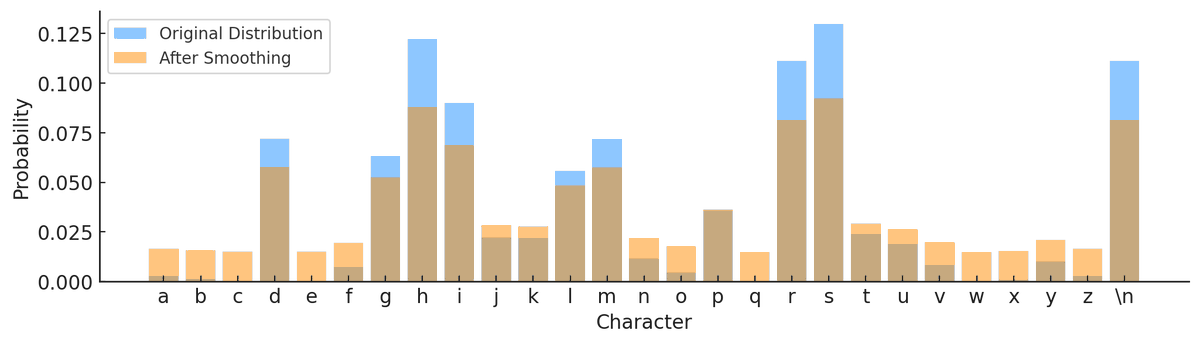Although we haven't been active on this space since Twitter's demise. Our meetup community has been active producing new podcast episodes. Here's our latest episode: https://t.co/uWvQHbIIYU
Excited to finally share that I left Google DeepMind to create Kyutai w/ talented colleagues, a non-profit lab based in Paris and dedicated to open-science, w/ ~300M€ of funding so far. We are starting with multimodal LLMs, for everyone, for free. No distraction, just science.
ChatGPT "Advanced Data Analysis" (which doesn't really have anything to do with data specifically) is an awesome tool for creating diagrams. I could probably code these diagrams myself, but it's soo much better to just sit back, and iterate in English.
In this example, I was experimenting with a possible diagram to explain Supervised Finetuning in LLMs. The "document" at the origin (0,0) is the empty document, and eminating outwards are token streams. Highlighted in black are the high probability token streams of the base model. In red are the token streams corresponding to the conversational finetuning data. When we finetune, we are increasing the probabilities of the red paths and suppressing the black paths. I like this view because it emphasizes LLMs as "token simulators", with their own kind of statistical physics backed by datasets, bouncing around in the discrete token space.
The conversation where we built it in a few minutes:
https://t.co/BPYipeQWws
(Sadly I just remembered that ChatGPT sharing doesn't support images, but at least the text is there, of me iterating with the diagram in plain language, and needing to touch no code. Such a vibe of the future.)
I had a similar experience yesterday, was trying to create a plot that shows smoothing in n-gram language models. Again I could just have coded this manually, but this was 10X faster and so easy.
Conversation:
https://t.co/MTxD2YH6Kv
Posting because during these chats I was struck again by that feeling of what must be the future, where you just sit back and say stuff, and the computer is doing the hard work. And in some narrow pockets of tasks, you can already get that feeling today.
It was terrific that we could organize this workshop on #AIforConservation at @HCRCS. Very grateful to all the participants for their insights that are highlighted in this workshop report! Thank you @lilyxu0 and @rolf_comma_e for your leadership in co-organizing the workshop
In other news, I’ll be joining @UChicagoCS and @DSI_UChicago in 2024 as an assistant professor and doing a postdoc @Meta in the meantime!
I’m at ACL in person and recruiting students who want to find fresh approaches to working with generative models so if that’s you let’s chat!
@svpino Am curious how the curriculum could be streamlined and adapted for use by humanitarian actors interested in applications of CS and AI for good?
Today we're sharing new progress on our AI speech work. Our Massively Multilingual Speech (MMS) project has now scaled speech-to-text & text-to-speech to support over 1,100 languages — a 10x increase from previous work.
Details + access to new pretrained models ⬇️
@fooobar Curious what you’re interested in doing relative to document foundation models? Maybe you wanna give a talk on the subject to our Humanitarian AI meetup group members?
We are looking for a Student Researcher to join Google Research Bangalore to advance the state of the art in document foundation models. Candidates need to be currently enrolled in a PhD program with a strong background in ML/Vision research. Please RT/Like for reach.
DMs open
Getting labeled data for clinical NLP can be prohibitively difficult. In work at #emnlp2022, we find that GPT-3 models perform very well at clinical tasks in the few-shot setting, indicating a new paradigm for transforming EHR notes into actionable data https://t.co/qDA7L11ZTD
The Sixth AAAI/ACM Conference on AI, Ethics, and Society will be held at Le Palais des congrès de Montreál in Montreal, Canada August 8-10, 2023. Register for #AIES23 by June 30 to get the early bird discount ➡️ https://t.co/eHcUyuQOEc
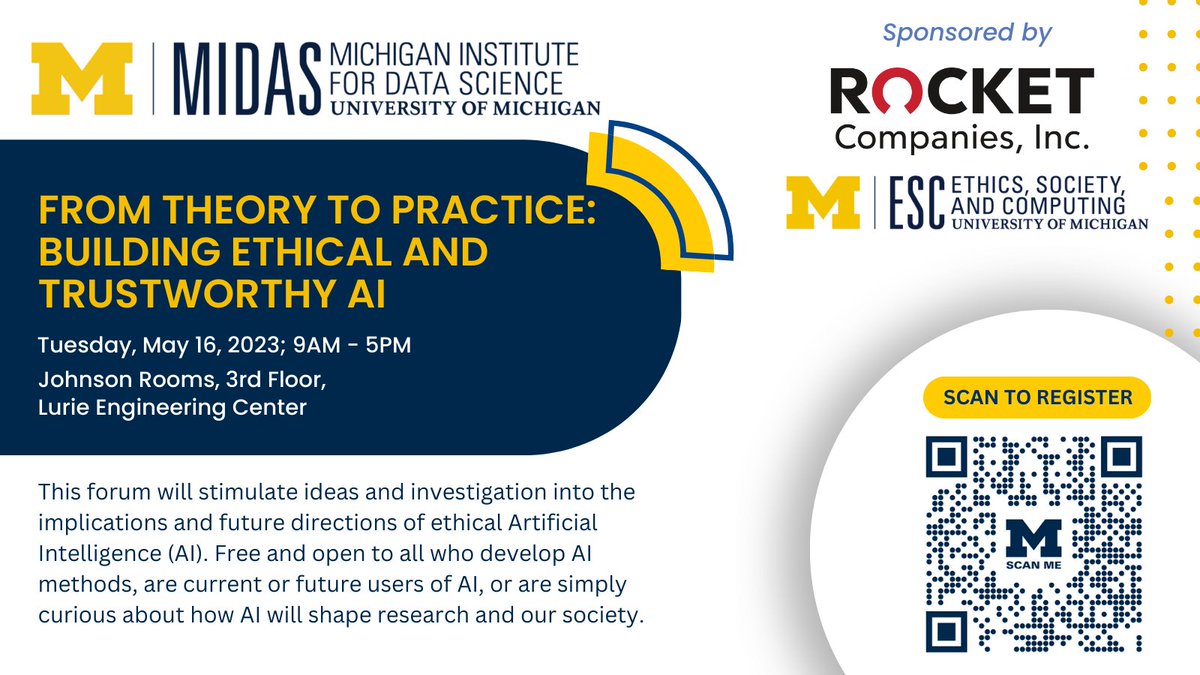
Next Tues. 5/16! "From Theory to Practice: Building Ethical and Trustworthy AI" Registration: https://t.co/RonR1f4c1G
We're surrounded by AI every day: self-driving cars, facial recognition, ChatGPT. But, do we fully comprehend the ethical implications in its use & regulation?
Congratulations to my PhD student @JacksonAKillian for successfully defending his PhD thesis focused on #AIforPublicHealth "Improving Engagement with Public Health Programs via Restless Bandits". Thank you committee @maiamajumder, @roboticwrestler, David Parkes.
📣 Just announced! Join live us on May 18th for #AtScaleMetaAI, a one-day virtual event sharing a look at the next generation of AI infrastructure and innovations powering Meta’s products and services today and in the future.
RSVP ⬇️