Heading to SGLang Summit this week? Keep the conversation going after with us!
We’re co-hosting From GPU to Token, an afterparty with @IOSFVC and Sourcem3d for the people building and serving models at scale: inference, kernels, serving infra, and everything between the GPU and the token.
🗓 Thu, Nov 12 · 6–9pm PT · San Francisco
🍻 Drinks and bites on us
Space is limited, so RSVP for approval: https://t.co/J1SOmAfUc4
🍽️IOSF Founder Table Vol. 1 | From Inference to RSI
Great AI conversations don’t always happen on stage. Sometimes, they happen around a table.
For our first gathering in San Francisco, researchers from OpenAI, xAI & Google DeepMind joined founders and investors to exchange ideas on inference economics, world models, recursive self-improvement (RSI), and AI agents.
A few takeaways:
🔶 Inference: Customer retention and sustainable margins matter as much as growing demand.
🔶 World models: Impressive demos are just the beginning. Real use cases drive adoption.
🔶 RSI: Faster research doesn’t always mean better decisions.
🔶 AI agents: Greater autonomy makes oversight and trust more important.
💬 Interested in joining a future gathering? DM us or leave a comment!
🔗 Learn more about our events:
https://t.co/wrm43D4ASf
#IOSF #FounderTable #AIResearch
🚀 From GPU to Token, join us in San Francisco!
Together with @hyperbolic_labs and SourceM3D, we’re bringing the AI compute ecosystem together for an evening of conversations and connections following SGLang Summit!
⚡From data centers and GPU clouds to inference and AI applications, let’s connect the people powering the next generation of AI.
Expect guests from SGLang, NVIDIA, GMI Cloud, Apple, Google, Amazon & more!
📅 Nov 12 | 6–9 PM PST
📍 San Francisco, CA
🎟️ RSVP: https://t.co/GvS9cuafu1
Let’s connect, exchange ideas, and make things happen! 🤝
#AIInfrastructure #GPU #SGLang
IOSF is doubling down as @hyperbolic_labs announces its latest round.
How we saw it:
In 2024 the open question wasn't whether inference would grow. It was whether the newest GPUs would just obsolete everything that came before. Our read was they wouldn't. Inference was going to keep climbing, and older cards would slide down the cost curve into new buyers and new workloads, not get thrown away like last year's phone.
The hard part wasn't owning more GPUs. It was about making heterogeneous compute supply unified, liquid, productive, and durable. That's the layer Hyperbolic built. Making messy supply easy to access, manage, and orchestrate.
Two years later that call still looks right. And a new demand is showing up on top of it: hedging compute. Long GPU books want price protection, not just capacity. Indices are easy; physical settlement isn't. Hyperbolic is rare in being able to do both: take multi-year supply, break it into short-term product customers actually buy, and sit underneath the hedge as the party that can deliver the hardware.
We're proud to continue our partnership with @zjasper and the @hyperbolic_labs team on turning compute into a liquid market.
We’ve raised an oversubscribed $30M Series A1 led by @walden_catalyst to build the Global Compute Grid.
We’re turning fragmented GPU capacity into one unified platform where AI teams can access, manage, sell, and orchestrate compute.
Our mission: make the world’s compute unified, productive and liquid.
China AI Weekly | Oct 28 – Nov 4
Where the capital moved this week:
💰 @deepseek_ai raised $15.9B, China's largest startup round ever. It alone lifted October global VC to $59B (+45% YoY); AI took 66% of all dollars.
🔌 Compute is going domestic. @deepseek_ai reportedly ordered ~160K Huawei Ascend chips (~$2.5B) for V5 (unconfirmed). Nvidia's China AI chip share is down to ~34%.
📱 @Apple Intelligence launches in China in December on @Alibaba_Qwen . $BABA +5%.
🤖 @deepseek_ai previewed a multi-agent "super agent" and shipped Creator Mode — going straight at the coding-assistant market.
⚖️ NDRC is drafting full-lifecycle AI safety standards; a financial regulator warned AI investment is "overly concentrated."
📉 Counter-signal: Chinese AI stocks are sliding, and private benchmarks show a ~12-pt gap to US frontier models.
Our read: mega-rounds at the top, compression everywhere else. Distribution now beats leaderboard rank.
Follow @IOSFVC for the weekly China AI → capital signal.
For AI agents, price per token is the wrong number.
@deepseek_ai V4.1 Flash: $0.003 per million input tokens on a cache hit vs $0.15 fresh (off-peak). That's 50×.
Our 60-second video explains why this matters for agents, how DeepSeek got here, and the caveats 👇
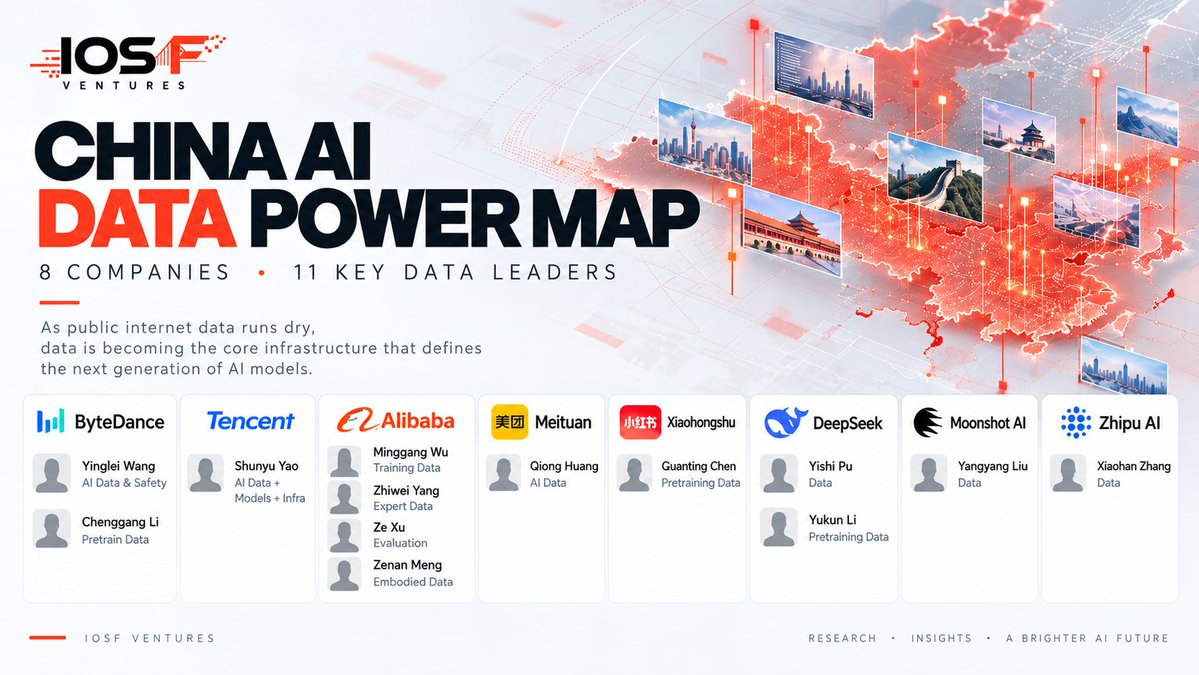
China’s AI race is shifting from model size to data control. But who are the people actually shaping that shift?
As high-quality public training data becomes harder to scale, the teams responsible for sourcing, training data, and evaluation are becoming increasingly central to AI development.
A closer look at 8 major Chinese AI companies reveals the people behind this transition:
• @BytedanceTalk : Yinglei Wang oversees AI Data & Safety, while Chenggang Li leads pretraining data within Seed.
• @TencentGlobal : Shunyu Yao has taken on leadership across foundation models, AI infrastructure, and AI Data.
• @AlibabaGroup : Minggang Wu, Zhiwei Yang, Ze Xu, and Zenan Meng cover training data, expert data, evaluation, and embodied AI data.
• @meituan : Qiong Huang is reportedly responsible for training data within its LongCat model team.
• @xiaohongshu : Former DeepSeek researcher Guanting Chen leads pretraining data.
• @deepseek_ai : Yishi Pu and Yukun Li are key figures in its training data operations.
• @moonshot AI: Yangyang Liu is a key contributor to its multimodal data and evaluation research.
• @ZhipuAI AI: Xiaohan Zhang has played a central role in building its data annotation infrastructure.
The bigger picture: data is no longer just a supporting resource. The people deciding what models learn, how data is produced, and how progress is measured are becoming increasingly influential.
As China’s AI industry moves beyond scaling models, these data teams are worth watching.
Explore the map below. 📷
Based on reporting by Z Finance. Roles reflect reported information and may change.
7/ For agents, price per token is the wrong number.
Watch the price of a new token, and how much of each request a provider can serve from storage.
Sources: https://t.co/Hknl4Q8ULy https://t.co/dBy14yRYvm https://t.co/wSG8K9Dc0f
1/ One AI bill, 14 models. DeepSeek V4.1 Flash handled 53% of the tokens for 2.7% of the spend.
$0.02 per million tokens. The bill's average: $0.41.
The trick isn't the model. It's the cache. 🧵
6/ The catch:
fresh prompts pay $0.15-0.30 in, $0.60-1.20 out
weekday peak hours cost 2x
cache hits need an exact prefix match
prices rose 50% to 1,100% by rate in Aug
Anthropic has twice accused DeepSeek of distilling Claude
China's humanoid boom: the industry will win. Most companies won't.
150+ companies. ~50 mass-production models. Sub-5% margins on entry units.
Don't bet on who wins — back the layers that win either way. 🧵
Robots are still in school. Valuations already graduated.
74% of a leading Chinese humanoid maker's shipments went to universities.
Funding: RMB 93.5B in H1 2026, ~5x YoY.
Unitree: ~61% off its post-IPO high.
The industry is in Phase 3. Capital is paying for Phase 6. 📷