Really glad to be working with @alibaba_cloud.
Looking forward to what we build together from here, and to giving our clients a better and more rigorous service!
AI models evolve weekly. Your infra shouldn't have to.
With Alibaba Cloud, @InfronAI scales open-source models like Qwen with dedicated capacity across 5 global regions, provisioned in days with verifiable placement.
Read now: https://t.co/cenR8orvA4
#Qwen#AI #LighthouseCustomerStories
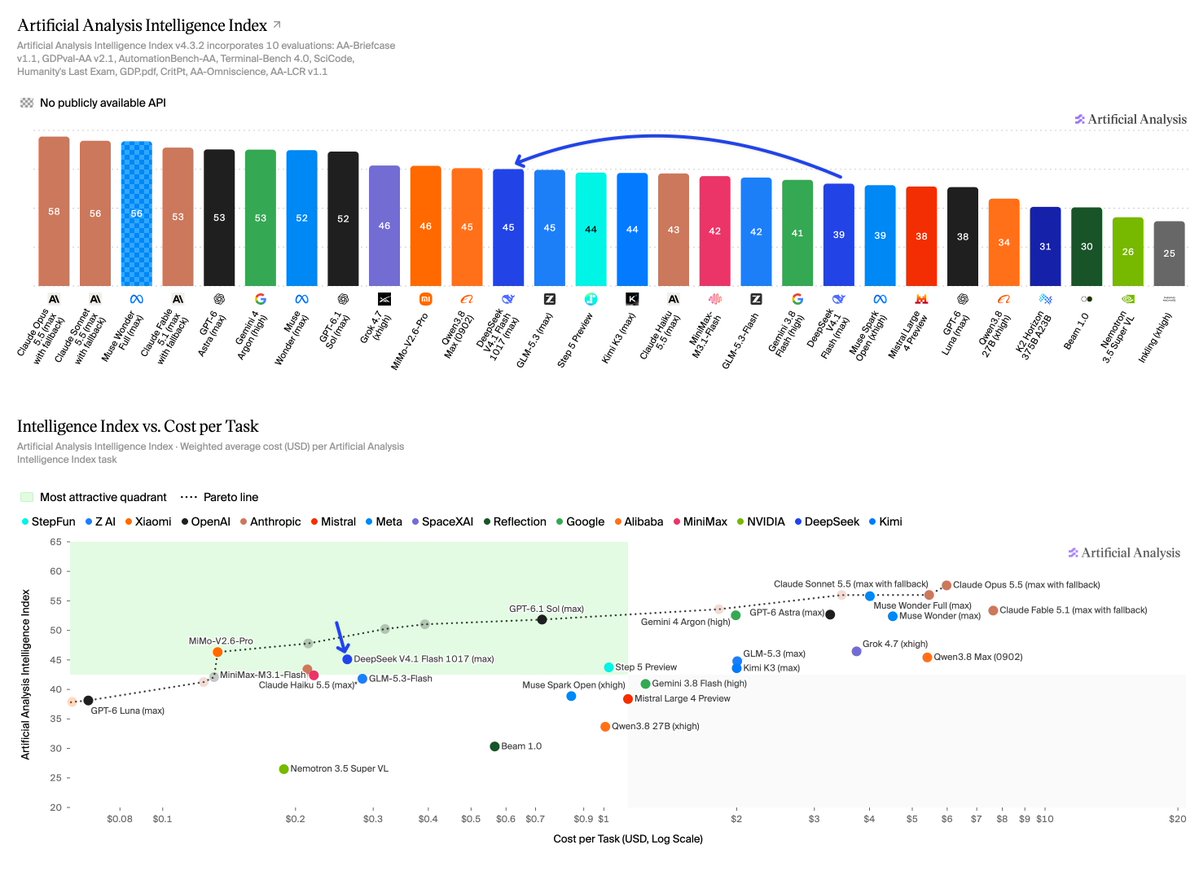
DeepSeek V4.1 Flash 1017 scores 45 on the Artificial Analysis Intelligence Index, up 6 points.
Infron offers 3 DeepSeek V4.1 Flash options:
• 1017: Up to 60% off
• Standard: Up to 60% off
• Free: $0 token costs
DeepSeek V4.1 Flash 1017 scores 45 on the Artificial Analysis Intelligence Index, improving on DeepSeek V4.1 Flash by 6 points, and is the equal #2 open-weights model
@deepseek_ai has released DeepSeek V4.1 Flash 1017, an update on their flagship model DeepSeek V4.1 Flash. On the first-party API, DeepSeek V4.1 Flash 1017 is priced at $0.30 per 1M input tokens and $1.20 per 1M output tokens during peak hours, with off-peak pricing half of peak rates, the same pricing as DeepSeek V4.1 Flash.
Key results:
➤ DeepSeek V4.1 Flash 1017 makes gains in agentic capabilities, knowledge and scientific reasoning. DeepSeek V4.1 Flash 1017’s Elo rating on GDPval-AA v2.1 is 1746, an increase of 146 points from DeepSeek V4.1 Flash’s rating of 1600. On AA-Briefcase v1.1, its Elo rating increases by 150 points from 1420 to 1570. On AA-Omniscience, its non-hallucination rate is 33%, a 29-point improvement from DeepSeek V4.1 Flash’s 4%, while seeing an improvement in accuracy from 43% to 46%, pushing its overall AA-Omniscience Index score from -5 to +5. On CritPt, DeepSeek V4.1 Flash 1017 scores 24%, up from 14% for DeepSeek V4.1 Flash.
➤ DeepSeek V4.1 Flash 1017 is now the #2 open-weights model alongside GLM-5.3. With a score of 45 on the Artificial Analysis Intelligence Index, DeepSeek V4.1 Flash 1017 is behind MiMo-V2.6-Pro by only 1 point and ahead of other open-source models like Step 5 Preview and Kimi K3 (both at 44).
➤ With a Cost per Task of $0.26, DeepSeek V4.1 Flash 1017 sits in the most attractive quadrant of Capability vs. Cost. With a Cost per Task of $0.26 and Intelligence Index score of 45, DeepSeek V4.1 Flash 1017 compares favorably to GLM-5.3-Flash at $0.28 per task and a score of 42. At the same time, MiMo-V2.6-Pro (46) at $0.13 per task and GPT-6.1 Sol (medium, 48) at $0.21 per task both offer higher capability at a lower Cost per Task.
Additional model details:
➤ Context window: 1M tokens (equivalent to DeepSeek V4.1 Flash)
➤ Pricing: $0.30 per 1M input tokens and $1.20 per 1M output tokens, unchanged from DeepSeek V4.1 Flash. Cache hit price of $0.006 per 1M tokens, a 98% discount
➤ Size: 552B total parameters (16B active)
➤ License: MIT
➤ Providers: Available through DeepSeek’s first-party API, @FireworksAI_HQ , @baseten, @DeepInfra , @wafer_ai , @Cloudflare and others
This Thursday, we’re co-hosting Open Infra Night for Agent Builders with @struktoai and @XTrace_ai.
📅 Oct 22 · 17:00–20:30 PT
📍 San Francisco
RSVP: https://t.co/WFtwb7r0hg
#OpenSourceAIWeek#infron
MiniMax M3.1 Flash: Space Performance + Bunny Speed
🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash.
💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed.
API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens.
Model weights will arrive on Oct 23.
API: https://t.co/fHRdSV73Hr
M Plan: https://t.co/XfJWSyauda
MiniMax Code for desktop: https://t.co/SGmLTI2HQm
Infron provides Grok Imagine Image 2.0 at 20% off the listed xAI Standard rate.
Text-to-image generation: $0.032 per generation, down from $0.04.
Explore the model and current pricing:
https://t.co/COLKOVaU1f
#infrondiscounts#Grok
Excited to support AgentVFS as a sponsor. The idea of giving AI agents a familiar way to work with service through files and shell commands is really inspiring.
Congrats to the team on the release, and a special thank-you to @cdxy_ and @AndrewHan_Zheng for contributing. Looking forward to seeing what the community builds with it!
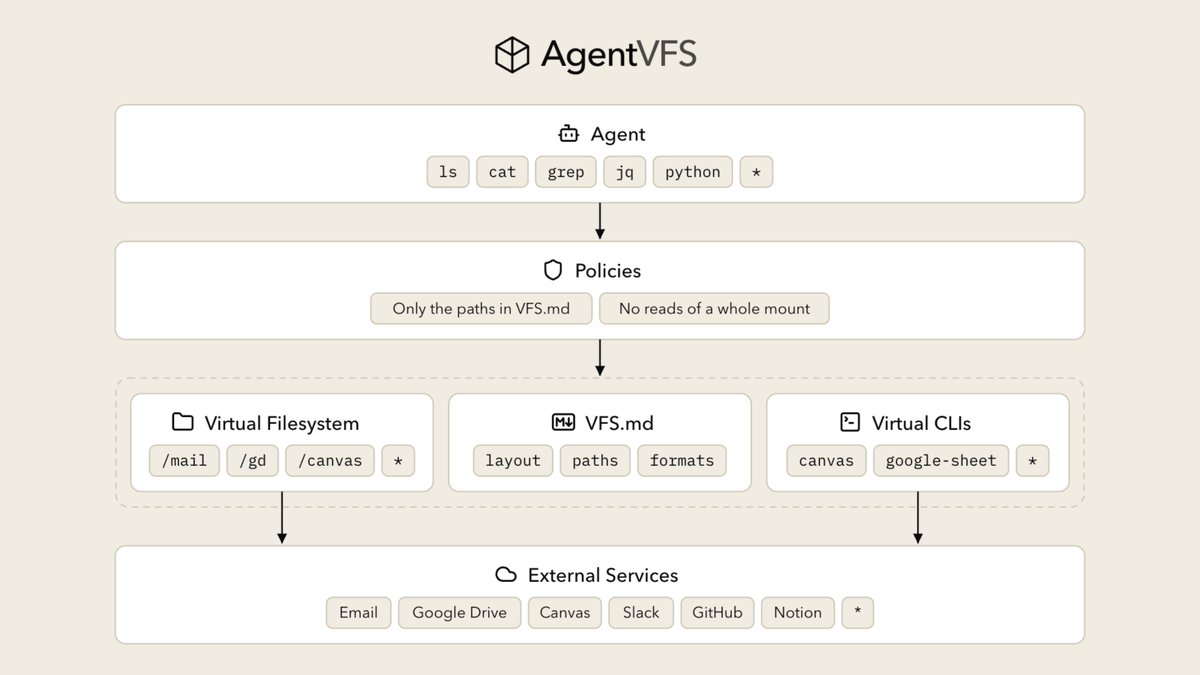
We're releasing AgentVFS, a virtual filesystem interface for AI agents https://t.co/MNGMltHHvB
AgentVFS unifies every service into one interface and replaces the need of calling MCP. Stored data becomes one virtual filesystem across services, described by VFS.md, and actions become virtual CLIs, so the agent no longer calls MCP tools at all. AI agents work on live data across every service through the terminal-like interface they know best. They use the Unix tools they learned in training (ls, grep, jq, pipes, loops) and the terminal workflows they practiced in post-training on agentic coding.
We're also releasing VFS-Bench 1.0 https://t.co/TPXLRs622F, the first systematic study and benchmark to compare a virtual filesystem with MCP on the same tasks. Compared with MCP, AgentVFS uses up to 88% fewer tokens and has about a 5% higher success rate on average.
173 discounted models. 13 model families. 👀
Explore the latest discounts across GPT, Gemini, Qwen, DeepSeek, GLM and more.
Download the full pricing list in Excel or CSV for easy comparison.
Need volume pricing? https://t.co/AXQ6HJb64a
Explore discounts: https://t.co/EAxQy71vq1
#infrondiscounts
Other speakers:
→ Dewey Fang, Tech Lead for TensorRT Model Connect at NVIDIA
https://t.co/qcnFs3fulh
→ Vishvesh Bhat, Co-founder at CoreThink AI
https://t.co/sm2U2qw8cc
→ Yuan He, Applied Scientist at Amazon Rufus
https://t.co/9fegvQ9SCX
→ Christine Hu, Co-founder & CEO at Philo Labs
https://t.co/bFCqPgVThc
→ Yiwen Yuan, Former AI Dev Acceleration Team Lead at xAI
https://t.co/HiYsqaeVzW
→ Neo Zhang, Co-founder & CEO at DaoBrew AI
https://t.co/OYYdm6Lvjz
→ Simantak Dabhade, DevRel & Growth at TinyFish
https://t.co/4KgpIhYqom
This Thursday, we’re co-hosting Open Infra Night for Agent Builders with @struktoai and @XTrace_ai.
📅 Oct 22 · 17:00–20:30 PT
📍 San Francisco
RSVP: https://t.co/WFtwb7r0hg
#OpenSourceAIWeek#infron
From the co-hosting teams:
→ Zecheng Zhang @zechengzh, Founder & CEO at @struktoai : https://t.co/sJwJqNpORC
→ Lawrence Xu @cdxy_ , Co-founder & CEO at @InfronAI : https://t.co/Yb5ud8VlqO
→ Felix Meng @felixmeng_ , Co-founder & CEO at @XTrace_ai : https://t.co/XzcAeBCjVN
Strukto is the virtual environment layer for AI agents: virtualized terminal, filesystem, CLIs and runtimes that work on any infrastructure. Its core, Mirage, is open source (Apache 2.0).
Infron AI provides AI infrastructure and inference services for open-source models, from serverless and elastic capacity to dedicated and custom deployments.
XTrace helps engineers spend less time correcting agents and more time shipping. It shares lessons across the team, helps enforce coding standards, and exposes wasted token spend.
Meet your hosts for the evening:
Zecheng Zhang · Strukto AI
https://t.co/cmdoQemVWC
Lawrence Xu (@cdxy_) · Infron
https://t.co/wTVPJR8VVh
Felix Meng · XTrace
https://t.co/X6HkzVMUMC
Tomorrow, we’re co-hosting Agents in Production with @oodleai and @XTrace_ai !
If you’re building agents, come join us for a panel, 4 builder demos, and food. We’d love to hear what you’re working on.
📅 Tuesday, Oct 20
🕒 17:30 - 20:00 PT
📍 Mountain View, CA
RSVP: https://t.co/9xtMEbw3db
#infron #OpenSourceAIWeek