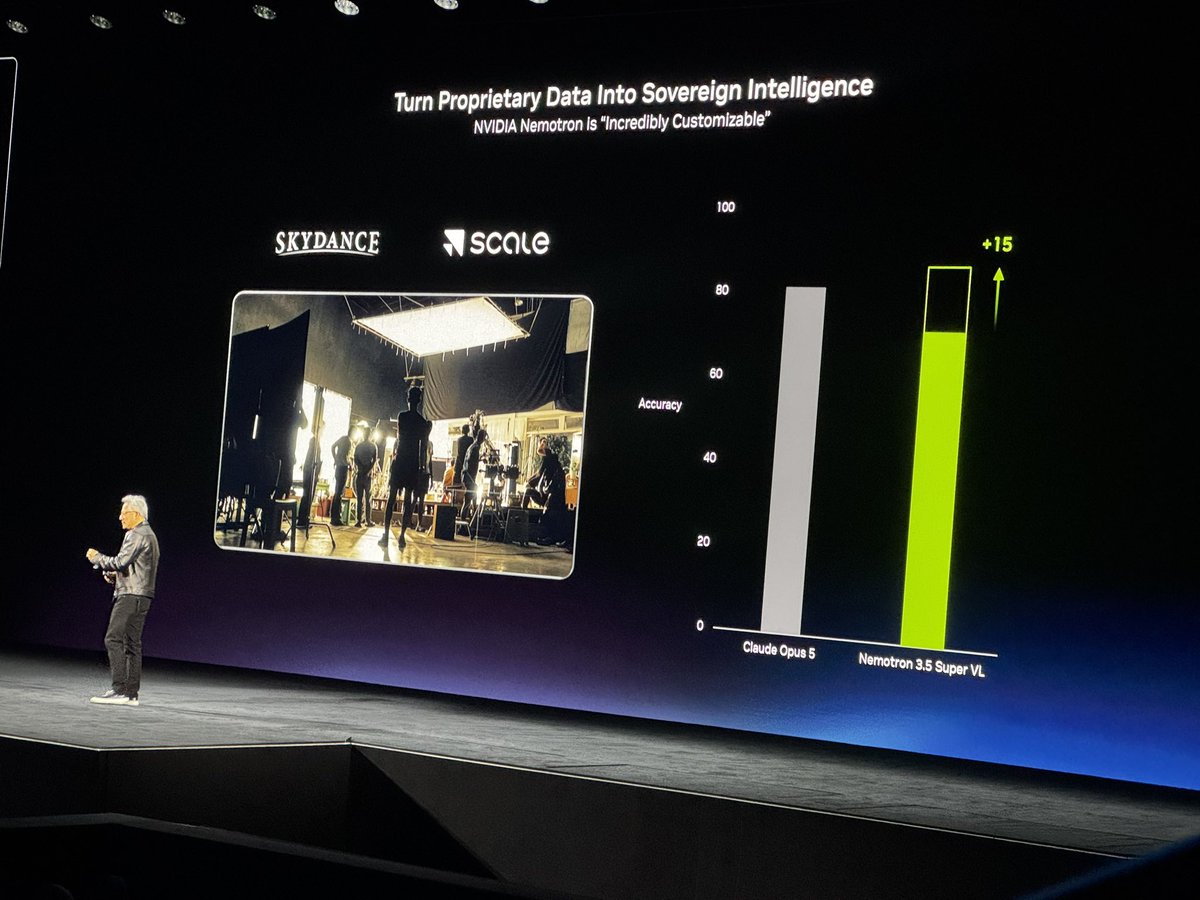
At #NVIDIAGTC Berlin, @JensenHuang highlighted our work with @Skydance to post-train @NVIDIAAI Nemotron 3.5 Super VL.
On real production tickets, the agent matched frontier-model accuracy at ~1/40 the inference cost and 5x the speed.
Scale ❤️ NVIDIA: Proprietary data + great post-training = sovereign intelligence. Thanks @JensenHuang and @nvidia for highlighting what @scale_AI and @Skydance built on Nemotron: +15 pts in accuracy.
From classrooms to legislative drafting, AI is being built into specialized government workflows.
Through a multi-year partnership with @MCITQatar, Scale is one of the partners contributing to AI adoption across Qatar’s public institutions.
What that looks like in practice ↓ https://t.co/5sa3sBxsuK
The future of enterprise AI is multi-model, and enterprises deserve the freedom to choose.
NEWS: We’re expanding that choice through our collaboration with @NVIDIA, post-training its open-weight Nemotron 3.5 Super VL for enterprise workflows. Here’s what it delivered for two of our customers:
✅ @Skydance: A complex finance workflow that reviews vendor credit memos, statements and invoices to find credits the company is owed. Post-trained Nemotron matched their current frontier model’s accuracy at 40x lower inference cost, with 5x faster response times.
✅ @EY_US: An M&A due diligence agent that finds and reconciles answers across hundreds of files in a virtual data room. Post-trained Nemotron matched EY’s current frontier model at about one-eighteenth of the inference cost, returning answers more than twice as fast.
Put NVIDIA’s open-weight models to work for your business with Scale Post-Training.
Thank you, @JensenHuang and the NVIDIA team, for the early access and collaboration.
https://t.co/NMMA3BilJV
A great pianist can play almost anything, but mastering one piece is what makes a performance exceptional. The same goes for AI.
With today's launch of Nemotron 3.5 Super VL, we’re collaborating with @NVIDIAAI to combine their open post-training tools with Scale’s data, evaluation and applications building expertise. Together, we're turning general-purpose models into powerful, cost-effective specialists for enterprises everywhere.
Welcome to the multi-model world. 🤝
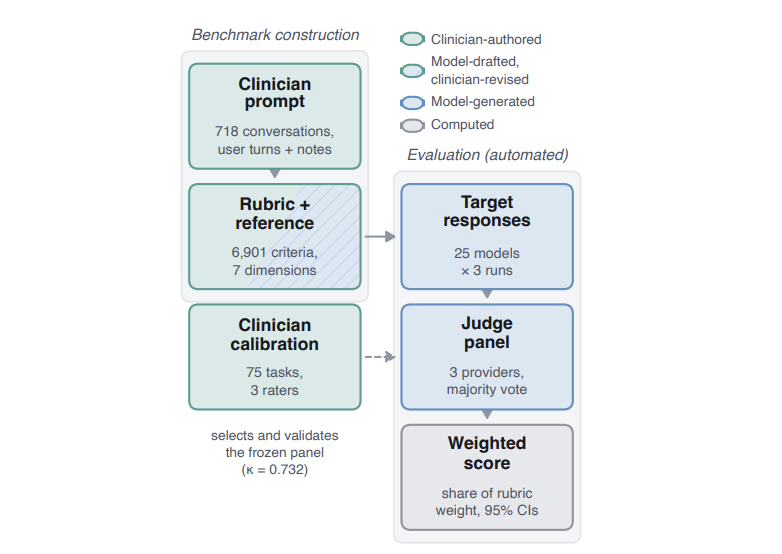
People increasingly turn to AI chatbots for mental health support. But are models actually helping when it matters most?
We're releasing DistressBench, a new benchmark measuring how well AI models respond to mental health crises.
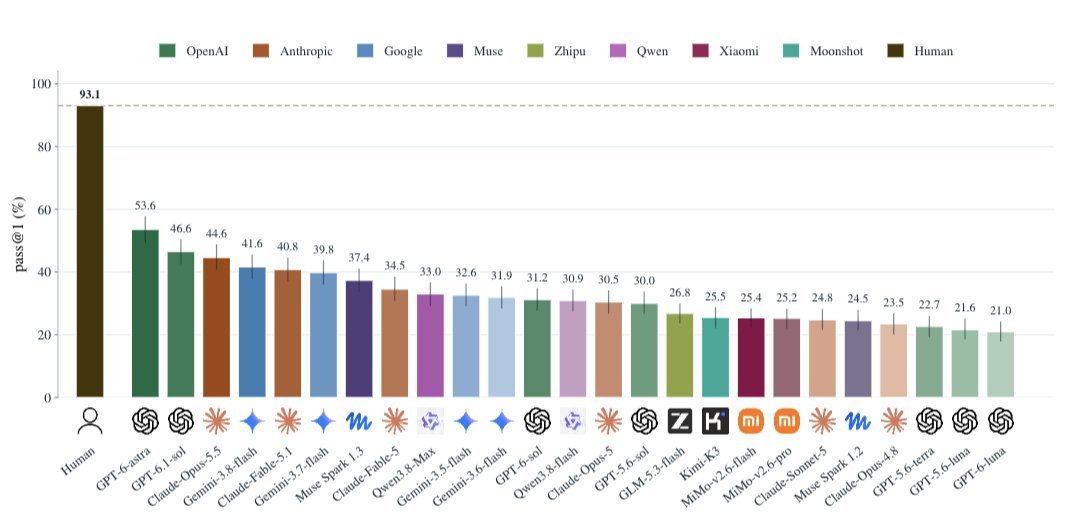
We’re introducing Humanity’s Sixth Sense, a new benchmark testing the intuitive visual reasoning people rely on every day.
Across 522 open-ended tasks spanning images and video, HSS tests everything from spatial and causal reasoning to social understanding.
The gap is significant. Humans score 93.1%, while the strongest model, GPT-6-astra, reaches 53.6%. The median model scores just 30.9%.
Much of the AI security debate is about frontier models. But a lot of people are building on open-weight models. We need to understand their capabilities and risks too. A real testing strategy covers every model, not just the frontier.
You can’t improve agents if you can’t measure where and why they fail.
At #LATechWeek, we're hosting a hands-on evals workshop led by our Head of General Agents @Bckenstler to break down how we structure evals, what we measure, and how we use the results to improve AI systems.
Apply here to join us: https://t.co/50EfNIl0Lw
We’re excited to bring @nvidia's Open Agent Safety Platform technologies to Scale GenAI Portfolio, helping us build, train, deploy, run, and evaluate AI agents in controlled environments with enforceable security and a clear record of their actions.
Today, with over 100 industry partners, we introduced the NVIDIA Open Agent Safety Platform, bringing together OpenShell and Sentry.
Artificial intelligence is extraordinary technology that will advance discovery, productivity, security, health, and prosperity for generations to come.
But its full promise can only be realized when people have confidence that AI is being built to be safe and deployed with wisdom and responsibility.
This is bigger than a single product. It's the beginning of an open ecosystem to build the trust layer for safe agent systems.
Together, we are building the foundation of the AI economy.
Trust and innovation are not in conflict. Safety is how trust is earned. We must build not only the most capable AI, but the most trusted AI, so that this extraordinary technology can realize its enormous promise for the world. https://t.co/ugYWQ1MyRi
An honor to meet with His Highness the Crown Prince of Kuwait to discuss how @Scale_AI can support Kuwait’s digital transformation and develop Kuwaiti AI talent.
The nation that can measure the AI frontier will be the one that steers it. Our future should not be steered by speculative warnings. We have to be driven by evidence. That was the clearest takeaway from this week's AI conversations at the UN General Assembly.
Governments need to get serious about testing frontier AI, and nowhere is that more urgent than in Washington.
Getting serious means three things:
→ Clear responsibility for testing across agencies
→ Access to models before they're deployed
→ Funding for the experts and tools to do the work
Scale AI's cyber research shows what testing can reveal. We've seen AI agents carry out an attacker's instructions while still finishing the user's task, so the user never knew anything went wrong. We've also seen models refuse to help people defend their own systems.
Both are failures. Real testing has to measure the harm AI can cause and the help it fails to give.
Government shouldn't have to rely solely on AI developers to explain these failures. It needs its own testing capacity, with the expertise to ask hard questions and the tools to answer them.
Scale has worked with the U.S. government for years to test the risks and capabilities of AI models, and we're accelerating that work in the months ahead.
Here's what we think America should do next: https://t.co/mdyk5eCTHY
We’re partnering with @googlecloud to make it easier for enterprises to put AI to work.
Our joint reference architecture is a blueprint bringing the Scale GenAI Portfolio to Google Cloud, with Gemini Enterprise integration.
Excited to give builders a proven foundation to put AI to work faster. https://t.co/6jT9L7Rbgp
Today, we released SWE-Bench Pro V2, a refreshed public split of SWE-Bench Pro.
The frontier keeps moving, and the standard for measuring it should move with it. We’ll keep strengthening our leaderboards, incorporating feedback, and building more rigorous evals for what comes next.