Do I need an existing Iceberg catalog and compute engine to get started with oleander? Nope.
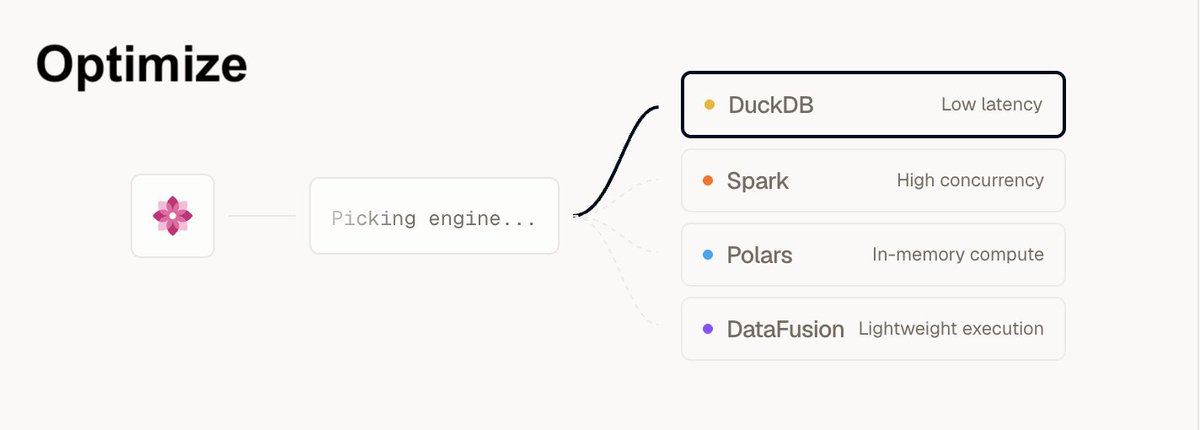
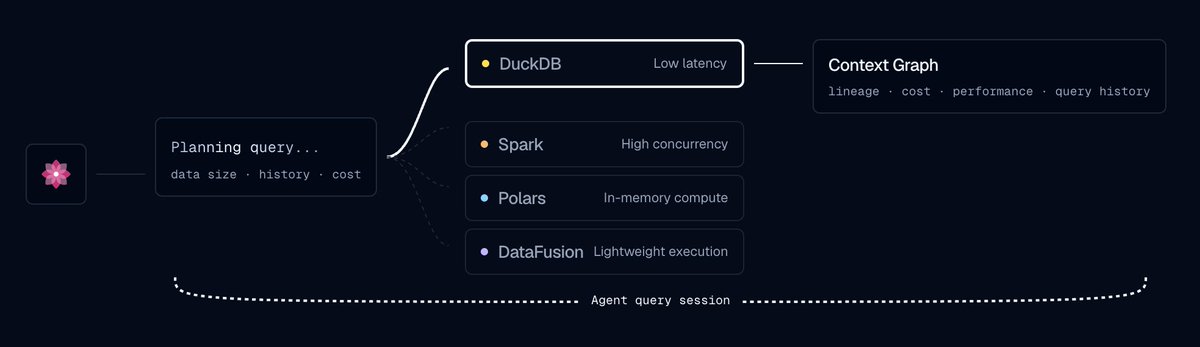
Every organization gets a fully managed Iceberg catalog + 4️⃣ on-demand engines (@duckdb, @DataPolars, Spark and Bloom) with built-in RBAC for humans, services or agents out of the box:
Which means:
→ One permission model across the entire query execution path
→ Govern the compute and the data access
→ Agents are principals, not API keys, with a full audit trail 🌸
Models have token budgets. Agents should have data budgets. Every query. Every dataset. Every dollar. One graph.
oleander captures each query execution in the same context graph across DuckDB, DataFusion, Polars, and Spark. oleander selects the right engine for each query, records why, and learns from every run.
• Set guardrail budgets per agent, per session.
• Enforce dataset access per agent, with table and column-level lineage.
• Allow or block specific execution engines.
• Set latency or cost policies.
• Trace every query back to the agent and session.
More 👉 https://t.co/XAVOgfaffx
Agents demand a new generation of data infrastructure. We're starting with a multi-engine data warehouse built for agents.
oleander supports every step in the MCP data lifecycle. No extra tools.
• Ask. Agents query your data autonomously. Use SQL or natural language via oleander's MCP server.
• Optimize. Every query runs on the right engine. oleander's multi-engine router picks the optimal engine based on your data, query, and cost history.
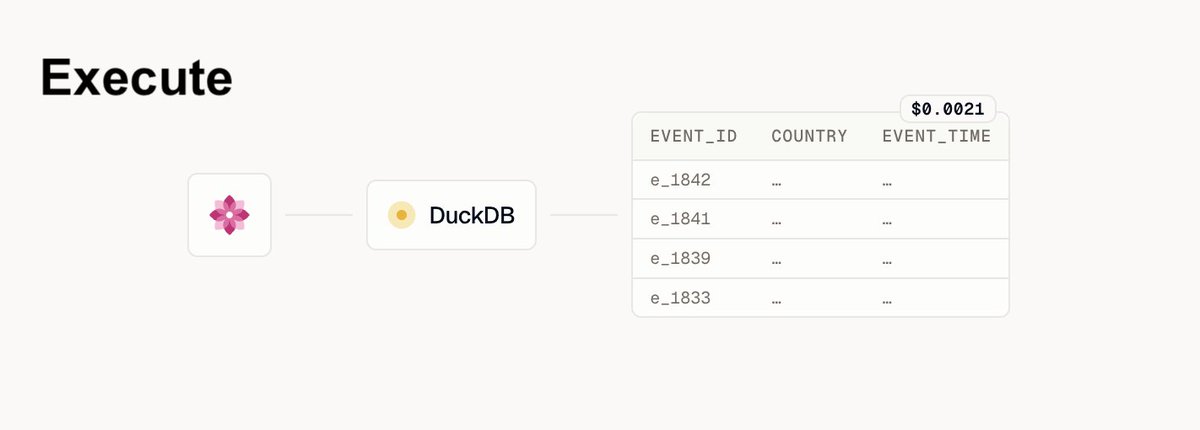
• Execute. Serverless SQL execution on-demand. Queries run instantly on the right engine with zero infrastructure to manage.
• Govern. Built-in governance for agents. A context graph, powered by OpenLineage, automatically captures execution history, lineage, cost, and performance through oleander's MCP server.
Try it: https://t.co/gBZvZ6ACi0
In SF during Snowflake Summit June 1-3? Duck out (ha!) to The Dive! Hear from rockstars at Anthropic, Braintrust, Lovable, Hex, & more.
See the future of lakehouses with @J_ , creator of Apache Parquet, and @zeroshade, founder at Columnar (& me!)
Register! https://t.co/VlIlwlrw8q
@J_ & Pierre Lacave of @datadoghq on how they rely on and contribute to key projects in the data ecosystem:
Arrow for data interchange
Substrait for plans
Calcite as an optimizer
DataFusion as an execution core
Parquet for columnar storage
The database landscape is going through its biggest shift in a decade. AI workloads are pushing OLTP and OLAP closer together, object storage is becoming the de facto foundation for AI search at hundred‑billion‑ to trillion‑document scale, and agents are spinning up databases and schemas programmatically in patterns classic systems were never optimized for.
AI Council's Data Engineering & Databases track is where the builders re-architecting the stack come together. Curated by @saisrirampur, Director of Product at @ClickHouseDB, here's the lineup:
→ Hannes Mühleisen, Co-Founder & CEO at @duckdb: "Super-Secret Next Big Thing for DuckDB"
→ @nikhilbenesch, CTO at @turbopuffer: "Fast AI Search on Object Storage @ >1 Trillion Scale"
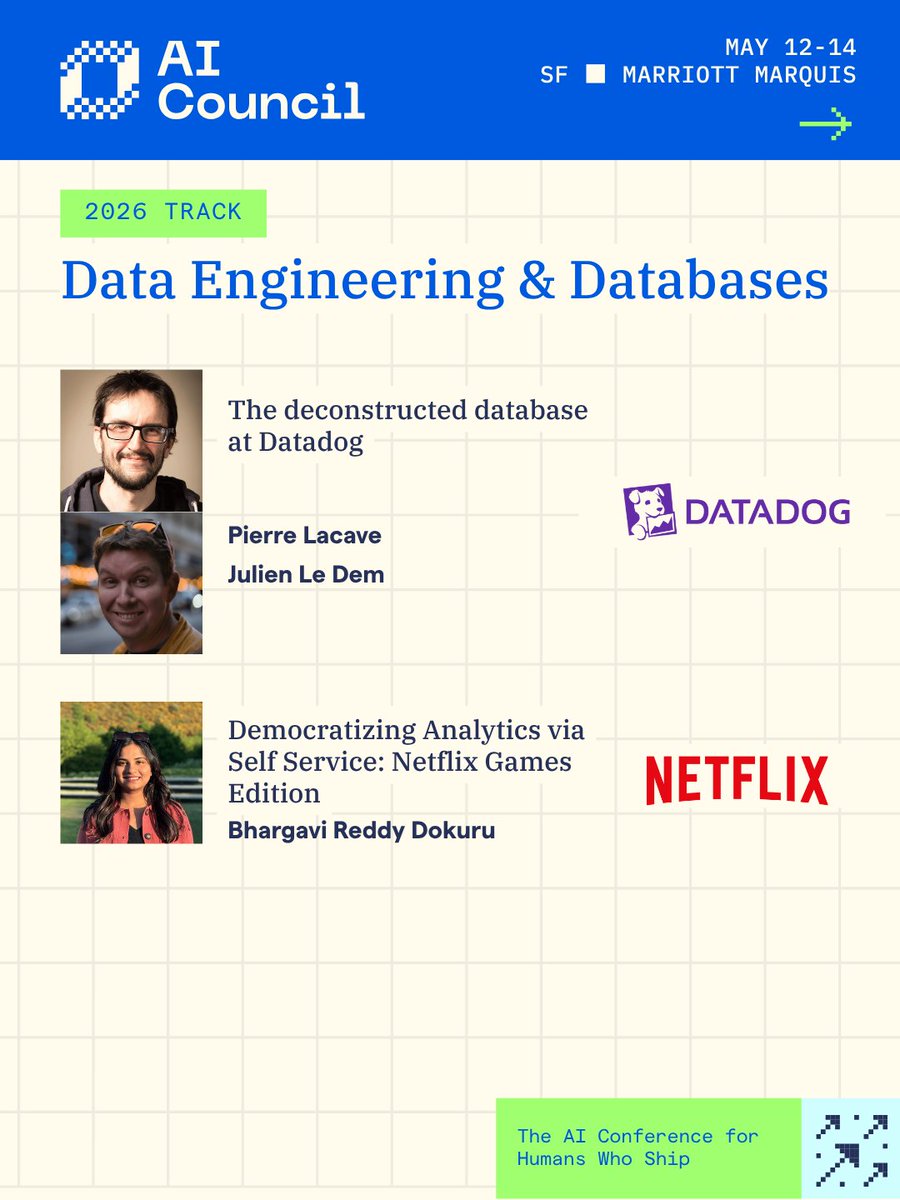
→ @J_ & Pierre Lacave, Principal Engineer & Staff Engineer at @datadoghq: "The Deconstructed Database at Datadog"
→ @iskakaushik, Engineering Lead at ClickHouseDB: "Building a Unified OLTP + OLAP Database for AI Workloads"
→ Bhargavi Reddy Dokuru, Staff Data Engineer at @netflix: "Democratizing Analytics via Self Service: Netflix Games Edition"
→ @kelvich, Principal Software Engineer at @databricks & Neon co-founder: "AI Needs a New Kind of OLTP: Lakebase & Serverless Postgres in the Agent Era"
→ Robin Tang, Co-founder & CTO at @artie_labs: “Scaling CDC to Trillions of Rows: What Broke, What We Rebuilt, and What AI Demands Next”
A huge thank you to Sai for curating this awesome track!
Join us SF, May 12-14! 🎟️ https://t.co/TddrwUD2ff
@J_ co-created Apache Parquet, Apache Arrow, and OpenLineage. Three projects. Three industry standards.
Parquet at Twitter in 2013. Arrow at Dremio. OpenLineage at Datakin, acquired as part of Astronomer's $213M Series C. He is now Principal Engineer at Datadog and an officer of the Apache Software Foundation. That is an unusual track record of picking the right abstraction at the right time.
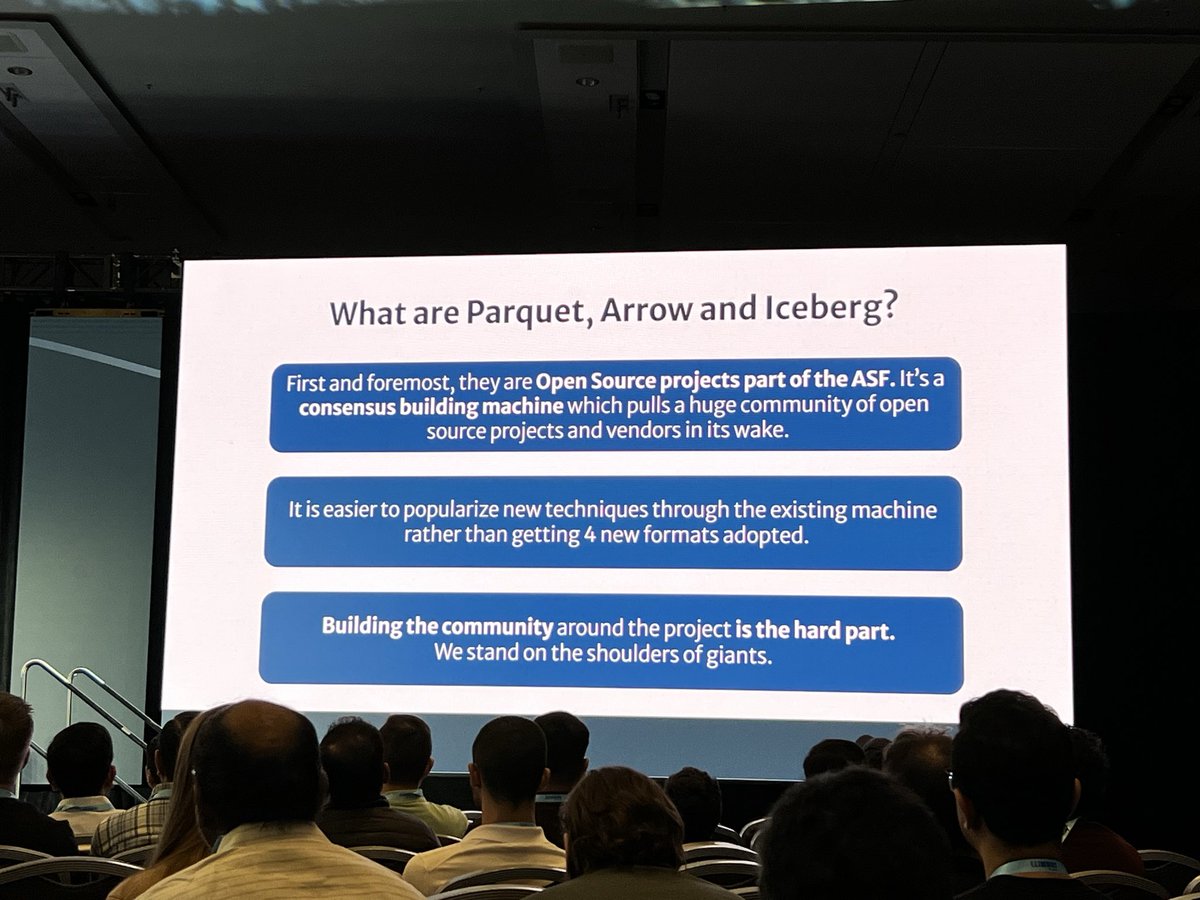
His OpenXData talk argues that the current wave of challengers -- Lance, Vortex, Nimble, FastLanes, BtrBlocks, F3 -- are solving real problems but misreading what made Parquet succeed in the first place. The core contribution was not the encoding choices. It was the community consensus mechanism those choices were built inside. His case: use established open source communities to absorb these innovations rather than fragment the ecosystem across six competing formats.
He published the written version of this argument at https://t.co/LqzyL2HIN7 in December 2025. OpenXData is where you can push back live.
👉 Register here: https://t.co/ZV3kSTNtiE
@changhiskhan My point is the upper layers can be built on top of the existing format. You don’t need to start a new stack from scratch. Not everything needs to be in parquet an you don’t need a new format to build them.
In the past few years, we’ve seen a cambrian explosion of new columnar formats, challenging the hegemony of Parquet. Presumably, the design of yore is not going to cut it moving forward. I spent some time to understand how things actually changed.
https://t.co/BxtXabynQ8
If you missed my talk "The advent of the open data lake" at AI By the Bay, the recording is now available.
https://t.co/5pLMhL2ynn
https://t.co/ET94a4Tu6C
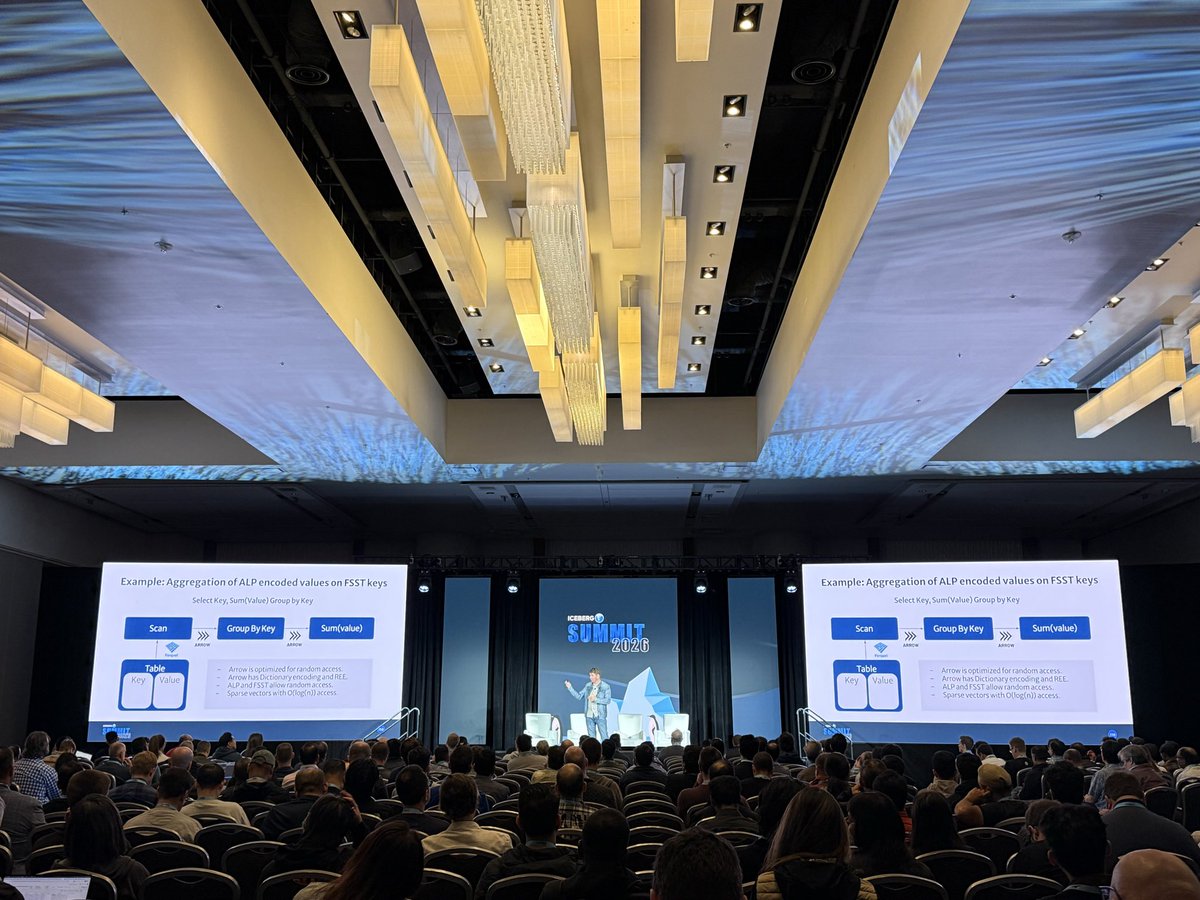
There is some crazy (good) activity on the @ApacheParquet mailing list for new encodings. A sample: PFOR, FSST, ALP, Strings and Cascaded Encodings. 🤯 Huge kudos to Arnav Balyan, Prateek Gaur, and Micah Kornfield for driving this.
https://t.co/YRE13QEm2j
Parquet sparked a revolution in columnar storage. Now AI workloads are driving a new wave of change.
At 𝗢𝗽𝗲𝗻 𝗟𝗮𝗸𝗲𝗵𝗼𝘂𝘀𝗲 + 𝗔𝗜 𝗠𝗶𝗻𝗶 𝗦𝘂𝗺𝗺𝗶𝘁, Julien Le Dem (@datadoghq) will cover:
🔹 What’s changed since Parquet was introduced
🔹 Why new columnar formats are emerging now
🔹 The encoding advances shaping what comes next—and how they’re pushing Parquet to evolve
📅 Nov 13 | Mountain View
🔗 Register: https://t.co/AquA7RpKhh
#openlakehouse #opensource #columnstorage #ai #parquet