We’re so excited to introduce Muse, your 24/7 personal assistant powered by the latest Muse Spark 1.3!
I’ve personally spent many hours optimizing the model under the hood and smoothing out the rough edges to make it better.
Give it a try and let us know what you think!
1/ today we're rolling out Muse, our new personal ai assistant. Muse is always-on, wicked fast, can use a browser, connect to your apps, and is designed to be secure.
try it now: https://t.co/n7swQh9v6C.
Thoughts About Scaling Law
Scaling, but not only of parameters. Every model release now ends with the same question: how many parameters? It isn't a question that can be answered on its own. Parameter count is only meaningful alongside three others — how much data you have, where you intend to spend your compute, and who will run the model, under what conditions.
The field learned this the hard way. Kaplan et al. (2020) fit an exponent that told everyone to grow parameters faster than data — roughly 2.7:1 — and the industry complied: GPT-3, Gopher, MT-NLG. Hoffmann et al. (2022) redid the experiment across four hundred models and found the compute-optimal split is closer to 20 tokens per parameter, and that with sufficient compute the two should grow at the same rate rather than drifting apart. The error in the earlier fit compounded with every order of magnitude of compute, which is why the largest models of that generation were the most misallocated. The trillion-parameter round was, in retrospect, a detour the whole field took together and then reversed.
Chinchilla wasn't the end either. It optimized training compute for models that would be trained once and evaluated. Today a model is called billions of times a day and inference dominates lifetime cost. Put inference into the objective and the optimum moves toward smaller models trained far longer — deliberate over-training, which is what Llama-2-7B and Gemma-2-9B were doing at roughly 290 and 889 tokens per parameter.
Sparsity moved the target again. In a MoE model two quantities have to be kept apart: total parameters govern roughly how much the model can hold — knowledge, facts, the long tail — while activated parameters and effective depth govern roughly how far it can think, how many steps of a causal chain it can carry before it comes apart. A dense 20:1 ratio does not transfer. And the ratio isn't a single number at all: Roberts et al. (2025) find the optimal tokens-per-parameter is task-dependent, with memorization favoring more parameters and reasoning favoring more data. Follow-up work on MoE observes that at fixed TPP, pushing total parameters higher actually degrades reasoning, while activating more experts reliably helps it.
This matters for what we are building toward. Finding a vulnerability is not a retrieval problem. It doesn't come from having memorized more CVEs; it comes from carrying a twenty-step chain of inference to the end without losing the thread. That capability does not live in total parameter count.
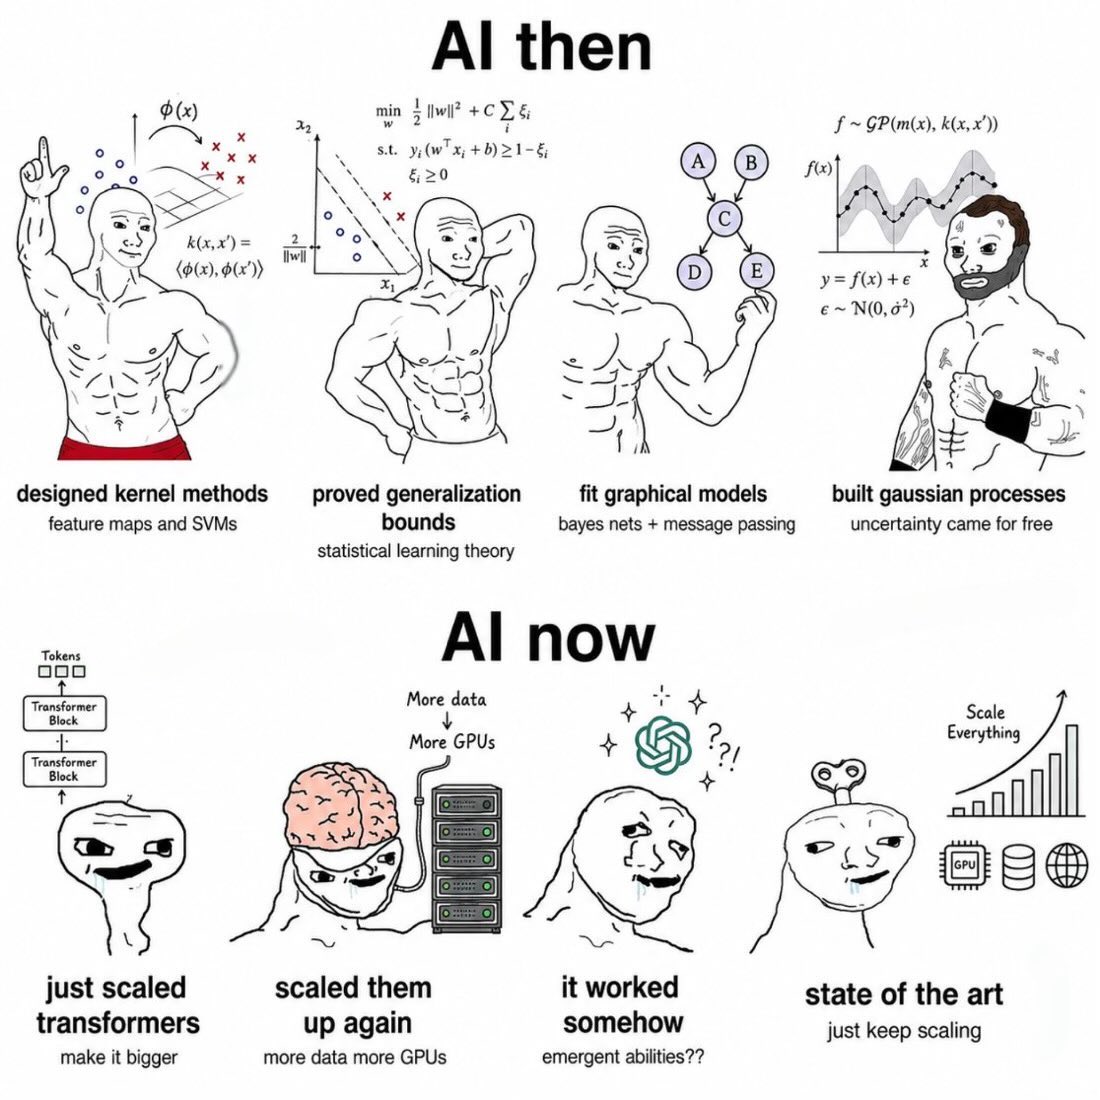
Which brings us to this release. Total parameters appear to matter up to a threshold — enough to hold the world — after which additional capability comes from scaling elsewhere: effective depth per forward pass, and above all post-training. GLM-5.3 is our controlled experiment on that claim. Same base, same architecture, same total and activated parameters as GLM-5.2. One month of scaling long-horizon environments and RL. The gains are not marginal. Well, scaling has more than one dial. We turned the post-training one this time because it had the most slack left in it — not because the others are finished. Base model size, pretraining data, compute spent per forward pass: all of them are still on the table, and we will come back to each. What this experiment taught us is that the dials do not have to be turned together, and that the one worth turning next is rarely the one that was worth turning last. We are not done scaling. Next time, maybe mid-training, pre-training, and even more.
Releasing the model weights and technical report of Kimi K3.
Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window.
New model architecture: 2.5x the intelligence per unit of compute, not just more params.
Alongside Kimi K3, we're opening up more of the stack behind it — high-performance attention kernels, MoE communication library, and infrastructure for running agent environments at scale.
Model weights: https://t.co/7m7eEg6Y0B
Tech report: https://t.co/yeu6cjpMCT
Tech blog: https://t.co/YTfiMSNM1f
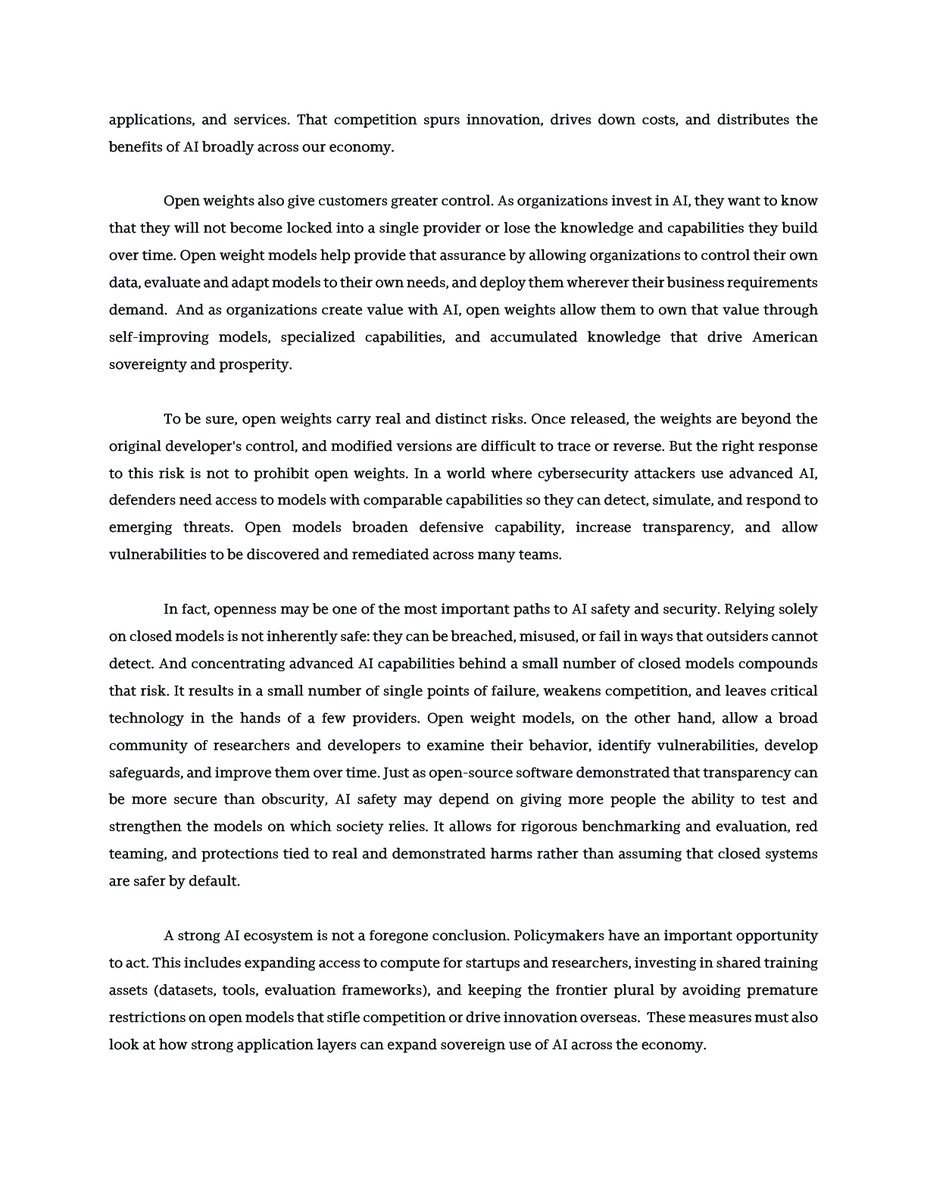
Open-weight models are essential to a healthy AI ecosystem. Together with others across our industry, we are outlining a path for open-weight models to strengthen American competitiveness and expand economic opportunity, while protecting national security. https://t.co/Tr0sAzAxTD
Where I currently stand on how distillation is used and what performance uplift it uses.
For context, Anthropic HAS said that DeepSeek and others are using their models in an RL shaped data pipeline, but that does not mean it has substantial effect. These were very small numbers of samples, and likely to initialize an internal model or do a small training experiment.
The place where distillation is used as a key step is in SFT and/or midtraining (for seeding reasoning behaviors, thinking of sft and midtraining as separate is not helpful). This is why the Chinese models say they're claude -- when training with next-token prediction, the models learn "features" that are clusters of tokens, which will regularly appear in model outputs.
This SFT data is generated by skirting the intended behavior of the API and getting reasoning tokens out. Without getting the reasoning tokens directly from the model, the data would be very hard to train on (and likely not include the "I'm claude" behaviors).
SFT datasets have been O(1 million prompts) with high quality completions. Today, getting the prompts is often the hardest part -- especially prompts with carefully designed environments for proportional RL later, but this is mostly about SFT.
Getting to the end of it. The part where this SFT distillation is likely very useful is when a model moves into a new domain, a great example being the CripPT physics benchmark, where the US labs are far ahead. The idea would be to get some prompts, and get completions from a frontier model that you can use for an initial SFT.
With an initial SFT set, there is A TON of work to still do to get a model in the performance ballpark of GLM 5.2 and Kimi K3. The SFT stage is the start of a long, strenuous process for building a post-training recipe. It involves generating more SFT data and filtering it, something like rejection sampling, and polishing the behavior with extensive RL.
For models like Kimi K3 and GLM-5.2, the timeline is such that Fable 5 likely had no impact as a distillation teacher. That could help future models, though.
And as post-training becomes more dependent on techniques like multi-teacher on policy distillation, rather than just RL, there is even more complexity in how SFT distillation helps the final model. There are a lot of steps, and RL has been meaningfully scaled up in it's proportion of the final performance.
The real kicker for this is that in the above SFT stages, the best teacher models aren't normally the easies to integrate into the post-training recipe! The leading fully open, reasoning SFT works (open thoughts and olmo) have had a very hard time updating their recipes to use the strongest models as teachers. Often it is a smaller, surprising model which is the best teacher. This means that it may not even be the cutting edge models that are enabling distillation! Messy.
All together, the evidence in post-training is that distillation is becoming less impactful. Previously, before scaling RL, distillation was more impactful because the relative amount of performance gained from SFT on top of the base model was far higher.
I expect this trend to competitive, with how strong the best open weight models are -- and the teacher ambiguity clamps down on arguments that open-weight models are just "distillation washing" by removing the need to use Claude/GPT APIs. It could be that open models are just genuinely easier to distill from, by being easier to modify and tinker with.
✉️🇦🇷 Leo Messi’s letter.
“𝑳𝒊𝒐𝒏𝒆𝒍 𝑴𝒆𝒔𝒔𝒊’𝒔 𝒍𝒆𝒕𝒕𝒆𝒓. ❤️🩹🥺
The pain is immense, it will take time for this wound to heal.
But I also choose to hold on to all the good things, all matches we turned around by giving everything and moments that will remain in our memories forever.
I will always remember the support of an entire country that, together with the work and effort of this group, brought us back once again among the best teams in the world.
Today, it is difficult to appreciate what we achieved… but this group has really reached two consecutive World Cup finals.
Thank you from the bottom of my heart for every greeting and every message.
Once again, we managed to come together as a country and stand united, sharing the immense pride of being Argentine.
I also want to congratulate Spain on winning World Cup”. 🇪🇸
Antes del partido, el equipo de Egipto recita una cita del Coran contra los infieles
Cuando Egipto se puso 2-3 contra Argentina parece que el DT hizo la seña contra el racismo
Luego cuando se le pidió que explique la razón por la que hizo la seña, no dio ninguna explicación
Está claro que la abuso para detener el partido, y está claro que la seña debería haberla hecho todo el plantel argentino después de enterarse del contenido del rezo en el vestuario de Egipto
Estoy cansado y asqueado de la manipulación que hacen especialmente los musulmanes para siempre tratar de situarse en el papel de víctima, les encanta infantilizarse y en parte esto pasa porque el mundo los acompaña en esta estupidez, hay que ponerle un freno ahora y para siempre
new post on harness engineering for AI self-improvement: https://t.co/ZYvGfVs61k
It is hard to forecast how much the future of RSI will rely on harnesses. Likely harness engineering will evolve in the direction of self-improvement and enable auto-research, and, in turn, smarter models keeps harnesses simple.
Even when many harness improvement get eventually internalized into core model, the need to specify goals and context will not disappear.
🚨🏆 Cristiano Ronaldo: “I’ve won Euro 2016 and for me it has same dimension as the World Cup”.
“That remains forever. Tomorrow is a new day, and we go”.
🚨🏆 Cristiano Ronaldo: “I’ve won Euro 2016 and for me it has same dimension as the World Cup”.
“That remains forever. Tomorrow is a new day, and we go”.
Madame Celeste Amarilla,
Vous êtes une femme méprisable et indigne de sa fonction.
Vous ne représentez pas le Paraguay, ce pays qui a transpiré la passion et l’honneur tout au long de la compétition. Par votre inconscience et votre racisme décomplexé, le monde entier a déjà oublié le parcours et l’effort historique que vos joueurs ont réalisés durant cette coupe du monde pour laisser place à une dame incompétente donnant la pire image possible de son pays.
Je ne laisserai jamais aux gens comme elle, la liberté de laisser propager leur haine et leur racisme à travers le monde.
A super long overdue (3+ years?) post on scaling laws.
Compute is expensive. Scaling laws are a way to help us reason about the optimal compute allocation between data and model size before committing to a large run.
The post covers what scaling laws predict, how compute-optimal allocation works, why Kaplan et al. and Chinchilla disagree, and how data limits + fitting details make extrapolation tricky.
https://t.co/HP26eJvjHB