For over 20 years, we've dedicated ourselves to removing language barriers so people can learn, speak and connect more deeply than ever before.
Today, we’re taking our next step with the release of Gemini 3.5 Live Translate — our latest audio model for live, speech-to-speech translation across 70+ languages. 🧵
Introducing Claude Fable 5: a Mythos-class model that we’ve made safe for general use.
Its capabilities exceed those of any model we’ve ever made generally available.
Introducing Audio-to-Video in LTX.
The third paradigm in AI video generation.
Start from audio to get consistent voices, control over performance, and actions timed to the beat.
We’re proud to partner with @elevenlabs for this launch.
Here’s how it works (sound on) 🧵
Google Unveils the Future of AI Shopping
Google has announced the launch of the Universal Commerce Protocol (UCP), a new open standard designed to streamline how AI agents navigate the shopping experience. Developed in partnership with major retailers like Shopify, Etsy, Target, and Walmart, this protocol allows different systems to communicate seamlessly, laying the groundwork for a standardized AI shopping infrastructure.
The most significant update for consumers is the upcoming integration of native checkout. Powered by UCP, users will soon be able to purchase items directly within the Gemini app and AI Mode, removing the friction of navigating away to external websites to complete a transaction.
Apple's new paper is mindblowing
They showed that one attention layer is enough to turn pretrained vision features into SoTA image generators!
This dramatically simplifies diffusion models while keeping the top-tier quality
ITS HAPPENING
>anthropic preparing for ipo as soon as 2026
>investors are enthusiastic
>anthropic can front-run openai by going public first
>dario in talks for a round at a $300–350B valuation
>will be one of the largest ipos ever
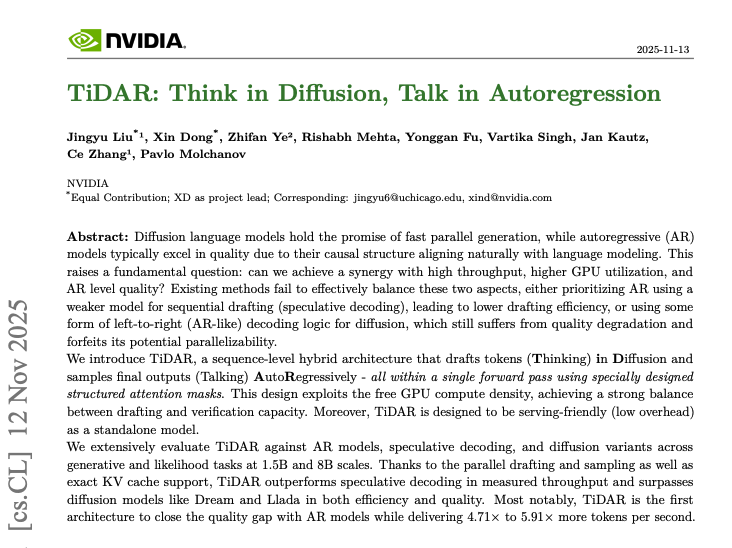
NVIDIAが、LLMの「速度 vs 品質」のトレードオフに正面から切り込む論文を発表しました。
拡散的な更新で一度に複数トークンをドラフトしつつ、最終的なサンプリングは自己回帰(AR)で行うハイブリッド手法「TiDAR: Think in Diffusion, Talk in Autoregression」です。
TiDARの技術的な概要と主要なポイントです。
拡散モードとARモードを単一のTransformer内に統合し、専用の注意マスクを用いることで「拡散で並列ドラフト → ARで検証・確定」を1回のフォワードで実行します。これにより、GPUの「空きトークンスロット」を拡散ドラフトで埋めつつ、ARと同等レベルの品質を維持します。
・Think in Diffusion:拡散的な目的で未来の複数トークンを並列ドラフトし、GPU計算資源を無駄なく使う
・Talk in Autoregression:ドラフトをARとして1トークンずつ評価し、受理/棄却しながら最終出力をサンプリングして品質を担保
この手法は、従来のARモデルと比べてトークンスループットを大幅に高めつつ、ほぼ同等の品質を保つことを示しており、LLM推論のアーキテクチャ設計にブレークスルーをもたらす可能性があります。
・拡散ベースの並列ドラフティングで、GPUの「遊んでいるトークンスロット」を有効活用
・ARサンプリングにより、純粋な拡散LMよりも安定した高品質な出力を維持
・単一モデル・単一フォワードで動作するため、実運用を意識した高スループット・低レイテンシなLLM設計の具体例となる
https://t.co/Fl5d3i8C2V