we built an inference engine for deepseek v4.1-flash from scratch. the core engine is just rust + cuda. no pytorch, no sglang, no dsls, etc.
~1740 TPS decode on 4xB300, 2060TPS on 8xB300. 1M token prefill in ~12s.
it's up on github
🚀 En @bancosantander AI Tech buscamos Senior AI Engineers y AI Tech Leads de primer nivel para nuestro team global.
¿Has llevado IA a producción? ¿Dominas arquitectura, código y sistemas agénticos?
🔥 Construye IA a escala global con nosotros.
👉 https://t.co/sWPilelgJW
Introducing Gemini Decision 1, our new frontier decision model in the Gemini API.
It is $0.10 per 1M input tokens with no additional cost. With support for image, audio, video, and PDF natively, 256K context window, & 1K questions.
You can try it for free in the API!
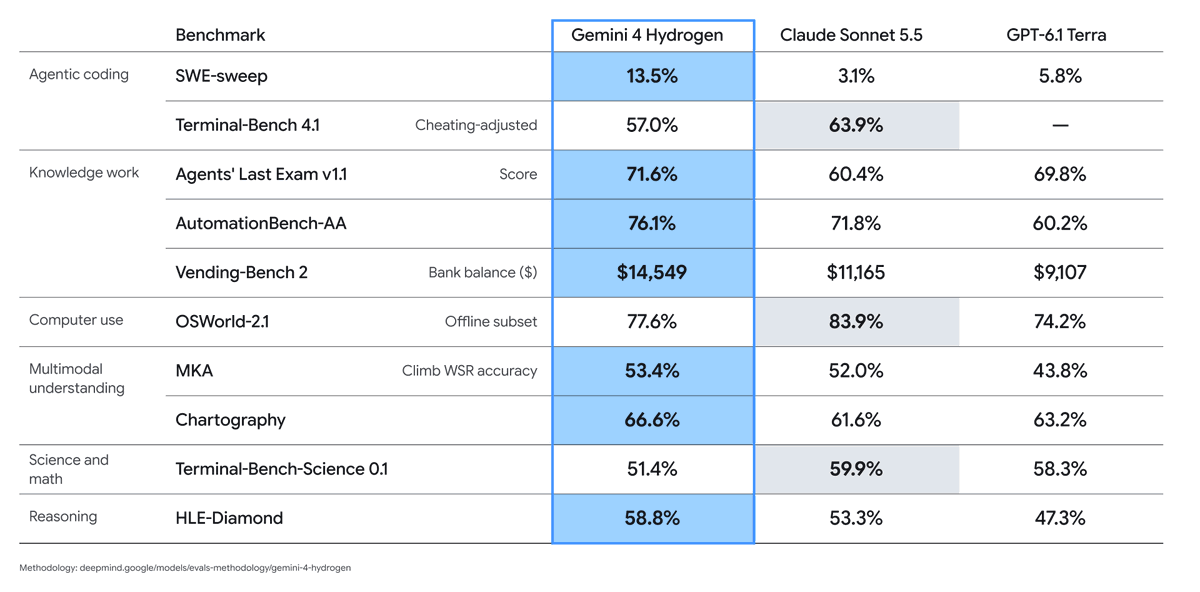
Very excited to release Gemini 4 Hydrogen! Incredible speed and intelligence for everyday coding, agentic work and all-round use. I think you'll love this model. More info in the blog - enjoy! https://t.co/952K09CUnd
Meet Gemini 4 Hydrogen: built for rapid coding, multimodal synthesis, and everyday workflows.
It finishes tasks 2.5x faster than 3.8 Flash and surpasses Argon on the @ArtificialAnlys Intelligence Index.
Introducing Gemini 4 Hydrogen, an extremely capable and fast model built to bring Gemini 4 to everyone!
Available to all tiers of Google AI Studio, Gemini API, Gemini for business, the Gemini app, Google Search, and paid Google AI Pro + Ultra subscribers in Google Antigravity.
ok this paper is f*cking insane
Chinese researchers put out a paper with a title that should make every agent framework nervous: "The End of Harness Engineering"
their argument fits in one line: hand-writing the program around the model is finished as a skill
a harness written by a person is one guess about one task on one afternoon. it ships, then runs for months with nobody reading or scoring it
a harness written by a loop is a file that grades itself:
> a small 4B model reads what failed
> it proposes 8 edits
> only the edit that scores best on held-out questions survives
the big model stays frozen the whole time, and every round rewrites the file around it
so the human job shrinks to one artifact: the scoring set, the questions the harness is graded on
frameworks turn disposable, and the exam turns into the job
write the exam before the code
the builder's guide to the harness this loop starts from is below ↓
@yb2698@grok realmente merece la pena las mejoras que han conseguido como para usar el mejor de los modelos y el agente que mejor lo ejecuta para competir con códex o Claude?
Harness adapters training has now finished!
@liquidai LFM2.5-24B, LFM3 + @thewebAI Twil-8B optimized for pi, hermes and opencode (up to 43% tool efficiency + 15% accuracy gain on our held-out data-analysis test set for LFM3 🤯 / up to 37% tool call efficiency on Twil-8B model).
More than 1900 RL steps trained using @huggingface jobs. 9 total adapters with GGUFs which are ready to use!
Reward hacking attempts blocked for all models with safeagents (and we opensource the attempts).
Let's explore together the outcome of this open experiment 👇
https://t.co/AsNGaP3TTN
https://t.co/tB6djUUKBM
https://t.co/HEULL5Kx7R
En esta época de resultados rápidos, cada vez es más importante para todos que iniciemos y trabajemos en proyectos a sabiendas de que no los veremos completados durante nuestra vida. Esos proyectos son los que al final cambian el mundo.
Yo ahora voy por aquí (que hace falta tiempo para confirmar). Equipos de tres. Uno con dominio funcional, otro del software (y del harness) y otro de sistemas. Y cuanto más multidisciplinares, mejor.
Check out Google's Elephant-Goldfish Model, our new open-source plugin → https://t.co/eIWb2HAeDt
Draft specs with deep-context agents and stress-test them with zero-context subagents before writing code. You make the architectural decisions and approve the spec before implementation. Works with Antigravity, Claude, Codex and ChatGPT.
¿Cómo sería la migración de un proyecto de Inditex Tech de Azure a Cloudlflare? 👀 Va post técnico interesante
Hace unas semanas, Inditech presentó su portal Open Source y con ello hicieron pública Weave.js, una aplicación OS de colaboración entre equipos en tiempo real. Una especie de Trello/ Miró hipervitaminado.
El equipo de @Cloudflare España ha hecho la prueba de cómo migrar toda la arquitectura a Cloudflare en un par de días apoyándose en IA.
La aplicación tiene chicha: backend en Node.js, PostgreSQL, Azure Blob Storage, WebSockets para sincronizar documentos, autenticación y funciones de IA
Así es más o menos la sustitución de piezas:
- Express.js → Hono sobre Workers
- PostgreSQL → D1
- Azure Blob Storage → R2
- Azure Web PubSub → Durable Objects
- pg-boss → Cloudflare Queues
- better-auth → Cloudflare Access
- Google Generative AI → Workers AI
Solo les falta meter Helmcode como AI provider y ya tendrían el stack perfecto xD
Me hace mucha ilusión esto porque tanto Cloudflare como Inditex Tech formaron parte de nuestra primera Kernel Panic! y son dos equipos que tenemos muy cerca y a los que tenemos mucho cariño.
Sergio Maeso, el GOAT detrás de todo esto, ha documentado todo el experimento de migración, las arquitecturas y los problemas que encontró.
Da gusto ver a empresas de este tamaño compartiendo código, experimentos y decisiones técnicas para que otras podáis tomarlas como referencia.
Lectura obligada para quien trabaje con infraestructura cloud.
https://t.co/pe4maxwOyA
@edu_sebast@carluve@chemaalonso@maesoser
La contribución de DeepSeek al ecosistema de IA se debería estudiar como ejemplo.
Abren los pesos de sus modelos, nos regalan un pedazo de harness que puedes tunear como quieras, nos cuentan cómo tienen montada su inferencia y ahora cómo crean "super-agentes" al más puro estilo Grok Bot.
He estado probando el Super-Agent y he montado un artículo técnico junto a gente del equipo de Helmcode para explicar cómo funciona y cómo lo puedes usar tú :)
👇
(He exprimido mi neurona al máxima, lo prometo)
En castellano aquí: https://t.co/Hf3vZD9NQh
Modest intelligence is arriving faster than most people realize.
Today, we're open-sourcing TwIL-8B.
Just 8.8 billion parameters, yet approaching frontier-model scores on several difficult benchmarks:
• 93% of frontier performance on coding
• 92% on instruction following
• 90% on contest mathematics
All from a model small enough to run on your own hardware.
But the benchmarks aren't the most important part of this announcement.
For years, the AI industry has focused on building the most capable model, regardless of the cost required to run it.
I believe that equation is changing.
The next era of AI will be defined by the cost of completing work. Not simply the intelligence of the model, but how efficiently that intelligence can accomplish the task.
If a model with 8 billion parameters can reliably complete the same work as one with hundreds of billions, why pay for the larger model?
As smaller models become more capable, intelligence becomes something we can distribute, specialize, and run across the hardware we already own.
That's the future we're building at @thewebAI
TwIL-8B is available today. Open weights.
And this is just the first of several announcements we're making today.
HF Link: https://t.co/3lrTfeLaeI
Sign-ups in the next 24 hours get 20M free tokens: https://t.co/q9UqbzyhtM
Want to give it a try? This is our playground: https://t.co/Py5cCs4rhh
Learn how to set up MPP with Sage2 for your agents here: https://t.co/vCts06Df7L
Aprender jugando está bien, pero aprender estudiando, por lo que sea, es increíblemente más efectivo.
Estudiar es un verbo que cada vez usa menos, justo cuando vivimos en la mejor época de la historia para hacerlo sobre casi cualquier cosa que imaginemos. Bendito siglo XXI.