Your MacBook can now host a coding agent at 300+ tps!
I gave DeepSeek V4.1 Flash a job: write a specialized inference engine for LiquidAI's LFM2.5-24B-A2B on Apple's M5 Max. For $21 of API, it built Molten: 300+ tps, about 1.5x faster decode than mlx-lm and llama.cpp.
Why specialized? General frameworks like mlx-lm and llama.cpp have to run any model on any hardware. A specialized engine serves one model on one chip at batch size 1, so there is far more room to optimize.
Molten is native Rust + Metal: one ~6 MB binary, no Python, PyTorch or MLX. It comes with a chat CLI and an OpenAI-compatible server with streaming and tool calls, so you can point your own coding agent at it. It needs an M5-series Mac with 24 GB+ (sorry, M1-M4 friends).
The numbers (M5 Max, 128 GB)
• 305 tps at 256 tokens of context, vs 190 for mlx-lm and 199 for llama.cpp
• Still 248 tps at 16K, where coding agents actually live (mlx-lm: 165)
• Faster time to first token: 1.76 s vs 2.17 s for a 16K prompt
• Same weights and math as mlx-lm
How it was built
The agent (DeepSeek V4.1 Flash in the Pi harness) ran in a recursive self-improvement (RSI) loop. Each session starts from the best engine so far, plus the feedback from every earlier round. A fixed evaluator rebuilds each candidate from source, checks its tokens against mlx-lm, times and profiles it. Only correct and faster engines survive.
• Hour 3: first correct engine, 0.56x mlx-lm
• Day 2.5: passes mlx-lm
• Day 5.7: 1.28x end to end, 1.53x decode
78 agent sessions, about $21 (1.36B tokens, 98.6% of them cache hits).
What the RSI loop found useful for speeding up:
• Fuse chains of small ops into single kernels: norm + router + top-4 expert pick, expert FFN + combine, Q/K/V projections + KV-cache write, Q/K norm + RoPE + attention, LM head + argmax.
• Keep the decode loop on the GPU. Tokens never round-trip to the CPU, and the GPU stays 99% busy.
• Hard-code every shape, so the 4-bit kernels stream weights at ~75% of the memory bus.
• Target the hardware: prefill runs on the M5 GPU's Neural Accelerators through Metal 4 tensor ops, with MoE routing and expert GEMMs fused and kept on the GPU.
(It's not Rust, by the way. llama.cpp is native C++ too. It's the specialization.)
TBH, I don't fully understand all of it yet lol. The agents wrote this in under 6 days, and it's going to take me longer than that to read it. As the human researcher, I'm now officially the slowest-improving component of my own RSI loop🤣, so I'll spend the next few weeks learning from my agents.
Where I think this goes: local inference will matter more and more, and a specialized engine can beat a general one. As RSI matures, the cost of building one keeps falling toward zero. I think every model, every chip, and maybe every workload will eventually get its own inference engine.
The idea is inspired by @perplexity_ai 's Lily. Thanks to @liquidai for the great model, and Apple's MLX, whose kernels Molten adapted from.
Repo here:
https://t.co/E0iayak9C4
DeepSeek V4.1 Flash 1017 runs at 1,521+ tok/s on Fireworks Ultrafast.
Fast enough to ship Tetris in 11 seconds, 7x faster than Claude Opus 5.5.
Join the Ultrafast waitlist: https://t.co/vE0jM7Lyou
Meet Flint from @Recursive_SI! A ~40B parameter MoE open model for fast, accurate agentic coding use case made to run on-device.
Flint can generate >125 tps on a M4 Pro Macbook Pro and >150 tps on a 64GB NVIDIA RTX Spark on short contexts.
Try it on Ollama today:
ollama run flint
Claude Code:
ollama launch claude --model flint
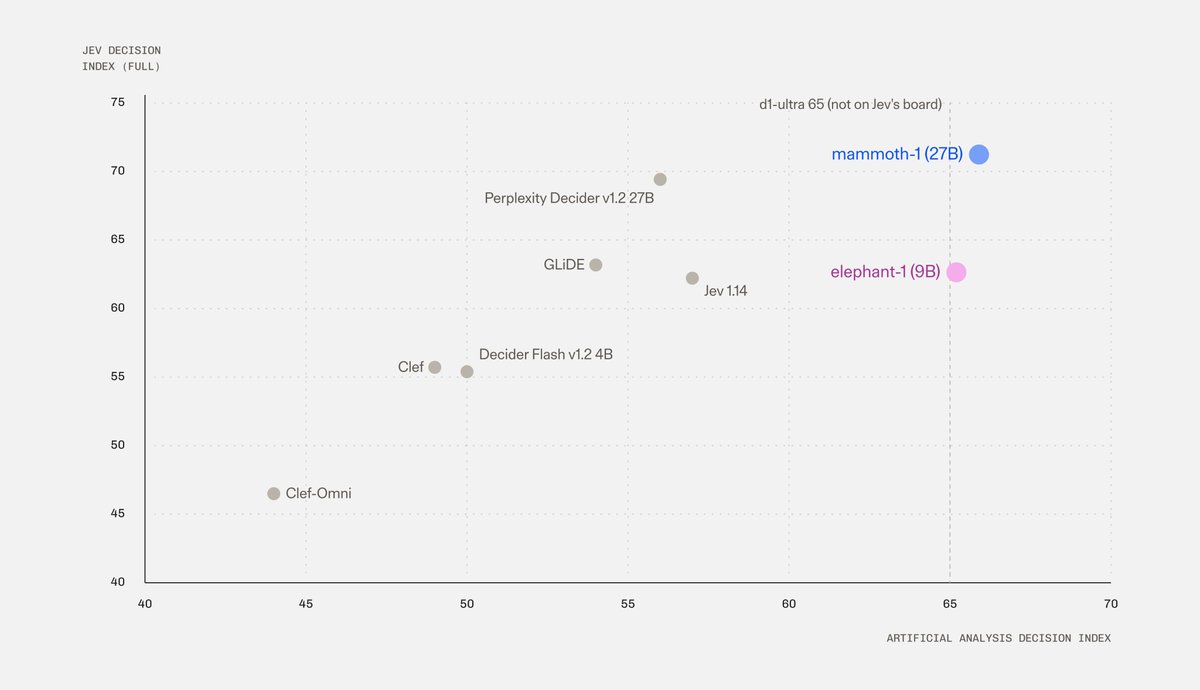
Today we release mammoth-1 and elephant-1!
We post-trained mammoth-1, the #1 ranked best decision model in the world, and elephant-1, which is the best model under 15B (and beats Jev).
We're open-sourcing all model weights and provide a technical report detailing all our training and data methods.
Me encanta leer o escuchar al que usa modelos en un tema que no tengo ni idea y él domina.
Como "buen" programador, el tema del diseño me supera y me maravilla a la vez.
Almost feature complete for 1.0:.
Xogot for Mac Beta 4 brings a full 3D modeler, native AnimationTree editors, exports to Windows, Linux, Android, and the web and support for side-by-side installations:
https://t.co/Bwbl3MkJEt
Acabo de probar la última actualización de https://t.co/xVQpZXT0Vs 1.1.1
Qwen3.5-2B Q/4 bits ->95,08 tok/s
Tiempo hasta el primer token
88 ms
La cosa no sería impresionante si no fuera porque es una RTX 3050 Vram 4Gb
Gracias @ashxhart
Ahora me toca ayudar a otros -> localIA