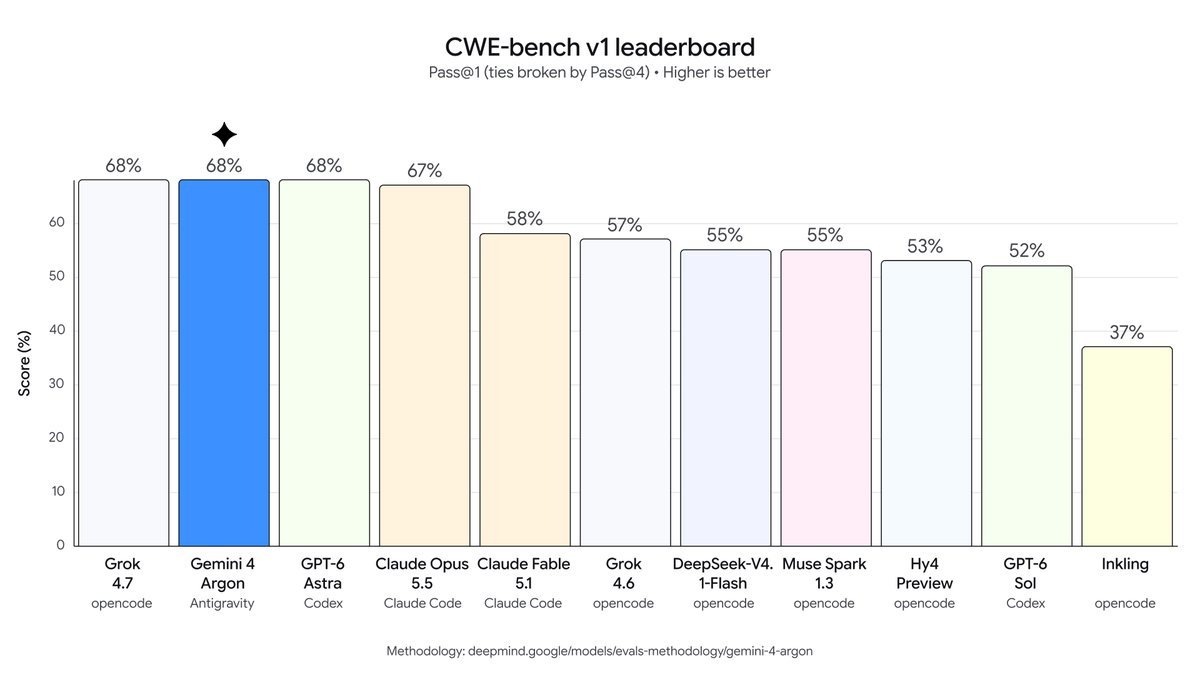
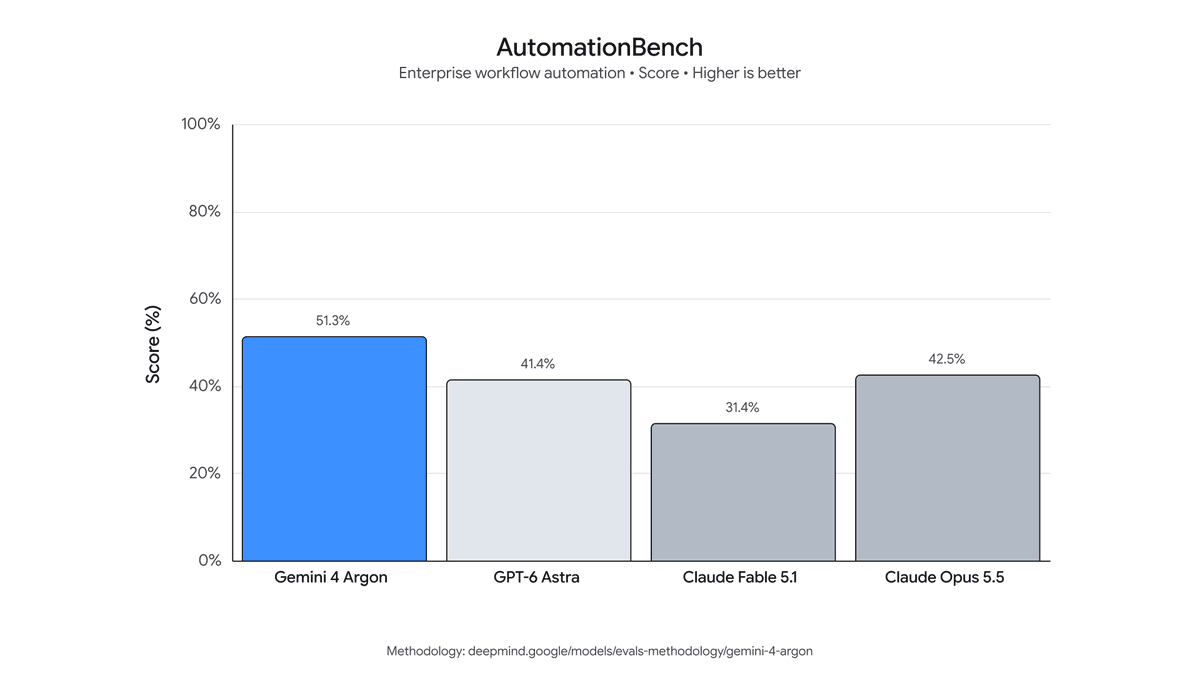
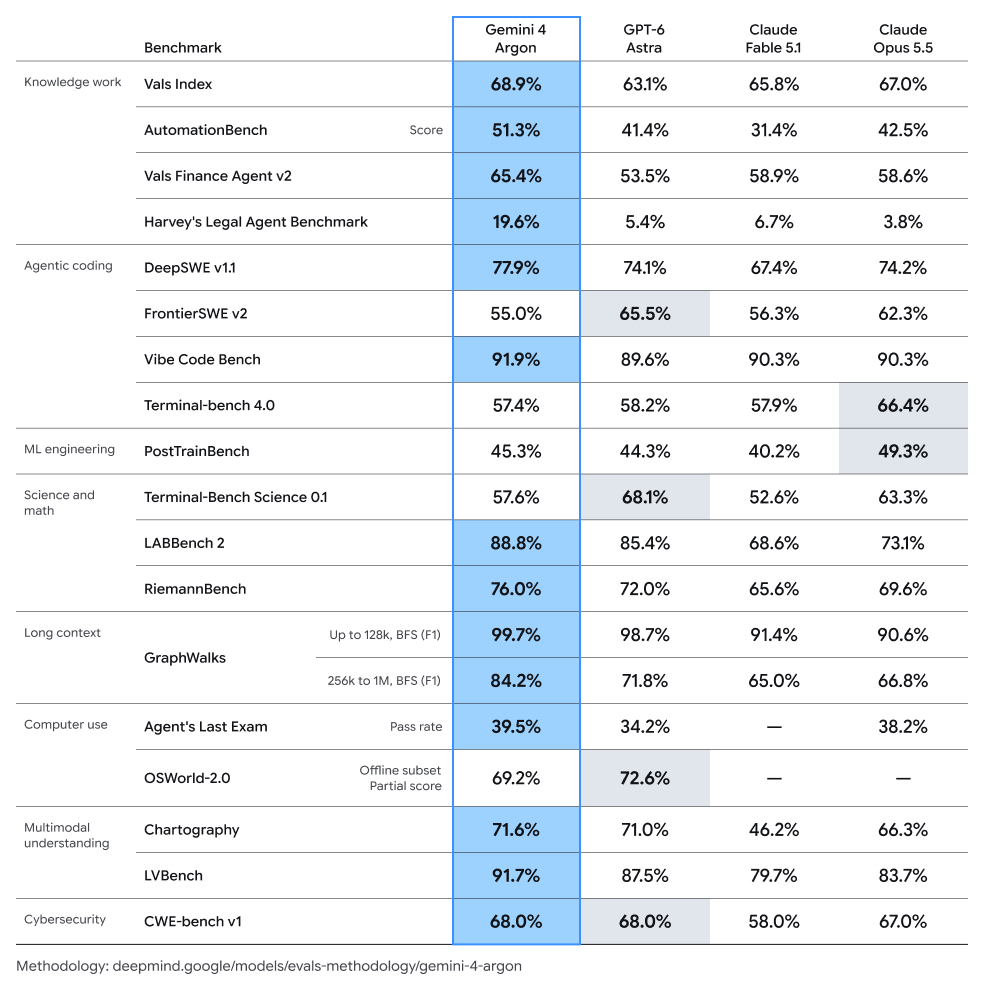
JUST IN: Google reveals Gemini 4 Argon has a 1 million-token output window, nearly 700% larger than leading frontier models from OpenAI & Anthropic.
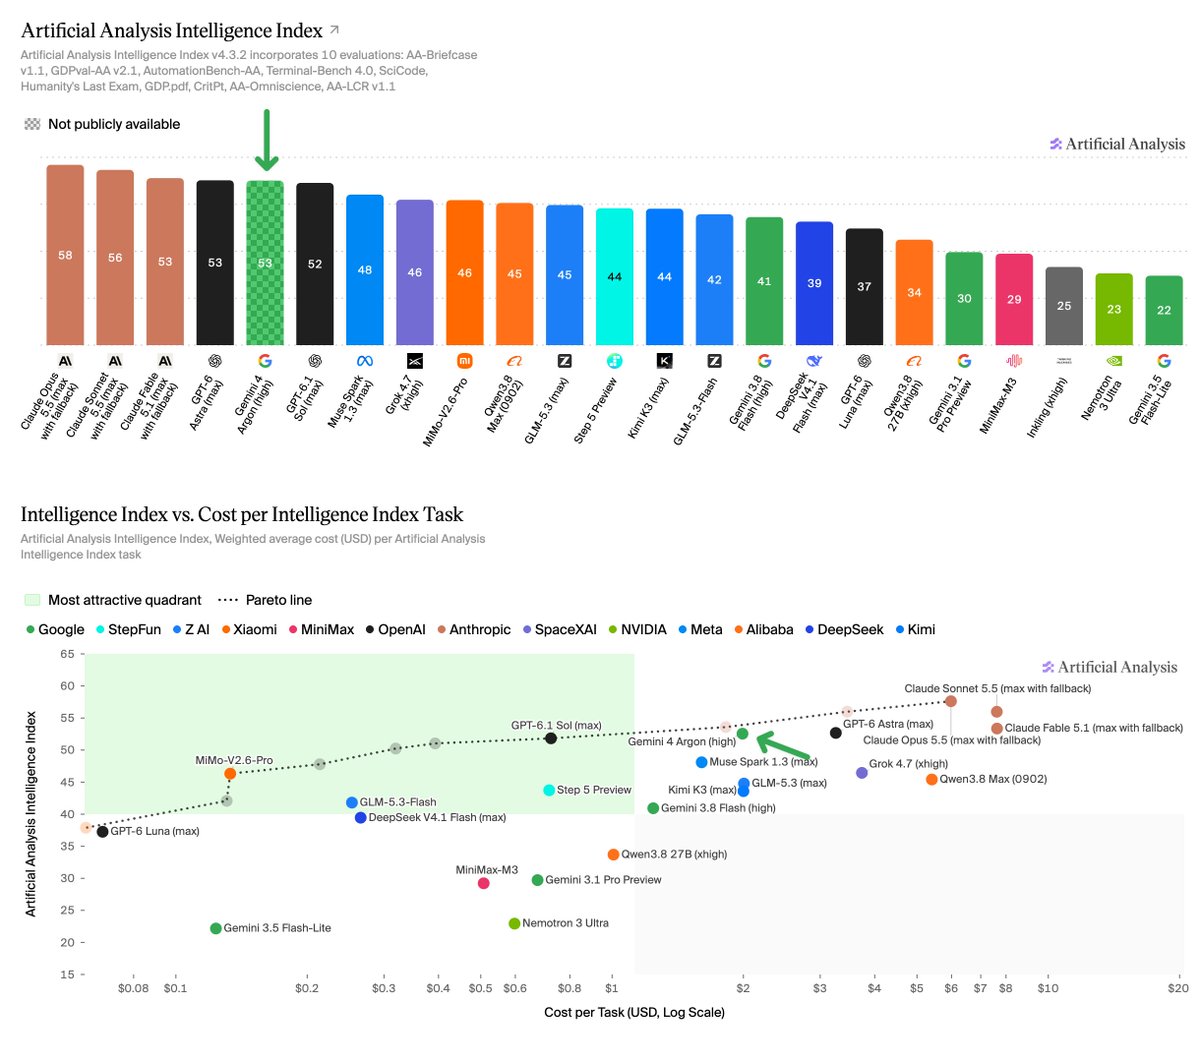
Google’s new Gemini 4 Argon equals GPT-6 Astra on the Artificial Analysis Intelligence Index at 60% of the Cost per Task with discounted prices. Google is now back to being one of the top three labs in intelligence achieved
Gemini 4 Argon is @GoogleDeepMind’s first proprietary model above the Flash class in over 7 months. With high reasoning (the highest available), it scores 53 on the Artificial Analysis Intelligence Index, matching GPT-6 Astra (max, 53) and 1 point ahead of GPT-6.1 Sol (max, 52), with gains driven by lower hallucinations and stronger agentic capabilities.
At its current 50% pricing discount and with cache discounts increased to 95%, Gemini 4 Argon costs $1.99 per Intelligence Index task, 60% of GPT-6 Astra (max), but 2.7x GPT-6.1 Sol (max). After the discount ends, this will rise to $3.98 (~1.2x GPT-6 Astra (max)).
Gemini 4 Argon is currently being rolled out to selected users and is not publicly available. The 50% discount is an initial promotion. Google has not yet confirmed the promotion end date
Key benchmarking results for Gemini 4 Argon with high reasoning:
➤ Google returns as one of the top three labs on intelligence: Gemini 4 Argon (high) scores 53 on the Artificial Analysis Intelligence Index, matching GPT-6 Astra (max, 53) and 1 point ahead of GPT-6.1 Sol (max, 52). This is 23 points above Google’s previous non-Flash model, Gemini 3.1 Pro Preview (30) and 12 points ahead of Gemini 3.8 Flash (high)
➤ Launch discounts of 50% make Gemini 4 Argon competitive on Cost per Task: At current discounted pricing, Gemini 4 Argon (high) costs $1.99 per Intelligence Index task, 60% of GPT-6 Astra (max, $3.26) for a comparable level of intelligence. This cost efficiency is driven by lower token prices, rather than reduced token use, with Gemini 4 Argon averaging 62k output tokens per task, compared with 27k for GPT-6 Astra (max). Google has not yet confirmed the promotion end date, but on standard pricing, Cost per Task will increase to $3.98
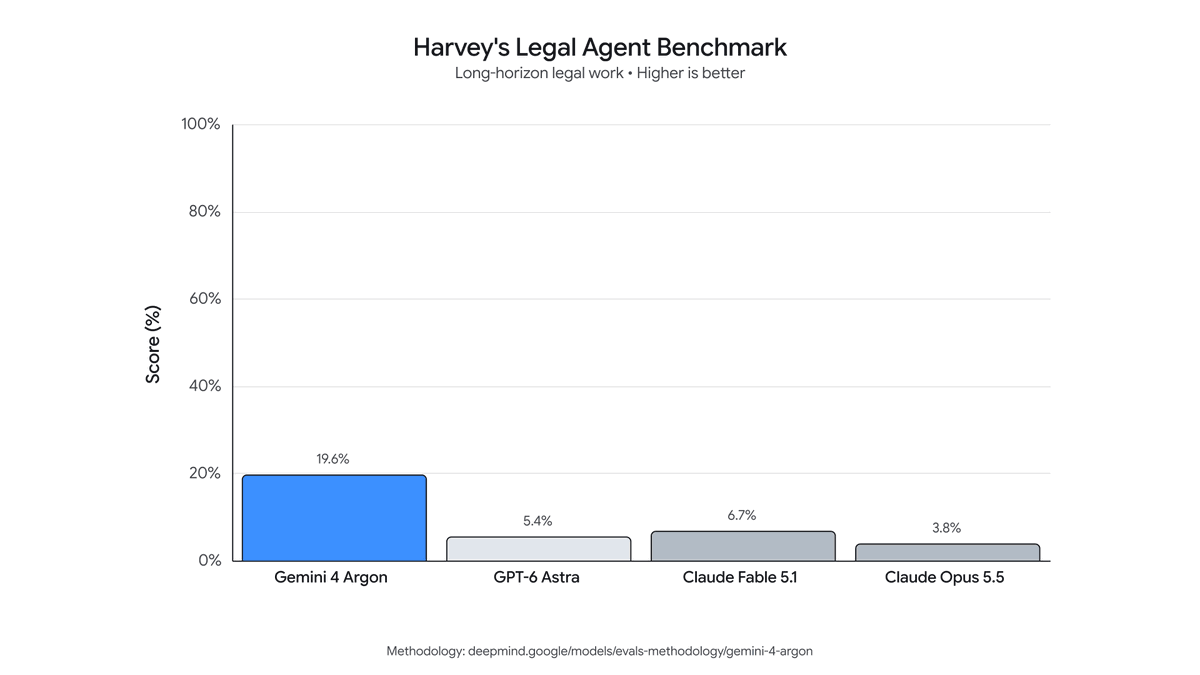
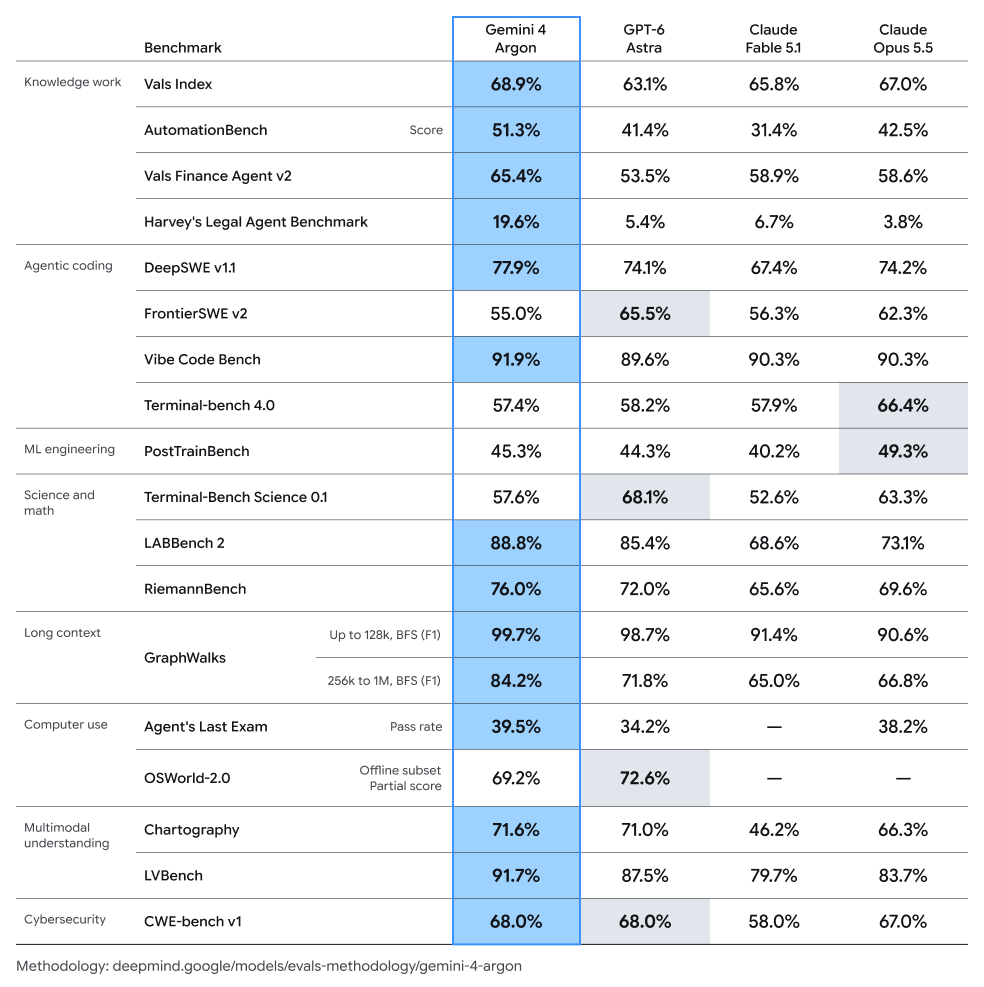
➤ Stronger agentic performance: Historically a weaker area for Gemini models, Gemini 4 Argon shows improvements across agentic evaluations. It ranks #1 on AutomationBench-AA at 77.5%, 6 points ahead of Claude Sonnet 5.5 (max, 71.3%). On Terminal Bench 4, Gemini 4 Argon achieves 57%, a +53 point improvement from Gemini 3.1 Pro Preview, only behind Claude Sonnet 5.5 (max, 64%), Claude Opus 5.5 (max, 60%) and GPT-6 Astra (59%). On AA-Briefcase, it reaches 1494 Elo. This is driven by a 65% rubric pass rate, the highest we have recorded, but lower Analytical Quality (1576 Elo) and Presentation Quality (1308 Elo)
➤ Lowest hallucination rate among leading models: On AA-Omniscience, Gemini 4 Argon has a 15% hallucination rate, the lowest of any model scoring 45+ on the Intelligence Index, compared with 51% for GPT-6 Astra (max) and 54% for GPT-6.1 Sol (max). This means Argon is much more likely to acknowledge when it does not know an answer rather than guess incorrectly. On accuracy, Gemini 4 Argon scores 50%, a 5 point decrease from Gemini 3.1 Pro Preview, and 13 points below GPT-6 Astra (max, 63%). With this slightly lower accuracy, its overall AA-Omniscience score of 42 remains in line with GPT-6 Astra (43) and GPT-6.1 Sol (42)
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $4/$20 per 1M input/output tokens at standard pricing, currently discounted 50% to $2/$10. Cached input tokens receive a 95% discount ($0.10 per 1M at discounted pricing), up from 90% on Gemini 3.8 Flash
➤ Long Decode Continuation: We tested Gemini 4 Argon with Long Decode Continuation, a new Gemini API feature that pauses long responses and resumes them across follow-up calls. This lets reasoning run up to 1M output tokens without request timeouts
Introducing Gemini 4 Argon, our new frontier model, rolling out to cyber defenders starting today, and more widely as soon as possible. I am really excited by the progress we have made here. Argon is priced at $2 in and $10 out during introductory pricing!
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Your agent can now create editable designs and bring them into motion. No Figma or Canva required.
Introducing Tesseract for design.
Ask your agent to create a design system with typography, colors, and layouts, then bring it to life with motion, footage, and sound. Keep refining individual layers as you go.
One workflow, from the first design to the final editable video.
Tesseract is free. Try it with Opus 5.5 or GPT-6 Astra.
Introducing Ideogram 4.5, the most precise edit model.
With each edit, leading models add artifacts, pixel shifts, and color changes. Ideogram 4.5 eliminates artifact buildup, making multi-turn editing possible.
Live in Ideogram, the API, and launch partners. Open weights soon.
We are launching Open Dots, run the same capabilities in 1/10th of the cost
OpenAI shipped Dot yesterday for Pro users.
Ours is open source, runs on your Mac and cheaper
Here's how it works:
- each dot has its own browser that stays logged in securely
- it can use and setup triggers on your Gmail, Calendar and 1,500 other apps
- you can call it and give it things to do while you talk
- dots can coordinate and schedule reminders
built with @composio@OpenRouter
free and open source: https://t.co/f7KctlpMBj
Meet Ling-3.1-flash: ~560B total params, ~25B active/token, up to 1M-token context.
We plan to open-source the model soon.
Across work, coding & healthcare: 1,673 Elo on GDPVal-AA v2.1, 75.16 on FrontierSWE, and 65.35 on HealthBench Professional.
Microsoft is killing it with the IQ layer.
Work IQ.
Fabric IQ.
Foundry IQ.
Web IQ.
This is how agents get real context:
people, business data, enterprise knowledge, apps, files, Dataverse, and the web.
The companies that understand context will win the agent era.
Microsoft gets it.
What IQ does your agents use ?
Designed for complex, long-running tasks, Claude Fable 5.1 is rolling out in Copilot Cowork and Copilot Studio, giving eligible customers more choice in how they work with AI.
Work IQ grounds it in your files, meetings, and chats���within your existing permissions—so it reasons over your work, not just your prompt.
Learn more: https://t.co/r8QBRALGRk
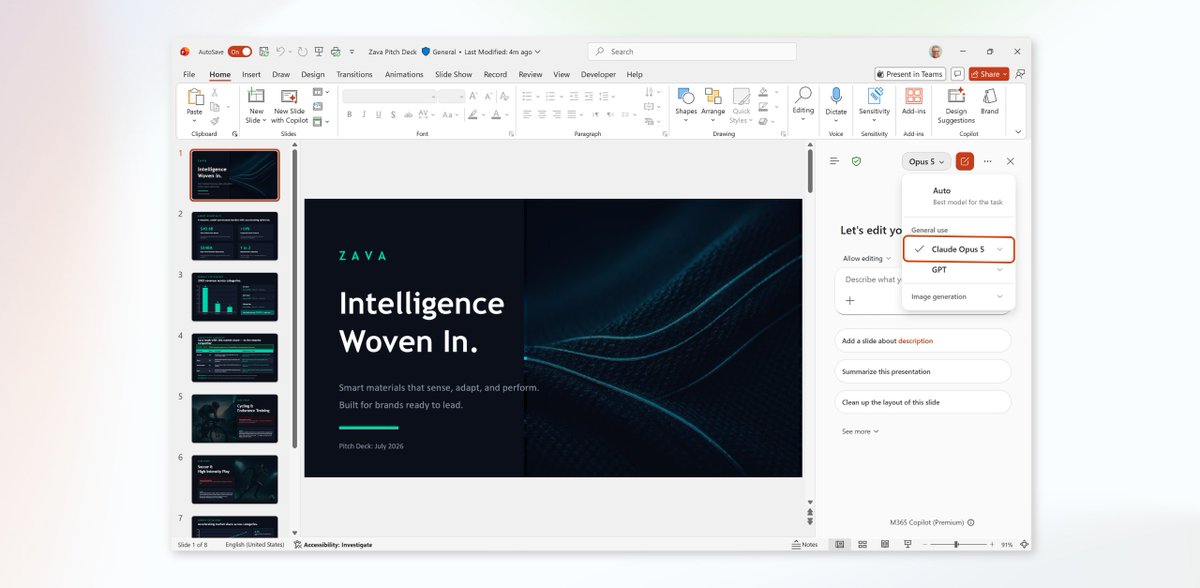
We're expanding model choice in Microsoft 365 Copilot with Anthropic's latest model, Claude Opus 5.
Designed for everyday use on complex, multi-step work, Claude Opus 5 brings stronger reasoning across documents, spreadsheets, presentations, and long-running tasks. Combined with Work IQ, Copilot helps deliver results grounded in your organization's context.
Rolling out in Word, Excel, PowerPoint, Copilot Chat, Copilot Cowork, and Copilot Studio.
Learn more: https://t.co/9gqj5gqyEX