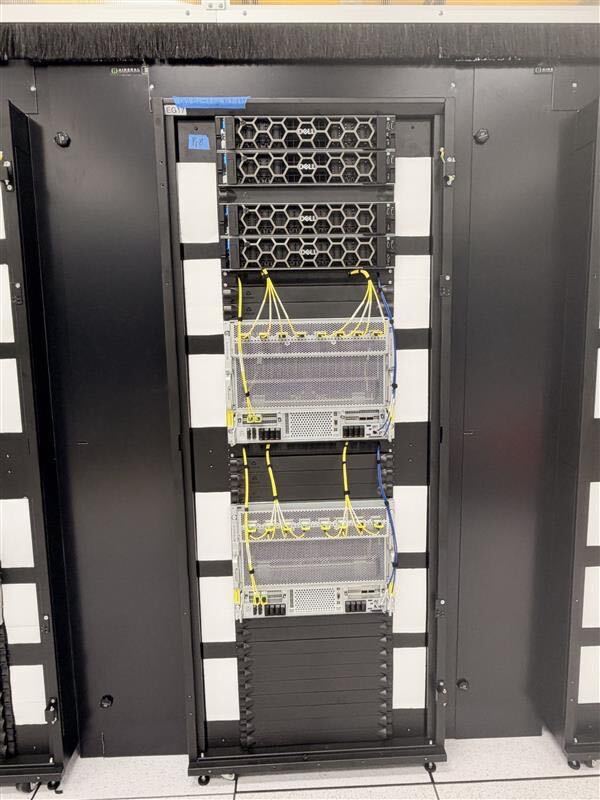
Our newest owned cluster is live: NVIDIA B300s in Denver, in the @parasail_io fleet the day after burn-in.
We have a mixed fleet of renting & owned capacity. Rented lets us scale fast and pick up new silicon as it lands. Owned clusters give us a base we control and tune for the largest customer workloads. An inference cloud locked into one way of getting compute gets stuck when the winds change.
2028 is going to be crazy.
The compute for 2027 is already locked in, but the challenge for the AI industry next year is going to be how to:
1. Change the narrative around datacenters
2. Make the value of everyday AI a no brainer
3. Innovate at the chip layer
At 8 concurrent requests, our MiniMax M3.1 Flash serving stack started repeating words. Single-request tests missed the race.
Here's how we fixed it, handled long agent sessions, and tested correctness under load:
https://t.co/nYOu1LMBSa
@deedydas The margin largely also depends on the shape and type of the traffic. The trick for most inference providers is to understand what type of traffic various optimizations and hardware is best suited for, then how to route the right workloads to them. Non trivial eng challenge
GPT-6 Luna is half the price of GPT-5.6 Luna. We’re entering an intelligence pricing war, which is fantastic for everyone. Brought to you by pressure from the OSS models.
@Yuchenj_UW K3 is my workhorse now too. Feels like a smarter opus 4.8 which was my favorite Claude model. Also been testing out glm 5.3 but doesn’t seem as good for planning and strategy. K3 still seems better overall
Kimi K3 is live on Parasail.
It is the largest open-weight model in the world (2.8T parameters), and is the most capable open model we've worked with so far.
We're excited to bring fast, compliant, and reliable production-grade access to Kimi K3 to more users with no rate limits at scale. Link to get started in thread.
We’re excited to partner with @dMatrix_AI and @nvidia to deliver up to 10x faster interactive token generation.
“Parasail is proving what we’ve believed from the start: the future of inference is heterogeneous,” said @sidsheth, founder and CEO of d-Matrix. By deploying Corsair alongside their NVIDIA fleet, Parasail is embracing a heterogeneous inference approach designed to optimize each phase of the workload across multiple accelerators.”
D-Matrix’s incredibly fast SRAM-based inference and NVIDIA’s willingness to collaborate and open up their system makes this all possible. Link in thread.
The models are improving at too rapid a pace to make it a worthy investment. You might as well give it as little context as possible and let the model figure out the right thing to do things.
I just spent a couple days configuring pi for subagents orchestration and everything and the thing that I realized is that the less context bloat you give good models, the better you do. I believe the future is going to be harness engineering but not yet. It’s too early.
@Yuchenj_UW@ClementDelangue The fact that it’s close and significantly cheaper is insane. In the medium term everyone’s going to have to figure out how to extract the most value out of their tokens.
The thing I’m scared about the open source labs blocking their models