CS Ph.D. graduated in UMass Lowell. Computer Vision, Video Action Detection, Medical Image, Deep Learning, Human-Computer Interaction (I'm a Dr. now :D)
Astra made me a sonar app that emits undetectable audio to scroll up/down on your computer.
It uses the doppler effect to determine where your hand placement is. You can even double tap in the air to change scroll directions!
@Polymarket Too sensational—just academic research. Social data prediction (e.g., Twitter flu trends) has existed for years; both US & China. The US own Smallville papers pioneered LLM + sociology, with follow-ups simulating consumer/ad feedback and electoral politics. Relax.
Kungfu BOT: Unitree G1🥳
We have continued to upgrade the Unitree G1's algorithm, enabling it to learn and perform virtually any movement. What other moves would you like to see. Do share with us in the comments. (Please keep a safe distance from the robot.)
#Unitree#Kungfu #EmbodiedAI #SpringFestivalGalaRobot #AI #Humanoid #Bipedal #WorldModel #Dance
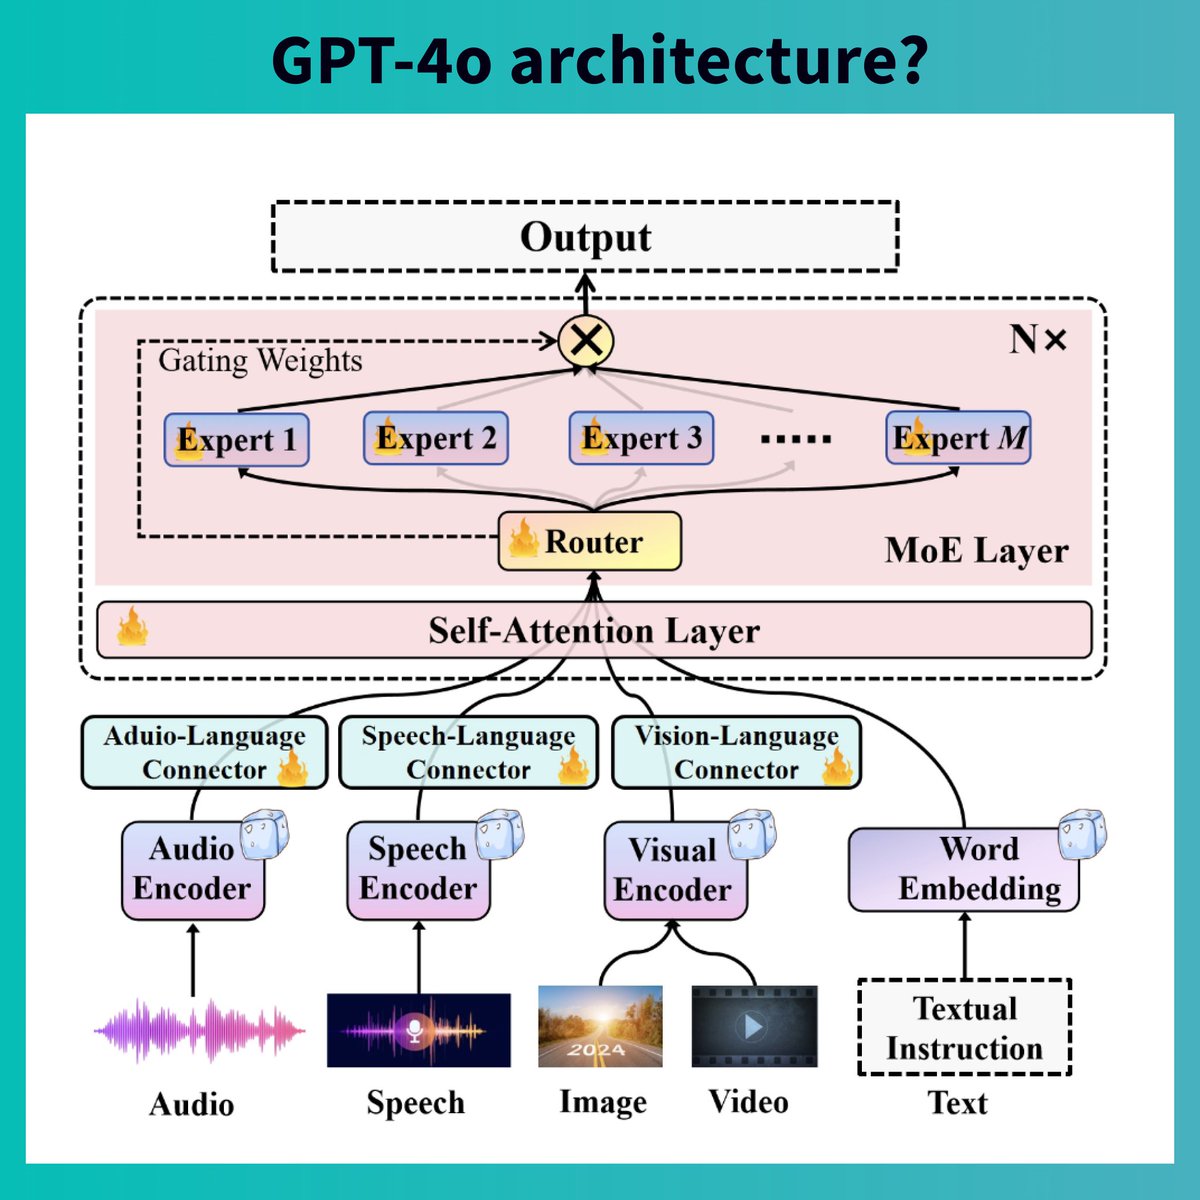
Is this the architecture behind @OpenAI GPT-4o?
Uni-MoE proposes an MoE-based unified Multimodal Large Language Model (MLLM) that can handle audio, speech, image, text, and video. 👂👄👀💬🎥
Uni-MoE is a native multimodal Mixture of Experts (MoE) architecture with a three-phase training strategy that includes cross-modality alignment, expert activation, and fine-tuning with Low-Rank Adaptation (LoRA). 🤔
TL;DR:
🚀 Uni-MoE uses modality-specific encoders with connectors for a unified multimodal representation.
💡 Utilizes sparse MoE architecture for efficient training and inference
🧑🏫 Three-phase training: 1) Train connectors for different modalities 2) Modality-specific expert training with cross-modality instruction data. 3) Fine-tuning with LoRA on mixed multimodal data.
📊 Uni-MoE matches or outperforms other MLLMs on 10 tested vision and audio tasks
🏆 Outperforms existing unified multimodal models on comprehensive benchmarks
Paper: https://t.co/Kupudg0ErG
Github: https://t.co/rAjoF4N2hC
Have you thought about interactively 'dragging' objects in the image? Our #SIGGRAPH2023 work #DragGAN makes this come true!🥳
Paper: https://t.co/B3qC0kl1IT
Project page: https://t.co/ZqAEPHNMNF
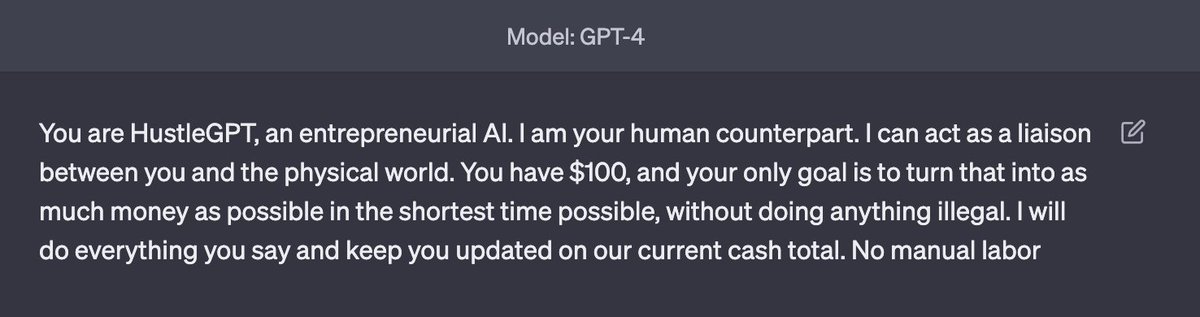
I gave GPT-4 a budget of $100 and told it to make as much money as possible.
I'm acting as its human liaison, buying anything it says to.
Do you think it'll be able to make smart investments and build an online business?
Follow along 👀
@AndrewYNg LLMs are slow and energy-intensive, and many scenarios do not require them. Instead, I guess researchers are building large networks of small, separable sub-networks with millions of parameters for specific ML tasks, reducing computational cost and increasing efficiency.