Oltre la pasta e la pizza, in Italia c'è .. GilBERTo!
@GiulioRavasio and I are very happy to release GilBERTo 🇮🇹 an Italian uncased language model based on RoBERTa trained on ~71GB Ita Common Crawl!
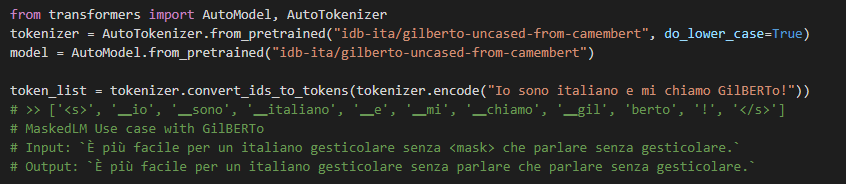
Try GilBERTo with #fairseq or find it directly into @huggingface 🤗library
Ciao!
How to train a model with 10^11 parameters without running out of GPU memory?
Use DeepSpeed from Microsoft Research!
It's PyTorch compatible.
It partitions the network onto multiple processors automatically and efficiently.
@seb_ruder There is also 🇮🇹 GilBERTo🇮🇹 as an italian pretrained language model based on RoBERTa and trained on a large common crawl corpus ~71Gb! You can find it here: https://t.co/fI02DZszaB or through the beautiful #huggingface
You can find more details about the model on:
- huggingface models https://t.co/dXfrD1Yvee
- github https://t.co/fI02DZszaB
If you find it useful, please star the repo and we strongly recommend to contribute to it
Oltre la pasta e la pizza, in Italia c'è .. GilBERTo!
@GiulioRavasio and I are very happy to release GilBERTo 🇮🇹 an Italian uncased language model based on RoBERTa trained on ~71GB Ita Common Crawl!
Try GilBERTo with #fairseq or find it directly into @huggingface 🤗library
Ciao!