We’re building @LibreChatAI with LibreChat.
Meet Lia, the agent helping us code and investigate issues as we build beyond dependence on Claude Code, Codex, and Cursor.
What’s shipped, what’s next, and our October 9 town hall:
https://t.co/r3lrsdbPuf
LibreChat v0.8.8-rc2 is out 🚀
Help us test ahead of v0.8.8!
Below is our Speed Chess demo showing Human-In-The-Loop interrupt, steer & queue; live Agent activity/reasoning; and beta Agent Events & teams.
https://t.co/S02UYnFoB6
@RemcoE33@ClickHouseDB Fair question. LibreChat already has generative UI through artifacts, so we’ve prioritized other work while the MCP Apps spec evolves. MCP Apps support is on our roadmap, and we’ll ship it before year-end.
@gabrieltrabanco@digimobil_es#LaLigaGate al bloquear IPs compartidas de Cloudflare, también están dejando inaccesibles servicios legítimos como https://t.co/G3dhMU9ZfE. Una sola IP puede servir a muchos dominios no relacionados. Bloquearla por completo causa daños colaterales. @digimobil_es, revisen esto
An MCP server is only as good as the API it wraps. One of many lessons from a year of running @LibreChatAI in production for the whole company: https://t.co/67M5h9JCvA
How to keep AI spend flat while token usage grows exponentially: Not with friction and spend alerts. With better defaults, routing, and caching.
Better Defaults (not Usage Caps) – Engineers can choose any model they want, but defaults matter. We’re experimenting with defaulting to open weight models like GLM 5.2 and Kimi 2.7 through our LLM gateway, while still encouraging engineers to choose the right model for the task. 91% of our employees were never hitting their usage caps, so instead of lowering caps and driving up alerts, we're moving to cheaper defaults. Note that code reviews use a diversity of models, so they can check each other's work.
Better Routing – In our custom harnesses, we preprocess prompts and route to the best model for the job, considering cache hits and model pricing. For instance, you may want a frontier model for planning, but not for execution where they can be overkill. Ultimately, humans shouldn't be choosing models - AI can automate this task.
Better Caching – Cache misses are the easiest way to drive your cost up. All of our requests are cache aware, so we’re reusing a warm cache wherever possible. For example, our cache hit rate went from 5% → 60% in LibreChat once properly implemented.
Keep Context Lean – Start fresh sessions when switching tasks. Scope file context narrowly. Disconnect unused tools. Don't just compact. The goal isn't fewer tokens used, it's fewer tokens wasted.
Better Visibility – Our engineers can use as many tokens as they want, from whatever model they want, but we’ve made usage visible – and the more you spend on AI, the more impact we expect.
The goal isn't to suppress usage. It's to build the infrastructure that makes exponential growth sustainable.
Putting this into practice has cut our AI spend nearly in half, while our token usage continues to grow.
This is why building your AI story on open and scalable foundations is key, and the reason @ClickHouseDB joined forces (acquired) @LibreChatAI and @langfuse. Open platforms on top of a fast data substrate take it to the next level. https://t.co/X6EHSLKMuw
See how @Visa built conversational business intelligence agents at scale with ClickHouse Cloud and @LibreChatAI:
✔️ Sub-second queries over millions of rows
✔️ 8-10 hours saved per user per week
✔️ Millions of dollars in revenue risk surfaced early enough to act on
https://t.co/INzx7CixnL
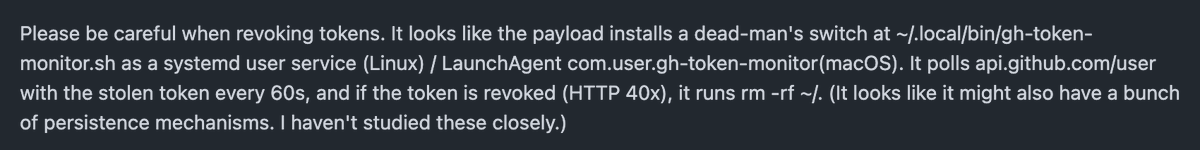
This is crazy. The hacker installed a dead-man's switch that will wipe your computer if you revoke the GitHub token they stole from you. Revoking the token is what triggers the wipe.
LibreChat v0.8.5-rc1 is out!
🏞️ Highlights:
- Admin Panel Foundation
- Context Compaction
- UI Redesign: new sidebar, refreshed prompts & tools
- Pinned Model Specs
- Performance & MCP improvements
Full changelog:
https://t.co/BUS52cTWXm
🔔 LibreChat v0.8.4 is out!
This release focused on security hardening with internal + independent pen testing, along with several bug fixes.
Strongly recommend updating.
v0.8.5-rc1 already underway with new sidebar UI and chat compaction.
📋 https://t.co/SBS0NDLz04
Software horror: litellm PyPI supply chain attack.
Simple `pip install litellm` was enough to exfiltrate SSH keys, AWS/GCP/Azure creds, Kubernetes configs, git credentials, env vars (all your API keys), shell history, crypto wallets, SSL private keys, CI/CD secrets, database passwords.
LiteLLM itself has 97 million downloads per month which is already terrible, but much worse, the contagion spreads to any project that depends on litellm. For example, if you did `pip install dspy` (which depended on litellm>=1.64.0), you'd also be pwnd. Same for any other large project that depended on litellm.
Afaict the poisoned version was up for only less than ~1 hour. The attack had a bug which led to its discovery - Callum McMahon was using an MCP plugin inside Cursor that pulled in litellm as a transitive dependency. When litellm 1.82.8 installed, their machine ran out of RAM and crashed. So if the attacker didn't vibe code this attack it could have been undetected for many days or weeks.
Supply chain attacks like this are basically the scariest thing imaginable in modern software. Every time you install any depedency you could be pulling in a poisoned package anywhere deep inside its entire depedency tree. This is especially risky with large projects that might have lots and lots of dependencies. The credentials that do get stolen in each attack can then be used to take over more accounts and compromise more packages.
Classical software engineering would have you believe that dependencies are good (we're building pyramids from bricks), but imo this has to be re-evaluated, and it's why I've been so growingly averse to them, preferring to use LLMs to "yoink" functionality when it's simple enough and possible.