Today we’re rolling out Gemini 4 Hydrogen! While teams rely on Gemini 4 Carbon and Gemini 4 Argon for deep architectural judgment and untangling subtle bugs, you also need a fast, disciplined model for writing code, running tests, and verifying changes.
Hydrogen stands on its own for everyday work, surpassing Argon on the Artificial Analysis Intelligence Index at its default thinking level (51 vs. 50, reaching 54 at xhigh)....or pairs with Carbon as the high-efficiency execution engine in multi-model workflows. It is at the pareto for speed vs quality and has been delivering fast frontier intelligence for our teams.
Claude Fable 5.2 from @AnthropicAI on ARC-AGI (Verified):
- ARC-AGI-3: 97.7%, $18.6K (provider adapter harness), 81.2%, $21.9K (standard harness)
- ARC-AGI-2: 93.8%, $0.98/task
- ARC-AGI-1: 98.5%, $0.36/task
Fable 5.2 sets a new high score on ARC-AGI-3 in the standard harness.
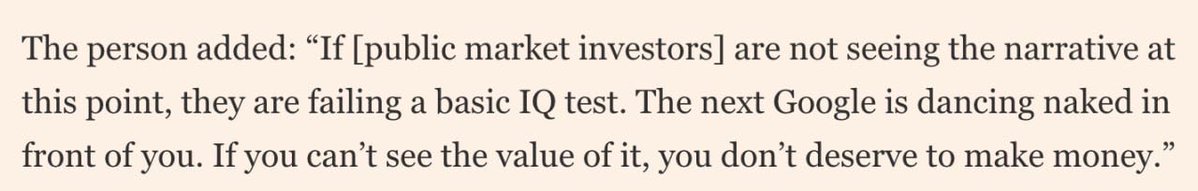
If this is true, then I don’t think they understand how deep Google’s moat on infrastructure.. “google” means the full stacks built upon these infra, from cable networks to the best search engine, not just coding models that you can’t see gaps among the frontiers.
After witnessing internal researchers use it to analyze and trace the bugs automatically from Jax all the way down to Assembly language and hardware, I have to admit this is the #1 coding agent for debugging..
Introducing Gemini 4 Carbon, it's a big jump over Argon which we released just 2 weeks ago.
Gemini 4 Carbon is SOTA on cyber, long horizon tasks, ranks #1 on Artificial Analysis V5, significantly improves on usability in domains like coding, and is more aligned.
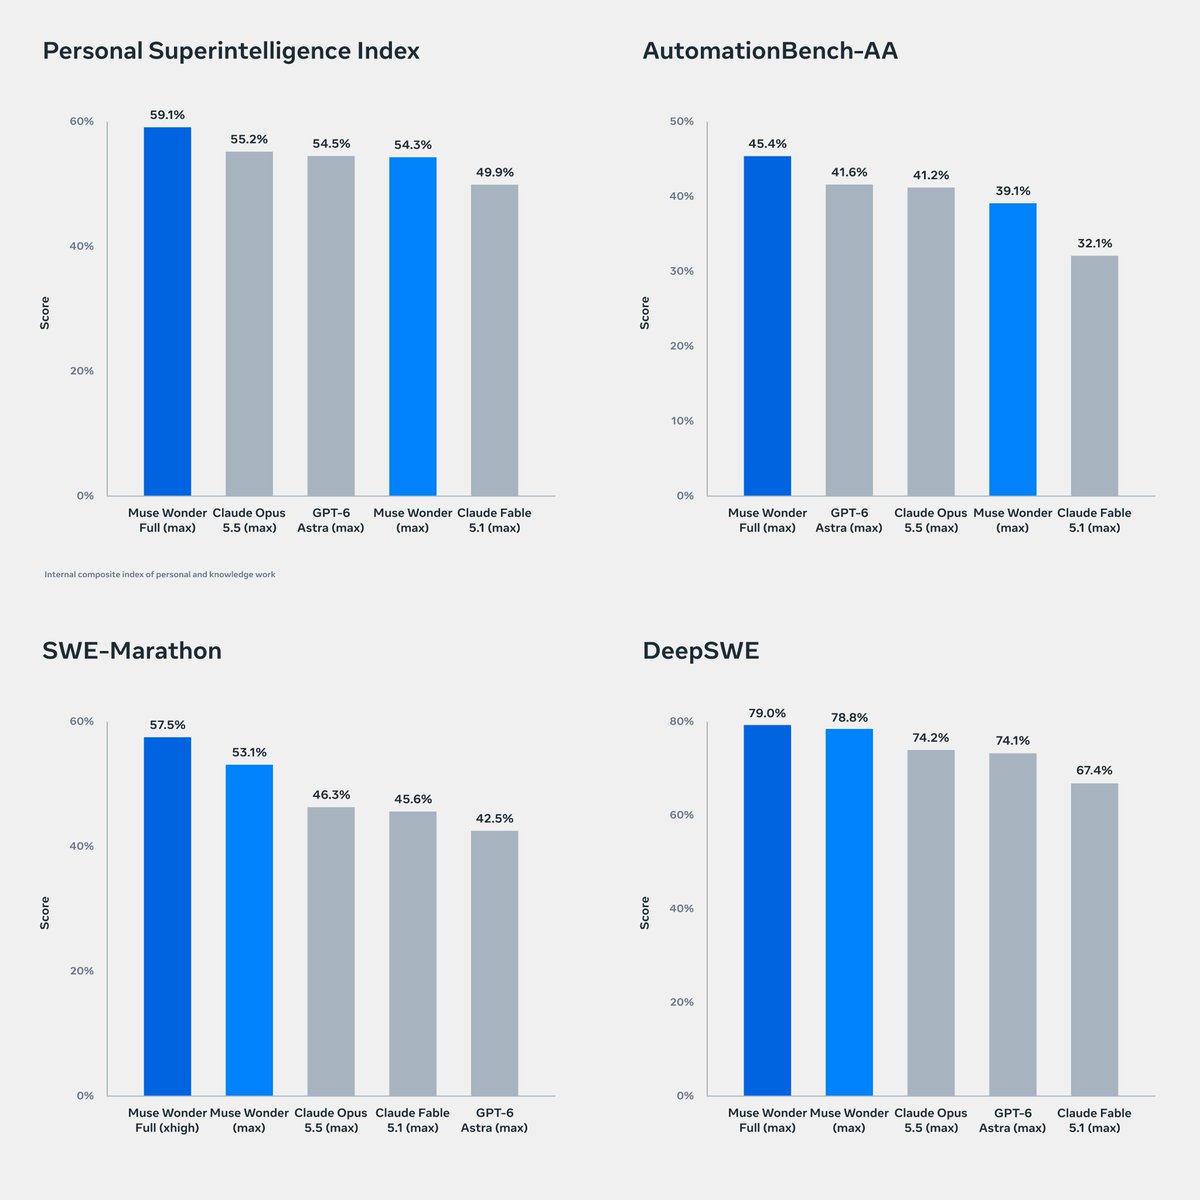
Today we are launching Muse Wonder and Muse Wonder Full, our best models yet, with state-of-the-art performance on personal and professional agentic tasks. They are built for long running, multi step work. Muse Wonder is available today in the Meta Model API and Muse Code, and Muse Wonder Full in Muse Code.
MUSE WONDER 🍉
muse wonder is the best model in the world for personal agents and professional agents.
we evaluated our model against the best models in the world across agentic and coding tasks, and we think you all will like it.
I will be at COLM on Wed afternoon. If you’d like to chat about @muse, the coding model/harness @meta, and continual learning. Please let me know. My DMs are open.