Currently at Google Research.
PhD in Reinforcement Learning from the Technion.
Main research interests include Reinforcement Learning and Large Language Models
We're excited to share our new paper: "Personalized and Sequential Text-to-Image Generation"!
Check out the paper and our new sequential human rater dataset! 👇
Paper: https://t.co/kyvBHZ5Uja
Dataset: https://t.co/UmZ2RZJ3Ro
Details below..
1/N 🧵
Check out our paper for more details on how we're pushing the boundaries of RLHF for more natural and effective multi-turn conversations!
https://t.co/RE9EDutUqr
@LiorShan@aviv_rosenberg@AsafCassel
(8/8)
Excited to share our latest research on aligning Large Language Models (LLMs) with human preferences! We're moving beyond single-turn interactions to improve multi-turn conversations.
https://t.co/RE9EDutUqr
Joint work by @GoogleResearch@GoogleDeepMind
(1/8)
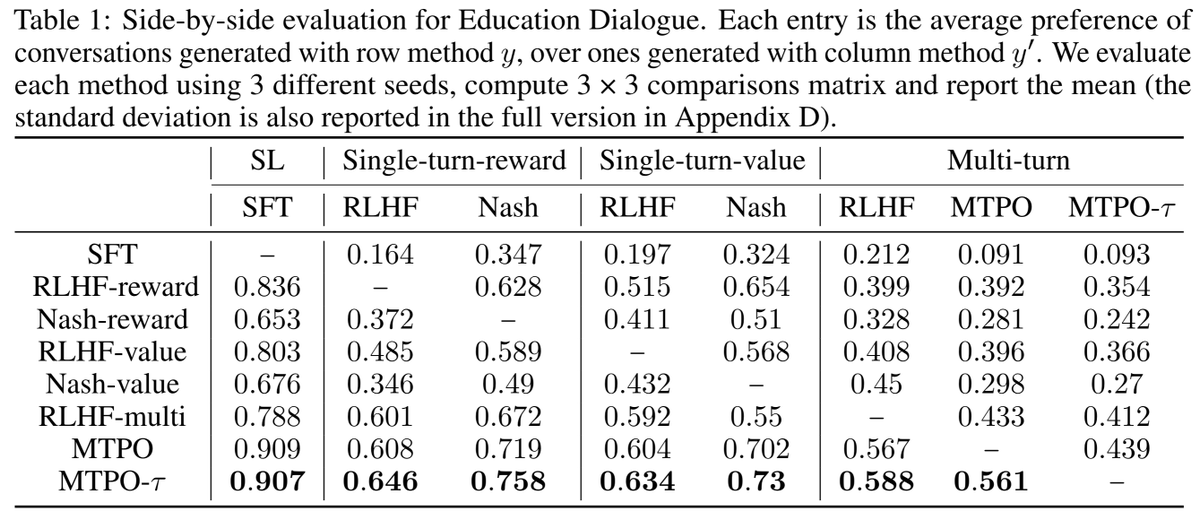
Experimental results showing MTPO outperforms single-turn RLHF baselines and a multi-turn generalization of RLHF. This demonstrates the effectiveness of our approach in improving the quality of multi-turn conversations.
(7/8)
Check out our paper here: https://t.co/gPqkAmuRys
Code can be found here:
https://t.co/p8WjcLc434
And of course, thank you to everyone who collaborated with me on this project: @NadavMerlis, @LiorShan, @shiemannor, @ShalitUri, @GalChechik, Assaf Hallak, and @DalalGal.
(9/n)
n=9
Finally, we discuss the need for exploration in imitation learning, and argue that our Apprenticeship Learning based approach which relies on the MDP structure, is superior to supervised learning approaches such as BC.
Glad to present our paper "Online Apprenticeship Learning" at #AAAI2022
https://t.co/24tTXxl1bJ
with @TZahavy@MannorShie
We show how to efficiently reproduce experts' behavior from an offline data of trajectories, by interacting with the MDP (when rewards are not specified).
We show our approach is both theoretically efficient and practical: we provide regret guarantees and show how to avoid solving an MDP at each iteration as in prior works. This allows us to devise a well-performing deep RL implementation of our (OAL) algorithm.
teleporting, swimming with sharks, and lots more. It turned out better than I've ever expected!
Now, before releasing it out to the world, I'm looking for a partner that can help me market the game properly. You can help me out by retweeting!
Promo:
Ludwig @Princeton Director Joshua Rabinowitz, a pioneer of metabolomics, has contributed to the development of a cancer therapy & undone enduring assumptions about metabolism. His work is opening new approaches to cancer therapy. Learn more: https://t.co/yCUXGwtqpy
Overall, MDPO is an easily scalable policy optimization algorithm with minimal hyper-params/heuristics involved, and is nicely grounded in mirror descent theory :)
Joint work with @LiorShan, Yonathan Efroni, Mohammad Ghavamzadeh
Come chat on Dec 11, 11:30 am PST!
Overall, MDPO is an easily scalable policy optimization algorithm with minimal hyper-params/heuristics involved, and is nicely grounded in mirror descent theory :)
Joint work with @LiorShan, Yonathan Efroni, Mohammad Ghavamzadeh
Come chat on Dec 11, 11:30 am PST!
Prof. Shie Mannor is presenting our work at the great RL theory seminar this Tuesday! The talk will be about the connections between TRPO and convex optimization, possible practical implications and how to explore in policy optimization...
Our next talk:
06/09: Shie Mannor (Technion)
"Adaptive Trust Region Policy Optimization: Global Convergence and Faster Rates for Regularized MDPs"
For details, please see the website:
https://t.co/zra0wITmwb
Prof. Shie Mannor is presenting our work at the great RL theory seminar this Tuesday! The talk will be about the connections between TRPO and convex optimization, possible practical implications and how to explore in policy optimization...