@thekitze@eiselems@viticci With the right inference engine like ninfer on my 5090, Qwen 3.8 27B I get 120-190 tokens/second with MTP on code. Average around 150. But, running larger models with offload will be slower than M5 Ultra unfortunately, so I've preordered M5 for that sweet sweet memory.
@TheZachMueller What SlimSAS connectors are you using? Are they bifurcated as well? Need to get stable PCIe extenders and the normal flat ribbon cables are not cutting it.
@airesearch12@typesafeai Thank you! Using your leaderboard to run against our internal data/benchmarks. I unfortunately can't share as the data is proprietary and not mine to provide. So far your top-ranked model is also the top with our data. Quite interested in your presentation generator too, details?
@antirez By the same token, do you recommend 2x 256 GB M5 Ultra instead of 1x 512 GB Ultra? Do you get double the memory bandwidth for inference? Does streaming from SSD still work in a 2x configuration? Love ds4, it's an amazing achievement!
@superalesha Thank you for the pointer! This inference engine is insanely good for running a very good Qwen 3.8 27B quant on a single 3090 with crazy context and speed. If I didn't try it myself, there's no way I would believe this was possible. Insane what a ~6 year old GPU is capable of now
https://t.co/gHoAUUfHAR - boot once, run everywhere.
A MicroVM that runs on hardware you already own.
Close your laptop and it hands off to another host.
Works across macOS, Linux, and Raspberry Pi. (aarch64)
@alexocheema@HanchungLee Using A6000 as a comparison doesn't make sense. 2x RTX Pro 6000 makes more sense for comparison. 192 GB VRAM and 3600 GB/s by your math. I love both options, but let's do a realistic comparison.
@luthiraabeykoon@karpathy .\run_inference.sh (dot, backslash, script name) will not run your script in a standard Unix shell. Backslash is a Windows path separator, not Unix path separator; it's a Unix quoting operator. If it's Unix, you want ./run_inference.sh (dot, forward slash)
@0xSero Good choice. Turboderp has been a one-man wrecking ball from the early LLaMA days. He was doing this all pre-coding assistants and making more performant and better quants vs. whole teams of people.
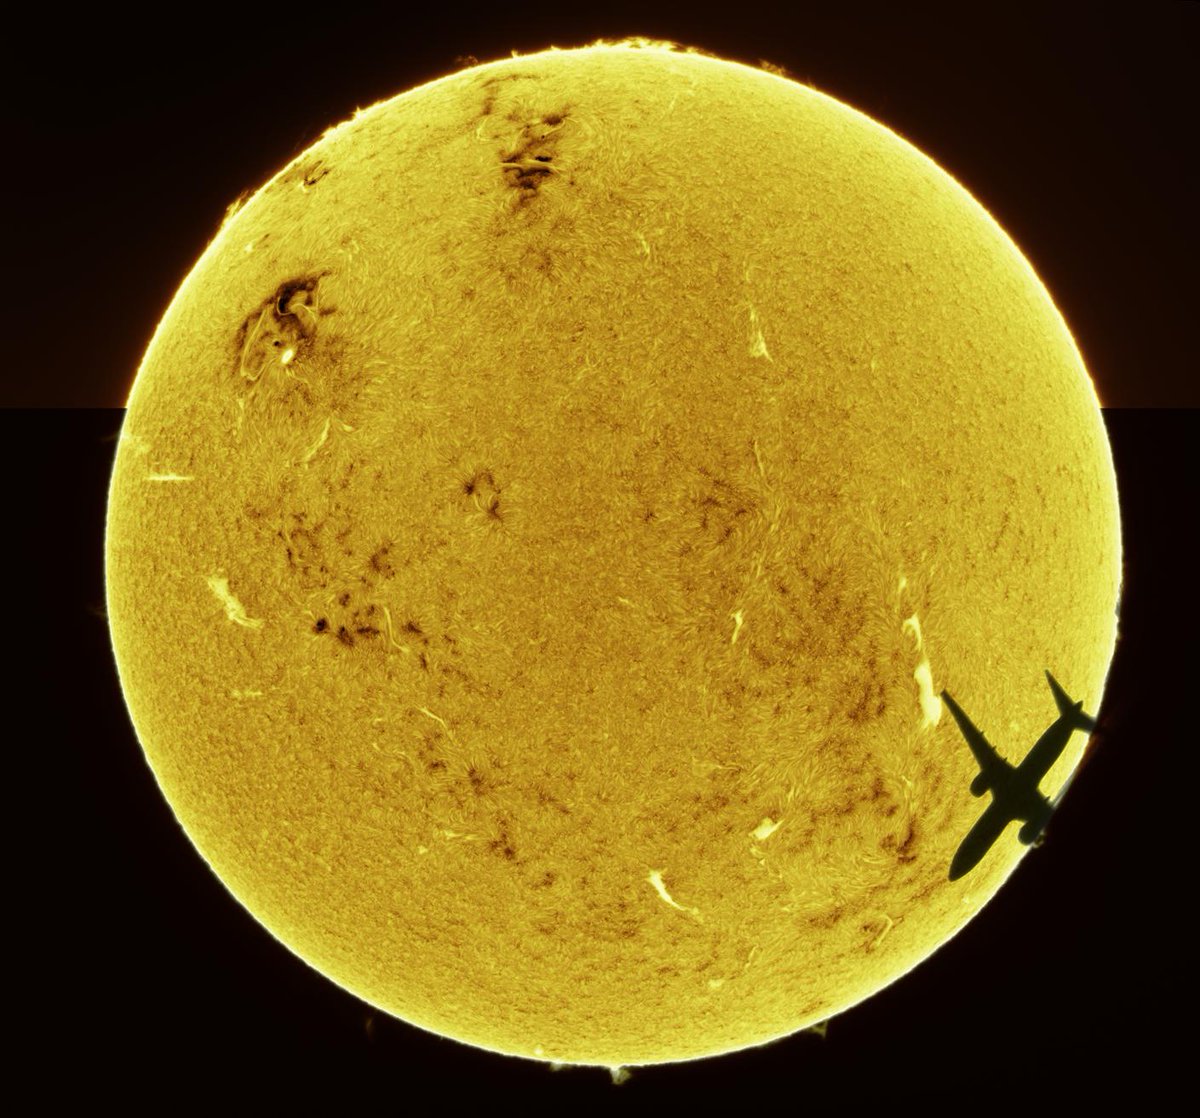
Randomly caught a solar transit of a plane while using my HA telescope. Sometimes it pays to just be randomly lucky @MikeSeeley@AJamesMcCarthy. Mosaic image was processed to invert the Hydrogen Alpha image and merged with top half taken separately (scope covers ~1/2 of the sun)
@QuixiAI@ClementPillette I'm with @QuixiAI here. There's no way an M3 Ultra can compete with RTX Pro 6000s if everything fits in available VRAM and is configured correctly. I roughly benchmarked the M3 Ultra at around 3090 speeds for LLM inference on single requests; not even considering batching gains.
@mikeseeley@AmericanAir@flightradar24@Boeing@BoeingAirplanes It's the perfect excuse to get a strain-wave harmonic tracking mount for starters. You can use that to track the sun and mount your DSLR + telephoto lens. Then you'll be all set once you buy the HA scope :) The tracking mount is useful for astro but also eclipses...
We're releasing ACE-Step-v1.5(2B), a fast, high-quality open-source music model.
It runs locally on a consumer-grade GPU, generates a full song in under 2 seconds(on an A100), supports LoRA fine-tuning, and beats SUNO on common eval metrics.
GitHub: https://t.co/Zydfhw9oUl
Key traits:
Quality: beats Suno on common eval scores
Speed: full song under 2s on A100
Local: ~4GB VRAM, under 10s on RTX 3090
LoRA: train your own style with a few songs
License: MIT, free for commercial use
Data: fully authorized plus synthetic
The music AI space lacks commercial-grade open models. Many creators are forced to rely on closed-source services, and can’t fully own, run locally, or fine-tune their own models. We want to help change that.