Barrels and ammunition → barrels and tokens
The classic @rabois startup wisdom is that at software companies you need two kinds of people:
▪️ barrels: rare, high-leverage individuals in a company who can take an idea from start to finish
▪️ ammunition: talented specialists (engineers, designers) who execute excellently but need direction and ownership to be effective
In the AI age all the leverage belongs to the barrels. The tools are getting so good they can now effectively take any idea to reality for the right barrel. The ammunition is LLM tokens and parallel agents.
I think this is best summary of how the software engineering market changes from now on (ht @cramforce).
1) DeepSeek r1 is real with important nuances. Most important is the fact that r1 is so much cheaper and more efficient to inference than o1, not from the $6m training figure. r1 costs 93% less to *use* than o1 per each API, can be run locally on a high end work station and does not seem to have hit any rate limits which is wild. Simple math is that every 1b active parameters requires 1 gb of RAM in FP8, so r1 requires 37 gb of RAM. Batching massively lowers costs and more compute increases tokens/second so still advantages to inference in the cloud. Would also note that there are true geopolitical dynamics at play here and I don’t think it is a coincidence that this came out right after “Stargate.” RIP, $500 billion - we hardly even knew you.
Real: 1) It is/was the #1 download in the relevant App Store category. Obviously ahead of ChatGPT; something neither Gemini nor Claude was able to accomplish. 2) It is comparable to o1 from a quality perspective although lags o3. 3) There were real algorithmic breakthroughs that led to it being dramatically more efficient both to train and inference. Training in FP8, MLA and multi-token prediction are significant. 4) It is easy to verify that the r1 training run only cost $6m. While this is literally true, it is also *deeply* misleading. 5) Even their hardware architecture is novel and I will note that they use PCI-Express for scale up.
Nuance: 1) The $6m does not include “costs associated with prior research and ablation experiments on architectures, algorithms and data” per the technical paper. “Other than that Mrs. Lincoln, how was the play?” This means that it is possible to train an r1 quality model with a $6m run *if* a lab has already spent hundreds of millions of dollars on prior research and has access to much larger clusters. Deepseek obviously has way more than 2048 H800s; one of their earlier papers referenced a cluster of 10k A100s. An equivalently smart team can’t just spin up a 2000 GPU cluster and train r1 from scratch with $6m. Roughly 20% of Nvidia’s revenue goes through Singapore. 20% of Nvidia’s GPUs are probably not in Singapore despite their best efforts. 2) There was a lot of distillation - i.e. it is unlikely they could have trained this without unhindered access to GPT-4o and o1. As @altcap pointed out to me yesterday, kinda funny to restrict access to leading edge GPUs and not do anything about China’s ability to distill leading edge American models - obviously defeats the purpose of the export restrictions. Why buy the cow when you can get the milk for free?
An army of billions of digital geniuses will descend on the workforce starting 2025.
They will work around the clock and never call in sick.
OpenAI just announced a model that outperforms their own head of research at competitive coding.
And it outperforms human level on the leading AGI benchmark.
We are entering a new world.
imagine if there was a platform that gave you access to stateful serverless compute + a browser + ai inference + real-time webrtc capabilities... that would be kinda perfect for building agents
oh wait. that's @cloudflaredev 🧡
good read 👇
Black Friday and Cyber Monday are wrapped and the numbers are in. Powered by Square, Afterpay, and Cash App, we’re breaking down how businesses and shoppers moved through one of the busiest shopping weekends of the year. From transaction growth to peak shopping hours, here’s how the holiday rush unfolded: https://t.co/wNhanHgspl
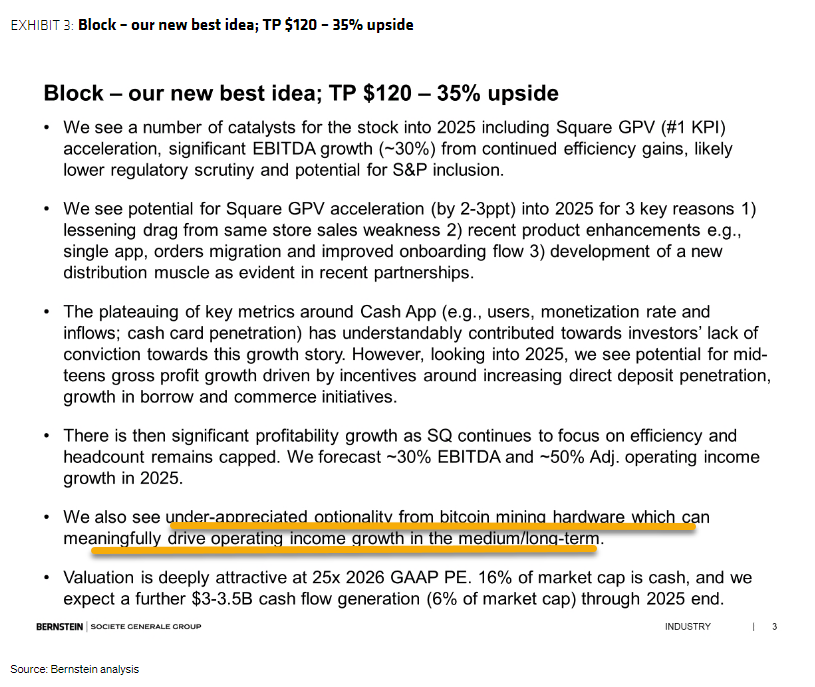
Bernstein: "Block (SQ) is our new best idea...We see under-appreciated long-term optionality from Bitcoin mining where SQ appears to be unique (in the US and in a new regulatory environment) in its access to 3nm chip."
Stock trades at 25x 2026 PE w/ 16% of market cap in cash.
A paradigm shift in edge computing is coming. Prediction: This will become best -in-class architecture for anything “Agentic AI”. Very few understand how well positioned $NET is for the coming explosion in AI inference.
Probably the biggest news in infra land. Phenomenal piece on how we use it, and what it takes to do it at this scale. It’s coming, and we’re hiring to make this real for everyone.
https://t.co/CP8nejRClt
🥔 AI just broke economics, says @Benioff. Q3 2024 saw productivity growth without labor expansion— "this has never been done before in the history of business". We're scaling GDP without hiring. Welcome to the post-labor economy.
Open source is core to how we build at Block. That’s why we’re teaming up with @AnthropicAI on the Model Context Protocol – an open standard helping AI systems securely connect to the data they need and bridge the gap to real-world applications. Learn more about Block’s collaboration with Anthropic here: https://t.co/jhtOdTXHPG