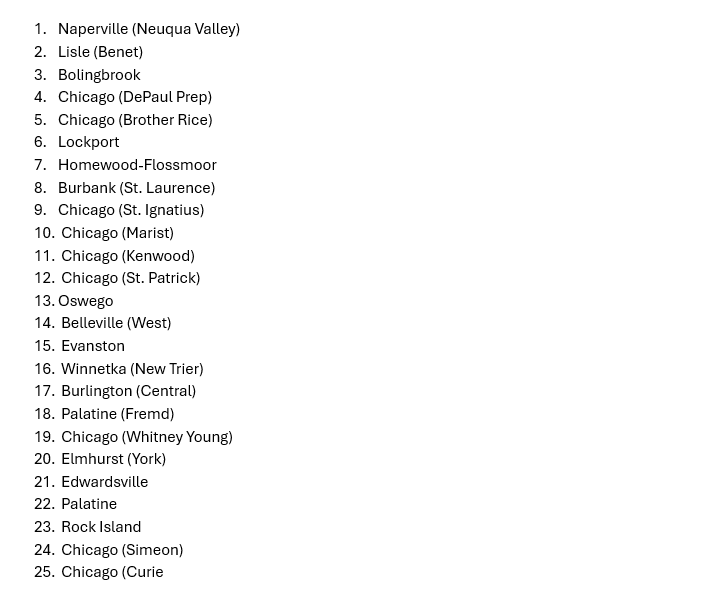
Congrats to AJ Chambers on his first collegiate game as he helps get the win for @mtumbb. In 23 minutes of play, AJ had 6/3/4stls. FAMO. @DePaulPrepAD@DePaulPrep
@DePaulPrepFB drops the Prep Bowl game to Leo. We are incredibly proud of the coaches and players who stuck it out and battled all season long despite facing a ton of adversity. You make us Ram Proud!
We compared Liquid Inference with 8 routers and gateways.
Each page has a head-to-head table, a fee calculator and dated sources. What the exchange does differently: providers compete for each request, and every request can have a hard cap.
https://t.co/j1pqv28qGe
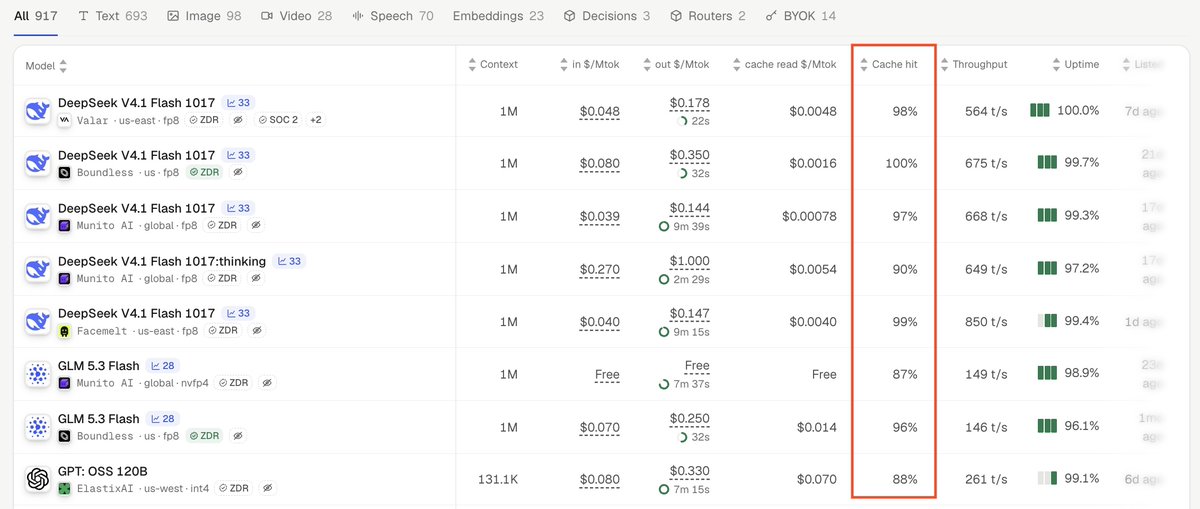
We've steadily improved our Liquid Inference routing algorithm to optimize for cache hit-rate. We've achieved >90% average across models, often realizing higher rates with DeepSeek and GLM providers.
The enterprise playbook won't do much to control costs. Only the expensive products will respond to RFPs. It's not flexible enough for the current market. Liquid Inference is the jack-of-all trades for AI procurement.
The top providers are constantly juggling their unused compute. They'll be serving one month and then fully booked with dedicated contracts the next. It's like herding cats.
What they should do is run tests with a tight budget to see where you can substitute to cheaper models. Then hit up our entire provider network for a quote based on your specs. We'll herd the cats and fill in all the blanks.
Liquid Inference checks every tool call a provider returns.
Bad call on a non-streamed request? We drop it and send the job to the next offer. Provider returns nothing? You pay nothing.
Last 7 days: 99.64% of tool-call answers had no bad call.
https://t.co/p8qOoTyvbQ
Reserve capacity on Liquid Inference.
Pick a model (text, video, image or speech) and set your terms: a monthly pool, rate limits, uptime, region and a term of up to 12 months. You get a quote, and you can negotiate before you accept.
Fixed monthly fee. Zero data retention on every reservation.
https://t.co/kY50QLBRXI
Could not be any more deserving. We’ve known this was coming since 7th grade. Smart, tough, and competitive. If you’re a college football coach and this young man isn’t on your board, you’re making a mistake. Congratulations, Captain!
Mean reversion in the GPU rental market. Over the past month, 1-year US GPU rental rates for A100, H100, and H200 have reverted back to mid-October levels, while B300 has given back most of its late-October gains. What we think is driving the divergence:
- Neocloud credit pressure. With neocloud equities down sharply and borrowing costs rising, some operators are moving B300 capacity at a discount to raise cash.
- Inference is driving demand. Neocloud demand continues to shift from training to inference (Bloomberg, below). Better small-to-mid-size open-weight models make older Nvidia accelerators more economical for many common inference workloads.
- B300 supply is catching up. B300s are the most commonly requested chip in the OTC market, and availability has historically been scarce. But we now see a number of B300/GB300 clusters coming online between end of Q4 2026 and mid Q1 2027.
We're brokering spot and options trades across the accelerator spectrum — reach out if interested.
Today, my team and I had a great visit to the @MIAXexchange trading floor in Miami. Appreciate the opportunity to meet some of the people helping power our markets. Thank you to the MIAX team for the warm welcome!
In Chicago for SC26?
Join us at Fioretta on Tuesday, Nov 17 with CMT Digital and Luxor. Bring your questions on trading compute and inference.
RSVP below.
DGML turns private-market documents into labeled data elements. Inveniam IO carries those elements through private-market workflows. Evidence for one element can be anchored on NVNM Chain. The files stay with their owner.
With boys season tipping off tomorrow, it’s time to count down to the 2026 version of The Jack Tosh
Dates - December 26, 28, 29, 30, 31
Championship Thursday Game Times
12:00 - 1:30 - 3:00
Admission (ALL 16 games each day)
$7 adults
$5 students & seniors
Bring your own key.
Connect your own Anthropic, OpenAI, Bedrock, Vertex AI or Azure account (16 clouds) and send requests through the same Liquid Inference API. Your cloud bills you at your own rates.
If your account can't serve a request, the market takes it before the first token. You can also set it to fail instead.
https://t.co/oUIihGskPe