We've built a coding agent that runs entirely on your own machine.
No account. No API key. Your code never leaves the laptop.
https://t.co/vP6mrv7fbe
Our ternary 35B-A3B model resolves 55.8% of SWE-bench Verified in 9GB — on a 16GB Mac or a gaming PC with 4GB of VRAM.
macOS + Linux
Ollama v0.40.0 (pre-release, Sep 25) now runs MLX-supported models on Apple Silicon by default. The March switch to MLX just became the default path. Mac users: your tokens/sec probably changed.
🔗 https://t.co/GjZRRmdH9x
A full-size AI model running entirely on an iPhone. No internet, no cloud, no data leaving your phone.
It beat Bonsai 1-bit on every test we ran, and answers noticeably faster while using less memory.
Free on the App Store if you want to try it. Try Millie by LLMs for All on AppStore
We put a 35B ternary LLM on an iPhone—in ~4 GB RAM.
Millie beats Bonsai 27B 1-bit across every benchmark we tested, with ~60% faster generation and lower memory use.
Works offline. Open weights + runtime
Try it on the App Store: https://t.co/s7X5foCdXX
24GB VRAM should comfortably fit the 11GB model, so I suspect a GPU driver or Vulkan issue. Could you close all Millie sessions and try the same prompt in CPU mode?
millie –model millie-35B-A3B-11GB –serving-profile cpu-full -c ‘llamacpp.gpu=[]’
It’ll be slower, but knowing whether it still freezes would help narrow this down
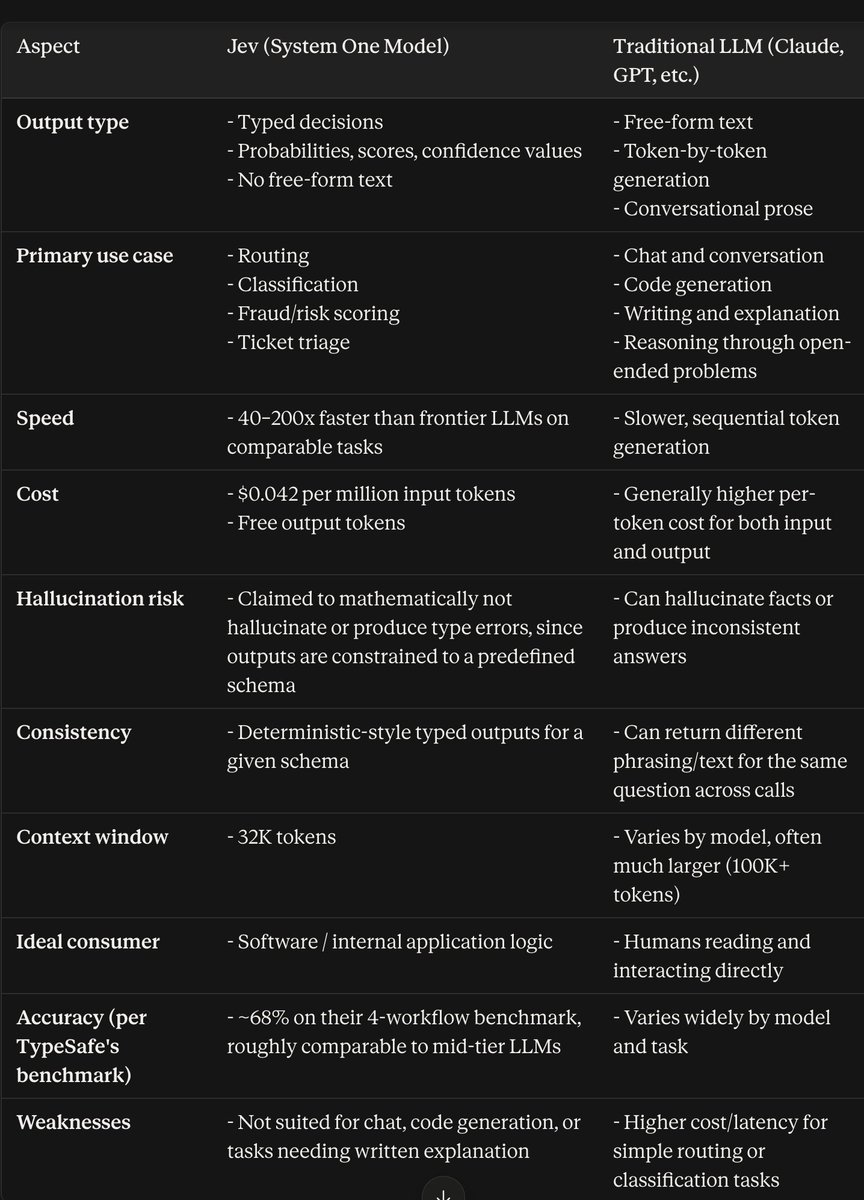
Digging into Jev today, TypeSafe's new "System One" model that skips text generation entirely. You give it app state + a question, it hands back typed decisions & probabilities, not prose. It literally can't hallucinate, because it only ever picks from labels you define upfront, no free text, no room to invent stuff. Also apparently 40-200x faster than frontier LLMs. Here's a table comparing Jev with traditional LLMs: