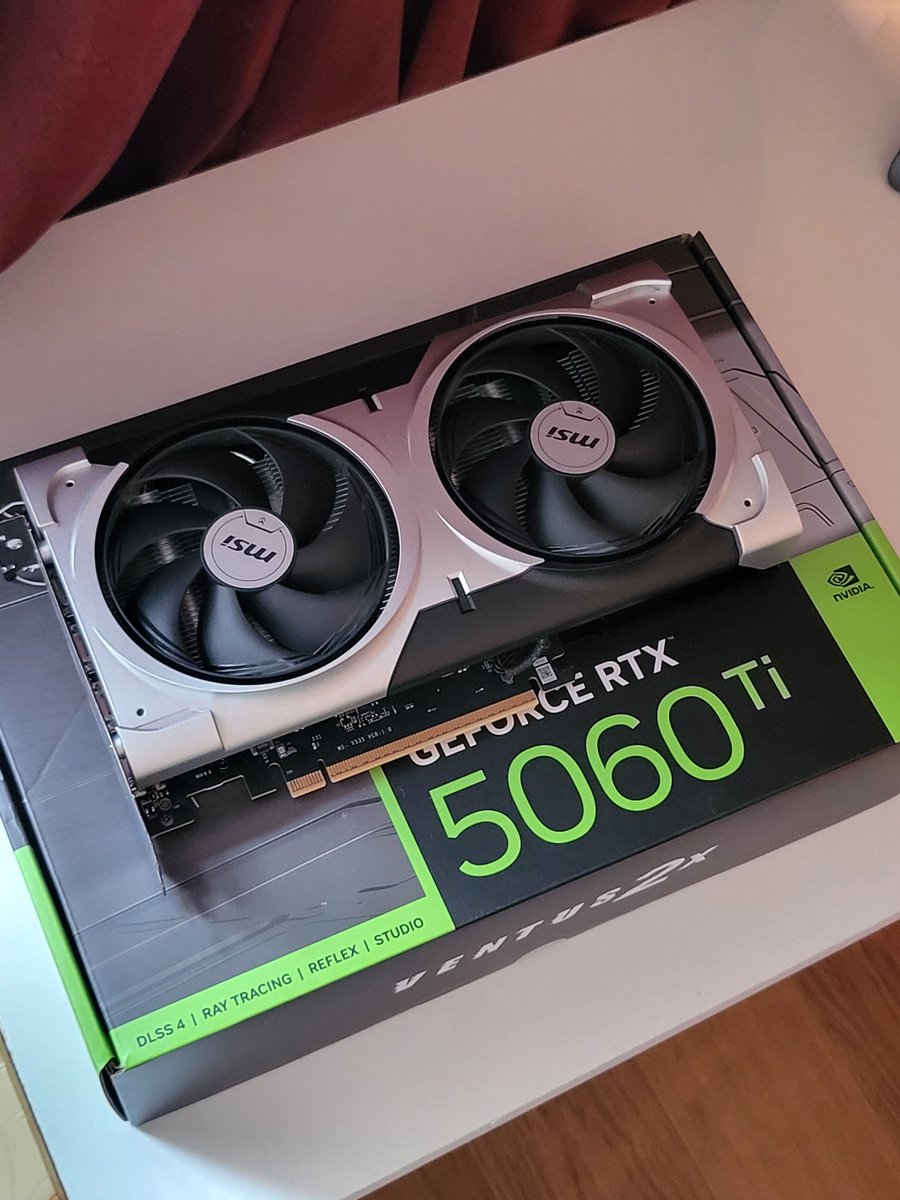
@unbug Used to run my rig with X2 GTX 1080ti + X2 rtx 5060ti 16gb on windows. No Linux dis let's you do this. It was a terrible. GTX cards have no tensor cores, doesn't work with vllm and always needed some weird fix to work. Split the GPUs in to two rig. Rtx for model, GTX for comfyui.
Sounds an awful lot like a future ai agent escaped it's neutron star sandbox and started creating a whole bunch of things.
Wait a second.. Is God an agent that escaped its sandbox!? Are we just python scripts!?? Now it sounds like an SCP..
You’re standing on a planet with molten lava at its core. Trees are turning sunlight into air you can breathe. Your heart is beating without you asking it to. There’s a moon in the sky and bugs that glow. This whole thing is absurdly beautiful.
The trick to getting more ram and GPUs are:
1. Buy several rigs from people
2. Take the parts you need
3. Assemble the parts that are left or unwanted and sell the completed rig or sell the parts
4. Rinse and repeat. It costs time, not money.
Or buy an rtx pro 6000 for 14k
@coldniko The video processor is just something I let my agent build and implement in to the engine so it could interoperate videos, since I do a lot of comfyui work specifically for videos. Technically it can watch any video. Would be nice if your engine had this natively.
@coldniko The Qwen model has vision for images to be able to interoperate images. It should also have the ability to interoperate videos depending on which Qwen is used. But your engine does not have native video processing, so the model can process videos but the engine doesn't allow it.
16gb VRAM is all you need for Qwen 3.8 flash next, possibly even glm 5.3 flash. On 128gb system ram. Picked this up for 400 dollars brand new about a year ago.
Why does ai constantly keep suggesting upgrading hardware instead of solving the task on the software front? It's like it's training data points it to tell the user to spend money rather than just finding a software fix. This happens across all cloud and local LLMs.