We just hit 300 members today—woke up to 100+ new people joining overnight. Come join these top DIY hackers using extreme optimization to make old hardware run Qwen3.8-Flash and GLM5.3-Flash. 🚀https://t.co/5W0ilKD1QY
Just a bit of insight: people are eager to build their own rigs for local LLMs, the same way we were obsessed with building gaming PCs 30 years ago. https://t.co/5W0ilKD1QY
Run a 763B-parameter model locally. DeepSeek-V4.1-Flash-1017 on a 12GB GPU.
Frontier quality with GSQ-RCO quants, directly supported in the Strata inference engine.
Further info below. Much more to come. Follow for updates.
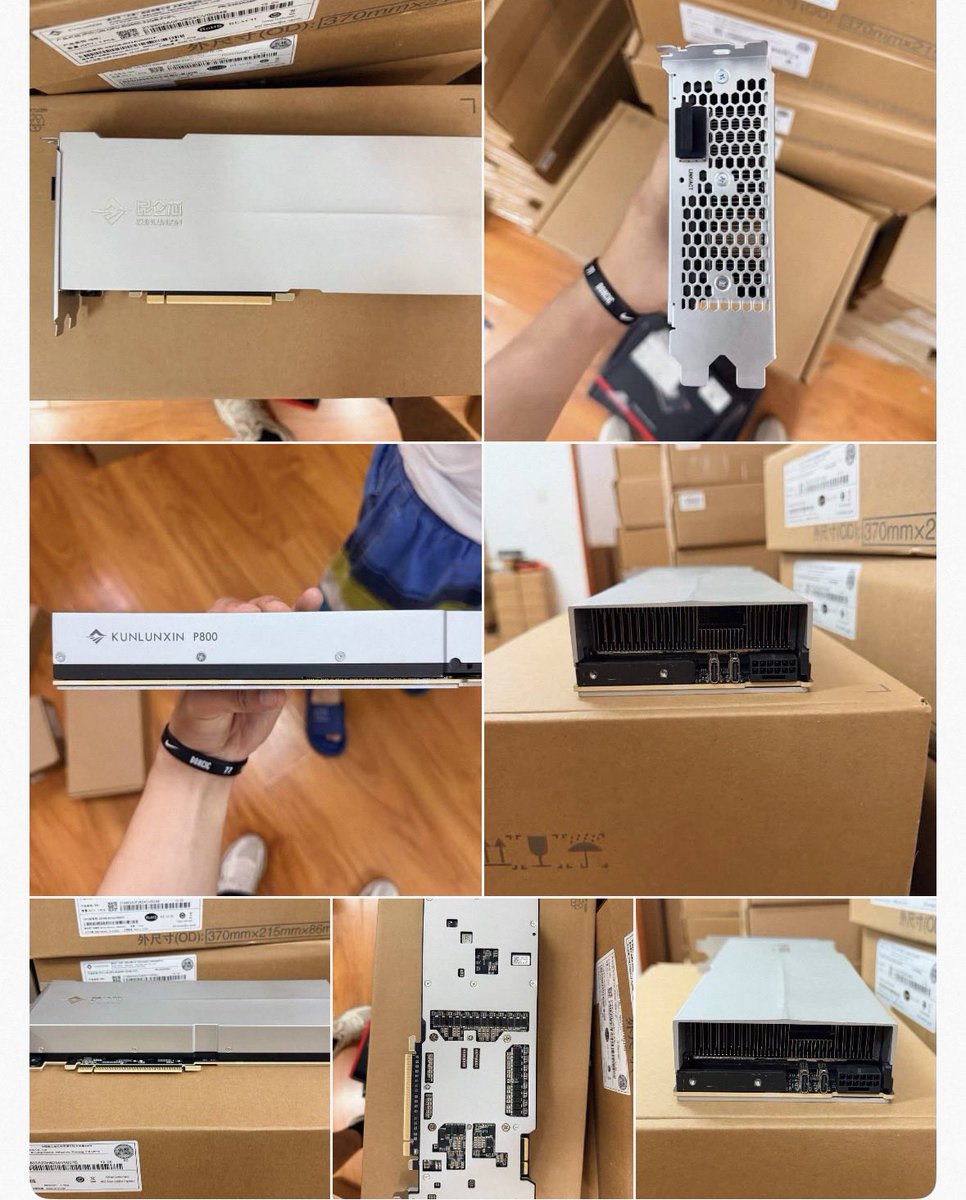
China actually has plenty of homegrown inference GPUs, but prices haven’t dropped as expected—and they’re still not great for local LLMs. Literally one big reason: no CUDA. Without the ecosystem—PyTorch, kernels, quants, llama.cpp/Strata support—local LLM tinkering gets way harder.
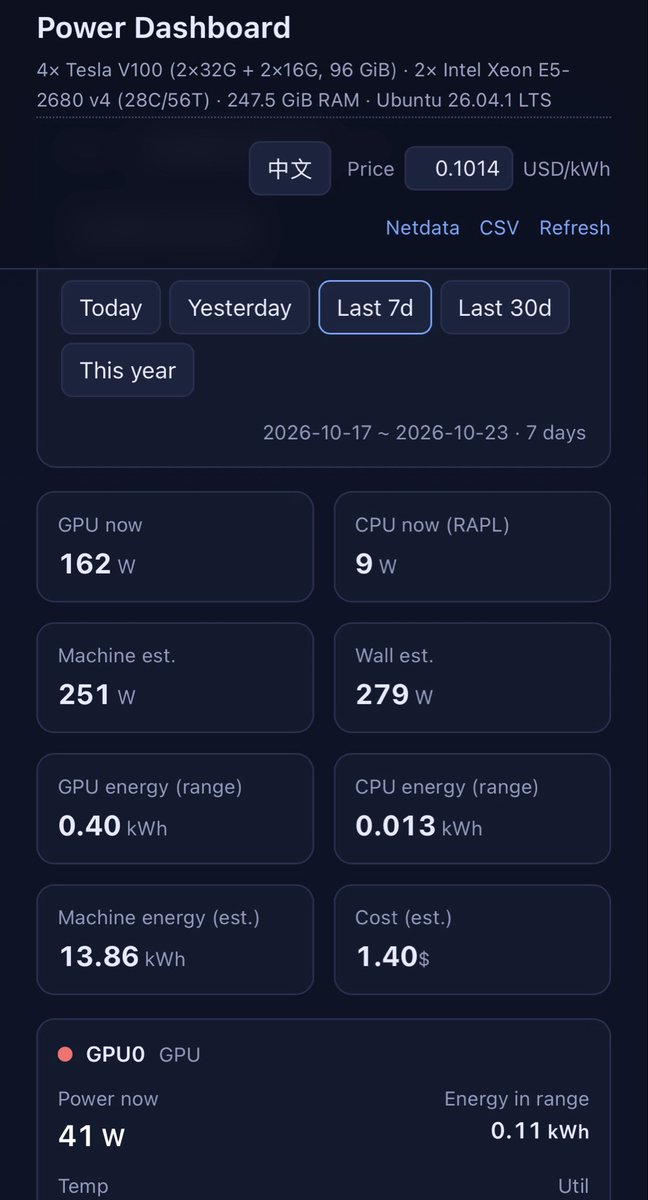
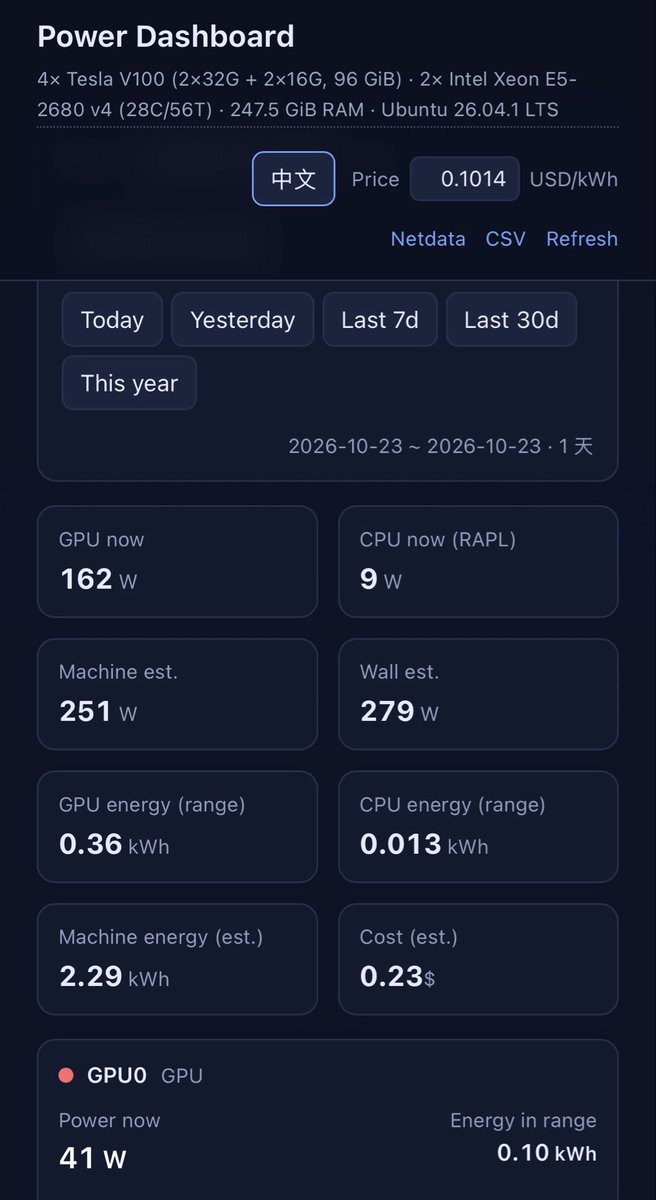
You guys keep asking about the power cost of my 4×V100. I asked Strata + Qwen3.8-Flash to build me a dashboard—here’s the daily, weekly, and monthly bill. Don’t be surprised 😎
Quick tip for the new Strata build: don’t forget --conversation-cache-mib 0 to disable conversation caching. You’ll lose a little prefill speed—just a heads-up.
We just hit 300 members today—woke up to 100+ new people joining overnight. Come join these top DIY hackers using extreme optimization to make old hardware run Qwen3.8-Flash and GLM5.3-Flash. 🚀https://t.co/5W0ilKD1QY
Like I said, new models come and new models come go—we all end up running only Qwen locally. DeepSeek V4.1 Flash is ridiculously slow on my V100 rig (256GB RAM + 96GB VRAM).