▲ Marktechpost just launched GPU Leaderboard ( in beta mode), a free cloud GPU price comparison for inference, along with a Chrome extension.
The key idea is pricing a whole run, not a single hourly rate. Pick a GPU, count, duration and utilization, and it prices that exact run at every provider.
The spread is large: an 8×H100, 72-hour run costs $967.68 at the cheapest provider and $3,545.28 at the priciest, 73% less.
The chrome extension shows a model's VRAM needs at FP16, INT8 and INT4 on Hugging Face pages, and the cheapest GPU that fits. Free, multiple providers, 201 live instances, 37 accelerators......
Full analysis: https://t.co/ejhnBos8IH
Portal: https://t.co/zTd1hwDVB2
Chrome Extension: https://t.co/5IP4PSgpZF
@Marktechpost@CoreWeave@nebiusai@latitudesh@LambdaAPI@runpod and many more...
▲ Google just released the Gemini Decisions API, powered by Gemini Decision 1, a model that answers typed questions instead of writing text.
The key idea is scoring, not generating. You send 1 shared input (text, images, audio, video or PDFs, up to 256K tokens) plus up to 1,000 yes/no, choice or rubric questions. The model scores every option in 1 forward pass and returns calibrated probabilities with a confidence value. Output tokens are always 0.
On Google's benchmark table, it leads 7 of 9 accuracy tests, including 92.2% on JevBench vs 90.9% for GPT-6 Luna on OpenAI's Decisions API. Its calibration error is 0.0250, about half of TypeSafe Jev 1.14 (0.0494). It is a trade-off though: Jev 1.14 wins When2Call (82.0% vs 79.9%) and costs less on the shared suite ($0.68 vs $0.88).
Pricing is $0.10 per 1M input tokens, $0 output, with a free tier in AI Studio. Google reports 150-250 ms end-to-end latency. No context caching or Batch API yet......
Full analysis: https://t.co/hCLi21dHNH
Blog: https://t.co/EOKwbJ4u8R
Docs: https://t.co/gxdvXZG9lC
Model: https://t.co/wqiUiqagnH
@GoogleAIStudio@OfficialLoganK@Google
▲ Google just released the Gemini Decisions API, powered by Gemini Decision 1, a model that answers typed questions instead of writing text.
The key idea is scoring, not generating. You send 1 shared input (text, images, audio, video or PDFs, up to 256K tokens) plus up to 1,000 yes/no, choice or rubric questions. The model scores every option in 1 forward pass and returns calibrated probabilities with a confidence value. Output tokens are always 0.
On Google's benchmark table, it leads 7 of 9 accuracy tests, including 92.2% on JevBench vs 90.9% for GPT-6 Luna on OpenAI's Decisions API. Its calibration error is 0.0250, about half of TypeSafe Jev 1.14 (0.0494). It is a trade-off though: Jev 1.14 wins When2Call (82.0% vs 79.9%) and costs less on the shared suite ($0.68 vs $0.88).
Pricing is $0.10 per 1M input tokens, $0 output, with a free tier in AI Studio. Google reports 150-250 ms end-to-end latency. No context caching or Batch API yet......
Full analysis: https://t.co/hCLi21dHNH
Blog: https://t.co/EOKwbJ4u8R
Docs: https://t.co/gxdvXZG9lC
Model: https://t.co/wqiUiqagnH
@GoogleAIStudio@OfficialLoganK@Google
▲ Google just released the Gemini Decisions API, powered by Gemini Decision 1, a model that answers typed questions instead of writing text.
The key idea is scoring, not generating. You send 1 shared input (text, images, audio, video or PDFs, up to 256K tokens) plus up to 1,000 yes/no, choice or rubric questions. The model scores every option in 1 forward pass and returns calibrated probabilities with a confidence value. Output tokens are always 0.
On Google's benchmark table, it leads 7 of 9 accuracy tests, including 92.2% on JevBench vs 90.9% for GPT-6 Luna on OpenAI's Decisions API. Its calibration error is 0.0250, about half of TypeSafe Jev 1.14 (0.0494). It is a trade-off though: Jev 1.14 wins When2Call (82.0% vs 79.9%) and costs less on the shared suite ($0.68 vs $0.88).
Pricing is $0.10 per 1M input tokens, $0 output, with a free tier in AI Studio. Google reports 150-250 ms end-to-end latency. No context caching or Batch API yet......
Full analysis: https://t.co/hCLi21dHNH
Blog: https://t.co/EOKwbJ4u8R
Docs: https://t.co/gxdvXZG9lC
Model: https://t.co/wqiUiqagnH
@GoogleAIStudio@OfficialLoganK@Google
▲ Google just released the Gemini Decisions API, powered by Gemini Decision 1, a model that answers typed questions instead of writing text.
The key idea is scoring, not generating. You send 1 shared input (text, images, audio, video or PDFs, up to 256K tokens) plus up to 1,000 yes/no, choice or rubric questions. The model scores every option in 1 forward pass and returns calibrated probabilities with a confidence value. Output tokens are always 0.
On Google's benchmark table, it leads 7 of 9 accuracy tests, including 92.2% on JevBench vs 90.9% for GPT-6 Luna on OpenAI's Decisions API. Its calibration error is 0.0250, about half of TypeSafe Jev 1.14 (0.0494). It is a trade-off though: Jev 1.14 wins When2Call (82.0% vs 79.9%) and costs less on the shared suite ($0.68 vs $0.88).
Pricing is $0.10 per 1M input tokens, $0 output, with a free tier in AI Studio. Google reports 150-250 ms end-to-end latency. No context caching or Batch API yet......
Full analysis: https://t.co/hCLi21dHNH
Blog: https://t.co/EOKwbJ4u8R
Docs: https://t.co/gxdvXZG9lC
Model: https://t.co/wqiUiqagnH
@GoogleAIStudio@OfficialLoganK@Google
▲ Google just released the Gemini Decisions API, powered by Gemini Decision 1, a model that answers typed questions instead of writing text.
The key idea is scoring, not generating. You send 1 shared input (text, images, audio, video or PDFs, up to 256K tokens) plus up to 1,000 yes/no, choice or rubric questions. The model scores every option in 1 forward pass and returns calibrated probabilities with a confidence value. Output tokens are always 0.
On Google's benchmark table, it leads 7 of 9 accuracy tests, including 92.2% on JevBench vs 90.9% for GPT-6 Luna on OpenAI's Decisions API. Its calibration error is 0.0250, about half of TypeSafe Jev 1.14 (0.0494). It is a trade-off though: Jev 1.14 wins When2Call (82.0% vs 79.9%) and costs less on the shared suite ($0.68 vs $0.88).
Pricing is $0.10 per 1M input tokens, $0 output, with a free tier in AI Studio. Google reports 150-250 ms end-to-end latency. No context caching or Batch API yet......
Full analysis: https://t.co/hCLi21dHNH
Blog: https://t.co/EOKwbJ4u8R
Docs: https://t.co/gxdvXZG9lC
Model: https://t.co/wqiUiqagnH
@GoogleAIStudio@OfficialLoganK@Google
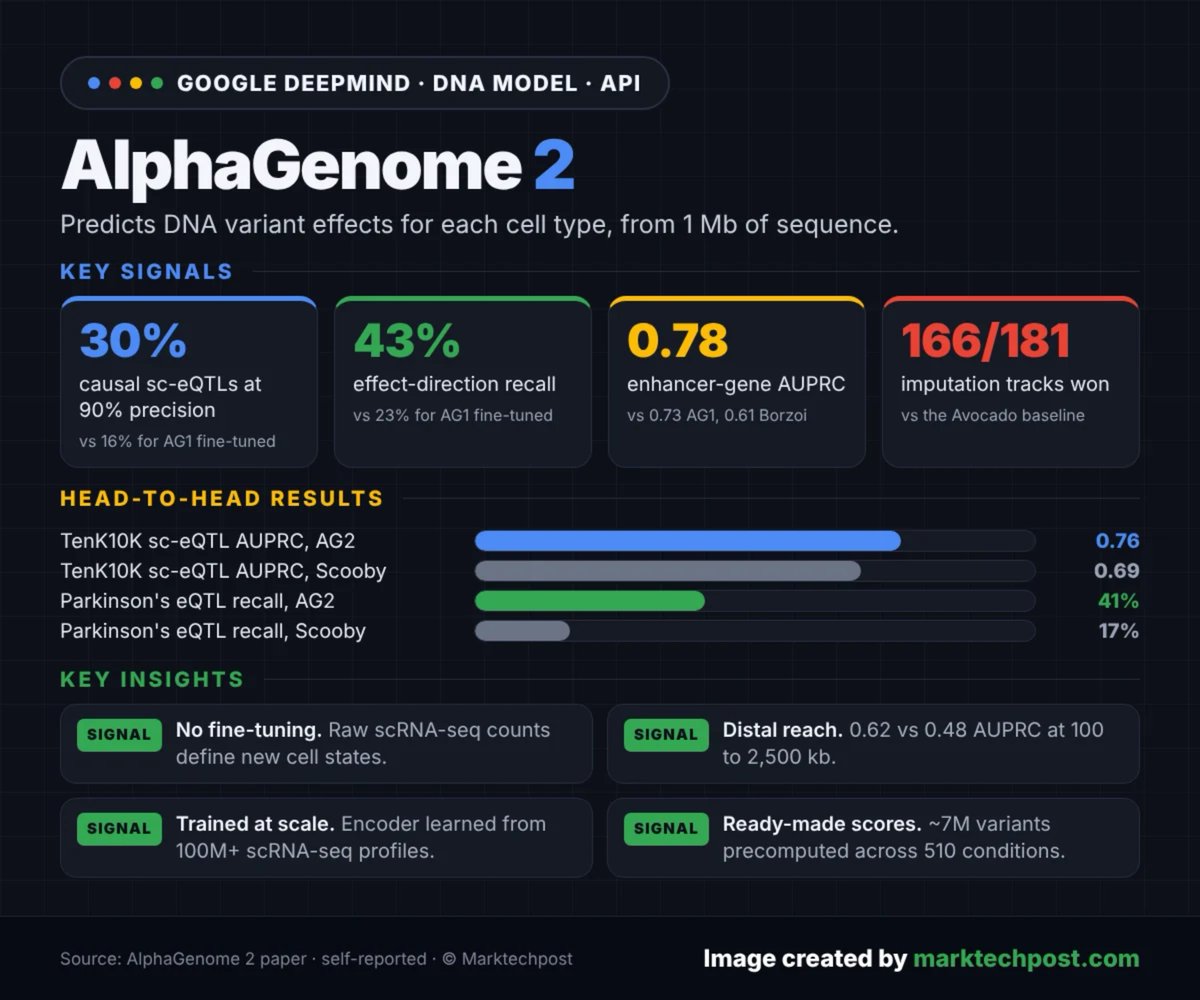
▲ Google DeepMind just released AlphaGenome 2, a DNA model that predicts variant effects in specific cell types instead of tissue averages.
The key idea is conditioning. The model reads 1 Mb of DNA plus 1 target condition, a tissue, cell type or cell state. A 256-d embedding modulates the encoder, transformer and decoder. You can also build that condition from raw scRNA-seq counts, with no fine-tuning.
On TenK10K single-cell eQTLs, it recovers 30% of causal variants at 90% precision. AlphaGenome 1 fine-tuned on single-cell data recovers 16%. Enhancer-gene AUPRC is 0.78 vs 0.73. It is a trade-off though: outside accessible chromatin, sign prediction AUROC tops out at 0.63.
Available now via the AlphaGenome API, free for non-commercial research. .
Full analysis: https://t.co/9Fg6yNeTY8
Paper: https://t.co/TKN1hto4LZ
Docs: https://t.co/cXDVea1yIw
Blog: https://t.co/3kNrvSE0HY
@GoogleDeepMind@pushmeet@sundarpichai
▲ Google DeepMind just released AlphaGenome 2, a DNA model that predicts variant effects in specific cell types instead of tissue averages.
The key idea is conditioning. The model reads 1 Mb of DNA plus 1 target condition, a tissue, cell type or cell state. A 256-d embedding modulates the encoder, transformer and decoder. You can also build that condition from raw scRNA-seq counts, with no fine-tuning.
On TenK10K single-cell eQTLs, it recovers 30% of causal variants at 90% precision. AlphaGenome 1 fine-tuned on single-cell data recovers 16%. Enhancer-gene AUPRC is 0.78 vs 0.73. It is a trade-off though: outside accessible chromatin, sign prediction AUROC tops out at 0.63.
Available now via the AlphaGenome API, free for non-commercial research. .
Full analysis: https://t.co/9Fg6yNeTY8
Paper: https://t.co/TKN1hto4LZ
Docs: https://t.co/cXDVea1yIw
Blog: https://t.co/3kNrvSE0HY
@GoogleDeepMind@pushmeet@sundarpichai
▲ Google DeepMind just released AlphaGenome 2, a DNA model that predicts variant effects in specific cell types instead of tissue averages.
The key idea is conditioning. The model reads 1 Mb of DNA plus 1 target condition, a tissue, cell type or cell state. A 256-d embedding modulates the encoder, transformer and decoder. You can also build that condition from raw scRNA-seq counts, with no fine-tuning.
On TenK10K single-cell eQTLs, it recovers 30% of causal variants at 90% precision. AlphaGenome 1 fine-tuned on single-cell data recovers 16%. Enhancer-gene AUPRC is 0.78 vs 0.73. It is a trade-off though: outside accessible chromatin, sign prediction AUROC tops out at 0.63.
Available now via the AlphaGenome API, free for non-commercial research. .
Full analysis: https://t.co/9Fg6yNeTY8
Paper: https://t.co/TKN1hto4LZ
Docs: https://t.co/cXDVea1yIw
Blog: https://t.co/3kNrvSE0HY
@GoogleDeepMind@pushmeet@sundarpichai
▲ Google DeepMind just released AlphaGenome 2, a DNA model that predicts variant effects in specific cell types instead of tissue averages.
The key idea is conditioning. The model reads 1 Mb of DNA plus 1 target condition, a tissue, cell type or cell state. A 256-d embedding modulates the encoder, transformer and decoder. You can also build that condition from raw scRNA-seq counts, with no fine-tuning.
On TenK10K single-cell eQTLs, it recovers 30% of causal variants at 90% precision. AlphaGenome 1 fine-tuned on single-cell data recovers 16%. Enhancer-gene AUPRC is 0.78 vs 0.73. It is a trade-off though: outside accessible chromatin, sign prediction AUROC tops out at 0.63.
Available now via the AlphaGenome API, free for non-commercial research. .
Full analysis: https://t.co/9Fg6yNeTY8
Paper: https://t.co/TKN1hto4LZ
Docs: https://t.co/cXDVea1yIw
Blog: https://t.co/3kNrvSE0HY
@GoogleDeepMind@pushmeet@sundarpichai
▲ Fish Audio just released Live 3, a full-duplex voice model that keeps listening while it speaks, so voice agents stop talking over callers.
The key idea is moving turn-taking into the speech model itself. Instead of silence thresholds and hand-written rules, Live 3 was trained on real human conversations. It learns when to acknowledge, wait, respond or stop, so "yeah" lets it keep going while "wait, actually" makes it yield.
Fish Audio says Live 3 can decide to react in as little as 186 ms for short cues like "mm-hmm" or "okay, 415". For context, Eleven Realtime v1 Max reports 0.57 s average time to first audio, a different measurement. It is a trade-off though: Live 3 is English only at launch, and Fish Audio has published 0 benchmark scores so far.
It runs on the Fish Agent Platform, the Fish Audio API and on-prem for enterprises. Agents are $0.035/min until Dec 31, 2026 ($0.07 list), covering STT, TTS and basic LLMs......
Full analysis: https://t.co/0SPYCw6p1v
Technical details: https://t.co/qOxld9WIfk
Try it: https://t.co/VEnhf5gUCg
Docs: https://t.co/JmM8RYni71
@FishAudio@rissa_cao@LengyueMatrix
▲ Fish Audio just released Live 3, a full-duplex voice model that keeps listening while it speaks, so voice agents stop talking over callers.
The key idea is moving turn-taking into the speech model itself. Instead of silence thresholds and hand-written rules, Live 3 was trained on real human conversations. It learns when to acknowledge, wait, respond or stop, so "yeah" lets it keep going while "wait, actually" makes it yield.
Fish Audio says Live 3 can decide to react in as little as 186 ms for short cues like "mm-hmm" or "okay, 415". For context, Eleven Realtime v1 Max reports 0.57 s average time to first audio, a different measurement. It is a trade-off though: Live 3 is English only at launch, and Fish Audio has published 0 benchmark scores so far.
It runs on the Fish Agent Platform, the Fish Audio API and on-prem for enterprises. Agents are $0.035/min until Dec 31, 2026 ($0.07 list), covering STT, TTS and basic LLMs......
Full analysis: https://t.co/0SPYCw6p1v
Technical details: https://t.co/qOxld9WIfk
Try it: https://t.co/VEnhf5gUCg
Docs: https://t.co/JmM8RYni71
@FishAudio@rissa_cao@LengyueMatrix
▲ Anthropic just released Claude Fable 5.2 and Claude Mythos 5.2, an upgrade that beats Opus 5.5 on most of its own benchmarks at a lower price.
The key idea is 1 model with 2 safeguard levels. Fable 5.2 runs classifiers that block high-risk cyber and research-biology requests, then hands those to Opus 4.8 or Opus 5. Mythos 5.2 is the same model without those blocks, for vetted orgs only.
On FrontierCode 2.0, Fable 5.2 scores 49.1% at Xhigh effort, vs 45.5% for Opus 5.5 and 42.8% for GPT-6 Astra. At High effort it matches Opus 5.5's best score for roughly half the cost per task. It is a trade-off though: Gemini 4 Carbon still leads AutomationBench (53.9% vs 51.4%), and every score is self-reported.
Pricing is $8 / $40 per million tokens, with a 1M-token context window and 128K output. Fast mode runs up to 2.5x faster at $16 / $80. API ID: claude-fable-5-2......
Full analysis: https://t.co/ncmOMMDbQA
Launch post: https://t.co/m7P6pIzzs1
Docs: https://t.co/oRKDbIIkYz
System card: https://t.co/c06QVL9k5N
@AnthropicAI@claudeai
▲ Zyphra just open-sourced ZONOS3-Mini, a text-to-speech model that clones voices and runs in real time on a phone or laptop.
The key idea is sparsity. It is a Mixture of Experts with 800M total parameters, but only about 100M are active per token. A new 15 Hz codec (ZAC-1) cuts the number of frames the model has to generate.
On Zyphra's ZTTS2-Eval it scores 66.2 on the Capability Index, ahead of Fish Audio S2 Pro (61.7) and MOSS-TTS v1.5 (60.2). Clean-set WER is 7.79 vs 11.06 for Fish S2 Pro. Time to first audio is 80 ms on 1 H100. It is a trade-off though: all of this is Zyphra's own benchmark, and reference-clip cloning drops to 44.7 on the same index.
Weights are Apache 2.0. Runtimes cover WebGPU in the browser, MLX, ggml and SGLang-Omni, plus a hosted API on Zyphra Cloud......
Full analysis: https://t.co/eTqUA0KNet
Model: https://t.co/vGYgUqAGJN
Repo: https://t.co/C5kksB09vK
Blog: https://t.co/XUiO87yUs8
Playground: https://t.co/XKHsn1wXFd
@ZyphraAI
▲ Meta FAIR just open-sourced e-means, a drop-in replacement for k-means that reaches the same loss in about one-tenth the epochs.
The key idea is simple. Lloyd's k-means recomputes every centroid from the full dataset each pass. e-means reads small mini-batches and keeps an exponential moving average of each cluster's sum and count. Two fitted scaling laws pick the batch size and step size from n, k and epochs, so there is nothing to tune beyond k.
The numbers: e-means beats Lloyd's 25-epoch loss in 1.4 to 2.6 epochs. That is a 10-45x GPU speedup vs Flash-KMeans and 8-15x on CPU vs Faiss. It also clustered 10 billion DINO embeddings into 16.7M clusters in 2.5 epochs. It is a trade-off though: runs are stochastic, and 16.7M centroids need 64 GiB of float32 accumulators, so they must be sharded. All results are self-reported.
Full analysis: https://t.co/NtuC4RjuRn
Paper: https://t.co/FtgD5Qtie7
Repo: https://t.co/emBkQ4hTWE
Blog: https://t.co/GMcSkdAQzd
@swann_bessa
▲ Meta FAIR just open-sourced e-means, a drop-in replacement for k-means that reaches the same loss in about one-tenth the epochs.
The key idea is simple. Lloyd's k-means recomputes every centroid from the full dataset each pass. e-means reads small mini-batches and keeps an exponential moving average of each cluster's sum and count. Two fitted scaling laws pick the batch size and step size from n, k and epochs, so there is nothing to tune beyond k.
The numbers: e-means beats Lloyd's 25-epoch loss in 1.4 to 2.6 epochs. That is a 10-45x GPU speedup vs Flash-KMeans and 8-15x on CPU vs Faiss. It also clustered 10 billion DINO embeddings into 16.7M clusters in 2.5 epochs. It is a trade-off though: runs are stochastic, and 16.7M centroids need 64 GiB of float32 accumulators, so they must be sharded. All results are self-reported.
Full analysis: https://t.co/NtuC4RjuRn
Paper: https://t.co/FtgD5Qtie7
Repo: https://t.co/emBkQ4hTWE
Blog: https://t.co/GMcSkdAQzd
@swann_bessa
▲ Meta FAIR just open-sourced e-means, a drop-in replacement for k-means that reaches the same loss in about one-tenth the epochs.
The key idea is simple. Lloyd's k-means recomputes every centroid from the full dataset each pass. e-means reads small mini-batches and keeps an exponential moving average of each cluster's sum and count. Two fitted scaling laws pick the batch size and step size from n, k and epochs, so there is nothing to tune beyond k.
The numbers: e-means beats Lloyd's 25-epoch loss in 1.4 to 2.6 epochs. That is a 10-45x GPU speedup vs Flash-KMeans and 8-15x on CPU vs Faiss. It also clustered 10 billion DINO embeddings into 16.7M clusters in 2.5 epochs. It is a trade-off though: runs are stochastic, and 16.7M centroids need 64 GiB of float32 accumulators, so they must be sharded. All results are self-reported.
Full analysis: https://t.co/NtuC4RjuRn
Paper: https://t.co/FtgD5Qtie7
Repo: https://t.co/emBkQ4hTWE
Blog: https://t.co/GMcSkdAQzd
@swann_bessa
▲ Zyphra just open-sourced ZONOS3-Mini, a text-to-speech model that clones voices and runs in real time on a phone or laptop.
The key idea is sparsity. It is a Mixture of Experts with 800M total parameters, but only about 100M are active per token. A new 15 Hz codec (ZAC-1) cuts the number of frames the model has to generate.
On Zyphra's ZTTS2-Eval it scores 66.2 on the Capability Index, ahead of Fish Audio S2 Pro (61.7) and MOSS-TTS v1.5 (60.2). Clean-set WER is 7.79 vs 11.06 for Fish S2 Pro. Time to first audio is 80 ms on 1 H100. It is a trade-off though: all of this is Zyphra's own benchmark, and reference-clip cloning drops to 44.7 on the same index.
Weights are Apache 2.0. Runtimes cover WebGPU in the browser, MLX, ggml and SGLang-Omni, plus a hosted API on Zyphra Cloud......
Full analysis: https://t.co/eTqUA0KNet
Model: https://t.co/vGYgUqAGJN
Repo: https://t.co/C5kksB09vK
Blog: https://t.co/XUiO87yUs8
Playground: https://t.co/XKHsn1wXFd
@ZyphraAI
▲ Zyphra just open-sourced ZONOS3-Mini, a text-to-speech model that clones voices and runs in real time on a phone or laptop.
The key idea is sparsity. It is a Mixture of Experts with 800M total parameters, but only about 100M are active per token. A new 15 Hz codec (ZAC-1) cuts the number of frames the model has to generate.
On Zyphra's ZTTS2-Eval it scores 66.2 on the Capability Index, ahead of Fish Audio S2 Pro (61.7) and MOSS-TTS v1.5 (60.2). Clean-set WER is 7.79 vs 11.06 for Fish S2 Pro. Time to first audio is 80 ms on 1 H100. It is a trade-off though: all of this is Zyphra's own benchmark, and reference-clip cloning drops to 44.7 on the same index.
Weights are Apache 2.0. Runtimes cover WebGPU in the browser, MLX, ggml and SGLang-Omni, plus a hosted API on Zyphra Cloud......
Full analysis: https://t.co/eTqUA0KNet
Model: https://t.co/vGYgUqAGJN
Repo: https://t.co/C5kksB09vK
Blog: https://t.co/XUiO87yUs8
Playground: https://t.co/XKHsn1wXFd
@ZyphraAI
▲ Anthropic just released Claude Fable 5.2 and Claude Mythos 5.2, an upgrade that beats Opus 5.5 on most of its own benchmarks at a lower price.
The key idea is 1 model with 2 safeguard levels. Fable 5.2 runs classifiers that block high-risk cyber and research-biology requests, then hands those to Opus 4.8 or Opus 5. Mythos 5.2 is the same model without those blocks, for vetted orgs only.
On FrontierCode 2.0, Fable 5.2 scores 49.1% at Xhigh effort, vs 45.5% for Opus 5.5 and 42.8% for GPT-6 Astra. At High effort it matches Opus 5.5's best score for roughly half the cost per task. It is a trade-off though: Gemini 4 Carbon still leads AutomationBench (53.9% vs 51.4%), and every score is self-reported.
Pricing is $8 / $40 per million tokens, with a 1M-token context window and 128K output. Fast mode runs up to 2.5x faster at $16 / $80. API ID: claude-fable-5-2......
Full analysis: https://t.co/ncmOMMDbQA
Launch post: https://t.co/m7P6pIzzs1
Docs: https://t.co/oRKDbIIkYz
System card: https://t.co/c06QVL9k5N
@AnthropicAI@claudeai