Senior Python Developer & Systems Research.
Deconstructing libraries to reveal the architecture behind the magic.
I read the source code so you don’t have to.
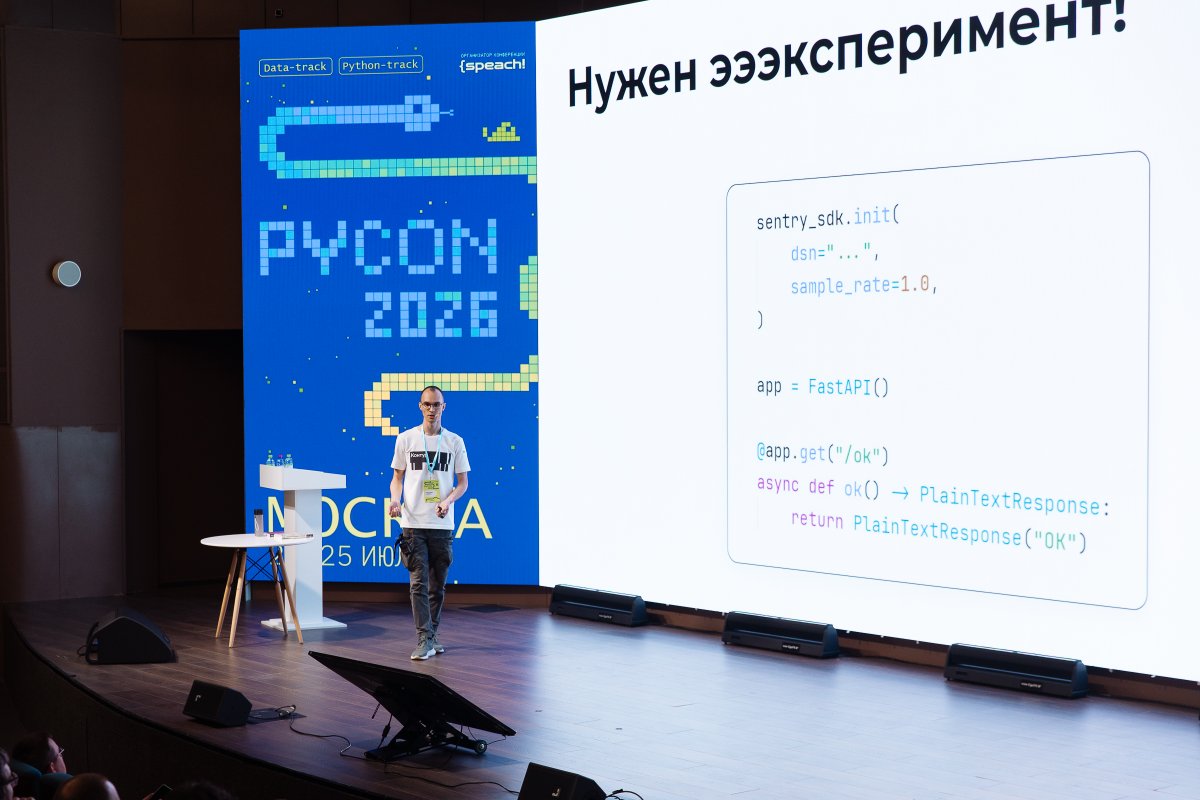
I spoke at #PyCon Russia for the second time, and I won Best Speaker again 🏆 Very happy about this! My talk was about making a typical app much faster — many more requests per second. I will post the video link when it is online. #Python
Settled on AMD Ryzen AI Max+ 395 128GB for its price/performance balance, but will wait for builds from trusted manufacturers — don't want to deal with teething issues of first-wave mini PCs on this chip. #AI#LLM
Can't stop thinking about running LLMs locally. Tried it on my AMD Ryzen 7 8845H + Radeon 780M 32GB — not enough for serious models. Now eyeing a MacBook, NVIDIA DGX Spark, or AMD Ryzen AI Max+ 395 128GB (my favorite so far). #AI#LLM
Really want to bombard AI with tons of questions and tasks for my projects without worrying about limits on cloud providers' paid plans. Plus, use the same setup for both work and personal projects.
Can't stop thinking about running LLMs locally. Tried it on my AMD Ryzen 7 8845H + Radeon 780M 32GB — not enough for serious models. Now eyeing a MacBook, NVIDIA DGX Spark, or AMD Ryzen AI Max+ 395 128GB (my favorite so far). #AI#LLM
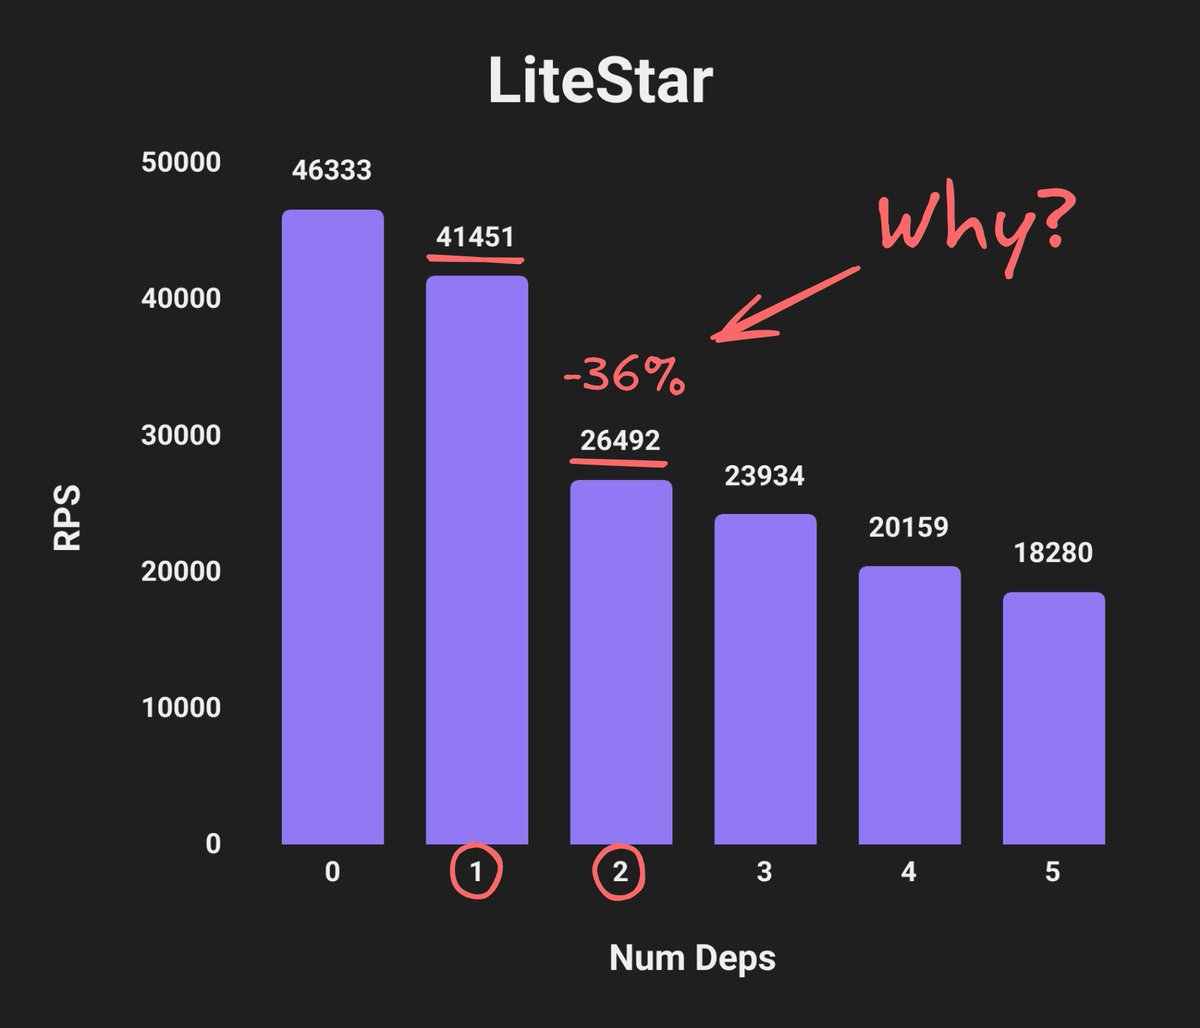
Testing #FastAPI vs #LiteStar with nested empty deps (0-5 levels).
Both show smooth perf degradation, unlike LiteStar's flat deps with TaskGroup.
Still, 5 deps = 28% drop for LiteStar -- DI overhead is significant even when deps do nothing.
#Python
Quick perf test: changed #LiteStar dependency resolution from TaskGroup to await.
RPS impact? Minimal vs 17% degradation with TaskGroup at 4 deps. Each request does 4 DB calls.
TaskGroup overhead matters more than expected.
More details in thread 👇
#Python#Backend
Conclusion: The results further confirm the hypothesis that RPS degrades specifically due to high TaskGroup overhead. 🛠️ This optimization is exactly what I’m proposing in the GitHub issue: https://t.co/XBxTq631w2
My #PyCon RU 2025 talk (Best Speaker award! 🏆) is now on YouTube: https://t.co/xS057u7mEs
English subtitles available! 🇬🇧
I break down the Dependency Inversion Principle, compare popular #Python#DI frameworks, and show why they matter for building better applications.
In the previous thread, Litestar's RPS dropped 36% with 2+ flat dependencies due to TaskGroup overhead. 📉
How do #Litestar and #FastAPI perform with real DB queries in dependencies? Let's figure it out in this thread 🧵
#Python
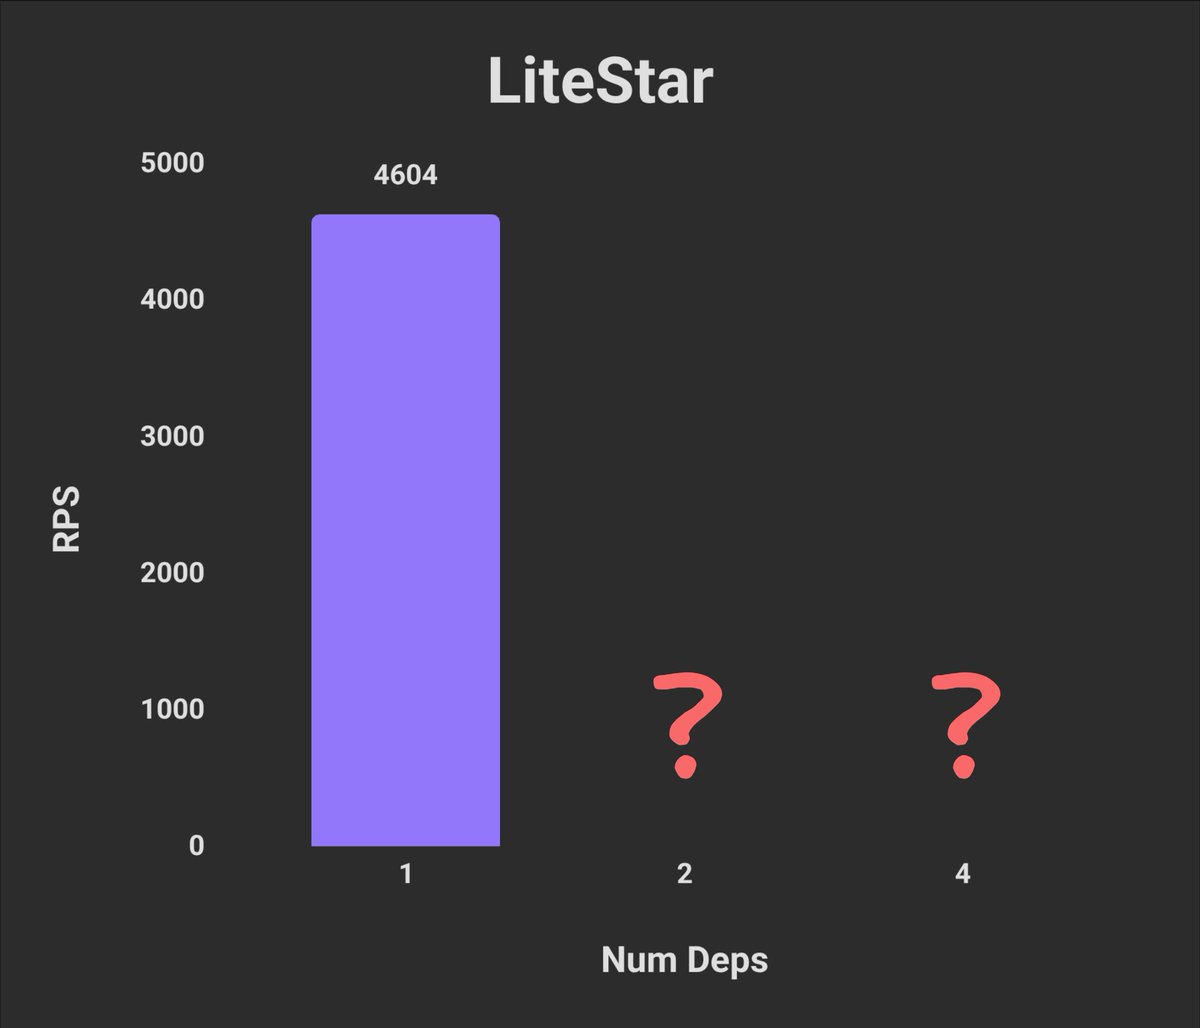
Is #LiteStar faster than #FastAPI? Benchmarks say yes, but look at Dependency Injection. 📉
Adding just 2 flat dependencies significantly degrades the throughput. I dug into the source to find why.
Thread: TaskGroups, Kahn's algorithm & performance trade-offs. 🧵
Conclusion: Even when the application performs a significant amount of logic (event loop, HTTP parsing, routing, 4 DB queries), dependency injection overhead remains substantial.
Is #LiteStar faster than #FastAPI? Benchmarks say yes, but look at Dependency Injection. 📉
Adding just 2 flat dependencies significantly degrades the throughput. I dug into the source to find why.
Thread: TaskGroups, Kahn's algorithm & performance trade-offs. 🧵
That’s a wrap for now! 🧵
I have plenty of niche details and "deleted scenes" from this research that didn't fit into these posts. I’ll be sharing these extra insights over the next 2 weeks.
Follow along so you don’t miss the upcoming deep dives! 🐍🔍
Is #LiteStar faster than #FastAPI? Benchmarks say yes, but look at Dependency Injection. 📉
Adding just 2 flat dependencies significantly degrades the throughput. I dug into the source to find why.
Thread: TaskGroups, Kahn's algorithm & performance trade-offs. 🧵
Don't take my word for it — verify it yourself. 🛠️
I've published the full benchmark code on GitHub so you can run the tests and see the results on your own machine.
https://t.co/ppJcNSZrsN