HPC performance monitoring, without the extra baggage. ⚡
Ershaad Basheer’s approach combines eBPF with LDMS to collect kernel-level metrics and track filesystem latency in real time.
Measure the system without making measurement the bottleneck.
@P99CONF@ScyllaDB#P99CONF
Key takeaways from @curious_coding session at #P99CONF :
🔹 Memory access bottlenecks priority queues.
🔹 SIMD-friendly layouts beat traditional heaps.
🔹 SimdQuickHeap is up to 2× faster than radix heaps.
Data layout matters! ⚡
@P99CONF@ScyllaDB#ScyllaDB
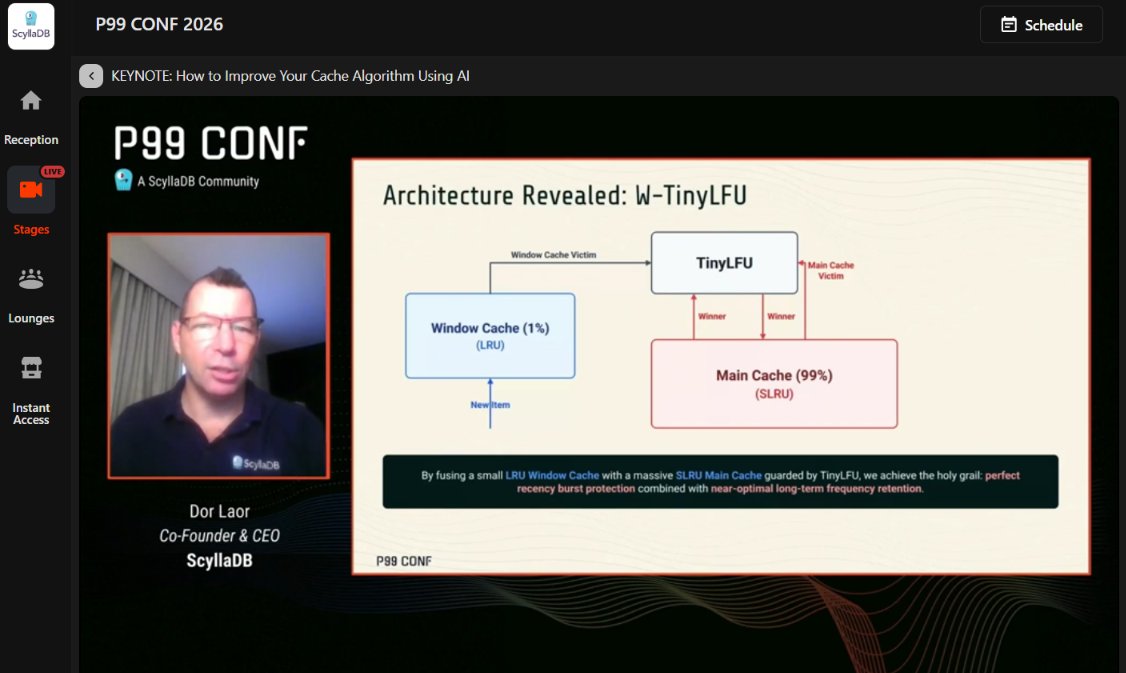
Can AI improve cache algorithms?
@DorLaor keynote explored W-TinyLFU, combining LRU and SLRU to balance burst protection with long-term frequency.
Key takeaway: Smarter cache admission can improve hit rates and protect performance during scans.
@P99CONF@ScyllaDB#P99CONF
Me: “I’ll attend a few P99 CONF sessions and sleep early.” 😴
Also me at 11 PM: learning SIMD, 100B vector search, QUIC, and database optimizations… while tweeting takeaways. 😂
Performance matters. So does sleep. Apparently, I chose performance. 💀
@P99CONF@ScyllaDB#P99CONF
Great insights from Felipe Mendes and Guilherme Nogueira at P99 CONF 2026!
📊 Live dashboards bring visibility into:
🔹 Request throughput
🔹 Read/write activity
🔹 Tablet distribution and load
@P99CONF@ScyllaDB#ScyllaDB#P99CONF#GRAFANA
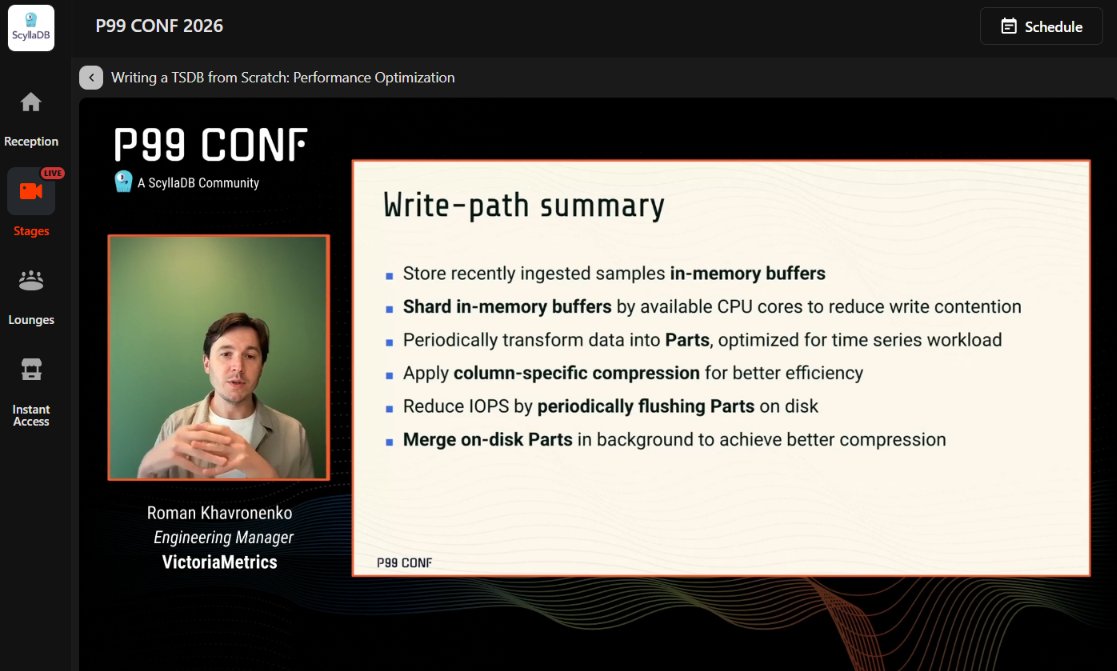
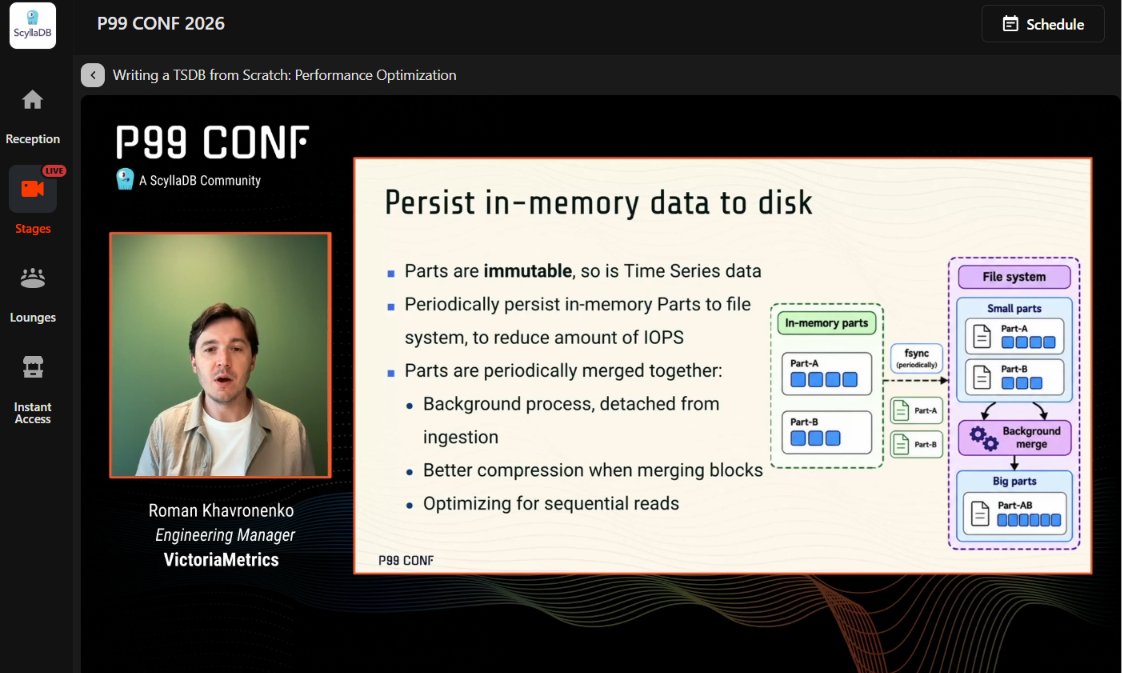
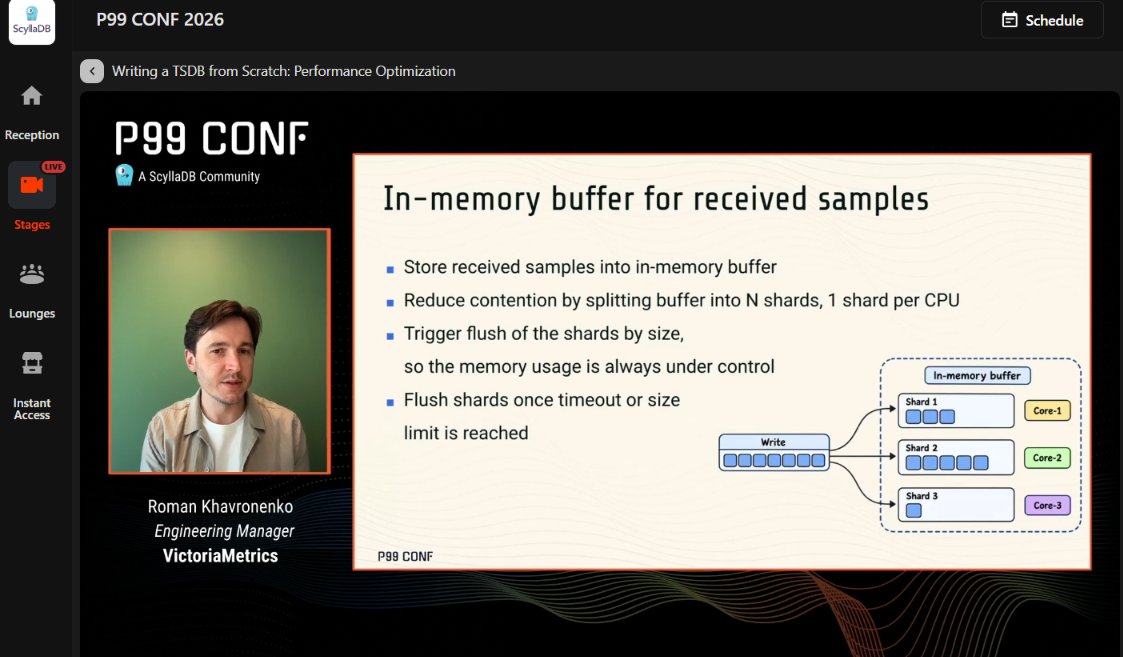
TSDB takeaways from @hagen1778 :
🔹 Shard buffers to reduce write contention.
🔹 Merge parts for better compression.
🔹 Filter by series ID and timestamp.
🔹 Process blocks concurrently for faster reads.
@P99CONF@ScyllaDB#ScyllaDB#P99CONF
The real challenge in TSDB performance? Making every stage of the data pipeline count.
@hagen1778 's approach:
⚡ Buffer writes in memory
⚡ Persist and merge data efficiently
⚡ Parallelize CPU-heavy query processing
Great insights into database engineering!
@P99CONF@ScyllaDB
Building a fast time-series database is about more than ingesting data. It’s about how efficiently you store, filter and process it.
@hagen1778 highlights smart data layouts, efficient reads and performance optimization.
@P99CONF@ScyllaDB#ScyllaDB#P99CONF
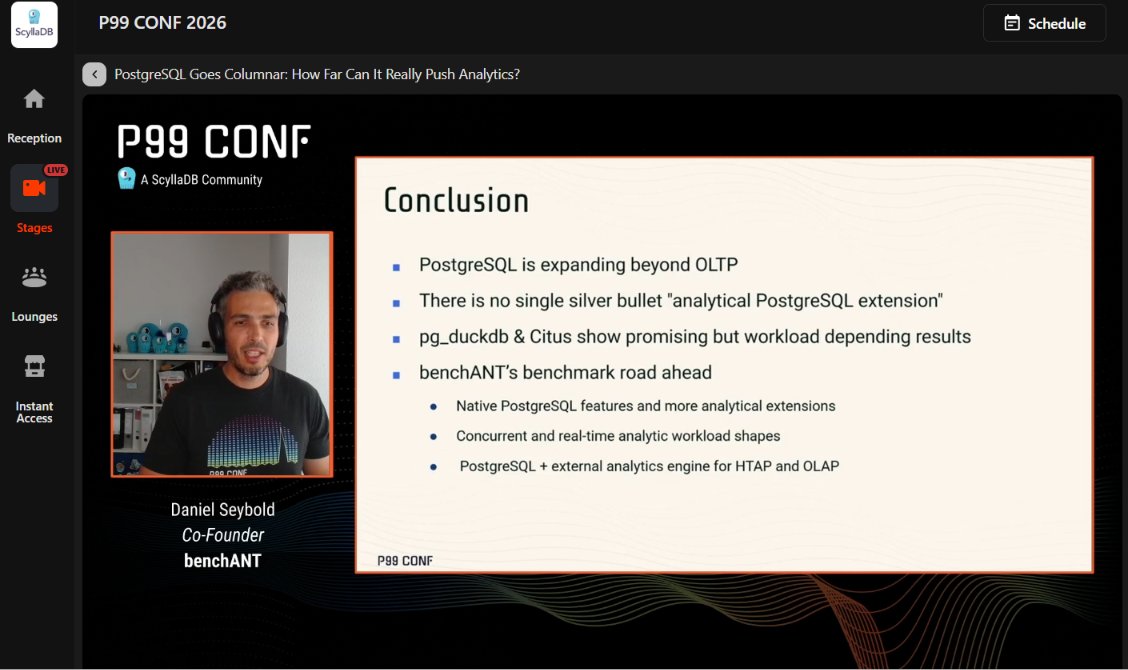
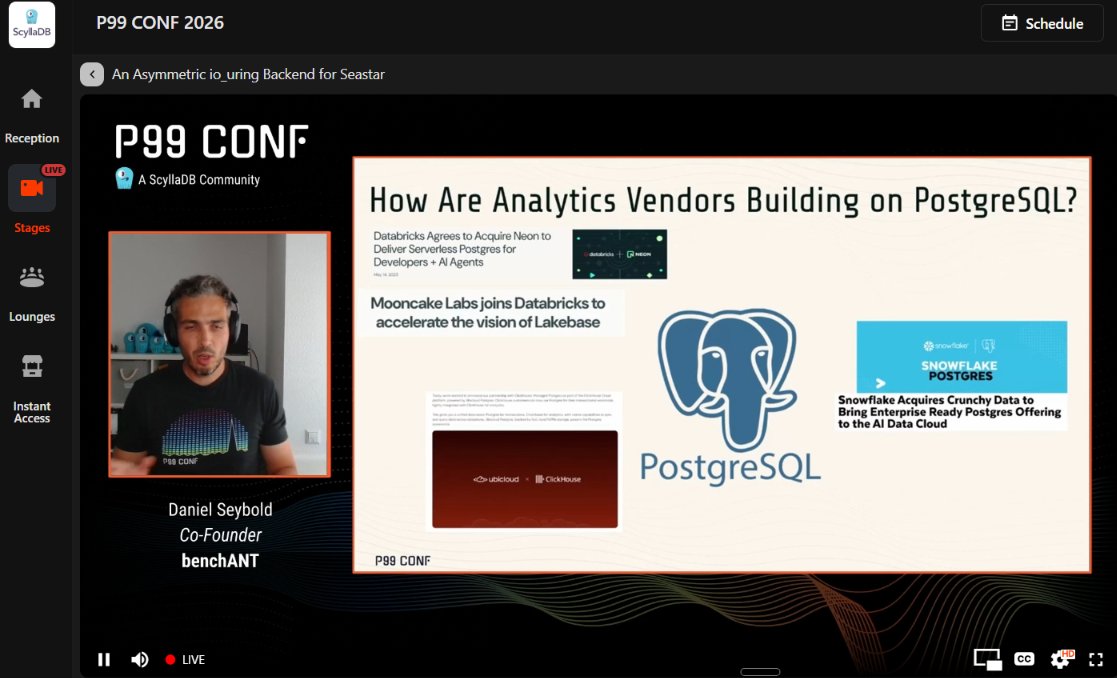
There’s no universal winner in analytical query performance!
Daniel Seybold’s benchmark insights:
🔹 Compares PostgreSQL, pg_duckdb, Citus and ClickHouse.
🔹 Evaluates ClickBench and TPC-DS.
🔹 Best performance depends on workload.
@P99CONF@ScyllaDB#P99CONF@duckdb@PostgreSQL
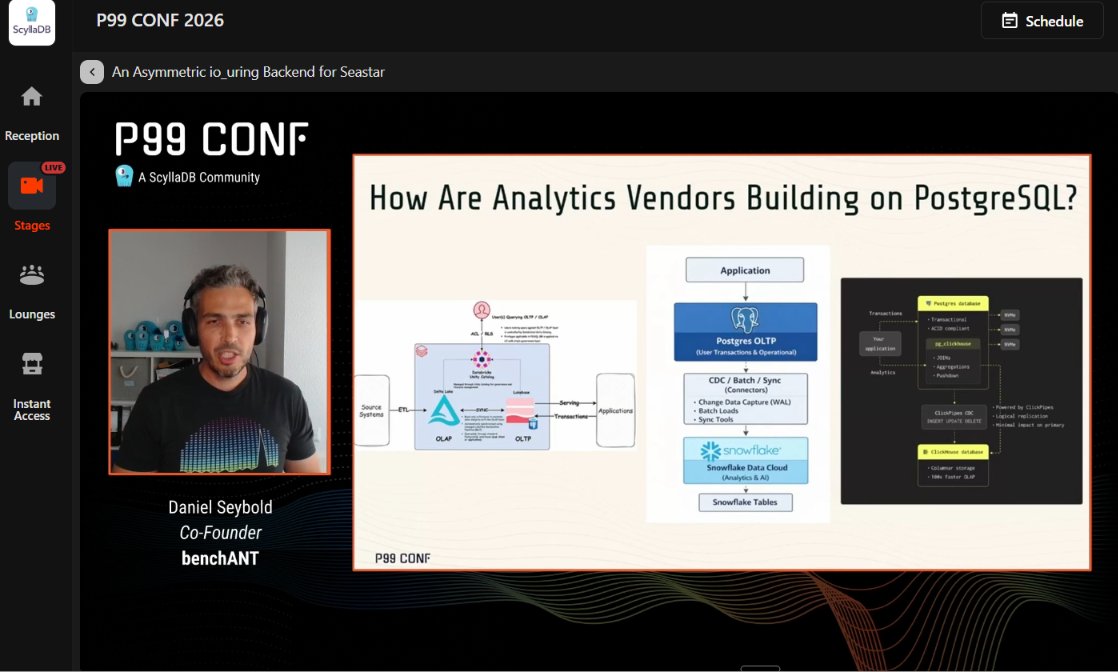
Can PostgreSQL handle analytics with minimal code changes?
Daniel Seybold highlights:
🔹 pg_duckdb brings DuckDB’s vectorized execution to PostgreSQL.
🔹 Supports analytics and data lake integration.
🔹 Extends PostgreSQL’s analytical capabilities.
@p99conf@ScyllaDB#P99CONF
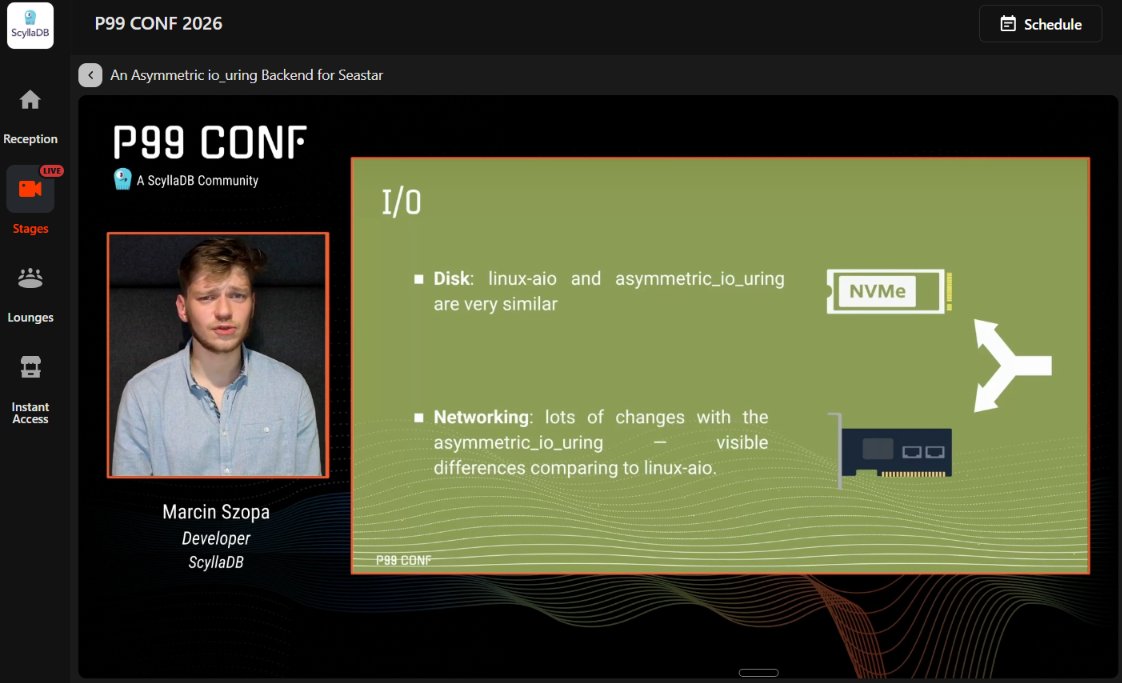
🚀 What happens when networking becomes a bottleneck?
At #P99CONF 2026, @MarcinSzopa explores the asymmetric io_uring backend for Seastar.
💡 Key takeaway: Profiling CPU overhead and identifying I/O bottlenecks are essential to improving throughput.
@P99CONF@ScyllaDB#ScyllaDB
How can smarter I/O improve system performance?
At #P99CONF 2026, @JakubCzyszczon shares insights on dedicated networking cores and io_uring.
💡 Key takeaway: Reducing CPU contention and optimizing interrupt handling can improve I/O efficiency.
@P99CONF@ScyllaDB#ScyllaDB
🔍 When network performance suddenly collapses, the root cause may be deep inside the Linux kernel.
At #P99CONF 2026, @Daniel_Sedlak98 explores how debugging Nginx throughput revealed a TCP memory-pressure issue and led to a kernel contribution.
@ScyllaDB#P99CONF#ScyllaDB
💡 Key takeaways from @elvisnchidera#P99CONF session:
HTTP/3 can reduce connection handshake latency and network failures, but packet loss and congestion control can impact throughput. Always validate performance with real-world A/B tests!
Learning from @ScyllaDB.
#ScyllaDB