Key takeaways from @curious_coding session at #P99CONF :
🔹 Memory access bottlenecks priority queues.
🔹 SIMD-friendly layouts beat traditional heaps.
🔹 SimdQuickHeap is up to 2× faster than radix heaps.
Data layout matters! ⚡
@P99CONF@ScyllaDB#ScyllaDB
Binary heaps are cache-inefficient and cause a cache miss on nearly every pop. In 20 minutes, @curious_coding dives into SimdQuickHeap and how it results in a priority queue that is up to 10x faster than binary and d-ary heaps. https://t.co/tVBWM2b0ub
#ScyllaDB#P99CONF
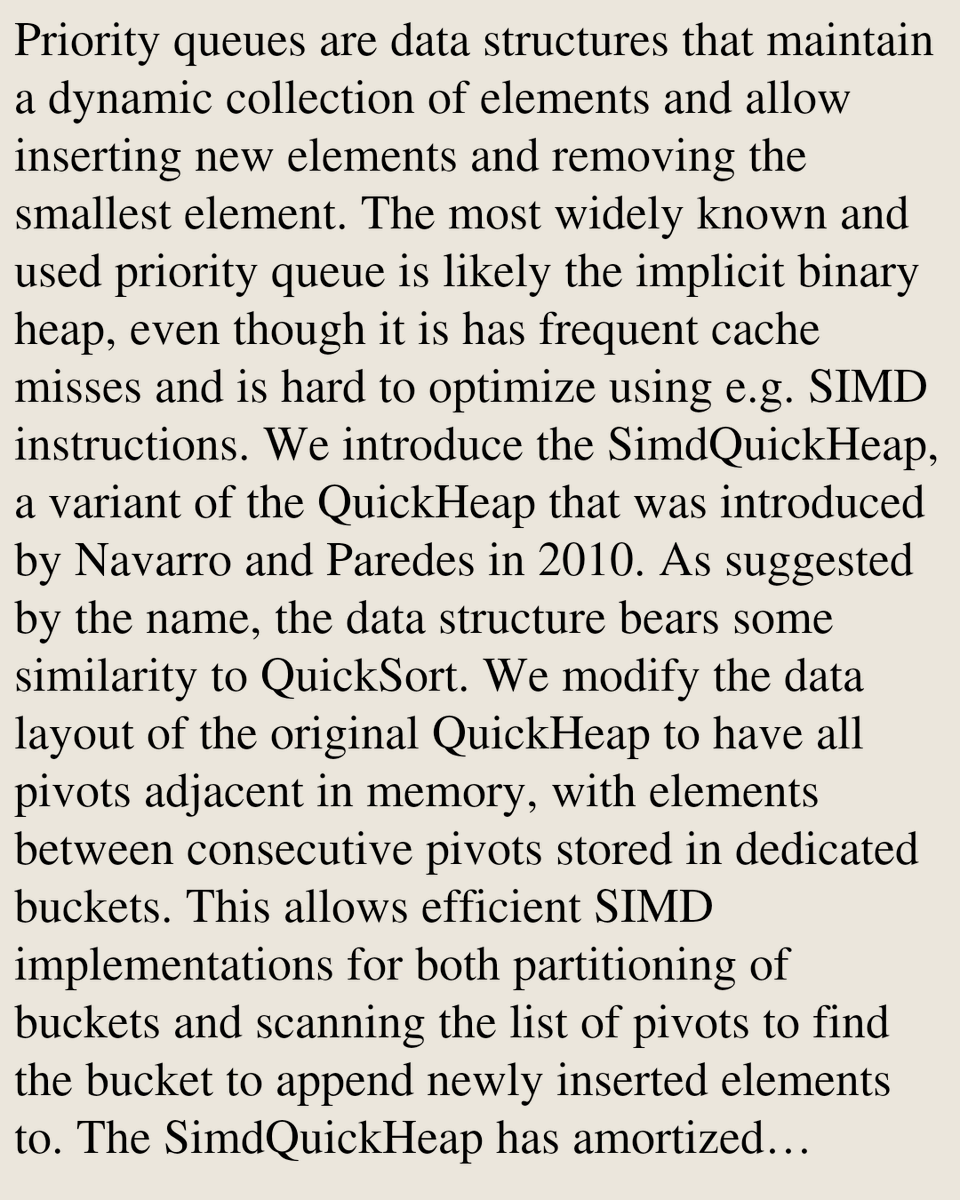
The SimdQuickHeap recursively partitions the data until the smallest element is found, and stores the pivots and buckets between them. @curious_coding will show how this is the fastest priority queue at our free @P99CONF on Oct. 21-22. https://t.co/oOae7JVuR6
#ScyllaDB#P99CONF
SIMD + Rust + pattern matching = Sassy, a small, sharp tool from @curious_coding et al., for fast sequence search. Proof that you don't need a giant framework to move the needle, sometimes you just need really well-written low-level code. 🔍🦀
https://t.co/J3kXTH9KEk
To all folks dealing with biological data:
do you ever need to check if your reads contain barcodes/adapters/primers/...? Or off-target matches?
Sassy is the tool to use! A super fast implementation of "approximate string matching" with a grep-like CLI.
https://t.co/WWdcuh82Fb
@jpelbers@heufd4 Rick made Barbell for demultiplexing+trimming. I'm not actually sure if it supports just trimming though.
It might make sense to add this to sassy directly.
The hard part is choosing all the thresholds usually (# errors; dist to end; overhang cost).
https://t.co/Hn8D8tIHX7
As said before, this is a super useful (and *fast*) tool, that we've already been using quite a bit for troubleshooting spurious primer matching and the like. Warmly recommended!
@heufd4 ❤️
Basically "fuzzy grep for fasta files": search fasta/fastq files for short DNA patterns to verify that they are present/absent in the data in the right places, and what kind of errors there are.
New preprint!
The SimdQuickHeap is the fastest priority queue, by far.
2x faster than a radix heap, and up to 10x faster than binary heaps.
Coauthored with Johannes Breitling and Marvin Williams.
As often: the SimdQuickHeap is a conceptually very simple data structure that thus can be easily optimized using SIMD, leading to pretty big speed gains.
New preprint!
The SimdQuickHeap is the fastest priority queue, by far.
2x faster than a radix heap, and up to 10x faster than binary heaps.
Coauthored with Johannes Breitling and Marvin Williams.
OMG! By popular demand (🤗) I'm going to speak at P99 again!
This time about the SimdQuickHeap preprint that just came out: the fastest priority queue by 2x (or 10x comparing to a binary heap).
We've been working hard behind the scenes to bring you an unforgettable P99CONF 2026. Registration is now open, so take a look at who is coming back and the new speakers we have on board > https://t.co/HMlcvQNjFs
#ScyllaDB#P99CONF