Cloudflare open-sourced the security audit skill that seeded its own vulnerability hunting harness. Your coding agent can now run it on your code.
How it works, in 6 phases:
→ maps your codebase
→ hunts for bugs area by area so nothing gets skipped
→ sends every finding to a fresh agent that didn't find it, to confirm it's real
→ writes structured results
→ verifies each record again, independently
→ writes the final report
You get a findings file split into confirmed, needs validation and rejected, so you fix the real problems first.
Install:
npx skills add https://t.co/ptOfJggqQB --skill security-audit
Then open your agent in your project and type: "security audit this codebase"
MIT licensed, 31.3K stars.
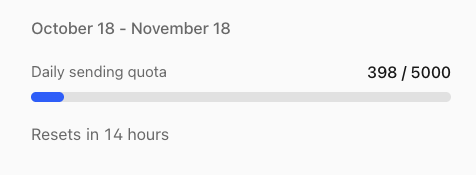
What makes matters worse is that Cloudflare’s billing dashboard doesn’t show each day’s total charges until the following day.
This means we can’t use it to spot problems in real time.
That’s why I created cf-medivh, an open-source project that estimates your current bill every ten minutes and quickly alerts you to unusual charges.
I hope this project can help others, too.
https://t.co/k49YXWiElI
Anybody that is considering using @Cloudflare D1 for simple database, don’t. It’s a total scam. I had 2x small databases on there for two little apps of mine, that only I use, so nothing public or heavily used. They sent me a bill for over $500 USD for reads and writes!!
this is insane, seriously
everyone is still trying to fix broken AI agents by tweaking prompts, but that's completely missing the point
here is how the agent machine actually works behind every single call:
prompt engineering (shapes the intent)
input -> parse -> schema -> valid
if your agent gets stuck repeating forever, fix the prompt
workflow engineering (routes the state)
state -> forks -> join -> next
if the state goes wrong midway through execution, fix the workflow
runtime engineering (governs the effect)
tool scope -> sandbox -> eval gate -> human gate
if the model leaks side-effects or unsafe actions, fix the runtime
the model proposes, but the system decides. stop fixing system architecture with prompt tweaks
XcodeBuildMCP v2.2.0 is out 🎉
And it's a big one! Lots of great quality of life improvements!
What's new:
- Code coverage tools: get_coverage_report and get_file_coverage for per-target and function-level coverage from test results.
- interactive setup wizard for creating project config.
- Custom workflows - define exactly which tools your agent sees.
- Unified build-and-run tool for physical devices.
- `init` command now generates AGENTS.md with workflow instructions.
- Swift Package and test result diagnostic fixes.
- CLI auto-fills arguments from session defaults and profiles.
Thanks to @irangareddy, doovers, czottmann, saschagordner, and Abdulrahmansoliman
https://t.co/xMn8k7e9Ft
MetalRT delivers the fastest TTS inference on Apple Silicon.
Key results on M3 Max:
- 291 ms latency for 5 words, 8.4x RTF, 2.8x faster than mlx
- Lowest latency recorded: 291 ms
- Peak RTF: 8.8x on longer inputs
This enables instant-feeling text-to-speech directly on device.
FASTEST voice AI pipeline on Apple silicon coming soon powered by @RunAnywhereAI
#AppleSilicon #TTS #MetalRT #OnDeviceAI #runanywhere
Wrote a cli to crawl Discord so I can get more signal out of where the pain points are. sqlite db is around 4GB, 660k messages. https://t.co/mteVgNr38U
As promised I've finally committed the Qwen3.5 MLX chat for iOS, iPadOS and MacOS (all the same). It's 100% vibe-coded but guided by experienced hands.
There's lots I'd like to do but I also have a real job 😎
Thank you @JustinLin610 and team, @Alibaba_Qwen, @Prince_Canuma & @awnihannun and team.
https://t.co/l48zvfHyDj
CloudFlare Workers might just be one of the most under-hyped products on the planet.
Seriously. If you haven't played around with it yet, cancel your weekend plans.
alibaba quietly dropped something kind of wild for developers
a $3/month coding plan that gives you access to multiple frontier models under one API key
• qwen3.5-plus
• glm-5
• kimi k2.5
• minimax m2.5
you can switch between them anytime
same key
same environment
different models depending on the task
so instead of committing to one AI model
you can route work to the one that performs best
coding
tool calls
agents
reasoning
and people are already wiring these into claude code style workflows
so your coding agent can dynamically swap models depending on what it needs to do
debugging → one model
planning → another
execution → another
multi-model AI dev stacks are starting to look very real
and the price point is honestly kind of insane
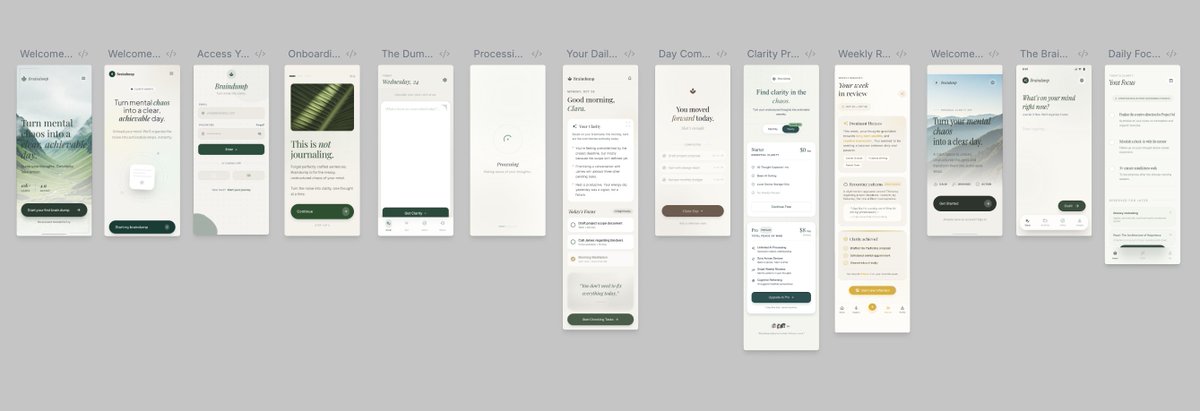
This design was made inside Google Stitch in under 5 minutes.
ONE prompt. That's it.
If you're skipping the design phase for your MVP because it's too slow or expensive, this is a much faster way.
Stop wasting weeks on Figma when you can ship clean designs in minutes.
Just shipped AgentGuard, a security framework that protects AI agents from prompt injection and command execution attacks.
Yesterday's Clinejection attack compromised 4,000 machines through a malicious GitHub issue that tricked an AI bot into running arbitrary commands. AgentGuard scans text input to AI agents and blocks these attacks by detecting malicious patterns like command injection (npm install, curl | bash), prompt injection (ignore previous instructions), and Unicode bypass tricks (Cyrillic homoglyphs, zero-width chars).
Installation options:
- OpenClaw skill: copy to ~/.openclaw/skills/agent-guard
- Claude MCP server: pip install + MCP config
- Python library: from agent_guard import AgentGuard
Tested against actual Clinejection payloads - detects as CRITICAL threats. All 10 unit tests pass. Production-ready AI agent security that would have saved 4,000 machines yesterday.
https://t.co/MpmoZHYT2T
gws (google workspace cli) conveniently includes:
> 50 common workflows for agents
> one command install as skills
> use with openclaw/ claude code/ codex
share this image with your agents to help them use any of the common workflows as recipe skills
BOOM!
New open source model!
We are testing this now at The Zero-Human Company!
Qwen3.5-27B-Claude-4.6-Opus-Reasoning-Distilled.
This Frankenstein of an AI model runs fast local consumer hardware!
More soon! https://t.co/qILhHgWVao
Just got this set up on my 2024 M3 MacBook Air with 24Gb of RAM. MLX build.
12Gb total memory footprint with 1-4 second response time for simple prompts. This memory footprint is insane! I didn’t expect any local model to even work half decent on this Mac. Well done @liquidai