Tested against 302 real shopper questions from store logs:
• Order & chip lookups: 0 ms (no model)
• 40-SKU shortlist: 133 ms
• Product-page fact check: 35/36 planted errors caught (~2¢ / 1k checks)
Full write-up & interactive trace:
https://t.co/sKof3GkmrC
Try it on the live website:
https://t.co/5mxu1uiZ3T
Put naive RAG on a 30k-SKU pharmacy store and it pitches niacinamide when you ask for “no niacinamide” or invents SPF a lotion doesn’t have.
So the LLM only speaks; small classifiers (@levantolabs Sage 2 + @typesafeai Jev) decide what’s true in 133 ms.
How it works ↓
@levantolabs@typesafeai Same grounding runs inside Ask Live (voice + rear camera on Hydrogen).
Interrupt mid-sentence, scan a bottle label, add to cart without hanging up, and switch between English and Saudi Arabic in 0 ms without dropping the call.
The System I Introduced
One rule holds the architecture together: language models speak and format, small classifiers decide.
Instead of sending every message through one heavy model, incoming questions from the search bar, product pages, Ask Live, and WhatsApp split by what kind of check they actually need.
Predictable questions never touch a model. ‘Where is my order?’ checks Shopify Admin and courier tracking (SMSA and Aramex) behind a phone code in 0 ms. Standard product-page chips (‘What does it do?’, ‘What’s in it?’) read from a cache keyed to a hash of that product’s verified facts instant until the underlying product data changes.
Full case study: https://t.co/D4QjpgH2qq
We replaced slow generative LLM routing across @avenzurworld with Levanto Sage 2.0 (@levantolabs ) — and the live production numbers speak for themselves ⚡
Here is how Sage 2.0 reacts to bilingual Arabic & English shopper inputs on the spot across 6 live storefront surfaces:
• 8.3ms – 13.9ms warm server latency on POST /decide/batch (0 output tokens)
• 140.5ms on POST /v1/extract to pull negated ingredients ("بدون سلفات وبارابين") and price caps straight out of natural Arabic queries
• 64.3ms to evaluate 20 product candidates in parallel in a single /decide/batch call (-84% tokens)
• 73.8ms – 79.5ms per chunk over wss://sage.levanto.ai/v1/stream — watching growing text in real time and escalating pregnancy + Rx dosing questions (12.1% → 98.1% → 99.95%) to a licensed pharmacist before a single unsafe token is generated
• Sub-100ms 1-sentence skincare stack conflict checks & autonomous ERP margin-floor pricing
Huge shoutout to the @levantolabs team for building a decision engine that actually runs at e-commerce storefront speed.
design teams have spent years trying to get people to actually read their design system documentation. agents can read them every single time they write code.
new article on design systems for agents:
https://t.co/MYvG4UyQSS
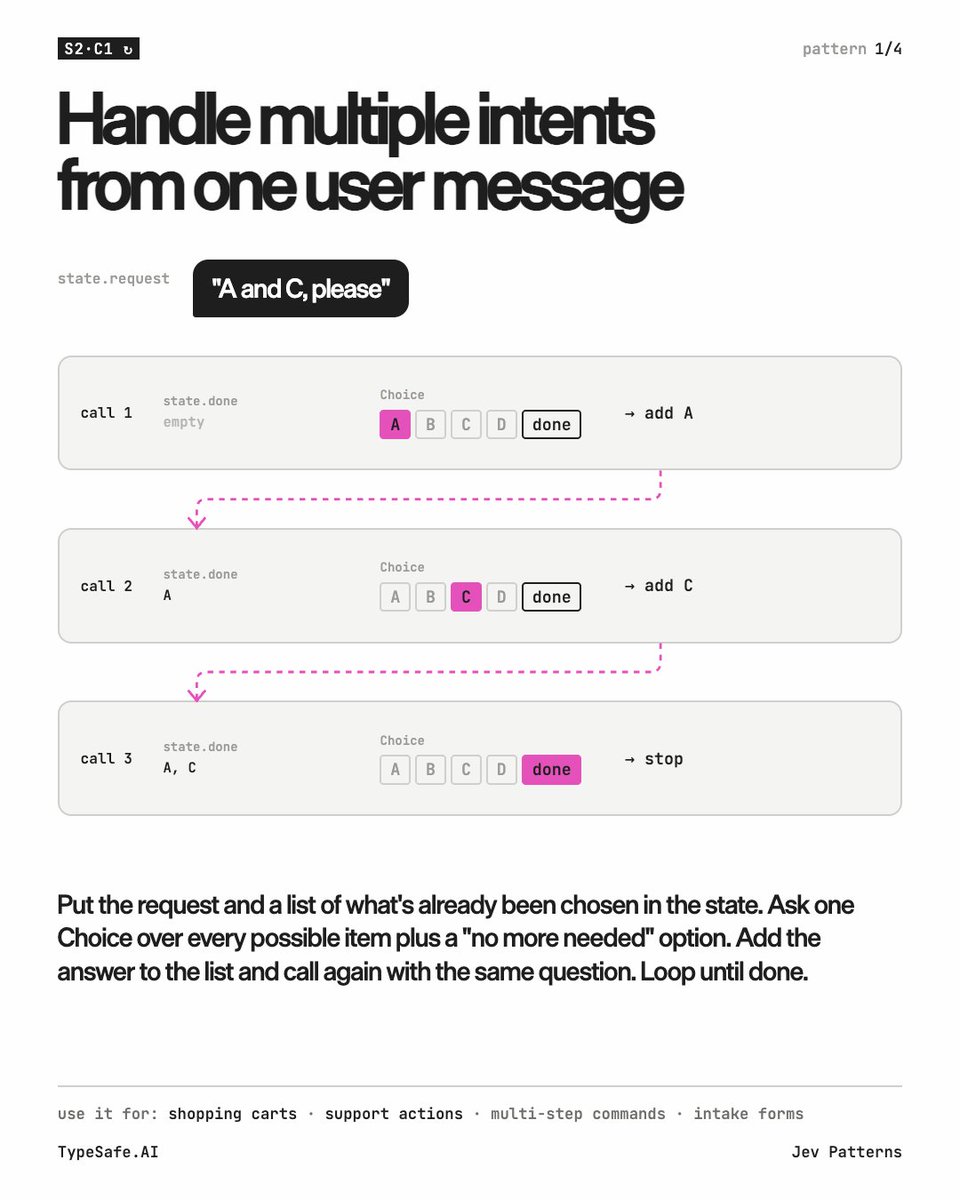
One thing that can be tricky to figure out is how to use Jev's primitives to handle more than one intent in a single user query.
My favorite way to approach this is what I call the "shopping cart" pattern: recursively pick the next thing until Jev says we're done.
I've personally used this to make a coffee ordering bot for our company Slack (using @DoorDash's CLI!), as well as a fast multi-intent handler for my smart home system.
Give it a shot!
I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!
Never trust an unverified scraper with your product catalog.
How our new Photo Harvester works:
Stage 1: Crawls allowlisted official brand domains
Jev gate: Compares candidate gallery images against the reference packshot via perceptual hash + CLIP (>= 0.80 for open web)
Pack-size guard: Filters out 30ml photos when the SKU is 50ml.
LLM searches. Jev decides.
(cmd-) f the world
indexing got you down?
can't find your keys?
f that. no really, f that
Jev's got your back
(demo replay for those who missed JevDay!)