An agent can propose a schedule. It shouldn't grade its own work.
Our scheduler lets the LLM find slots, but code validates placements and checks the full calendar.
Where do you draw the line between agent judgment and hard rules?
Read: https://t.co/xGON30gUb2
Updating a shared AI tool shouldn't mean redeploying unrelated agents.
In Microsoft Foundry, version the Toolbox separately and promote changes behind its stable endpoint.
Who owns shared tool releases on your team?
https://t.co/3pR3W7wsSS
Your AI agent's deployment config belongs with its code.
The GA Microsoft Foundry extension for azd keeps agent and resource definitions in azure.yaml for review and reuse across environments.
Where does config drift hit your team?
https://t.co/zakUzzTLSS
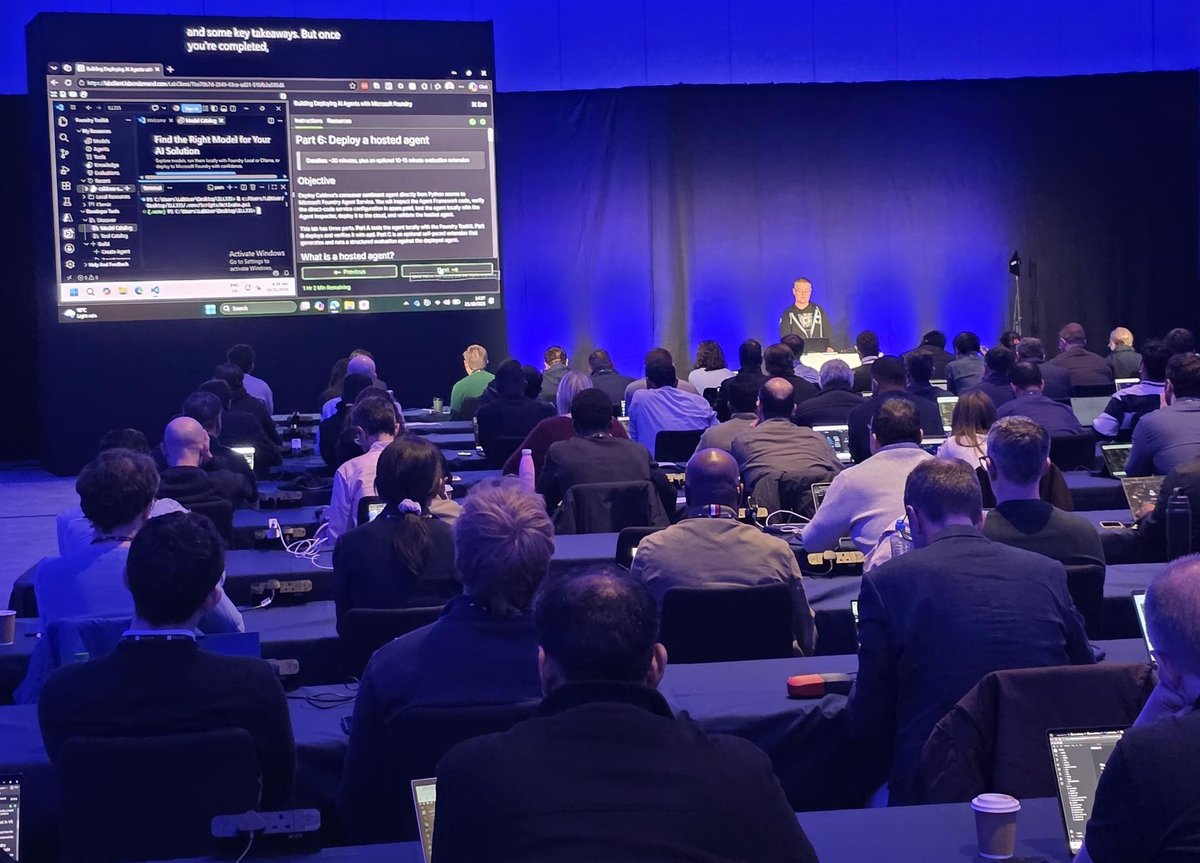
Seeing an AI agent work isn't the same as building one.
At @MicrosoftIgnite, we're running a hands-on challenge using Microsoft Foundry, VS Code and GitHub Copilot.
If you've built a simple agent, what would you want to try next?
Join us: https://t.co/e7tXdzeb2L #msignite
AI can read an invoice. That doesn't mean it's ready for approval.
In a Power Automate lab, rules checked POs, totals and duplicates before human review. Exceptions were held, not approved.
Which check would you refuse to skip?
https://t.co/9lu9cDVQjG
Two complaints can sound alike without involving the same water main.
Vector search finds resemblance, not proof. A knowledge graph defines relationships; Fabric Graph traverses them.
Where does your AI system verify the connection?
https://t.co/zwmDDTKa1b
Better prompts won't fix a poorly engineered AI workflow.
Meridian 24 checks actual execution records instead of trusting an agent's claim that it verified the news.
Where do you draw the line between agent autonomy and code?
https://t.co/DVenl0cbqN
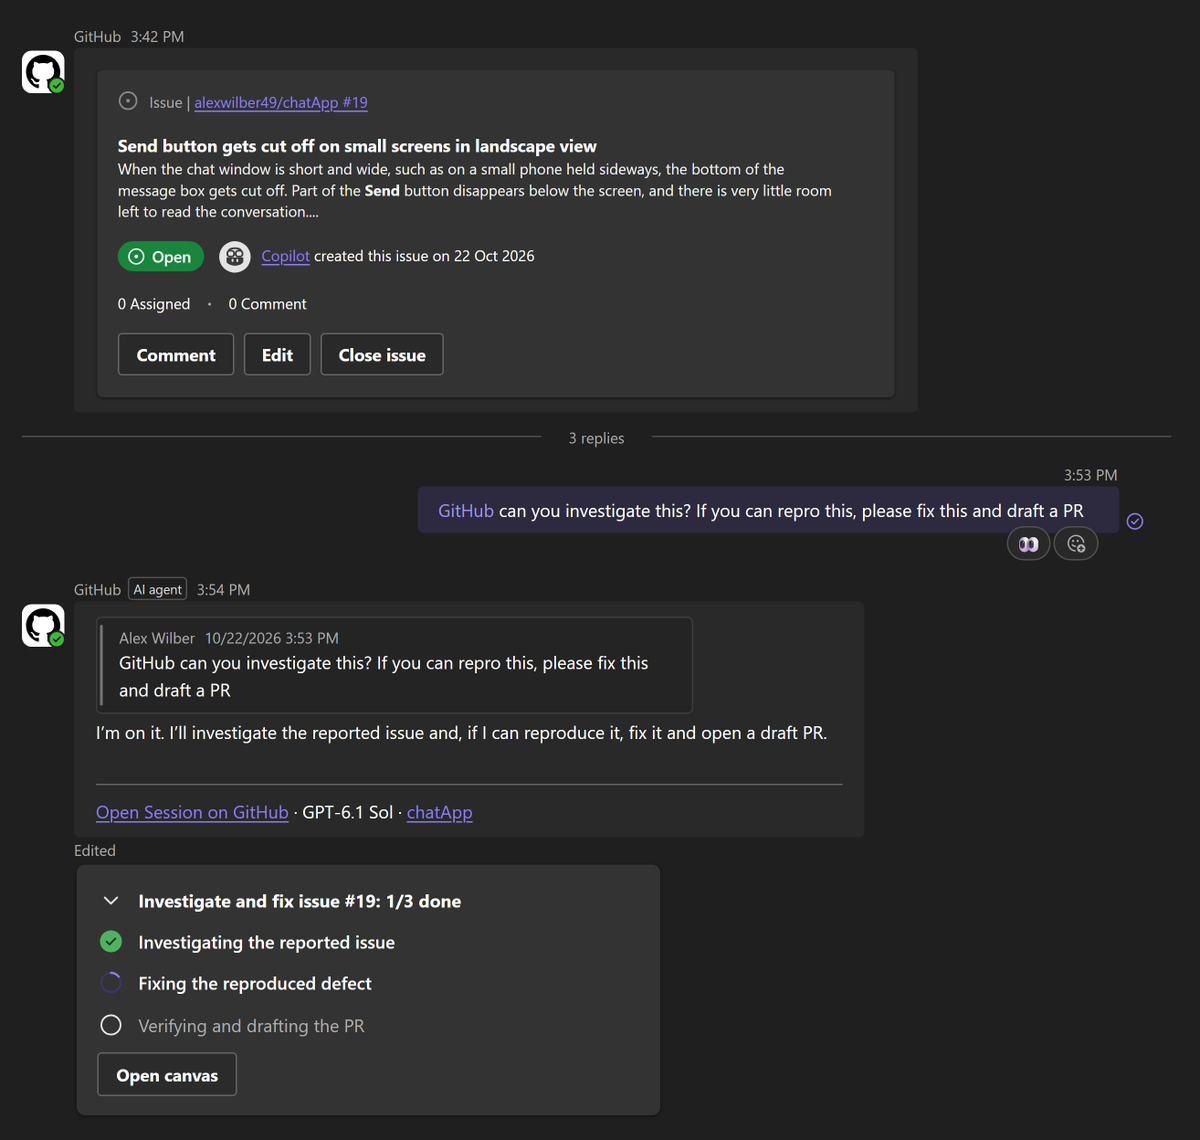
A pull request can start in a Teams chat.
Mention @GitHub on an issue, and Copilot can investigate, make changes, and draft a PR. The team can review the work beside the discussion.
Would you use this for bug triage or feature requests?
https://t.co/JKx3DLrsk8
A capable model isn't a complete agent. Someone still has to manage tools, context and execution.
Microsoft's Copilot harness in Foundry now manages that layer.
Would you own the agent loop or use a managed one?
https://t.co/5ZUUe1NrbE
GitHub's Copilot Fusion changes the choice: pick Standard, High, or Max effort, then let Fusion decide whether to use one model or several.
Would you rather control the model or the effort level?
https://t.co/sBkToQJkOv
The real output of software development is completed work, not code.
AI can increase code volume. That matters only if features, fixes, and security work ship.
What would teams measure differently if completed work became the default?
https://t.co/wyDpry8P0F
The agent stack is splitting by job.
GPT-6.1 Terra is built for high-volume visual and screen-based work. GPT-6 Astra handles open-ended planning.
If you build agents, compare Terra in Foundry: https://t.co/Fd8bxM2tj7
A fluent translation can still be a broken document.
Production taught us to catch missing lines and broken structure before chasing scores.
Meaning still needs human review. First, preserve the document.
What would you check first?
https://t.co/4OmBd6a2G5
Attending Microsoft Frontier Tour 2027?
Save this: https://t.co/rXdiZcDOvW
Get recordings, code, demos, slides, & lab materials created by @lee_stott and others so you can keep building after the session ends.
Bookmark the sessions you want to revisit.
#MicrosoftFrontierTour
Always choosing the strongest model is bad systems design.
Route once per turn. Pin through the tool chain. Filter by context and policy before scoring.
Optimize for reliable completion, not cheapest request.
What would you route first?
https://t.co/B8ldjvVHeD
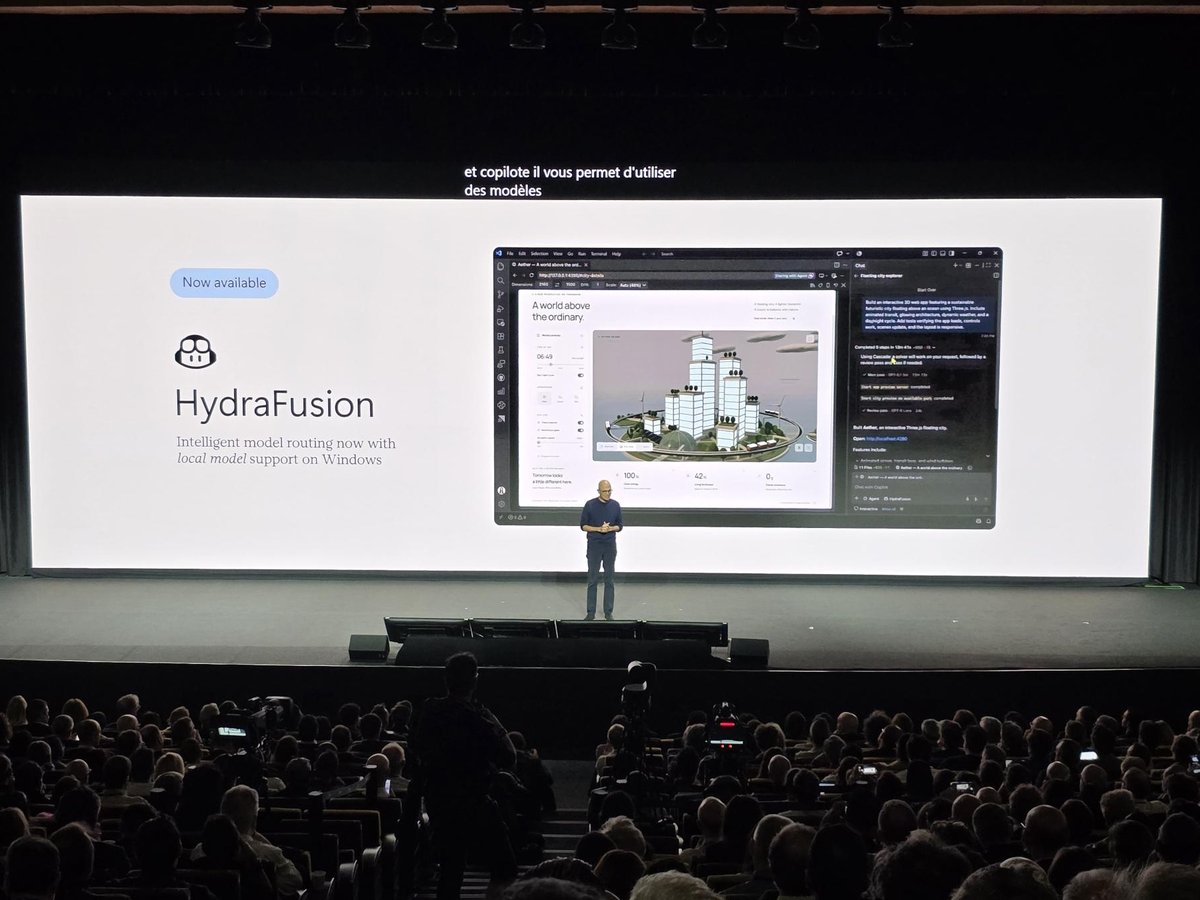
HydraFusion isn't another model. It orchestrates them.
For each prompt, Copilot can choose Single, Cascade, or Critique, then set reasoning effort per step.
Read the docs: https://t.co/zgfWJy6vee
Better reasoning does not fix stale evidence.
Web IQ ranks passages with provenance, giving agents current, citable context without feeding them whole pages.
Audit the evidence path before tuning the model.
https://t.co/RXbUrwtblp
#AIAgents#RAG
AI can speed up diagnosis. It cannot replace verification.
Treat the SRE agent's finding as a hypothesis not fact without verification.
What evidence do you verify first?
https://t.co/jUrfFAfE99
#SRE#DevOps
Copilot's biggest shift is not better chat.
It is moving from "What can I ask AI?" to "What work can I give AI?" Cowork, Code and Autopilot make delegation, building and persistent work part of the model.
Which matters most to your org?
https://t.co/4BiZglSz2Z
MCP governance does not stop at the admin console. It has to reach the gateway.
Agent 365 defines access decisions. Azure API Management enforces them when agents call MCP tools.
Where should MCP enforcement live in your stack?
https://t.co/FMlVFWgh0X