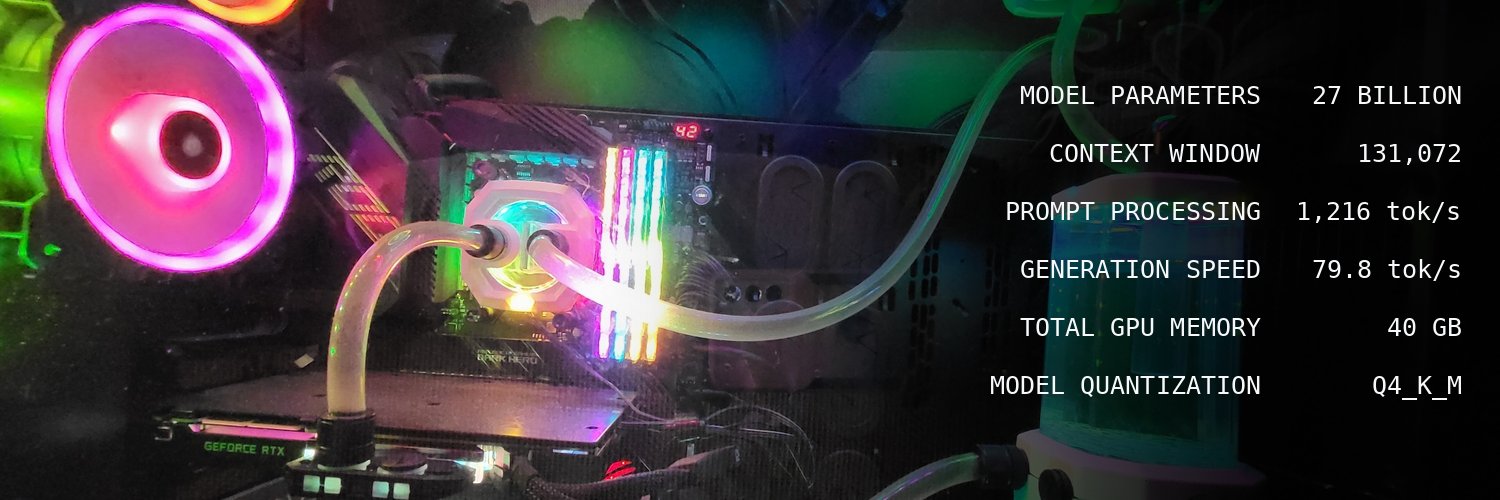
I run Qwen3.8-27B on one 3090. No cloud, no per-token bill. What I've measured on it so far:
74 tok/s stock, 157 with DFlash2
code 78-79 tok/s, prose 58-64
64k-token prompt: 63 s to the first word
13.5 W idle, about 340 W generating
same model won't fit on my 16GB 4060 Ti, split with system RAM it does 7 tok/s
I post every run. Starting local AI? Reply with your GPU and I'll tell you what to run first. Want help building yours: https://t.co/GsO7NzjsBm
@ngxson agree, reading the code is the whole job now. but on llama.cpp PRs do you actually reject ones where the author cant explain their own diff, or does passing CI still win?
@LTGraphicEssays@thinkymachines@unsloth ok 64gb max explains it. what counts as multi-hop for you though, like 3 chained calls or 10+? and are you feeding tool results back raw or trimmed, b/c at 32K raw json eats context fast
@Oluwaphilemon1 ngl the draft load is a one time cost, nobody restarts the server per prompt. prefill on long ctx is what kills TTFT on a mac. did 1.2.2 move TTFT at 32k or just cold start?
@LTGraphicEssays@thinkymachines@unsloth nice, 20 t/s on Q8 on an M1 is better than i expected tbh. which M1 is that, base or pro/max, and how much ram? and does it hold 20 at longer context or is that short prompts only
@termuxSolutions@liquidai ok thats a good twist. 70 tokens for a tool call is a lot though, is it padding w/ reasoning or just verbose args? if you force a json grammar in llama.cpp does the 1.7B still hold 95 or does accuracy drop w/ it
@Prince_Canuma@goldensurferx 50 is the real number tbh. dflash2 got me 2.13x on my 3090 but acceptance fell to 0.64 from 0.85 w/ mtp. whats dspark acceptance on image prompts, or is that 50 text only?
@RedFasterX@anomanus418476 massive like what though, you got an actual number from a split run? anomanus is guessing the hit stays small. if looping blows that up id want to see it
@muradylan Q3_K_M imo, closest thing to the mlx 3-bit you ran. keep -fa on and the same 16K ctx, and post peak mem for the gguf too b/c on 24GB id want to know its not swapping before blaming the runtime
@filpizlo honestly a recompile beats rewriting ghostscript in rust any day. but whats the slowdown on a big pdf render vs the stock gcc build? thats what decides if distros ship it
@geerlingguy@eevblog Agree, but the house of cards is the cloud side imo. My 3090 doesnt care what NVDA does. If it pops, do used 3090 prices crash or spike when everyone goes local?
@vishalsingh2972 ah ok 16GB vram, way better than I assumed. a 20GB model still cant fully fit in 16 though, so some layers have to be spilling to cpu right? what tok/s you actually getting w/ that split
@termuxSolutions ok get_weather on a url is pretty damning lol, I'll give you that one. 0/2 is a tiny sample though. was fetch_url sitting low in the list at 40? id move it to slot 1 and rerun just those 2 prompts before calling it all size
Every MCP tool you hand your agent gets paid for in prompt tokens before the model even reads your question.
Measured on my 3090 just now, Qwen3.8-27B Q4_K_M in llama.cpp, prompt cache off, same one line question each time:
0 tools: 21 tokens, 0.17 s prefill
10 tools: 1,081 tokens, 1.1 s
20 tools: 1,960 tokens, 1.7 s
40 tools: 3,718 tokens, 3.0 s
Thats ~87 tokens per tool plus a couple hundred for the tool instructions the chat template adds. Test tools were 10 normal file/git/web schemas I wrote, copied up to 40.
Prompt cache hides it on repeat turns, but everytime the prefix changes you pay it again, and on an 8k context setup 40 tools eats almost half the window.
imo load the 5-10 tools the task needs, not your whole MCP collection
@sjgoedecke agree but reading never built the intuition for me. running models on my own box did, fast. how far do you go, do you actually run the weights locally or stop at the API?
@rmoriz honestly just pick one long task you already did and rerun it on both. note the point where it starts repeating itself or forgets a file it already edited, and check if the CLI shows tokens used so you know how deep it was when it broke. a few runs is plenty to see a pattern
@sampullara plus tags are too weak for this imo, anyone can email you+agent and the agent cant tell who sent it. would you trust it to act on mail there w/o some signed header from you?
@LTGraphicEssays@thinkymachines@unsloth the mac people are prob on a diffrent upload then. which exact repo and file are you pulling, and does the model card actually say nvfp4 for the looped layers or are you going off the 0.4 t/s? b/c a plain cpu fallback would look the same
@vishalsingh2972 how does a 20GB model fit on a 16GB laptop though? feels like itd be swapping hard the whole time. what tok/s are you actually seeing on 16GB
@termuxSolutions ok 14/20 from a 0.5B at 10 tools is more than id have bet on tbh. the URL-as-file thing smells like the tool descriptions though. are read_file and http_request worded close enough that a tiny model cant tell them apart? id rename one before blaming the size
@tenignull opportunity cost vs what though, a frontier api? for anything private or long overnight runs local still wins for me. what would a small model have to do before youd actually use it daily