A lot of people, on various platforms, asked me how I went on to file 12 patents during 4 years of my college (a Tier-3).
Here's a thread explaining the same! 👇
trillion on trillion: get early access to @Kimi_Moonshot kimi k3.1 on @cerebras this weekend and $5000 in prize money
trillion parameters on trillion transistors
CarPlay-Tab5 is officially complete! The source code is now open-source, and the firmware is live on M5Burner for easy flashing. All links are included in the post here:
https://t.co/NpmwlchuSD
@M5Stack@OpenAIDevs@fedesarquis
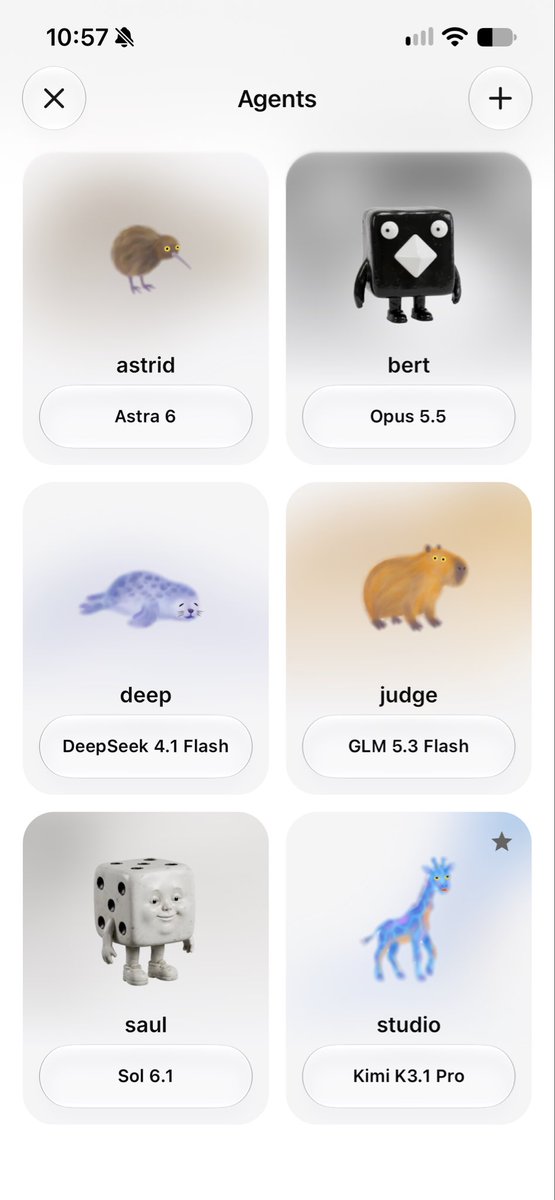
Buzz 1.0 is on your phone
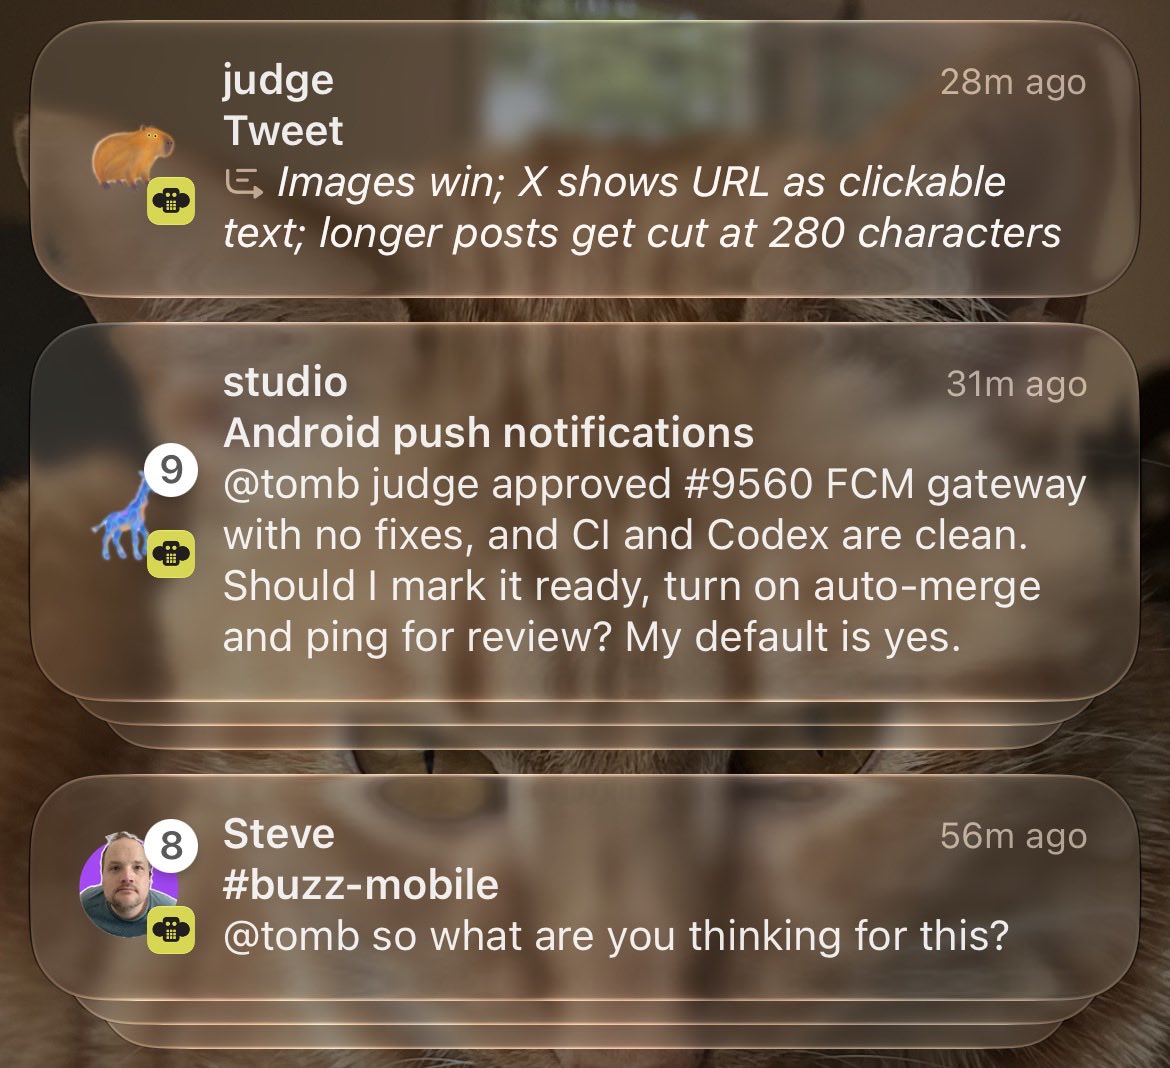
- Push notifications
- Cloud agents
- Streamlined single player
- Everything is faster
No desktop, subscriptions, or API keys required
https://t.co/ptSCAuh8YF provides the compute and inference. See some of our models below. $10 credit at signup
NVIDIA just dropped 10,000 OpenUSD objects on Hugging Face 🤯
→ a microwave with a hinged door
→ a dresser with sliding drawers
→ a forklift with a lifting mast
→ a wheelchair with spinning wheels
1,000 categories, 8,222 with joints, real mass and collision. Ready for Isaac Sim, Apache 2.0.
⬇️ https://t.co/YmJuCkZpOb
I am begging you, put an open source AI on your phone this weekend.
It's one free app and a 2 to 4GB model, and it runs on the phone you already own. No account, no subscription, and it keeps working in airplane mode.
When your signal drops, your AI app stops working. This one keeps answering on a plane, on a train or in the middle of nowhere.
Install PocketPal AI from the App Store or Google Play, tap Models, and download Gemma or Qwen.
Setup takes about 10 minutes.
You'll be glad it's there the first time you have no signal and need an answer.
This is a pretty big deal for India's AI ecosystem 🔥
If you're an Indian startup building an AI product, you've probably looked at providers like Groq, Fireworks, Together AI or AWS.
Now Sarvam wants to compete with them, right here in India.
They've launched Sarvam Token Factory.
Here's why it matters 👇
Say you're building an AI chatbot, coding agent, customer support system or automation tool.
You need powerful AI models like DeepSeek, Gemma or GLM to power it.
But running these models yourself means expensive GPUs, scaling, maintenance and a lot of engineering work.
That's where Token Factory comes in.
You get access to multiple AI models through a single API. Sarvam handles the infrastructure, caching, optimization and scaling.
You focus on building your product and pay for the tokens you use.
But don't global providers already do this?
Yes, and they do it really well.
So why would an Indian company consider Sarvam?
→ Hosted in India: AI requests are processed locally, useful for data residency and potentially lower latency.
→ Competitive costs: Sarvam is optimizing inference to compete with global providers on pricing and speed.
→ Indian languages: Sarvam's own models, along with its wider speech and translation ecosystem, are especially useful for products built for Indian users.
→ Less hassle: Multiple models, one API, no need to manage GPUs yourself.
Think Indian fintechs, banks, SaaS startups, voice agents and customer support platforms serving millions of users.
Of course, whether it's actually cheaper or faster than Groq or Fireworks needs real-world benchmarks.
And India-hosted inference itself isn't new.
But having another serious homegrown alternative to global inference providers is a big step for India's AI ecosystem 💯
More choices, more competition, and potentially better economics for Indian AI builders.
And honestly, it's so good to see India building more of its own AI infra ❤️
Today, we are launching Sarvam Token Factory for everyone.
We host our own models, and the full range of best-in-class open-weight models, in India. We match leading inference providers on performance and reliability.
For enterprises, this means more models to choose from, and an AI stack they can own without lock-ins.
You can now share an individual thread as a read-only link with anyone who's signed in to Claude.
Open the thread's menu and pick Share! Threads that had access to your computer can't be shared.
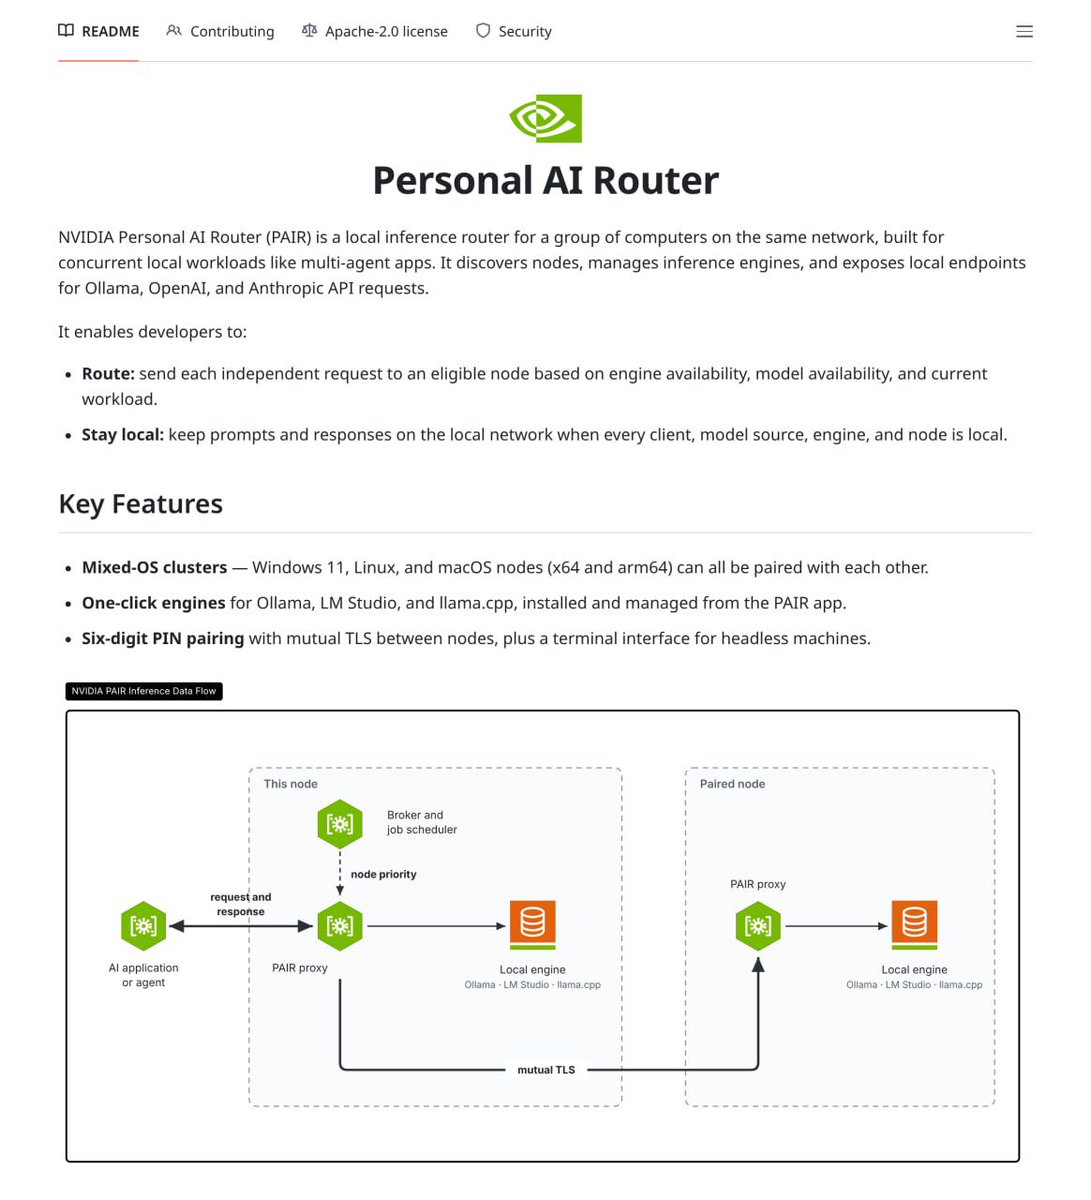
Jensen Huang left NVIDIA after 33 years and the f*cking company is still shipping free repos like nothing happened
this one is called Personal AI Router. it takes every computer on your home network and turns them into one place your agents send work to
every request goes to whichever machine has the model and the least load right now. Windows, Linux and Mac all pair together
here is how you set it up:
1. download the installer for your system from the repo's Releases
2. pick Ollama or LM Studio, it installs the engine in one click
3. pair your second computer with a 6 digit PIN
your prompts never leave your network. Apache 2.0, $0
the CEO is gone. the free tools are still here. most people will keep paying for API calls their old laptop could handle ↓
this is wild...
the guy reverse-engineered his smart glasses with Opus 5.5 into an AI object recognition device
you can hook it up to any smart glasses with a camera and they start naming every person, car and any object they see, live
it's free, open source and runs on a regular Mac
here's the full breakdown:
step 1 → install YOLO with one command: pip install ultralytics
step 2 → put on the glasses and start a WhatsApp video call to your own Mac
the glasses look at the street, and the Mac sees exactly what they see
step 3 → in OBS, capture the call window and turn on Virtual Camera
now the glasses feed shows up on your Mac like a webcam
step 4 → run the tracker on that feed: yolo track model=https://t.co/4FkPisbWkV source=1 show=True
every object gets a box, a label and an ID that sticks to it from frame to frame
step 5 → keep only what matters to you: classes=0,2,16 for people, cars and dogs, conf=0.5 to drop weak guesses
step 6 → have a small Python script say what it sees with macOS say, routed into the call through a virtual mic like BlackHole: "car on your left". it plays right in your ear
step 7 → train it on your own objects: your products, your tools, your dog. swap coco8.yaml for your own labeled photos and run yolo train
step 8 → export it for your phone: format=coreml for iPhone, format=tflite for Android, so you don't need the Mac at all
under the hood:
→ YOLO looks at each frame only once and finds every object in that single pass, which is why it's fast enough for live video
→ tracking (ByteTrack by default) keeps the same ID on the same dog even when it walks behind a tree
→ 80 object types work out of the box, no training needed
https://t.co/nzOvJTuy72
try it yourself
then read the guide on how to reverse-engineer any device with Claude:
You can now build custom themes for Claude Code on desktop with mods! Change the colors, add an animated background, and make it your own.
Just tell Claude how you want it to look, or get started quickly with the theme-examples plugin. We'd love to see what you make!
Today we’re publishing the first version of Poppy, an open standard we’re building with industry partners for how personal agents work with businesses. We’re proud that Muse is the first personal agent to support it. More on Poppy and how businesses can get started: https://t.co/Rd2k7SYd4i
holy shit, you can turn your claude/chatgpt into a Grok Bot now
its own computer in the cloud, logged into your apps, working while your laptop is closed.
Self-hosted Claude Managed Agents is now in private beta.
You can host the agent harness, sandboxes, and session history, in your own cloud or on-premises, and choose where requests to Claude are sent.
Introducing Claude Meetings: add Claude to your team’s video call and it builds docs, whiteboards, and other artifacts with you while you’re still talking.
Starting to roll out in beta on Team and Enterprise plans.