@reprise_99 If building from scratch. I'd start with rules detecting weaknesses introduced by IT teams and users in general—configuration changes, access misuse, policy violations—This may help baseline normal behavior, understand the environment, and fine-tune detection rules.
@nas_bench it can still be legitimate in that specific environment. That’s when you face the challenge of tuning — and if you don’t tune it properly, you’ll end up with a flood of false positives.
Like you said, finding the right balance is key, but it’s far from easy.
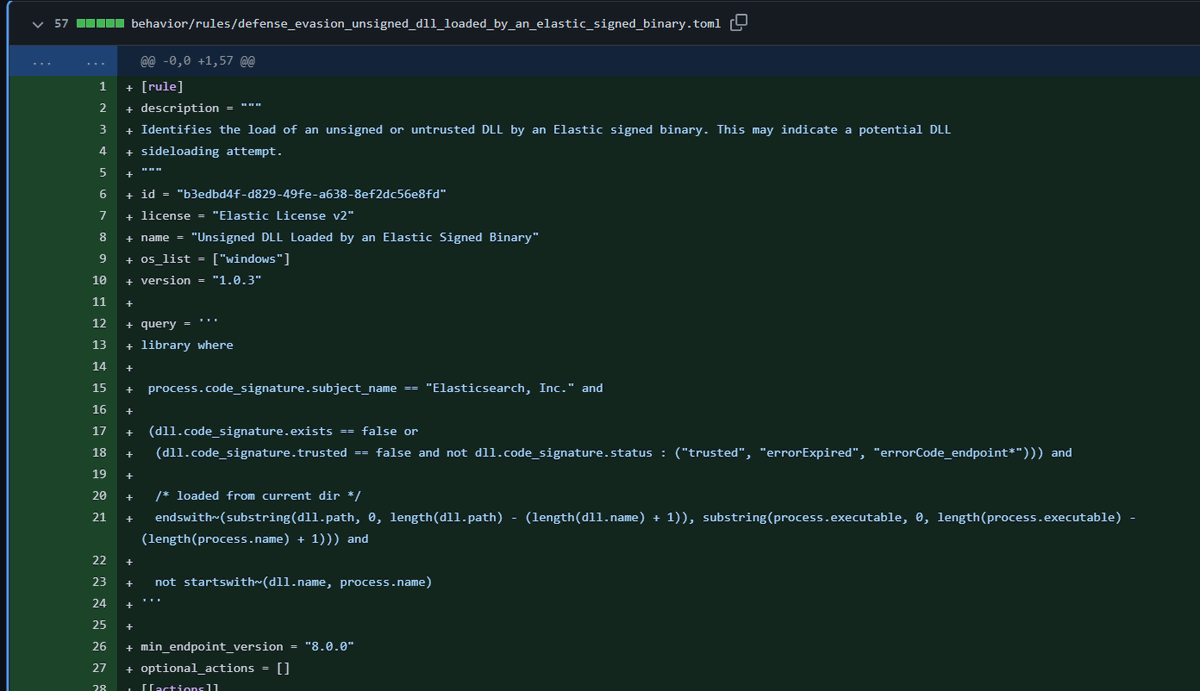
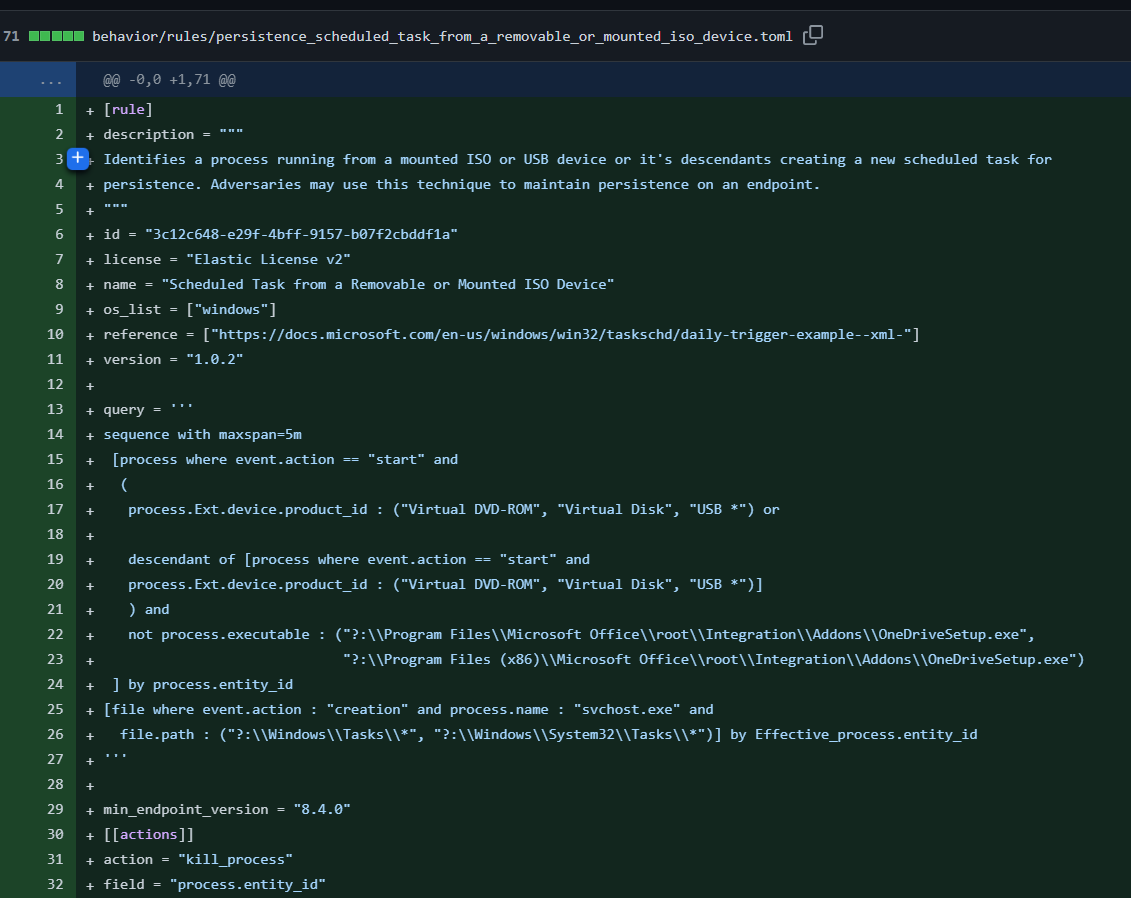
@nas_bench Great article! Sometimes I think tuning detection rules is even more challenging than building them. When building rules, you can emulate attacks or identify behaviors you assume are malicious. But in reality, even if a detection is a true positive and not a false positive,
@ChikwadoCy@0x534c This rule is not well implemented; it’s likely to generate a lot of false positives. You can check this article https://t.co/rJRWOeJ7l9—it might help you, as it contains good detection rules and highlights the false positives to consider.
Coming up on my 1 year anniversary with @HuntressLabs !
Taking this opportunity to go over some things myself and the team have seen in intrusions and drop some tips on basic things you can do to make your network more immune to compromise.
Let's start with initial access
- We see so much VPN compromise, it's by far our number 1 initial access vector - yes 0days for VPN appliance are there, but most of the time the compromise is a result of good ol' fashion credential stuffing or brute force.
- Some VPN appliances have decent log retention, others do not and it really sucks when only ~1 hour worth of logs are available - if you're standing up a SIEM or any kind of log collection effort in your org, make sure that devices which are externally exposed are sending their telemetry to the SIEM. If your VPN appliance has different logging settings, check them out and enable as needed - this telemetry is gold during intrusions.
- In addition to VPN appliances, we see a lot of RDP / RDS machines get compromised - same story here, no fancy 0days, just weak credentials in use. In some cases, MFA is in use, but has either been bypassed for the compromised user or has "failed open" - if you use RDP for your org, make sure that MFA is enabled somehow on it, if it is enabled, test to see what happens when the process that handles MFA crashes or is turned off. Also, make sure you have good procedures in place for turning MFA bypasses back off when they're applied.
- Remember to keep an eye on your web applications, deserialization attacks aren't super common, but happen fairly often. Turn on IIS logging and enable POST request logging if possible. Remember that a standard penetration test often does not deep dive into custom web applications, invest in a good Appsec focused test if you have a custom application exposed externally.
Turning to lateral movement
- Once inside networks, threat actors move very quickly and unfortunately do not run into a lot of resistance. We typically see multiple accounts compromised in rapid succession, suggesting weak or shared passwords in use. You have no idea how happy it makes me to see "LOGON_TYPE_NOT_GRANTED" in the logs - Yes I know segmenting your network is probably a pain, but its a very effective security control.
- In most cases we see, RDP is used for lateral movement and unfortunately, there is often no controls to prevent users from RDP'ing into servers they have no business need to RDP into. Check your Active Directory permissions and see what users can RDP into your file servers and domain controllers, you might be very surprised by what you find!
- Impacket & impacket-related tooling is very popular for lateral movement, if you are in charge of defending a network and have telemetry and a lab environment, try to use WMIExec etc for yourself and compare the telemetry you see versus normal activity, this is a great way to build high-fidelity alerts. Aside from that, remove local admin where possible. Local admin rights enable credential access and lateral movement avenues that would be shut right down were a non-admin account in use.
Looking at Execution / Impact
- Do threat actors use fancy 0days ? Yes of course, but in the cases we work, we rarely see it. Most of the time, "just enough tradecraft" is employed, all a TA needs is FileZilla and 7Zip to ruin your day.
- Tunneling tools like ngrok and plink are very popular, most often, these tools are being used to make RDP externally available to the TA - everyone loves a GUI I guess.
How do adversaries get credentials ?
- Registry credential dumping is extremely popular, same with LSASS credential dumping. Threat actors will also search local file systems and network shares for credentials and - guaranteed - will find them. By segmenting your network, limiting local admin access and hardening authentication silos within your AD environment ( things like a three-tiered admin model, or as close to it as you can get ) will limit the impact of credential theft drastically.
- Brute forcing is old and boring I get it, but unfortunately it works, especially for less-monitored environments, some cases we've seen hundreds of thousands brute force attempts for hours before an account is successfully compromised. Don't sleep on brute forcing, ensure you have account lock out policies in place and some kind of monitoring for brute force attacks.
Miscellaneous tidbits
- Please, please, please - change your default Windows log sizes via GPO. By default, these log channels do not hold a lot of data, if a threat actor undertakes a brute force in the environment, security-relevant telemetry will be clobbered hampering any investigation efforts.
- Have a standard naming convention for your organizations' workstations and servers, this makes it so much easier to orientate everything during an investigation and very often bubbles up malicious activity for workstations that don't fit the standard naming convention.
- Have a plan in place in case of an incident, it's bound to happen and it's better to be prepared. What happens if certain hosts need to be offline, who do you call to get a potential insurance claim started? What is the threshold for a formal IR engagement - deciding all these things under pressure from an incident is not ideal.
I think this post is long enough 😅 so I'll wrap it up 💙
@JonnyJohnson_ Great work! This might be a naive question, but in terms of performance impact on the target machine (the one we're collecting events from), is it comparable to enabling ETW providers manually and locally?
Introducing 🚀Eventlog Compendium 🚀
A new Streamlit app, that aims to be the go-to resource for understanding and playing with Windows Event Logs.
Explore it 👉 https://t.co/M8bHXpg8aL
Includes the following utilities and docs
⚙️ Build your own Advanced Audit Policy based on different data points making your policy data driven.
🧭EventID to Audit Policy mapping as well MITRE ATT&CK to Event ID explorer
📊Leveraging the EVTX-ETW-Resources project, you can explore the different ETW providers by build, version and filter down on key message strings.
📄 EVTX Baseline Search & Match - Explore the evtx-baseline project in a visual way. Where you can paste logs and check if they match in real time
🧮Event Field Decoder - Decode common Windows Security Event fields such as Logon Types, Access Masks, Active Directory GUIDs and SIDs
🔒Built-in SACL Explorer - leveraging SACL Scanner from Alexander DeMine, you can explore the built-in SACLs on a windows system.
And much more to come. Stay tuned
I just published Practical Threat Hunting: A Walkthrough of the Temple Lab on SecDojo Platform.
Step-by-step guide to investigating a cyber attack in a Windows environment using the Temple threat hunting lab on SecDojo.
https://t.co/KmX0nzwnVF
🚨 Detect C2 Beacons!
New Microsoft Defender for Endpoint telemetry provides new opportunities for threat detection!
🔗
https://t.co/L5TM7BWIc6
#ThreatHunting#DetectionEngineering#MDE
@AndreGironda@Cyb3rMonk@anton_chuvakin agree with your point,but Spark can still be useful with UDFs to enhance detection. My point isnt to dispute what you said but when clients prefer a specific SIEM with limited capabilities and no correlation,Spark help create effective detection can be hard with built-in features
@Cyb3rMonk@anton_chuvakin Haha, I'm not sure if you're being serious or just joking. But PySpark is great when you don't have a powerful language built into your SIEM. I get to use PySpark SQL to do the same thing you did with KQL for emulating Beacon detection using RITA.
Detecting IPv6 DNS Takeover!
I just dropped my first short blog on Medium about the detection of IPv6 DNS Takeover attack. The blog provides an easy method to detect this attack using Windows event logs.
Check it out 😄 and let me know your feedback! 💬
https://t.co/2FUn6Gts9O
Detection Baselines are like teenage sex: everyone talks about it, nobody really knows how to do it, everyone thinks everyone else is doing it, so everyone claims they are doing it — Me
Enjoy the read! #DetectionEngineering
https://t.co/PRc6tMS6Xx
@MaxRogers5 I think the concept of notable events in Rapid7 SIEM can also be useful. These valuable alerts, even with low confidence, can provide additional context to other alerts.
https://t.co/Gld51Q1eL8.
Because I talked recently about my "Seven Sins," here is another classic: An external entity informed our customer that their network was compromised (and also delivered evidence that the attackers might still be inside the network).
In the initial call, we asked if the customer observed malicious behavior and or received critical AV alerts. The answer was no... until we checked the AV logs for ourselves.
Yes - multiple Cobalt Strike detections! On multiple (critical) endpoints, among other offensive tooling.
Which brings me to Sin #3: Ignoring or misinterpreting AV alerts [1]
All I wrote in that thread is still relevant - plus, I would argue that "cleaned", "contained", or "quarantined" must be taken with a grain of salt. In many cases, the AV could not remediate the threat fully, resulting in the malicious code still running on the infected machine despite the AV reporting that the threat could be eliminated.
Because AV logs are such a goldmine, I always start with these logs in a new Incident Response case. We find compromised users, staging directories, tools (with hashes) etc. This information is not only helpful post-morten, but you should proactively use it to detect a threat in your environment.
Good luck ☘️
[1] https://t.co/AsM4CUrtu7