i think for certain classes of software the answer is obviously yes, but I think it also ignores human nature. If you start to cognitively offload/surrender to LLMs, what is the trajectory of considering someone “capable” over a codebase.
It’s anecdotal… for now… but I work with many people with 20-30+ yoe. Their understanding of the codebase and changes to the codebase are dropping precipitously, despite them claiming otherwise.
And to your other point, there’s no anthropomorphism going on in my example, my point is very specifically that choosing open source software to emulate is not impressive, just like I’m not impressed when the 20th chromium fork browser comes out.
To be more precise, there are many completely distinct AAA game engines out there, I want to see how an LLM would do at creating its own unique engine.
Also, maybe you’re missing the point of the parent post, which is to answer how “intelligent” these models are today.
Surely an intelligent and capable human could guide an LLM function by function to make a cohesive complex piece of software of that magnitude. The question is: how capable is the LLM at prompting itself to acceptable results.
To be clear, it’s my belief that LLM output tends to be retarded often enough that it’s impossible to not meticulously guide them and check their work, no idea where you fall on that spectrum
I think the point is more like, why would it be super impressive if the “really good at copying things” machine, goes through an open source repo file by file and approximately copies what it sees?
If you could guarantee and prevent an LLM from cheating, and it ended up making something better than chrome on its own, that would be such a giant leap in capability that I’m still unconvinced we’re going to get there anytime soon
Also, the way google got away with scraping your website and creating thumbnails of all your images to serve on their own site was because they argued that the whole point was that it wasn’t a market replacement for your site and they are generating clicks and traffic for you.
Now they scrape and show an AI summary of your website and don’t direct anyone to your site.
The old laws in place are still massively favorable to the AI companies, and they still manage to break laws and get sued for billions of dollars.
@jonnywallace@theo I work on a codebase that is 12 million lines long, and the LLMs absolutely hallucinate and get things wrong lol
It's easy to believe the LLM about understanding the codebase, because even if it's wrong you have no fucking clue either.
A massive amount of things, making small bespoke tools, testing things, prototyping, implementing things per your own specification (some people are slow at typing and for some reason can't translate their thoughts and ideas to code very well), research, verification, tons of the tedium and minutiae that are completely orthogonal to solving complex engineering problems (like figuring out some flags for some random tool that is expeditious to use), simple/low complexity apps/websites/tools can be one shot in general (which is still a very useful thing), making visualizations, things that are can't be done with IDE find and replace refactors, the ability to undo a lot of work and more quickly build up in an orthogonal direction (which could have previously been too tedious).
In general, there have always been a million little nice-to-have things that never needed to be of pristine quality that you would have never done, or had the time to do in tandem with your projects... now you can.
What people ignore are the massive amount of downsides to using AI on projects, losing grasp on details and understanding means you perpetually slide into the reality which is illusion of ownership, where you don't actually understand the thing you're working on, you become the equivalent of an intern who has some vague idea about how things actually work and all actual ownership and work must be deferred to the LLM because you've lost the plot. This would be fine if the LLMs were trustworthy and had a track record of successfully producing high quality complex software on their own, but it's just not the case.
People will claim that the above is not true (both cases) but if you ask the average programmer in a heavily LLM'd codebase to implement something, or to bug-fix, or to explain parts of a codebase without LLM assistance, it becomes painfully obvious how superficial and illusory their grasp of the product is.
There are, of course, exceptions to this, and these are the experts that I mentioned who meticulously guide and double-check everything the LLM does, but this is the super minority, almost everyone in practice in full prompt-and-pray mode.
> The AI models surpassed the average programmer a few months ago. On the present trajectory, there is not very much time left until they surpass you.
The average programmer was the equivalent of an 800 Elo chess player, struggling to work on the most basic of CRUD apps despite doing the same things over and over for decades.
We were in an extremely supply constrained environment where it was considered "impressive" to make any kind of interface wrapping a database, enough so that people were getting paid north of $350,000 a year to do a very mediocre job of doing even that.
Most of those patterns are very repetitive, and I remain unconvinced that LLMs are capable of making a single piece of complex software without an expert meticulously guiding, fixing, and course correcting them.
Note, I don't think LLMs are useless or anything, I just don't think that "trajectory" of solving complex software is proven out, whether it's Fable 5.2 or any other frontier model, they make retarded mistakes ALL the time, and bad architectural decisions ALL the time.
@novaartist_@arifinity_@sixoleau I would have believed you if you didn’t just keep saying you would make a video instead of spending this many hours stalling. It shouldn’t take more than a few minutes
welcome to my hyper-v escape tutorial, please like, comment and subscribe!
(s/o to @bet3rd for editing this 41 minute clip and @calif_io for the shigure ui inspo. yes its been shipped to MSRC and no, i won't tell you how to do it)
xoxo
@parisGPK Don’t know why this showed up on my feed but both of you need to learn the difference between “apart” and “a part” because you’re using it completely backwards
It’s just a game, that’s why someone saying “pick another character for sure” shouldn’t result in her crying and having a meltdown like a 6 year old.
On the other hand, I actually feel more empathy for her teammates, it’s probably really annoying to be locked in a game with someone for 20 minutes+ being forced to waste your own time with someone who doesn’t care about contributing as a teammate in a team game
Even UEFN is an insufficient subset of what UE provides... You can do a bit of scene graph, but it doesn't even feel worth trying.
I still think the current best dev experience with UE5 is just to use the Hazelight Studios fork with Angelscript, it's legitimately 100x better than vanilla UE5
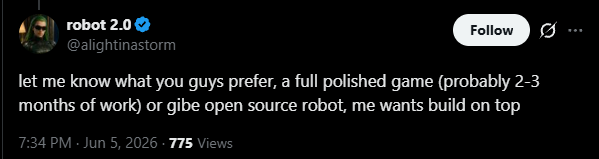
@rfleury@alightinastorm It only takes him a few months to make full polished games, ostensibly LLM performance has improved since half a year ago but I've yet to see a single polished game release
Ok… what a complete waste of time, it went from “this advice is slop” to “I agree with all the advice b-but if you’re already in a large shitty codebase maybe all you can do is try to clean up some of the biggest messes”.
Cool, nobody said don’t measure anything, we just told you that architecture can account for a 10x-100x speed increase. Your responses are very incoherent.
Please take note that we’re disagreeing with you calling good advice slop.
Your post responding to someone saying that you should start with good architecture is to call the advice slop… Very inconsistent.
Somehow you’re still misunderstanding; attacking the biggest bar on a flame graph of poorly architected software is unambiguously a tremendous waste of time that inevitably leads you into rearchitecting things in a data oriented way (if you actually care about performance). You said to keep addressing the biggest bar on the flame graph, do you know what happens at the end of that? You end up with 10,000 bars that can’t really get faster on their own, and the only way to get much faster is to rearchitect the code and data in a data oriented way. How do you do this? By laying things out in a way that is friendly to the way the hardware works.
Maybe you understand this now after this (way too) long back and forth, but you definitely didn’t before, or else you would not have made your original post.