Excited to share that @OpenGraph_Labs has been accepted into @NVIDIA’s Inception Program 🚀
Our mission is to build reliable infrastructure for multimodal data capture, powering the next generation of robotics & world models 🌎
World models can predict the next frame.
They can't predict the next touch.
That's the gap visuo-tactile world models will close.
Is the robot gripping hard enough?
Is the surface rigid or soft?
When exactly does contact begin and end?
Vision doesn't know. Tactile does.
We built @OpenGraph_Labs to capture what cameras miss.
Egocentric RGB × 5-finger multi-taxel tactile gloves.
Frame-synced. Calibrated. In-the-wild.
No lab setups. No scripted pick-and-place.
Just humans doing real tasks in real stores.
Watch the exact moment contact happens.
The pressure map lights up in sync. Every touch. Every frame. 👇
Robotics & world models require real-world multi-sensory data at scale.
But collecting vision, tactile, and IMU data simultaneously is much harder than it sounds. Each sensor runs at different frequencies, latencies, and clock domains. Integrating them means dealing with hardware quirks, driver inconsistencies, and constant timestamp drift.
This is fundamentally a synchronization problem. And it gets harder as more modalities are added and tasks become longer-horizon, because temporal misalignment compounds: the model loses the causal structure of what happened and when.
We learned this the hard way building our own pipelines. That experience led us to build a unified platform for multimodal capture, one that handles time alignment, hardware abstraction, and data integrity from day one.
@OpenGraph_Labs built 'SyncField - Multimodal Data Capture System " which:
▪️ Supports any hardware configuration (multiple cameras + tactile + IMU)
▪️ Automatic synchronization across all modalities
▪️ Output is fully time-aligned and ready to train on
It already powers humanoid robotics teams, data collection companies, and university research labs. If your team is collecting multimodal robotics data, we'd love to talk. (now onboarding teams one by one)
Introducing SyncField, our turnkey solution for in-the-wild data collection that your team can deploy from day1
Data quality = model quality = deployment success 🚀
Data can’t just be outsourced🤯 To iterate fast, robotics teams must own their data infrastructure
Introducing SyncField: turnkey data infrastructure for in-the-wild data collection (Best for UMI-style & Embodied human) #Robotics#UMI#DataCollection
Are you sure your training data is actually synced?
Egocentric camera sees a hand grasping an orange, but the wrist cam shows nothing and tactile reads zero contact.
Your policy is learning from broken data and doesn't even know it.
In Physical AI, multi-modal sync is everything.
→ Egocentric: 30fps
→ Wrist: 30fps
→ Tactile: 100Hz
Different devices, different clocks, slightly different rates. The drift starts small. Barely noticeable frame by frame. But over a 4-minute episode, that tiny difference compounds into seconds of misalignment. And you had no way to even check.
Until now.
We built the Sync Quality Dashboard. One score tells you if your data is clean. Then go deeper. Clock offset, drift rate, jitter, frame drops, per-stream correction. All visible, all measurable.
In a 4-min episode, accumulated clock drift reached 7.5 seconds by the end of the recording. After correction: 9.0ms. That's the difference between "roughly aligned" and "actually aligned."
Visually confirm vision-to-vision, vision-to-tactile alignment frame by frame. No more "trust me, the data is fine."
We don't just collect multi-modal demos. We ship a quality assurance layer so you can verify every episode before it touches your model.
All data in @LeRobotHF format. Ready to train. Verified in sync.
Stop guessing. Start verifying.
VLMs see everything. Feel nothing.
VLMs annotate what looks like contact. Tactile sensors verify what actually is contact.
We ran VLM annotation on real manipulation demos. It labeled a grasp as "approach." Skipped release phases entirely. Hallucinated state transitions that never occurred.
6 out of 36 action phases wrong.
17% of your training data, corrupted.
Why? Pixels don't know when a fingertip touches a surface. Pixels don't know when grip pressure hits zero.
Tactile sensors do.
So we built a pipeline that catches every error automatically. Tactile evidence validates every contact transition. Wrong labels corrected, missing phases inserted.
Not faster labeling. Truthful labeling.
This is one of the core problems we're solving at @OpenGraph_Labs
Robots can't learn if their eyes and hands are out of sync.
A 30fps camera and a 1kHz tactile sensor don't speak the same language. Multiple cameras, multiple sensors, all on different clocks at different rates. Jitter from USB and OS scheduling. Drift that compounds every second of recording.
We built a multi-modal sync pipeline that aligns all of it to ±2.5ms. Automatically. Every frame matched. Zero sensor samples lost.
No hardware triggers needed. Sensor-agnostic. Hardware-agnostic. Just plug in and record.
Physical AI needs real hand-eye coordination. Not approximate, precise.
We're building this at OpenGraph.
https://t.co/H3yzDkaw1j
Tactile feedback is critical for safe and reliable real-world robot deployment 🤚🧤🤖
Really impressive work from @WiYoungsun demonstrating how a shared latent space can bridge tactile signals from wearable gloves to robot embodiments
Dexterous hands vary widely—so do tactile modalities. 🖐️🌈
Our vision on tactile human-to-robot transfer:
🔓 Not tied to specific hardware
♻️ Reuse human tactile demos across embodiments
Presenting TactAlign, a cross-sensor tactile alignment for cross-embodiment policy transfer.
🏆 Won 1st Place at the AGI Hackathon at @agihouse_org with @juliakeem@JerryHan_og
and @OpenGraph_Labs!
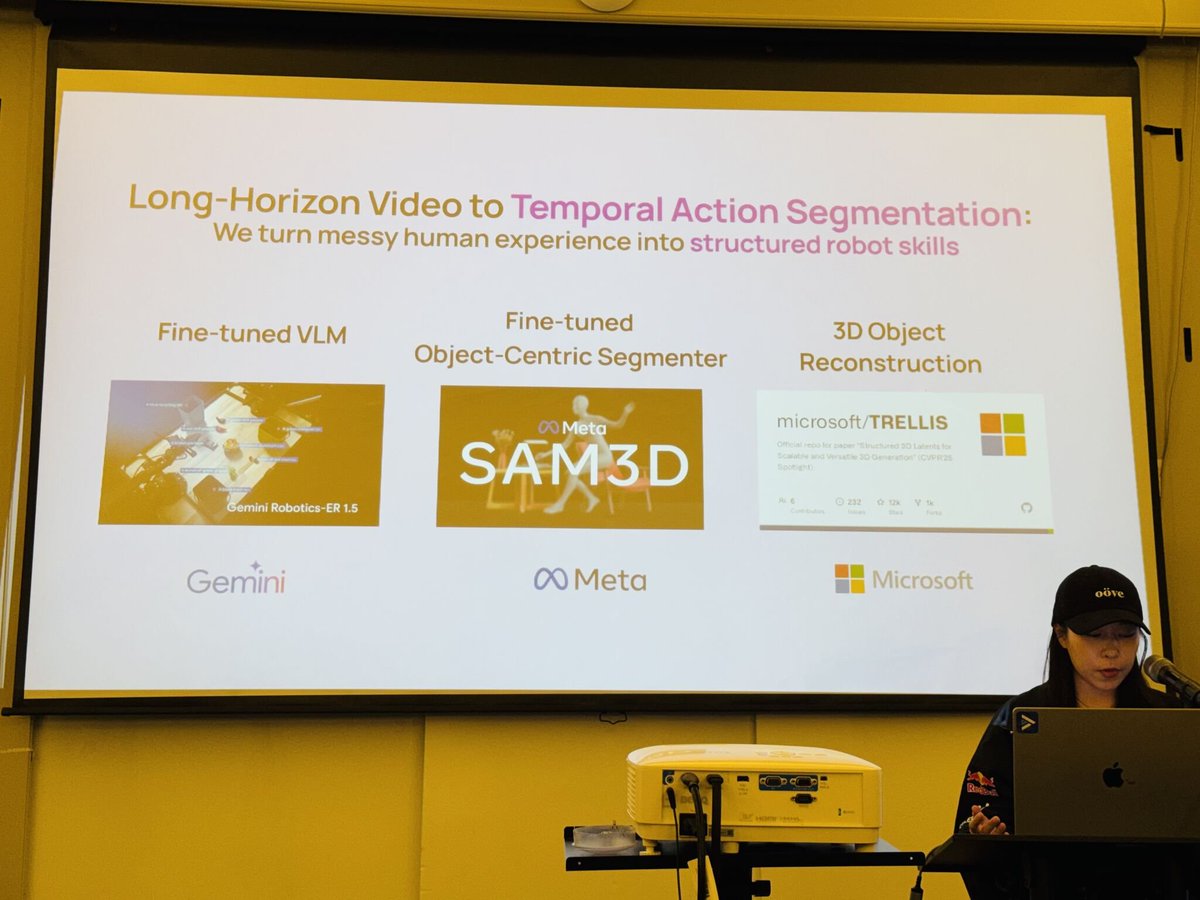
We built a "Temporal Action Segmentation Pipeline" for Physical AI.
The Problem:
Robotics data today = short clips, RGB-only, lab settings.
We need long-horizon, multi-modal, in-the-wild data.
Our Solution:
🎬 Input: Long manipulation video (5+ mins)
🤖 Gemini VLM → Action & Phase segmentation
🎯 SAM3 → Object tracking with text prompts
🌐 Pi3 → 3D reconstruction & camera poses
📚 Skill clustering → Reusable skill library
→ Output: Structured robot training data with timestamps, masks & 3D
Humans ARE the ultimate robots 🦾
#PhysicalAI #Robotics #Hackathon #Gemini #SegmentAnything
Huge thanks to @henry_yu_01 @NomadicML @zoox@DynaRobotics
Robotics right now feels like peak entropy. Everyone has a different bet on what will work, and they're all confident, which is why doing robotics research right now is so fun.
I wrote an essay on the question that's been driving our work from DreamGen → DreamZero → what’s next
My bet: human experience is the only data source that scales, world models are the right paradigm, and humanoids have the edge.
https://t.co/H1Pvr4R34l
8/
On top of this infrastructure, we’re scaling.
Across 30+ industries, our tactile gloves are deployed in homes, factories, and service environments. They capture long-horizon manipulation in the real world.
Introducing the Tactile Data Engine - the frontier dataset for robotics.
Tactile sensing is the new modality for next-generation robot training and world models, enabling robots to understand physical interaction beyond vision.
Let’s get to the next level 🚀
7/ From this data, we derive higher-level physical understanding:
- Temporal action segmentation
- Object tracking with SAM3
- Voice modality aligned with actions
- Affordance points with associated touch information
- Real-time physical deformation during contact