✈️ Off to Singapore to attend #ICLR2025
If you are around, message me to grab a coffee.
Presenting our insights about building vision-language models. Check out MM1.5 https://t.co/9JkdaoTwSw
We release AIMv2, the second iteration of the AIM family of large autoregressive vision encoders. This time we bring multimodality into the game 🔥
Paper: https://t.co/YpU6T8Pr9p
Repo: https://t.co/g1LO5rE5Y0
Model Gallery: https://t.co/j3jZ8TEtf5
🚀🚀 Thrilled to share MM1.5! MM1.5 is a significant upgrade of MM1. With one single set of weights, MM1.5 excels at (1) read your charts, tables, any text-rich images, (2) understand visual prompts like points and boxes, provide grounded outputs, and (3) multi-image reasoning.
🔥🔥 We also introduce two variants: (1) MM1.5-UI to understand your iPhone screen 📱, and (2) MM1.5-Video for video inputs 🎥.
As a research study, we also share the detailed ablations that guided our research process (🧵)
Attending #ECCV2024 this week in Milano🇮🇹 Message me if you are around.
📜Also check out our multimodal foundation model MM1 (https://t.co/MsHY9OGnb1): poster presentation is Tuesday 10:30am.
🌟How to align multimodal LLMs effectively? 🌟 please check out our paper below where we have performed a careful study on existing methods (PPO, RLOO, DPO, online DAP etc.) and preference datasets for alignment. abs: https://t.co/tHqWzIABwx
🚀🚀🚀 Introducing Ferret-v2, a significant upgrade to Ferret that enhances its detailed visual perception ability. With features like any-resolution referring & grounding, multi-granularity visual encoding, and a three-stage training paradigm, Ferret-v2 sets a new standard.
🚀🚀 Ferret-v2 is here. Checkout the latest work from our group. A new design of referring and grounding MLLM with any resolution input. Significantly improved performance on original Ferret and other baselines.
Work lead by @HaotianZhang4AI@XyouH@zhegan4
Apple presents Ferret-v2
An Improved Baseline for Referring and Grounding with Large Language Models
While Ferret seamlessly integrates regional understanding into the Large Language Model (LLM) to facilitate its referring and grounding capability, it poses certain
💡Imagine a multimodal LLM that can understand your iPhone screen📱? Here it is, we present Ferret-UI, that can do precise referring and grounding on your iPhone screen, and advanced reasoning. Free-form referring in, and boxes out. Ferret itself will also be presented at ICLR.
We live in such strange times. Apple, a company famous for its secrecy, published a paper with staggering amount of details on their multimodal foundation model. Those who are supposed to be open are now wayyy less than Apple.
MM1 is a treasure trove of analysis. They discuss lots of architecture designs and even disclose that they train on GPT-4V-generated data. They provide exact scaling law coefficients (to 4 significant figures), MoE settings, and even optimal learning rate functions.
I have not seen this level of details from a big tech's whitepaper for a very, very long time. Apple's so back!
Check out MM1 for detailed insights how to train vision language models!
Incredibly grateful and honoured that I had the chance to be part of this amazing team 🙏
https://t.co/2Mlwbt2RxU
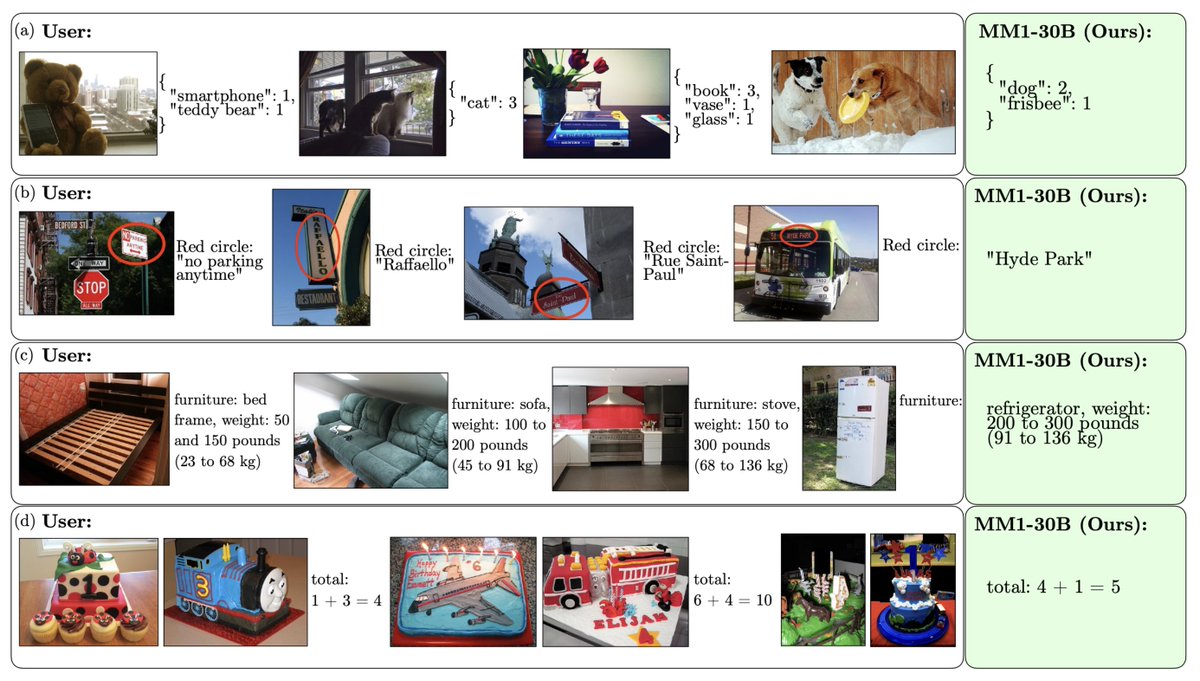
Thrilled to share MM1!. The MM1 series of models are competitive with Gemini 1 at each of their respective model sizes. Beyond just announcing a new series of models, we also share the ablation results that guided our research process (🧵).
Excited to announce our Multimodal LLM! The model is SOTA on a range of benchmarks in few-shot settings. And more importantly we give insights that hopefully will help folks out there build such models! J/ work with an excellent group of colleagues. https://t.co/Optgo1Khgf
@mariusmosbach Somewhat related: we trained small masked LMs on less than 10k tokens in this paper: https://t.co/FUt2CCff3R to investigate multilingual properties.
Excited to share that our paper “Towards a Broad Coverage Named Entity Resource: A Data-Efficient Approach for Many Diverse Languages" has been accepted at #LREC2022! 🎉
Joint work with @imani_ayyoob, @PDufter, and @HinrichSchuetze. [1/3]
Preprint: https://t.co/sX9GR3G0eU
Missed #EMNLP2021 & need something to read 📖 for the weekend 😋? Check out our papers on
a) tokenization compatibility across languages https://t.co/Z8cEsl0lcF
b) word alignments https://t.co/wS0PlGk1hj
c) character alignments https://t.co/oepeALelpe
@CisLmu
Check our new paper at #EMNLP2021 "Graph Algorithms for Multiparallel Word Alignment". We get better results compared to bilingual aligners even when we use noisy translations.
Joint work: @imani_ayyoob@lksenel@PDufter@HinrichSchuetze
PDF: https://t.co/rCoOvgV8dj
#NLProc