📣New paper 📣
We introduce MemLLM, a method to enhance language models by adding a read-write memory.
By designing an interaction schema and constructing training data, we fine-tune a model to store and use facts with an external structured memory.
🧵
Excited that our paper "Glot500: Scaling Multilingual Corpora and Language Models to 500 Languages" won the Area Chair Award at #ACL2023. Big kudos to our squad at @CisLmu who made it all happen. @lpq29743 to present the findings. #NLProc
An idea paper comes into play, offering an innovative solution: equipping LLMs with read-write memory.
“RET-LLM: Towards a General Read-Write Memory for Large Language Models”
🔗:https://t.co/73oZwBUmtU
A joint work with @imani_ayyoob , @MohsenFyz & @HinrichSchuetze
(🧵2/4)
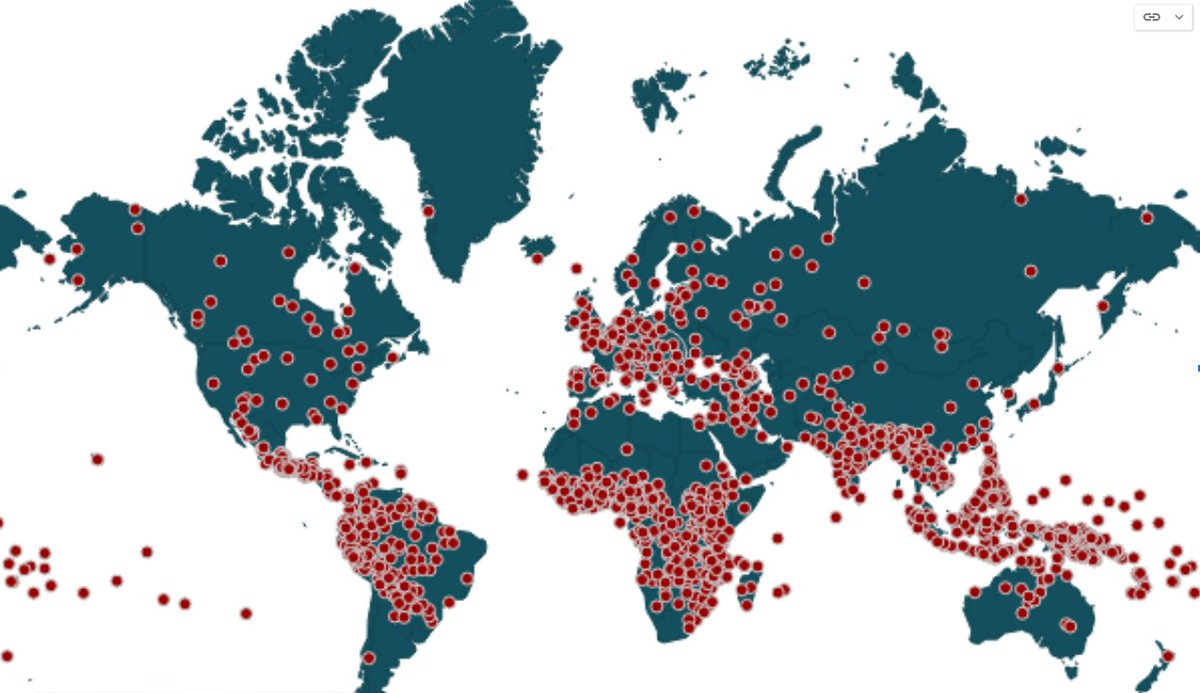
Glot500: Scaling Multilingual Corpora and Language Models to 500 Languages
repo: https://t.co/lNiY4rfia5
abs: https://t.co/fRhEtrr37z
HuggingFace: https://t.co/7XRqn8PMXA
🎉Happy to share that our paper “Graph-Based Multilingual Label Propagation for Low-Resource Part-of-Speech Tagging” was accepted to #EMNLP2022 !
Joint work with @imani_ayyoob, @_masoudjalili, @yvofr, and @HinrichSchuetze.
Preprint coming soon🍿!
#NLProc
We present ‘Graph Neural Networks for Multiparallel Word Alignment’. Our method significantly improves word alignment quality, especially for low-resource languages.:
✏️@imani_ayyoob@lksenel@_masoudjalili @yvofr @HinrichSchuetze
📎https://t.co/nFNPf01hE7
🗣️25th PS6 10:45 am