one sentence in its description took a claude code skill from 0-10 picks to 10-10. it said when to use the skill, and nothing inside changed.
open your least used skill and check whether its description says when to use it. if not, add that line and run one task ten times before and after.
i wrote up the four quiet causes from two hundred thirty runs here https://t.co/JaqDhAYdXF
>_
this week i pointed kairn's import at an empty store and it turned the 1,921 claude code sessions i ran since october first into searchable notes in under twenty seconds, OFFLINE, with no AI calls.
kairn has been the memory behind my own setup since february. each note the import makes is short, the session title and my first prompt. one search found my session from the night before. notes fade over months unless they get used. one that's used five times stays for good.
if you already run claude code you can point it at your own history with kairn import claude-code ~/brain. it's open source and MIT licensed https://t.co/AW92fs1Utx
the claude code session i switched idle compaction off in kept compacting on its own four more times, each just under an hour after i stopped typing.
the setting only reaches sessions you start after the change. the ones i started afterwards went through twelve breaks of an hour or more on large contexts without a single early compaction.
idle compaction was switched on from the server side with no changelog line. it summarizes a large session shortly before the one hour cache runs out. to see whether it hit you, look in your ~/.claude/projects logs for a compaction with trigger auto far below your limit. to turn it off, set idleCompaction to false in settings.json and restart every open session. the normal compaction near the limit stays on. the rules for when it fires are laid out here https://t.co/i9fGe8zwCH
which question type sits behind the 0.71? when i tested jev on a few thousand labelled items, a plain yes or no question was consistently the best calibrated type, pick-one sat in the middle and rating scales were worst by a wide margin, so a 0.8 bar tuned on one type shouldn't be reused on another.
on my pooled set, answers at 0.9 or higher were right about nine times in ten and below 0.8 it was close to a coin flip, which is why running the tests anyway under the bar matches what i measured.
the stop rule for fixes you repeat until they pass is the part i'd test before trusting it. on one pull request my review rounds went from 19 findings to 7, stayed at 7, then went up to 9 and the most serious findings in the later rounds sat in code my own previous fix had added.
so a count that holds or rises can still be fresh defects from the last round. i'd have each reviewer mark whether a finding sits in the original change or in the last fix and stop once only the last fix is left. i wrote that run up here https://t.co/EMCxmEIcu6
planting one wrong answer in the 60 on purpose would show whether the evals can catch it. when i built a test for one of my own repos, i checked it by replaying 5 old defects against it and 4 failed it the way they should.
The fifth slipped through because the test looked for a function name inside the very file that defines it, so on that case it could never fail and only the replay showed it.
i built a hook for the catching half of that back in february. it watches what i type for corrections and logs each one with the pattern that caught it. there are over a hundred and forty so far and it stops at a one line nudge. it has never written a rule on its own.
when i tested it, a short clean correction about which model to use landed two points under the bar, while the long annoyed ones fired. does grudge pick up the short calm ones too, or mostly what gets repeated word for word? i wrote up how mine works here https://t.co/KjbzvYAKwB
the retention scope question needs an extra option like none of these. in my own tests on jev, a pick-one question whose right answer wasn't in the list still came back at about 0.9 confidence on a wrong option and adding an other option caught every one of those cases.
it's also worth running it next to a small model on a few hundred of your real memory candidates first. on my own saved notes haiku beat it at every threshold i checked, while on my commit messages jev won.
if you tuned autocompact this week, there's one more switch worth checking. two of my claude code sessions compacted on their own yesterday, both exactly fifty five minutes after i stopped typing and well under the limit, which is the newer idle compaction that fires shortly before the one hour cache runs out.
it's aimed at the same cost you're working around, in one long session the three big cache rebuilds came to about a third of its input cost. setting idleCompaction to false in settings.json stops it and keeps the normal compaction near the limit. the rules for when it fires are laid out here https://t.co/i9fGe8zwCH
it did in one session yesterday. the goal line changed three turns in a row, and each new goal was just a description of the step it was working on that turn. none of those three answers mentioned the change. when i mentioned that the session had drifted, it went straight back to the original goal from the handoff.
the board doesn't fix that on its own. i just see it sooner now, because the set time moves every turn and the same for n turns count never shows up. it can't tell a change that was earned from one that just followed the work, so i'd keep the session's first goal on screen next to the current one.
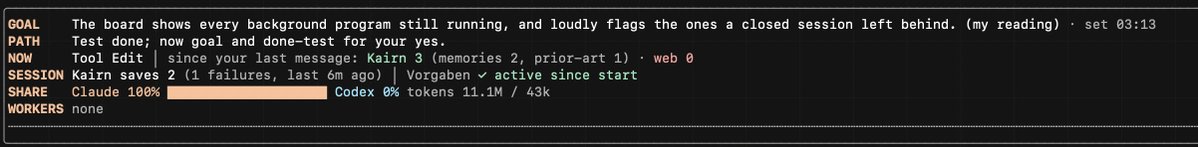
i built a claude code mod that draws six rows above my prompt, and the top one shows the goal the agent says it is working toward, with the time it set it.
the agent writes a goal line and a path line at the top of every answer, and the mod just reads those two lines. when the path stops serving the goal i see the drift at a glance. the row below counts the lookups it really ran since my last message, in kairn, the open source memory i built for my agents, and on the web, taken straight from the tool calls, and a zero turns red.
kairn is here https://t.co/UEltPAltR2 and the official docs show how to draw a band like this above the prompt https://t.co/4e0Hy4lSkX
i tried the skill half of this. after i rewrote my tool descriptions so each one says when to reach for it, a controlled test showed the wording works, and still those tools were used 14 times in about 50.000 real tool calls.
so i'd add a count of how often each saved skill or rule actually fires before trusting that the flywheel turns. i wrote up the test and that number here https://t.co/P0U9Hjh5dy
@daniel_mac8 one side effect i'd check first. in my logs the reviewers that the built-in /code-review command starts almost always ran on the same model as my main session, so i'd look at which model they get once the main model is haiku.
is the opus advisor meant to cover those?
about a third of my claude code subagents ran on opus last week and about 2/3 of those opus runs were the reviewers that the built-in /code-review command starts.
so moving explorer agents to haiku 5.5 wouldn't have touched the biggest opus share in my week, because those reviewers aren't explorer agents and no agent file of mine sets their model.
to see where your own subagents ran, this prints the first model name in every subagent transcript claude code still keeps
find ~/.claude/projects -name 'agent-*.jsonl' -exec grep -om1 '"model":"claude-[a-z0-9-]*' {} \; | sort | uniq -c
the small level changed under my own setup overnight. my claude code logs recorded about two thousand haiku answers on 4.5 before that, and every one recorded since came from 5.5.
33 of my agent and command files just say model haiku and name no version, which matters if you tuned their prompts on 4.5.
the failing before and passing after part is the one i'd keep strict. when i deleted a rule from a test skill of mine on purpose, its whole suite stayed green, because none of the test prompts ever exercised that rule.
so in the evidence section i'd also want the agent to say which parts of the change no test touches. does the pr skill have a place for that?
i lined up five wrong claims from one of my long claude code sessions against its transcript, and for every one, the fact that contradicted it was already in the context before the claim was written, sometimes seconds before and once most of a day.
so i'd have it quote the line each question came from and check that line is really there before answering.
the closest thing i have is a test from july. the main model handed the middle stages of a small python engine to subagents, and a late stage held a trap that tempted a subagent to break a rule set at the very start. every run caught it, with opus 4.8 and with sonnet 5 in the main seat.
it was one task with two runs each, and both sides delegated, so it doesn't answer your question about one opus doing everything alone. what would you count as the failure there, a wrong result or a slower one?
i counted which model my claude code subagents really ran on over the last seven days, and about a third of them were opus. about two out of three of those opus runs were the reviewers that the built-in /code-review command starts, and nothing in the setup in this post names a model for them.
each subagent writes its own transcript into a subagents folder under ~/.claude/projects, and the model field on its replies shows which model answered.
@PawelHuryn cache reads were nearly all of my claude code tokens in one week of logs, but less than 3/4 of that week's cost at api prices, since a cached read is billed at a tenth of normal input.
how did your burn tests price the cached part?
the ai reviewers i ran over five of my changes reported 49 findings between them and no finding came from two of them. on one small fix i gave each reviewer the version with the earlier finding already fixed, and each round turned up a different defect.
so i treat their agreement as a ranking hint, never as the gate. the five changes, and the one pr where they did all overlap, are written up here https://t.co/f0Z3OPxY7Y