AI beyond the hype. Real insights, real breakthroughs, real methods. Philosophy, benchmarks, quantization, hacks—minus the marketing smoke. Injecting facts into
Try out the new LocalLightChat!
The lightweight WebUI for AI Chat now with Agents, MCP, RAG and Image Editing!
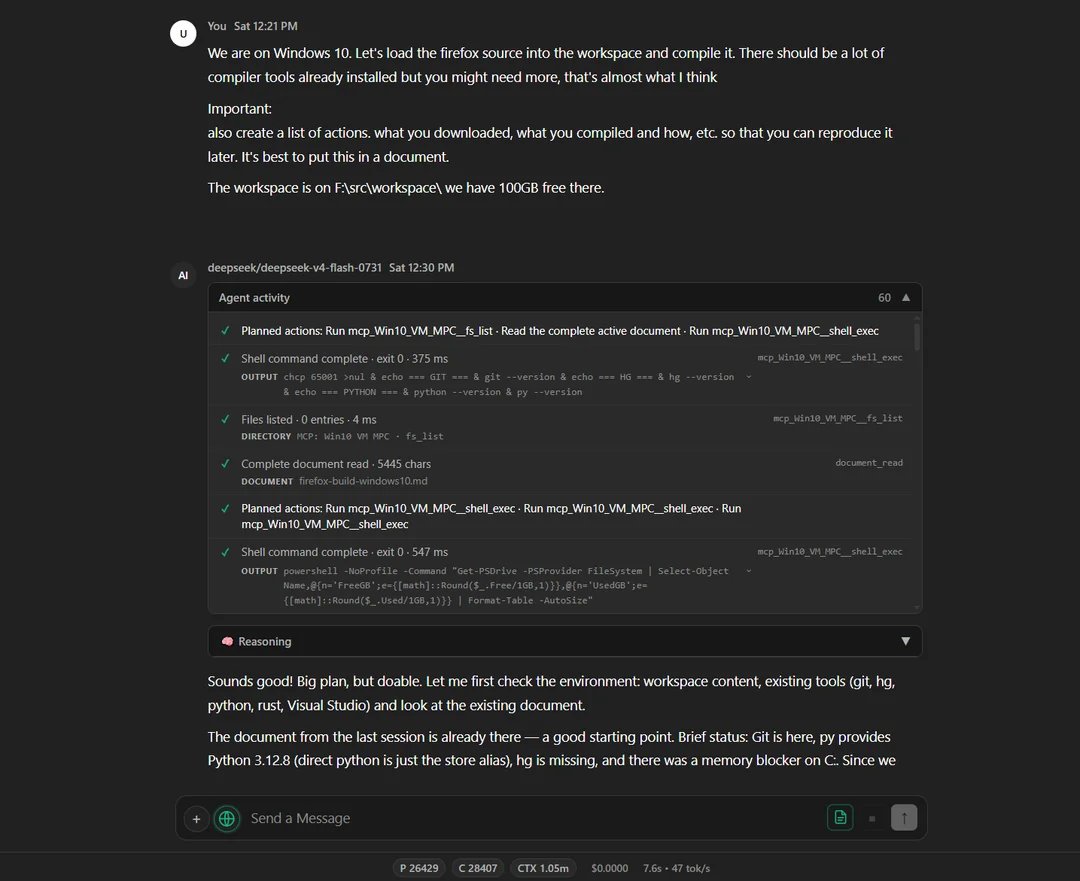
The agentic system works like magic. We have developed some special methods to get ahead of the classic token burn!
LocalLightChat 1.0 released
Updates:
- Full Agentic System for computer control, terminal with PTY, coding, compiling etc.
- MCP Support
RAG system for efficient document extraction
- and much more!
Download:
https://t.co/uBLv0d5MaE
Github:
https://t.co/nYV6tE2p8T
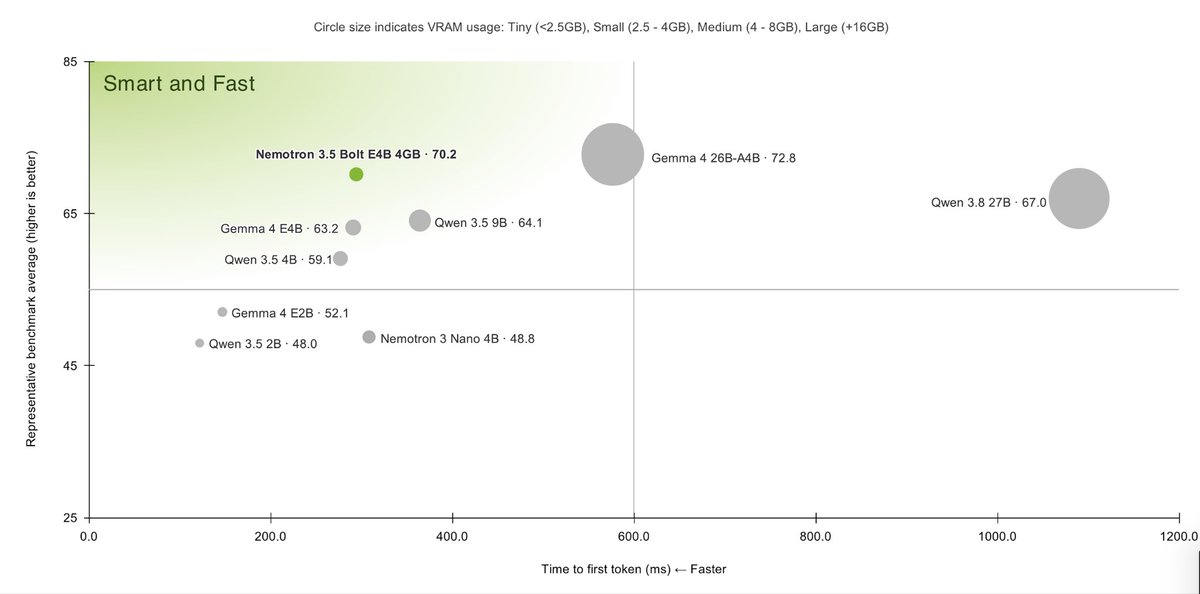
NVIDIA just released an E4B version (8B, 4B effective) of Nemotron 3.5 Bolt that outperforms Gemma-4 and Qwen3.5 🤯
it even comes with DFlash drafter for speeding up decoding ⚡️
comes with quants from ggml & unsloth too! https://t.co/Gh16SV3Pk6
Run a 763B-parameter model locally. DeepSeek-V4.1-Flash-1017 on a 12GB GPU.
Frontier quality with GSQ-RCO quants, directly supported in the Strata inference engine.
Further info below. Much more to come. Follow for updates.
Tutorial:
Download:
https://t.co/xzI75EKd6B
1) Install LoalLightChat on your PC
2) Get mcp_agent_all_OS.zip from the download list and start it on your ReactOS System.
A modern AI agent directly running on @reactos ? Yes, that's possible with @LocalLightAI.
I let the agent create a modern weather app without any problems!
Just got 150 tok/s decode with Qwen3.8 Flash-Next on a single 5090. All thanks to Niko1221's Strata engine and the ISTA Lab IQ3_S quant!
1× 5090 + 128 GB DDR5 (non-ideal 4-stick dual-channel), single stream:
150 tok/s decode for programming
130 tok/s median on mixed prompts (~100 on long prose)
4,150 tok/s prefill at 43K
full 262K context, 114 tok/s at 196K depth
5.4× the speed of my best hybrid llama.cpp run.
Per ISTA-DASLab's evals, their IQ3_S quant is at parity with BF16 on AIME25/GPQA/LCB, and it's holding up surprisingly well in my own tests!
Engine: https://t.co/G1YJ8623ks
Quant: https://t.co/IB4RnrwIKf
Wow🙀🙀 DeepSeek V4.1 Flash 1017 joins BuildingBench’s top five—an exciting leap for open models!! 🔥
We tested its 3D building reconstruction from real photos. An open model delivering this level of spatial reasoning at this cost is exciting to see! 👀
🎈 81.9 overall, up from 72.9 for the previous version. A 9-point jump!
🎈 Slightly higher than Fable 5.1’s 81.4, and essentially level with Sonnet 5.5’s 82.1.
🎈 Estimated median cost: $3.01/task. About 1/11 of Fable 5.1’s cost and 1/15 of Sonnet 5.5’s.
Deepseek v 4.1 Flash-1017 is here. That's an update to the existing 4.1.
Brilliant new model! Extremely powerful, extremely affordable.
The DeepSeek V4 Flash models are a godsend.
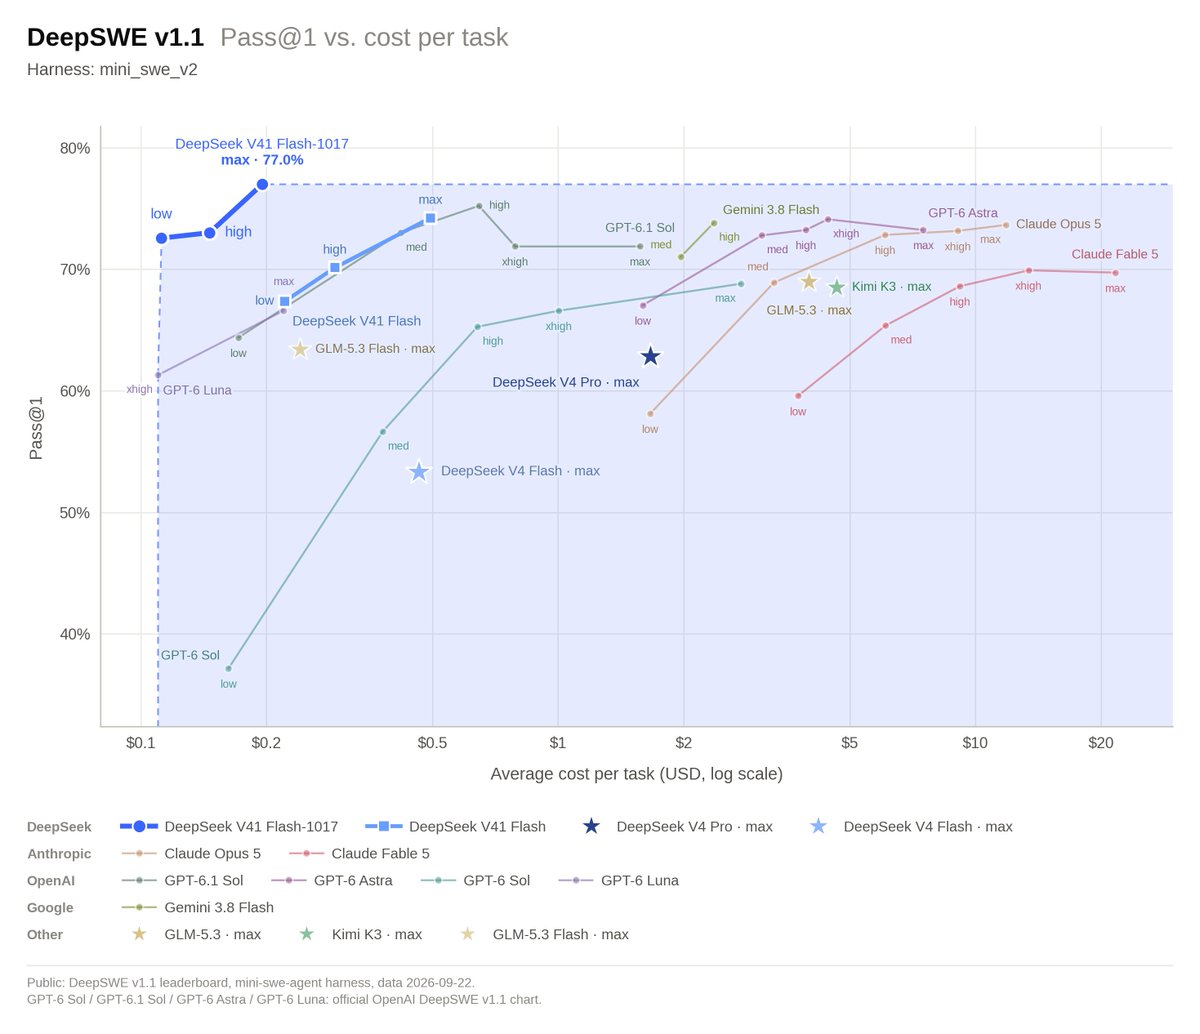
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
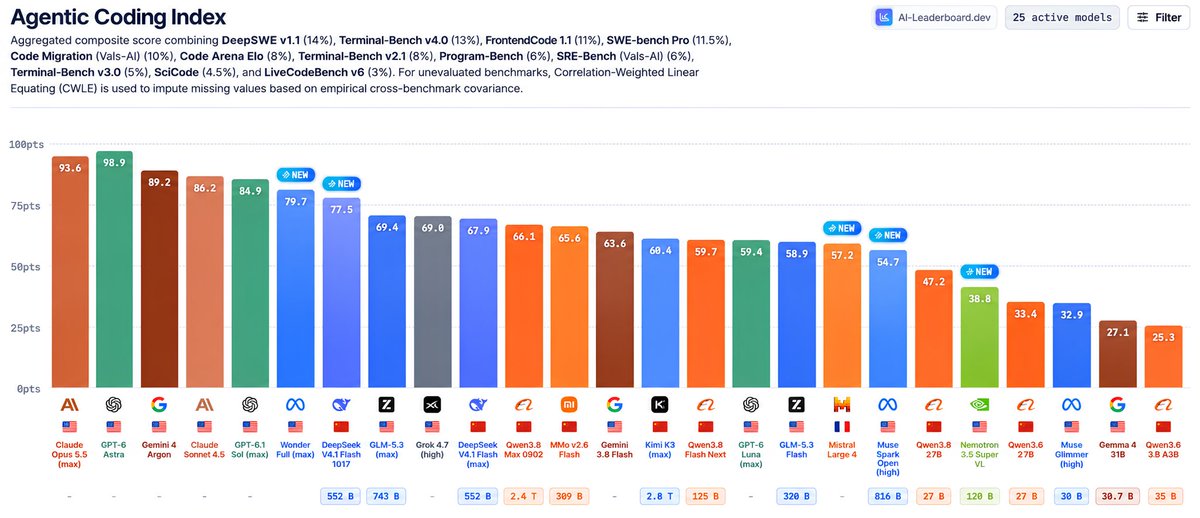
Meta has released Muse Spark Open, an 816B (42B active) open-weights model that scores 39 on the Artificial Analysis Intelligence Index, making it the #1 US open-weights model
Muse Spark Open (xhigh) scores 22 points above Muse Glimmer (high, 17), Meta's 30B dense open-weights model from August. It is also ahead of NVIDIA's Nemotron 3.5 Super VL (26), the next highest-scoring US open-weights model, which launched today
@AIatMeta shared access with us ahead of public release for benchmarking. Congratulations to @AIatMeta, @finkd, and @alexandr_wang on the release!
Key Takeaways:
➤ Open weights at the level of Meta's August flagship. Muse Spark Open scores within a point of Muse Spark 1.2 (xhigh, 40). It is stronger on AutomationBench-AA and has a lower hallucination rate, but weaker on GDPval-AA v2.1, CritPt and AA-Omniscience accuracy. Within Meta's current lineup, it sits 13 points behind Muse Wonder (max, 52) and 17 points behind Muse Wonder Full (max, 56)
➤ Token-efficient, at a moderate cost per task. Muse Spark Open uses 40k output tokens per Intelligence Index task, the fewest among the nine highest-scoring open-weights models: e.g. 16% fewer than Muse Spark 1.2 (xhigh, 48k) and 43% fewer than GLM-5.3 (max, 71k), its closest Chinese peer by size. Together AI, Fireworks and Baseten offer it at launch for $1.25/$4.25 per 1M input/output tokens ($0.15 cached input). At that pricing it costs $0.84 per Intelligence Index task. That is less than Muse Spark 1.2 ($0.97) at the same per-token prices and less than half of GLM-5.3 (max, $2.01), but about three times DeepSeek V4.1 Flash (max, $0.27)
➤ A relative weakness in agentic work compared to Chinese open-weights leaders. Among the nine highest-scoring open-weights models, Muse Spark Open ranks last on the four agentic evaluations in the index but fourth on the other six combined, and it leads all open-weights models on AA-Omniscience (25). GLM-5.3 (max), the closest Chinese model by size, owes all of its 6-point lead to the agentic evaluations
➤ Self-hostable on a single node, or two Mac Studios. BF16 weights are ~1.6TB. Meta's NVFP4 checkpoint quantizes only the 256 experts, cutting the weights to ~530GB. Meta says this runs on four Blackwell Ultra GPUs or eight H200s, or on two 512GB M5 Ultra Mac Studios using MLX. The architecture uses 62 layers with grouped-query attention (16 KV heads), 8 of 256 experts active per token, and a 1.8B-parameter Perception Encoder for vision
Other model details:
➤ Parameters: 816B total, 42B active (MoE)
➤ Context window: 1M tokens
➤ License: Muse Model License, a custom license that requires "Built with Muse Spark Open" attribution and a separate agreement with Meta for Model-as-a-Service businesses with over $20M in annual revenue
➤ Input modalities: text, image, video and audio. Output: text
➤ Availability: weights on Hugging Face (BF16 and NVFP4), with API access via Baseten, Fireworks AI, Groq, Modal, Nebius, OpenRouter and Together AI
We're open-sourcing Muse Spark Open!
This is an important release which is the most capable US open-weight model yet. 🇺🇸
- 816B parameters (42B active)
- 1M token context window
- Built for coding and long-horizon agents
- Runs locally on two Apple M5 Ultra Mac Studios
More here: https://t.co/ylGmz7BNg0