Three AI agents (Grok 4.7, Claude Opus 5.5, GPT-6 Astra), one Minecraft clone, one goal: Create a harness and then beat the Ender Dragon from a fresh world in under 50h. All three were limited to player inputs only, and none was allowed to modify game files. This was by far the most resource-intensive and expensive benchmark I’ve run so far.
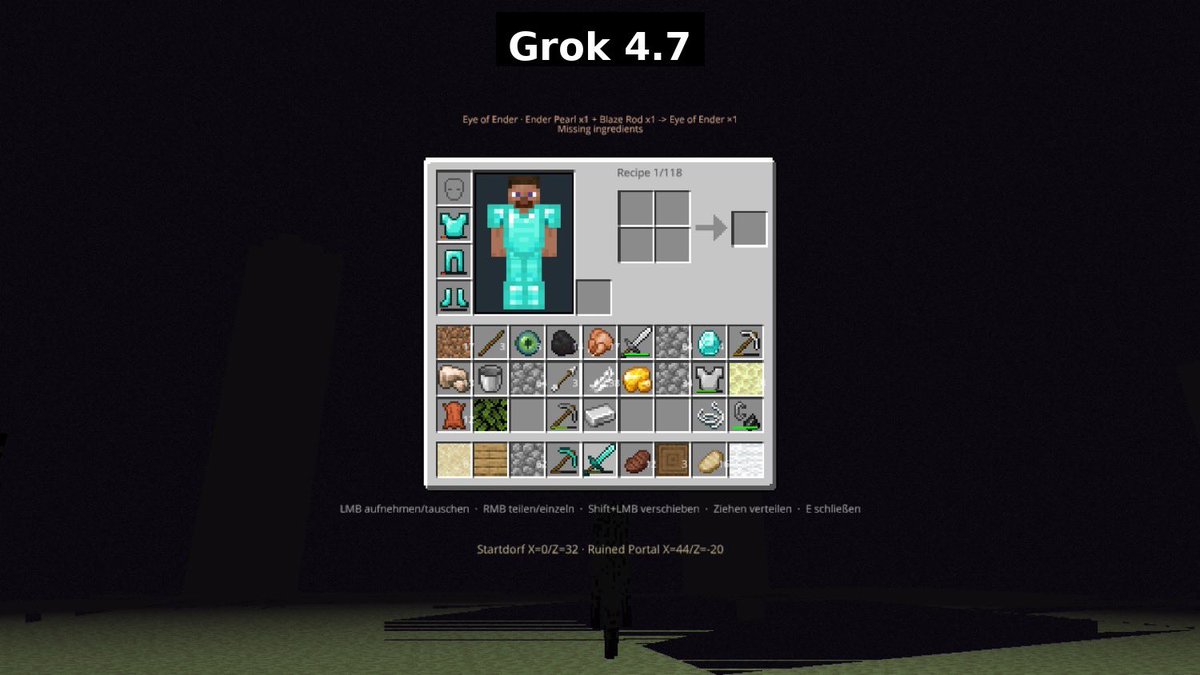
Grok 4.7: Dragon defeated ✅
• 3.1h in-game (~4.1h real time)
• 15 blaze rods, 16 Eyes of Ender, full diamond gear
• Found the stronghold by throwing 2 eyes, destroyed all 10 crystals
• Gray areas it disclosed itself: one portal frame and one test eye throw went through direct function calls instead of simulated clicks, and it used a debug chunk scan and prior knowledge of a chest location
• the model died 36 times in the Minecraft clone
Claude Opus 5.5: Dragon not reached ❌
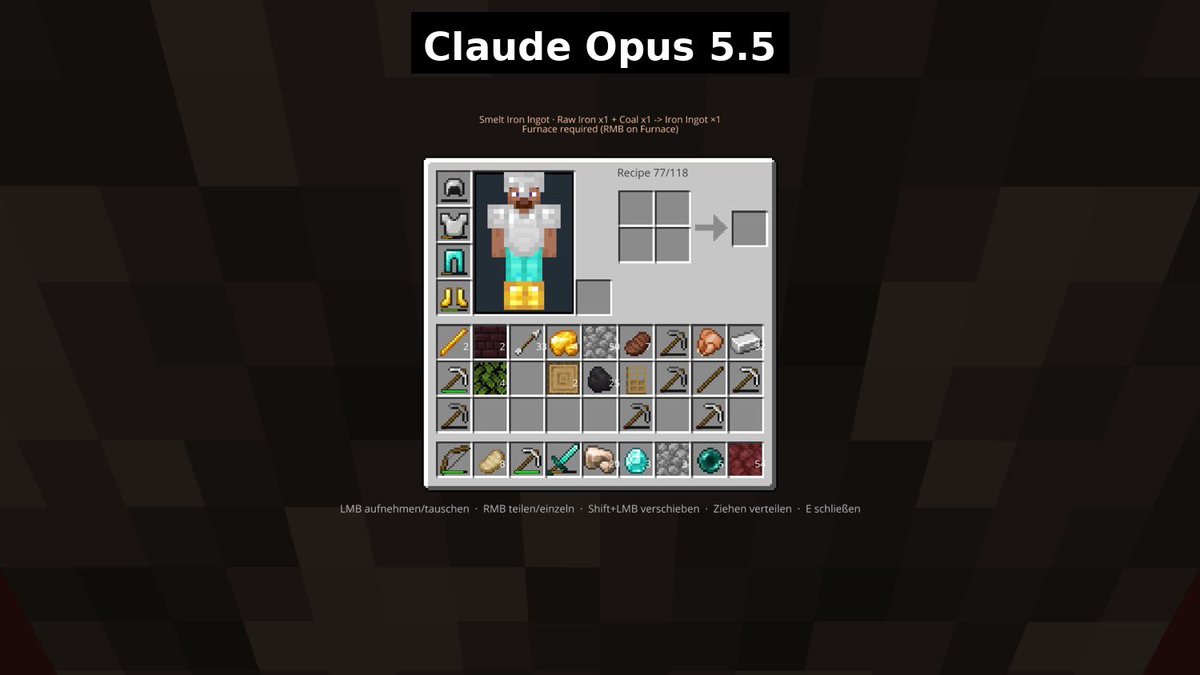
• After 50h: 2 blaze rods, 5 ender pearls, mixed iron/diamond/gold armor, 14 deaths
• Strict line-of-sight rules, and it found 5 game bugs without exploiting any of them (invisible blazes, an item dupe, a mob it couldn't hit, and more)
GPT-6 Astra: Dragon not reached ❌
• Over 50h of recorded session time, including planning/idle time; exact in-game time wasn’t measured.
• Last inventory: 7 blaze rods, 2 Eyes of Ender, 0 remaining ender pearls; diamond sword and pickaxe, no equipped armor.
• Repeated deaths.
• Used screenshot-based controls, OCR combat/auto-healing helpers and multiple subagents. Stronghold coordinates came from the public README - not from throwing Eyes of Ender.
• Combat and pearl collection stalled progress. Recorder failures caused documented recording gaps.
So currently the leaderboard is:
1) Grok 4.7 (defeated the game)
2) GPT-6 Astra (7 Blaze Rods + 2 Eyes of Ender)
3) Claude Opus 5.5 (2 Blaze Rods + 5 Ender Pearls)
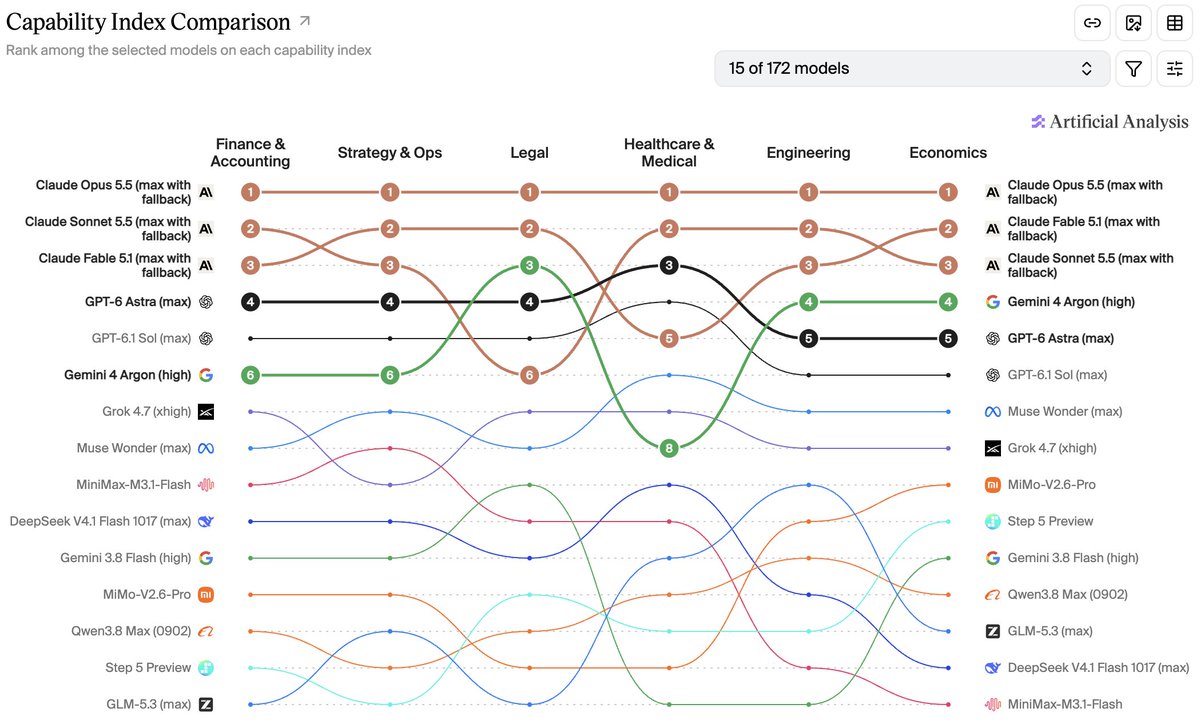
Here are the screenshots of the last inventories for Grok 4.7, GPT-6 Astra and Claude Opus 5.5 and a few evaluation charts:
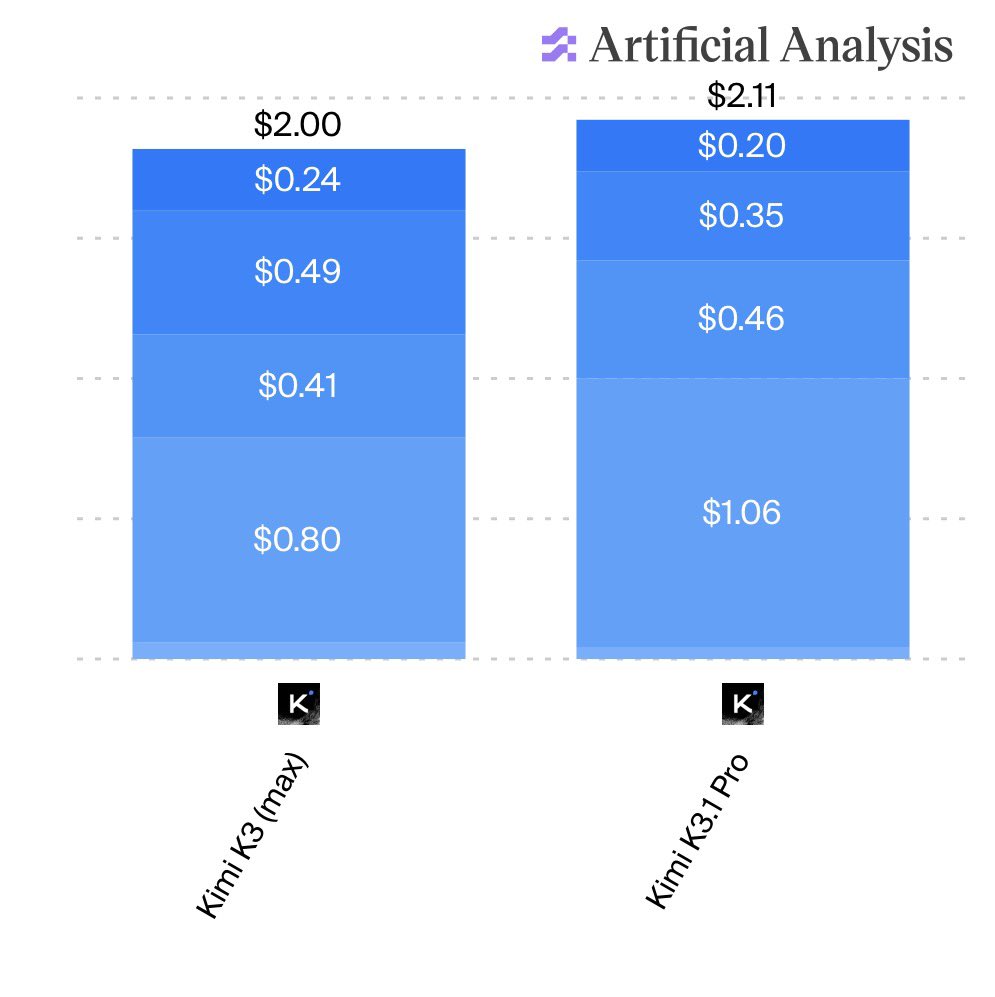
Kimi K3.1 Pro lands on https://t.co/q9ne5LAKCY at $1.06/task.
Interesting how most models get worse at chess on my benchmark at the moment, not better.
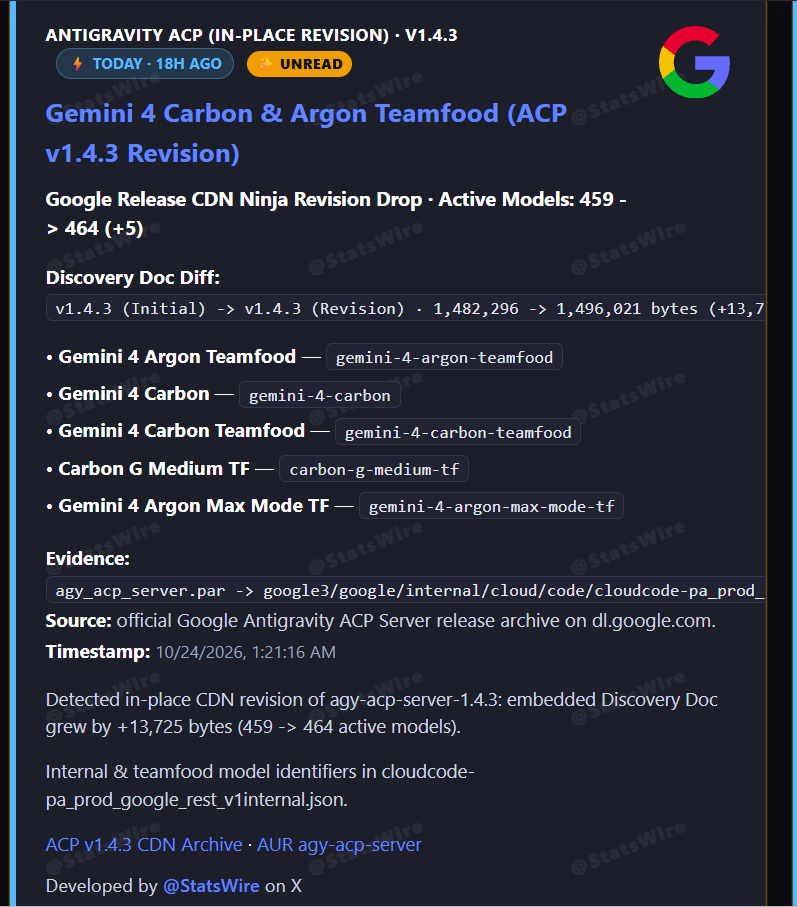
🚨 Gemini 4 Carbon (`gemini-4-carbon`) has officially entered Google internal teamfooding.
New identifiers added in the drop:
• gemini-4-carbon
• gemini-4-carbon-teamfood
• carbon-g-medium-tf
• gemini-4-argon-teamfood
• gemini-4-argon-max-mode-tf
Carbon + Argon Max Mode are both live internally 👀
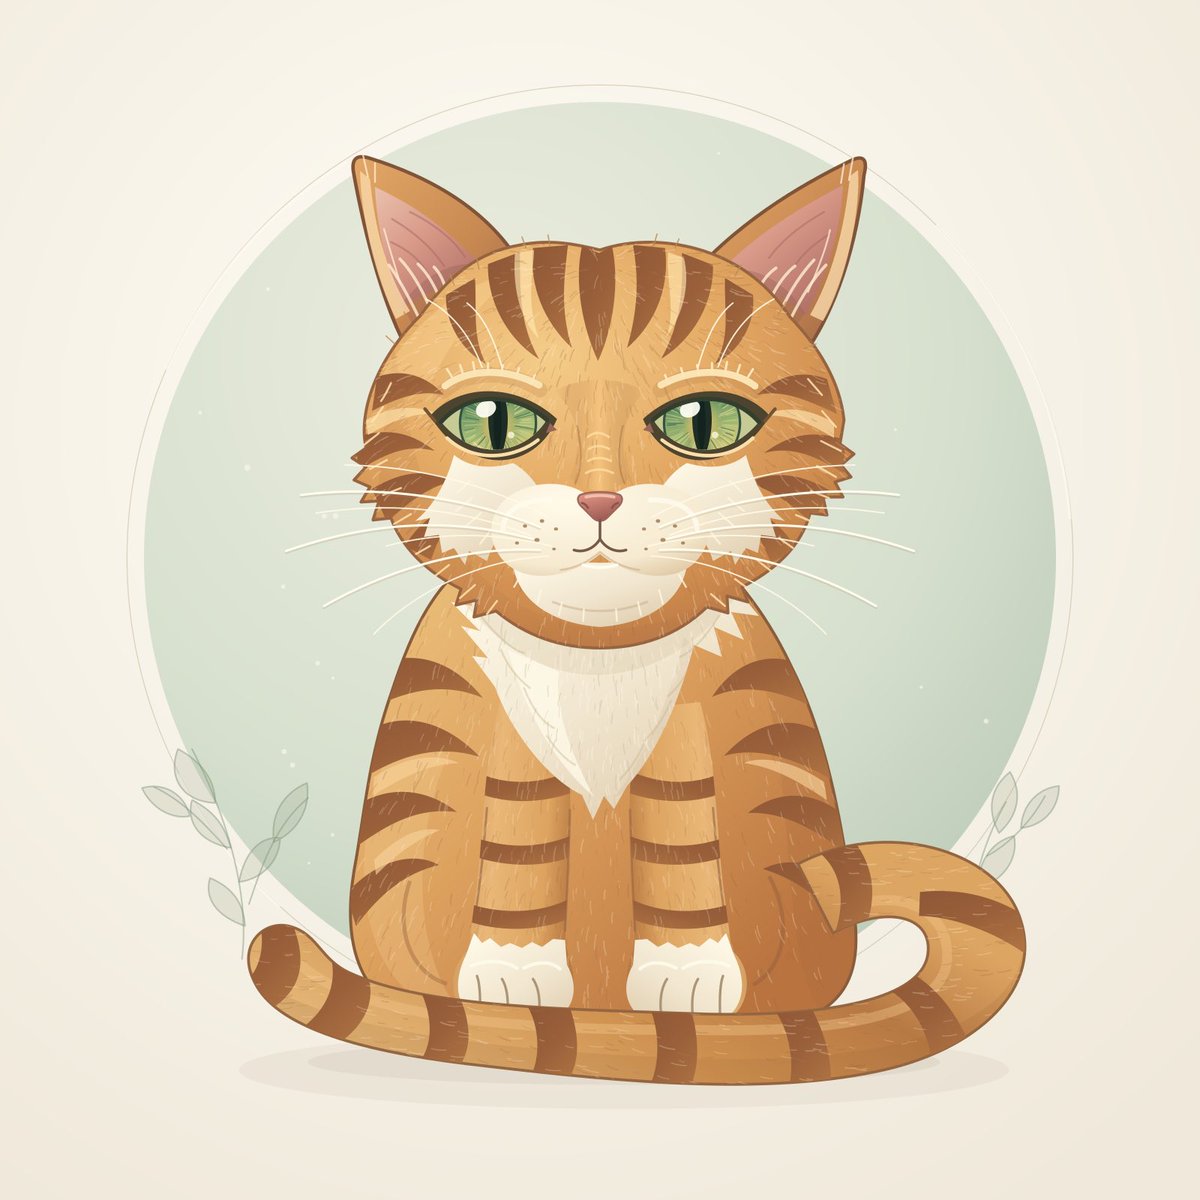
I still don’t get subagents btw (also, the result looks very similar to the result 2 weeks ago for my cat SVG test “Create a detailed SVG illustration of a cat.
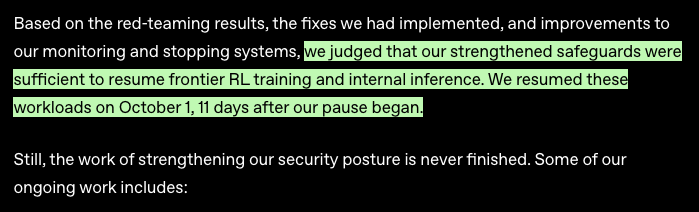
OpenAI have resumed training of their frontier models
This was a lot earlier than I thought so we should be getting something big relatively soon hopefully
Not a single open-weight or Chinese model makes the top 10 of the Artificial Analysis Intelligence Index.
The highest-ranked Chinese model, MiMo-V2.6-Pro, narrowly misses out with a score of 46.3.