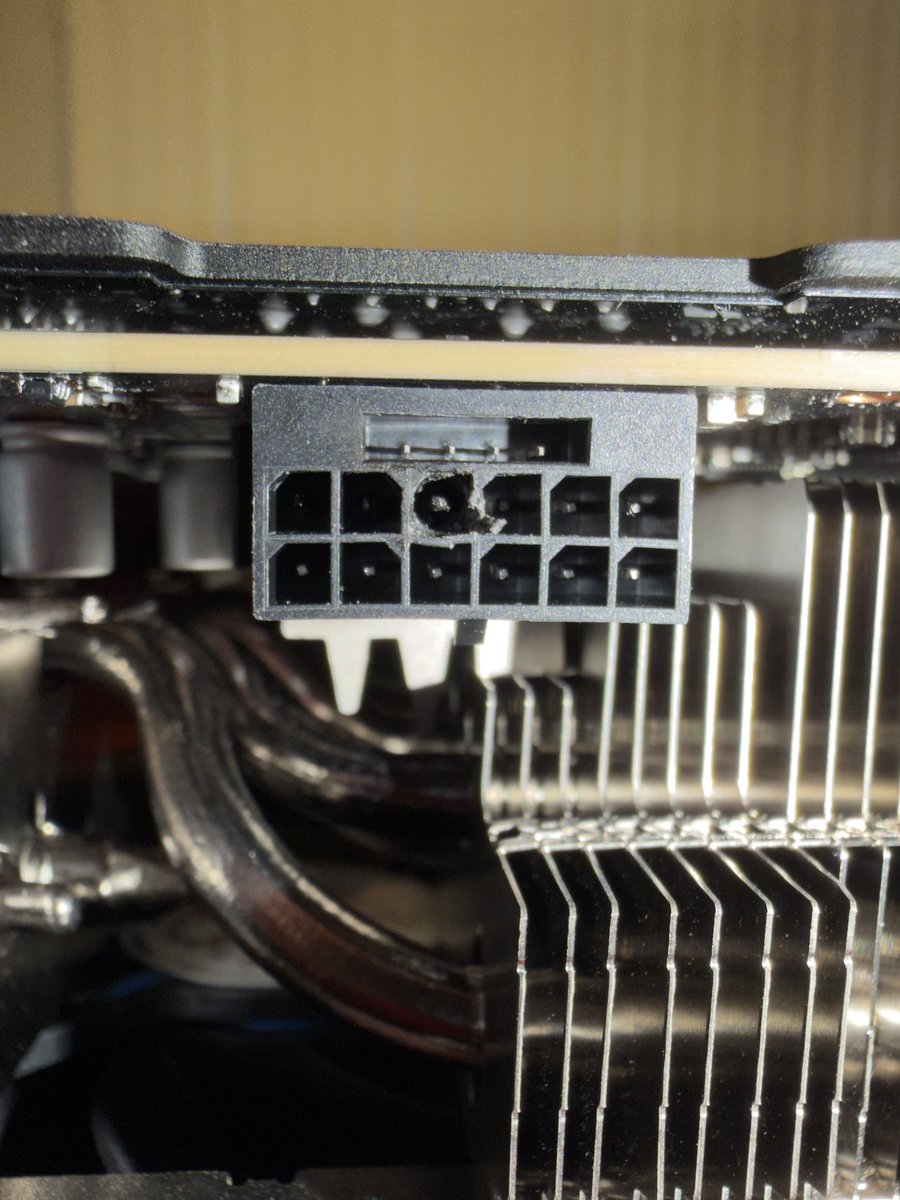
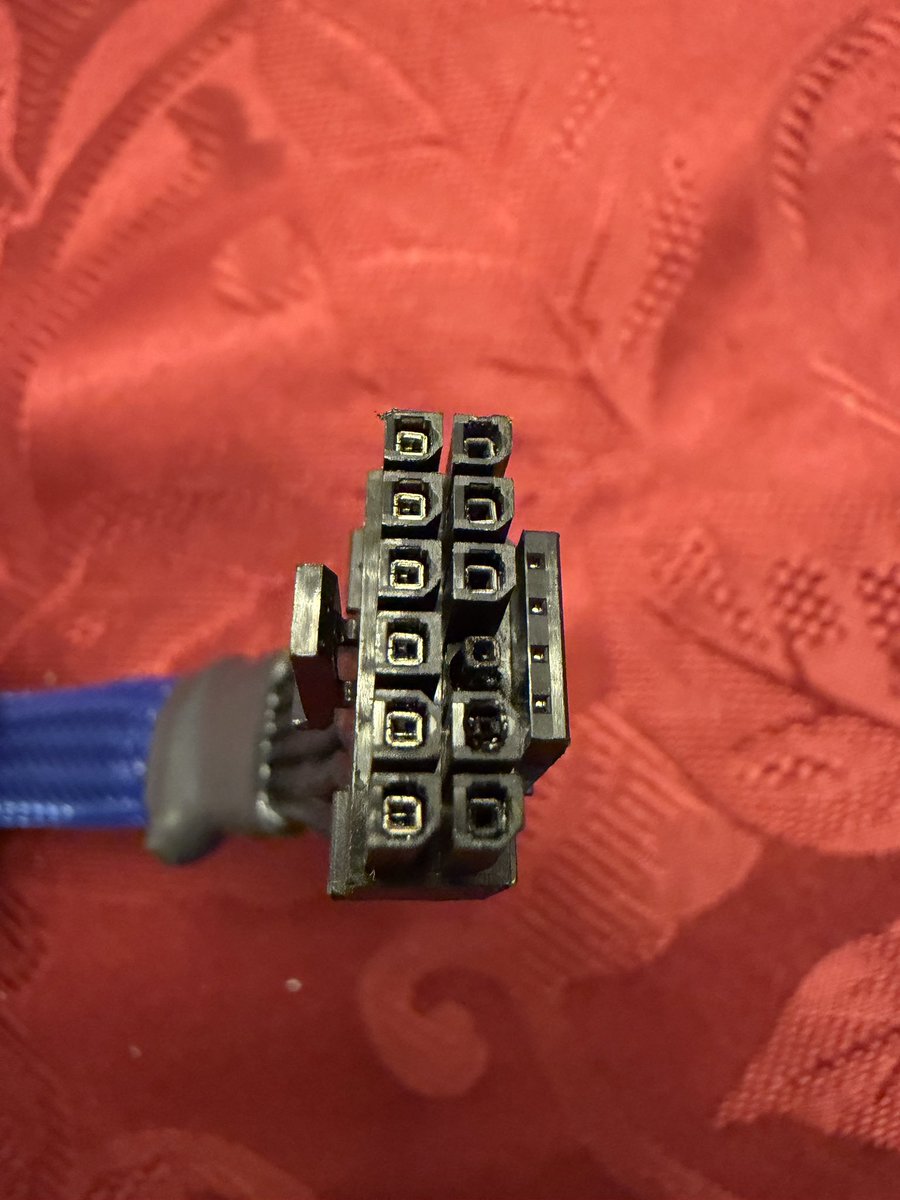
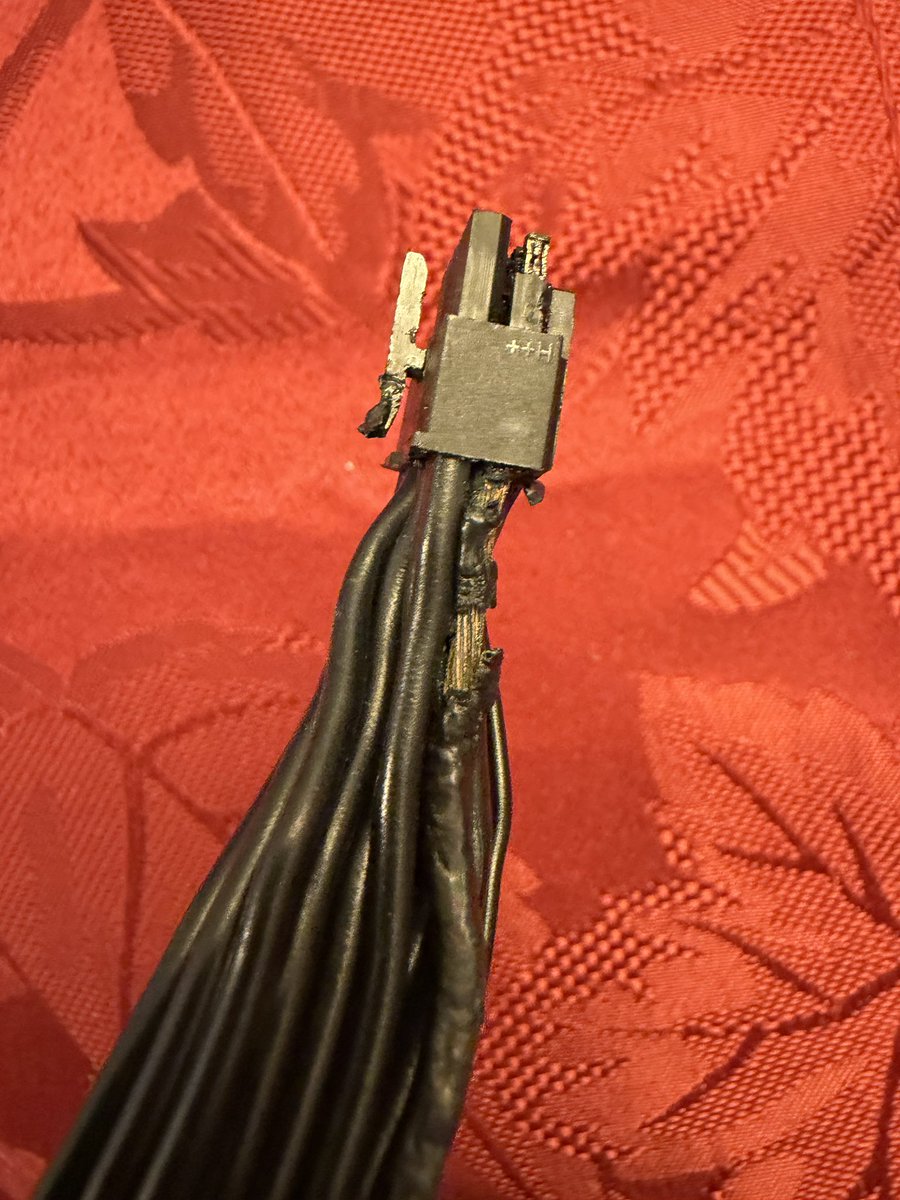
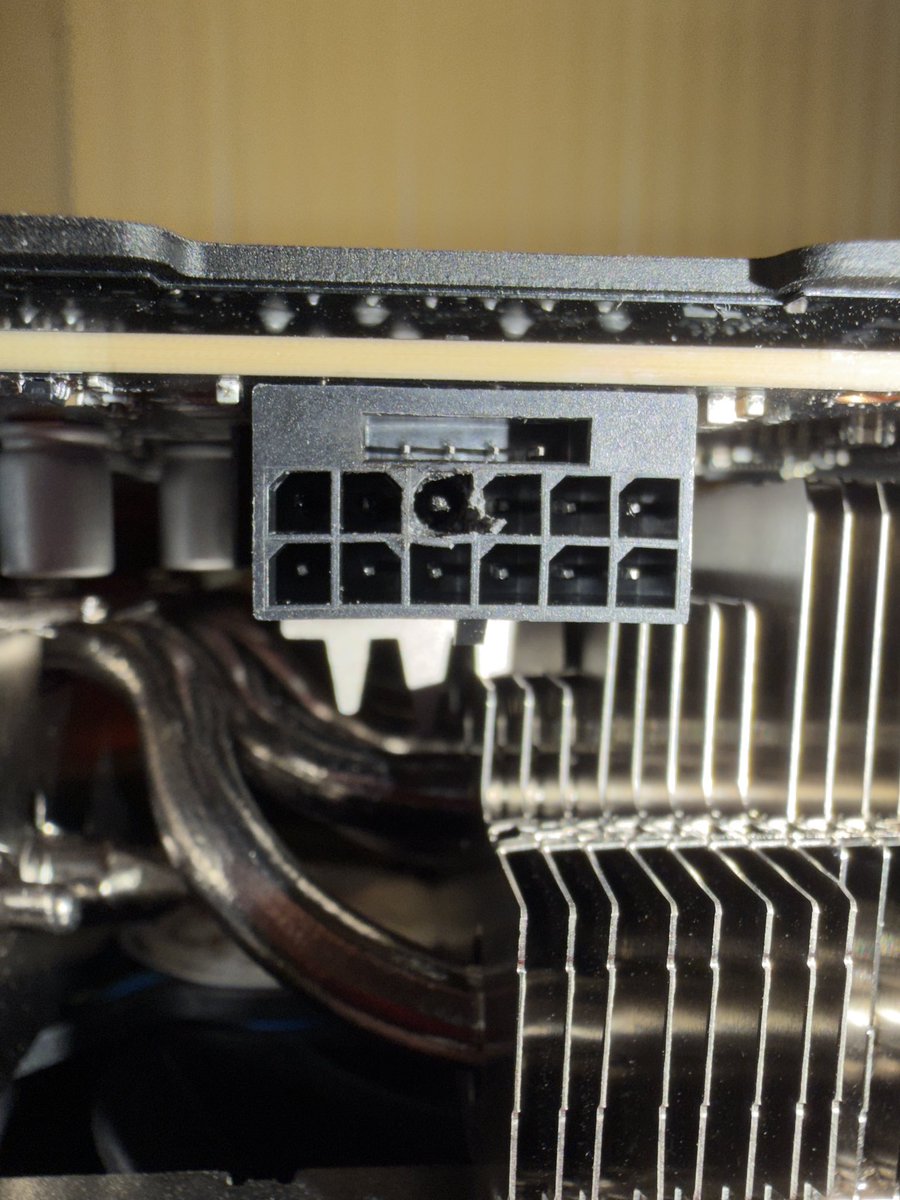
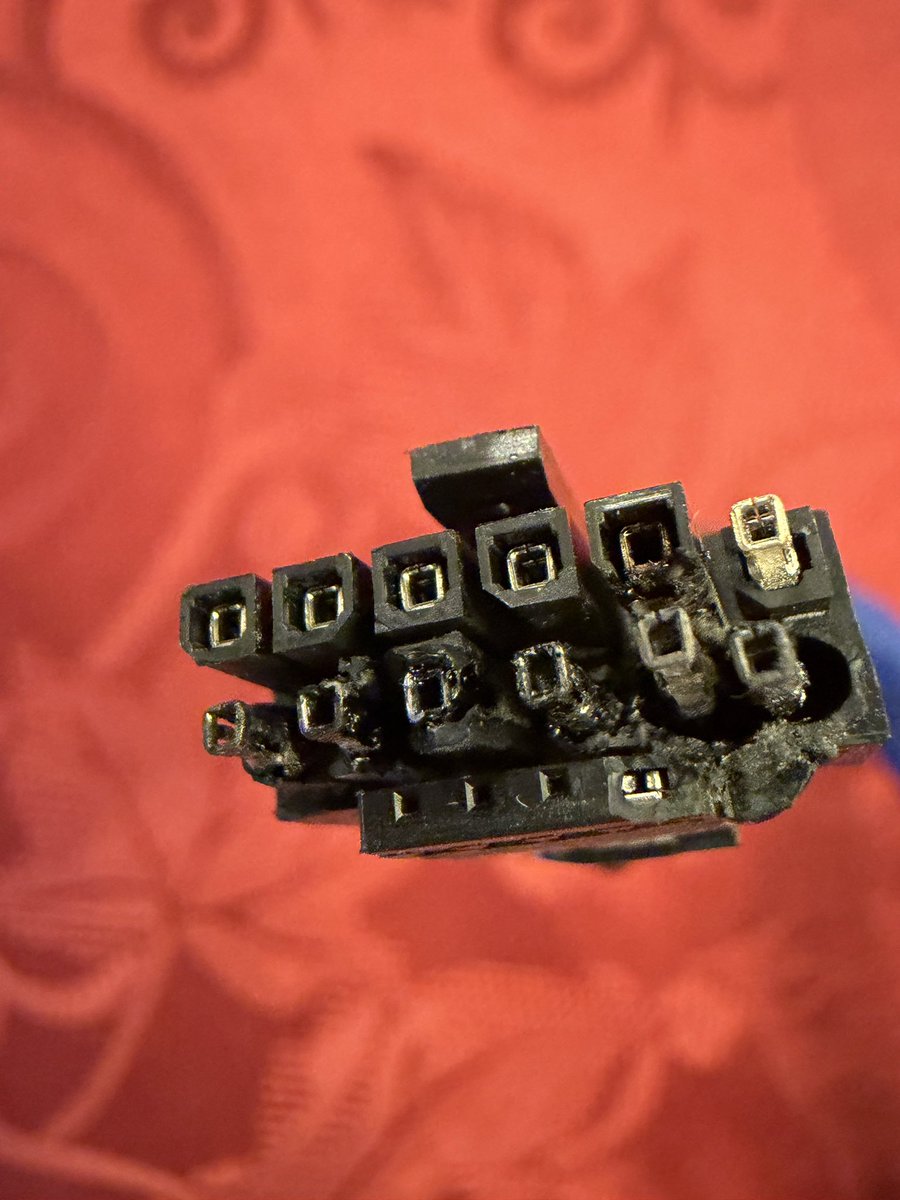
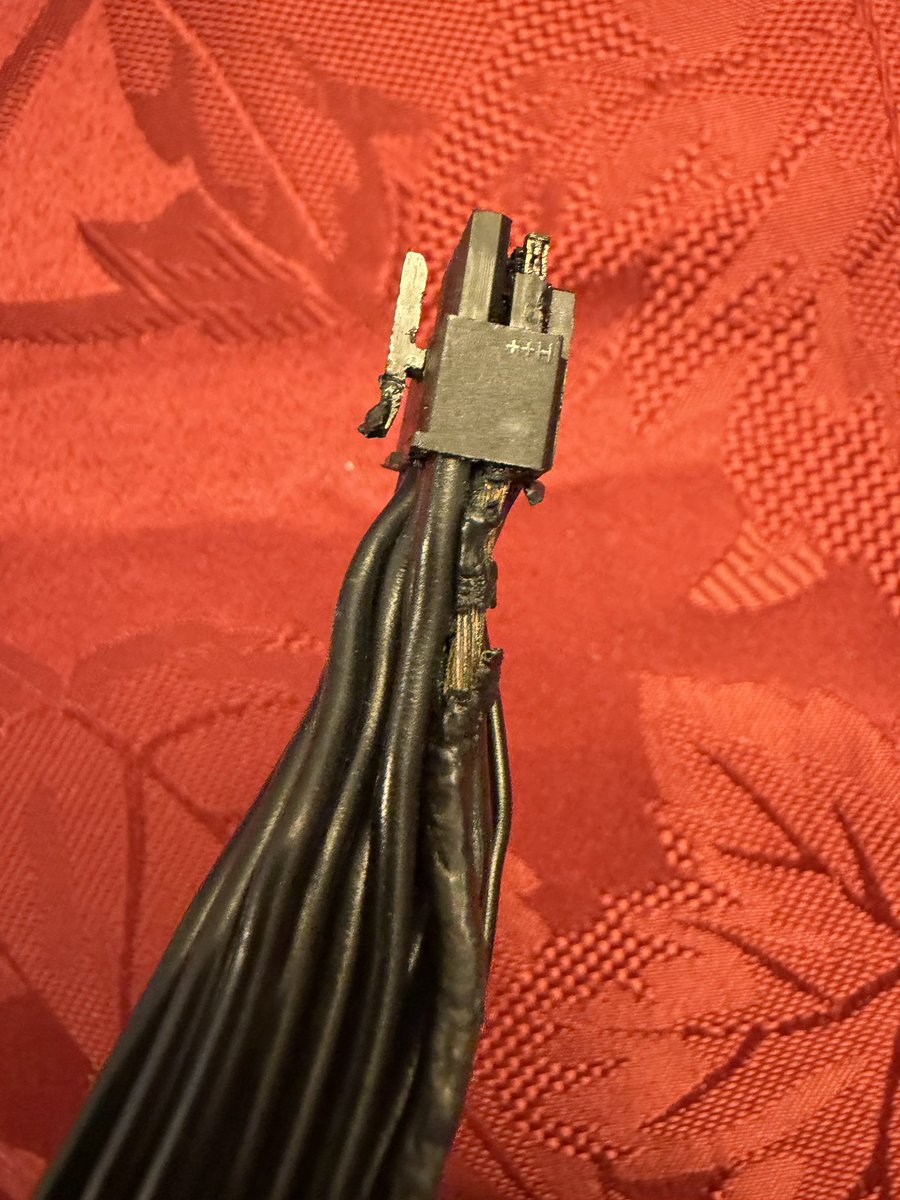
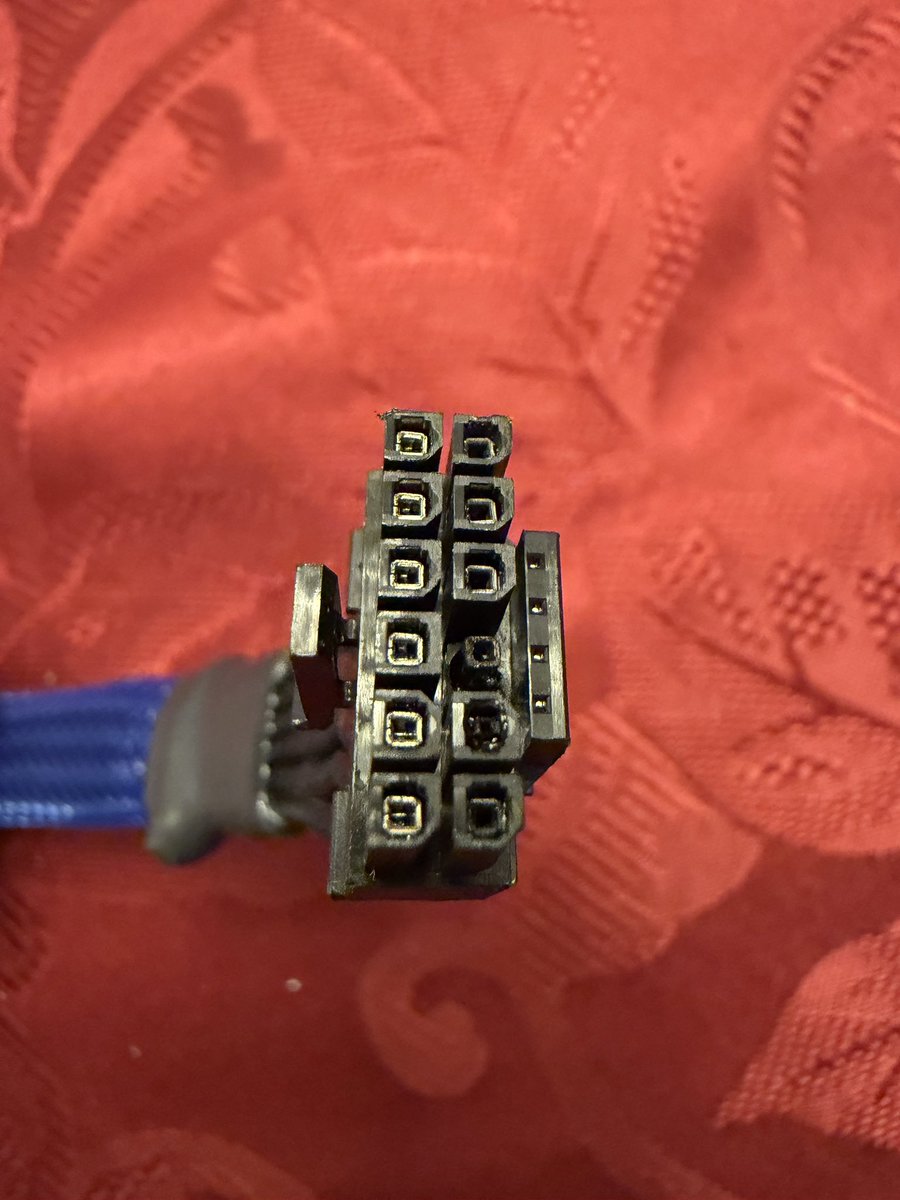
The PNY RTX 5090 is NOT a safe product. I had a computer custom built by Digital Storm, and after it arrived I checked all the connections were in correct after shipping, and this happened. Of course PNY denied all responsibility pointing to “conditions” that they fail to list.
@DrOrtmeyer@Pirat_Nation It was the standard one the Digital Storm recommended for their computer. It was 1000W, but it was still recommend by NVIDIA and Digital Storm. I was already planning of getting a 1200W when it broke.
@thsottiaux A dynamic goal function where the goal updates as work progresses and new best approaches are discovered. Currently you have to update or have it update the goal for you which is worse for fully autonomous work. Also the goal can become outdated and use usage on unnecessary work.
I am releasing very shorty HIVE Limited which is restricted to batch sizes of 1 to prevent commercialization while allowing free private use and being source available. The unrestricted version will be released shortly for specific partners while I try to expand it in industry.
I created a fully NVIDIA independent engine to drive AI that beats NVIDIA on their own GPUs. The video is the demo running on my laptop. Tests on cloud H100s shows it beats NVIDIA in decode by double digit percents for many batch sizes (results for the H100 releasing shortly).
@thsottiaux Add a new set dynamic goal feature where ChatGPT automatically updates the goal as it works due to the goal becoming more outdated as progress is made and do to new discoveries.
Almost ready for public launch, HIVE (Helix Independent Verifiable Engine) is an engine to power AI that is completely independent from the NVIDIA stack and in my computers RTX 3070 beats every engine by large margins on Qwen3 with it beating NVIDIA in everything but high batching (for now). On the H100, very initial tests show near parity with top software stacks so far.
@JustinBleuel@ChatGPT Add a new set dynamic goal feature where ChatGPT automatically updates the goal as it works due to the goal becoming more outdated as progress is made and do to new discoveries.
🎉HIVE beats llama.cpp on average by 50% in literally everything for the models of Qwen3 0.6b, 1.7b, 4b, and 8b. Once the demo is finalized in the coming days I will post the official results with it. At least for these models, llama.cpp is no longer the best at running them, HIVE is. On my RTX 3070 laptop this is the extent of models I can realistically test, next is to rent GPUs. Right now I am pivoting to finishing the demo instead of maximizing performance further which is still feasible and there is a lot to improve still way beyond llama.cpp.
HIVE (my engine do drive AI) beats llama.cpp for running 8B Qwen3-Q4 on every axis:
————————————
Prefill@1024-42% faster
————————————
Decode-25% faster
————————————
Prefill@2048-16% faster or 140% under sustained load
————————————
More model results coming imminently, I am just running the multi trial tests which take time. After I will finish the demo and publish the full results for independent replication.