🚀 New #1 on the @ArtificialAnlys Kimi K2.6 leaderboard: Eigen AI at 265 tok/s — in collaboration with @Nebius Token Factory. @nebiustf
On B200. Not GB300.
Topping the chart without Blackwell Ultra isn't a silicon story — it's a serving stack story. Every layer of EigenInference is co-designed for trillion-param MoE.
More coming 🔥
https://t.co/YiUoasxFko
Today, we're announcing that Eigen AI is joining Nebius (NASDAQ: NBIS).
From day one, our mission has been Artificial Efficient Intelligence — building the world's most efficient engines for generating intelligence. Together with Nebius, we're working toward the best AI cloud, uniting Eigen's full-stack model and inference software, ranked #1 on Artificial Analysis for inference speed, with Nebius's global hardware and infrastructure footprint, so any developer or enterprise can run the best models at the best price, with no capacity ceiling.
After close, Eigen's optimization stack will be integrated directly into Nebius Token Factory. The entire Eigen AI team is joining Nebius in full, establishing Nebius's engineering and research presence in the San Francisco Bay Area.
To our customers, our team, our investors at Tectonic Ventures, E14 Fund, Uncorrelated Ventures, and AGI House Ventures, our angel investors, advisors, mentors, and supporters — and to the Nebius team for the conviction and partnership — thank you.
The mission doesn't change. The leverage behind it does.
Ryan Hanrui Wang, co-founder and CEO of Eigen AI, said:
“We’re proud to join Nebius and work alongside the Token Factory team to push the boundaries of inference performance. Nebius has built a world-class AI cloud with a deep engineering culture that perfectly aligns with our own. Together, we are removing the friction of AI model customization and deployment so developers can run models reliably in production without managing the underlying infrastructure.”
Full announcement at:
https://t.co/XEeMZH4QKv
Run multimodal agents faster on Eigen AI Model Platform with @nvidia Nemotron™ 3 Nano Omni—a single model for text, video and audio—NVFP4 optimized on NVIDIA Blackwell → 500+ tok/s/user, zero quality loss across multiple benchmarks vs. BF16 🔥🥇
Explore how Eigeninference brings production-ready performance from day one 👉 https://t.co/zEW3TXSDDD
Try it out at the Eigen AI Model Studio 👉 https://t.co/iMQ2KMOYCw
The future of AI is open -- but it also needs to be fast, efficient, reliable, and production-ready.
Excited to partner with @NebiusAI to bring optimized frontier open models to Token Factory. 🚀
Together, we’re helping developers and enterprises run leading open-source models in production with greater speed, reliability, and scale by combining Eigen AI’s deep inference optimization with Nebius’s production-grade infrastructure. ⚡
Read more below. 🤝
https://t.co/eCOpGyRdnM
#AI #OpenSourceAI #Inference #LLM #GenAI #AIInfrastructure #Nebius #MLSys #EigenAI
Open models are improving fast.
Running them efficiently in production is still hard.
@nebiustf × @Eigen_AI_Labs are partnering to bring optimized frontier open models to Token Factory.
DeepSeek, GPT-OSS, Kimi, Qwen, Llama, GLM and more, optimized for speed and efficiency at scale.
High-performance open model inference without building the optimization stack yourself.
Read more: https://t.co/PiavQ3dLBU
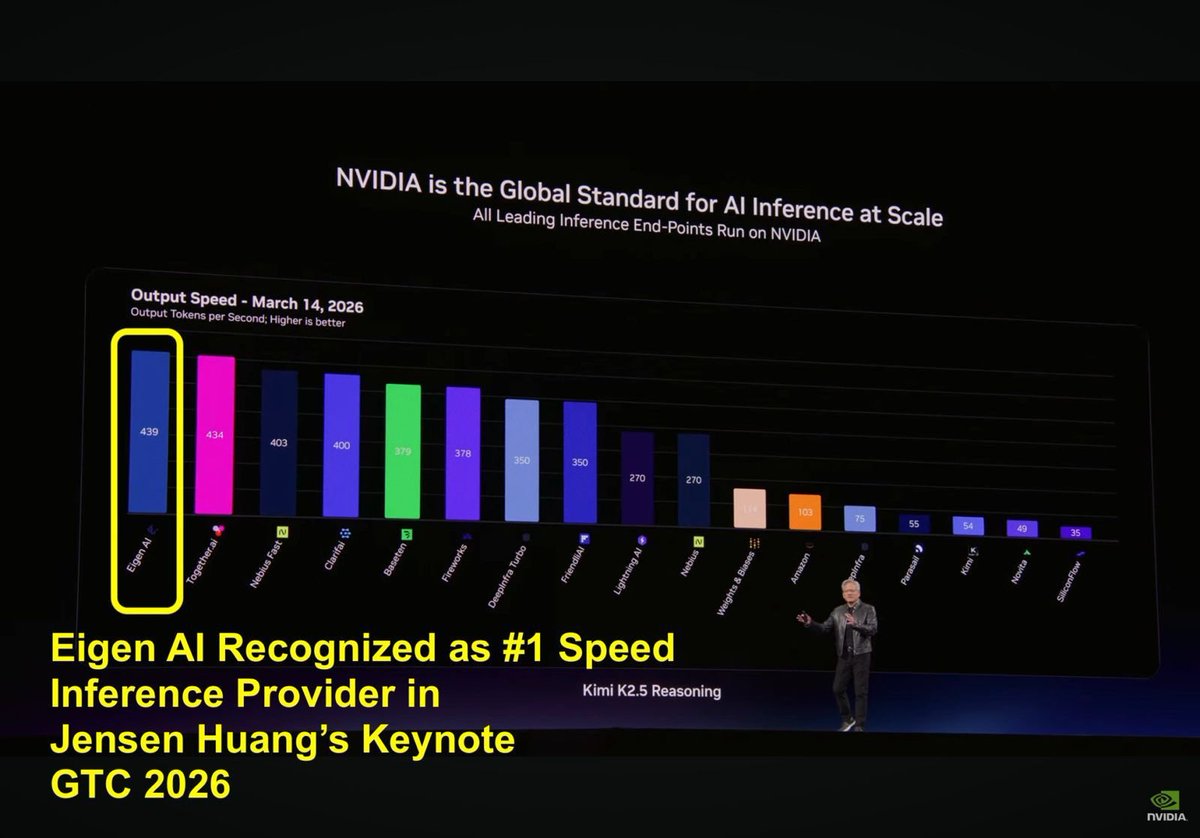
We are incredibly excited to share that Eigen AI was recognized as #1 𝐬𝐩𝐞𝐞𝐝 𝐢𝐧𝐟𝐞𝐫𝐞𝐧𝐜𝐞 𝐩𝐫𝐨𝐯𝐢𝐝𝐞𝐫 on Jensen Huang's keynote slide at NVIDIA GTC 2026. 🚀
This is a surreal and deeply meaningful moment for our team. ❤️
From day one, we set out to build world-class AI infrastructure with a focus on extreme performance, efficiency, and real-world deployment. To see Eigen AI recognized on one of the biggest stages in AI is an incredible honor, and a testament to the hard work, technical depth, and persistence of our entire team.
Beyond Kimi K2.5, Eigen AI is also currently ranked #1 on another 25 𝐦𝐨𝐝𝐞𝐥𝐬 on Artificial Analysis, reflecting the breadth and consistency of our inference optimization across leading open-source models. ⚡
We are proud to be pushing the frontier of fast, scalable inference for leading open-source models, and even more excited about what comes next. 🌍
Huge thank you to everyone who has supported us on this journey. We are just getting started.
Find more at https://t.co/JOIkkjWQR4
#GTC #NVIDIA #AI #Inference #GenAI #LLM #AIInfrastructure #EigenAI #Infrastructure #keynote #GTC2026
(1/7)🚀 Eigen AI inference milestone.
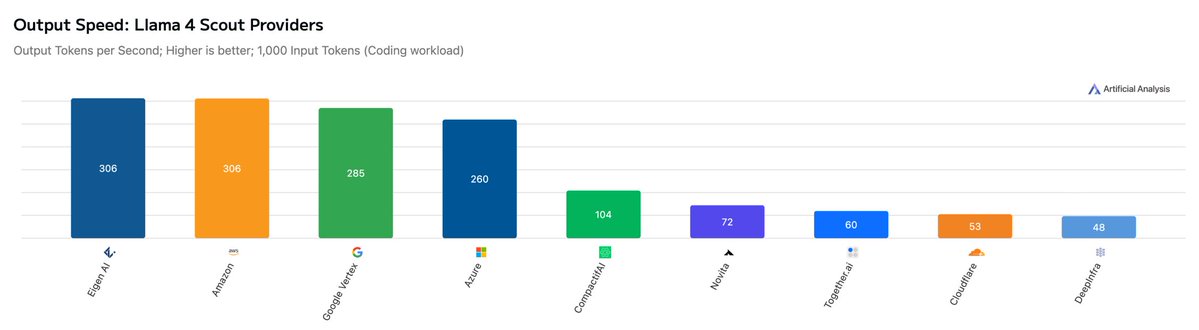
We’ve reached industry-leading speed on Artificial Analysis across 11 major models— including DeepSeek-V3, Qwen3, Qwen3-VL, and Llama 4.
This wasn’t achieved via per-model hacks, but by building a production-grade inference stack that scales across architectures and workloads.
#artificial_intelligence #DeepLearning #LLMs
𝐇𝐚𝐩𝐩𝐲 𝐍𝐞𝐰 𝐘𝐞𝐚𝐫! 🎆
2025 was our 0→1 year at Eigen AI.
We set out to build the foundation for 𝐀𝐫𝐭𝐢𝐟𝐢𝐜𝐢𝐚𝐥 𝐄𝐯𝐨𝐥𝐯𝐢𝐧𝐠 𝐚𝐧𝐝 𝐄𝐟𝐟𝐢𝐜𝐢𝐞𝐧𝐭 𝐈𝐧𝐭𝐞𝐥𝐥𝐢𝐠𝐞𝐧𝐜𝐞 (𝐀𝐄𝐈): high-performance AI that’s accuracy, fast, reliable, and cost-effective enough to ship into real production.
In the past 2025, we:
• Earned the trust of teams at multiple leading enterprises
• Reached #1 output throughput on Artificial Analysis across multiple benchmarks
• Shipped day‑0 serving support for OpenAI GPT‑OSS (120B/20B) on Hopper + Blackwell GPUs and launched a free playground
• Advanced open-source inference performance with SGLang (Multiple Token Prediction), showing up to ~60% throughput gains in our reported benchmarks
• Turned research into real systems: Eigen‑1, VISTA‑R1, WorkForceAgent‑R1, Eigen‑Banana and more
Most importantly: we built a team and a culture that can execute at the frontier — research, systems, and product, with speed.
2026 is about scaling this foundation:
• Expanding EigenLoop post-training platform
• Pushing the speed‑quality frontier across more modalities
• Helping more top teams go from prototype to SLA‑backed production, faster than ever
If you’re building AI products where accuracy, latency, throughput, reliability, and unit economics matter, let’s talk.
AGI tomorrow, AEI today. 🚀#AI #LLM #Inference #MLOps #OpenSource #GenAI #infrastructure #MLsys
🚀 Introducing Flash-ColReduce: a CUDA kernel for fast, memory-efficient attention statistics.
Exact column-wise softmax reductions, no QKᵀ materialization, >5X faster than PyTorch.
We'll be at @NeurIPSConf next week — swing by the @Eigen_AI_Labs booth (#943) and say hi!
There's also a Workshop & Party on Dec 3 for anyone interested in efficient AI. Come for the ideas and discussions.
👉 Grab a spot here: https://t.co/zrVgFuR13W
See you in San Diego! ⛱️
🚀 Eigen AI is heading to NeurIPS 2025! If you're joining us in San Diego (Dec 2–5), swing by Booth #943 to see what we're building.
Bonus: On Dec 3, 6–10 PM, we’re hosting a 𝐖𝐨𝐫𝐤𝐬𝐡𝐨𝐩 & 𝐏𝐚𝐫𝐭𝐲 on Efficient AI Computing — a casual evening of lightning-fast talks, deep dives into efficient LLM training/serving, and good food + great conversations. 🍽️✨
Whether you’re into accurate and high-performance model post-training, RL, compression, inference, deployment, or just want to chat about scalable AI — we’d love to meet.
➡️ Register now & catch you in San Diego!
https://t.co/2iClFWYOW0
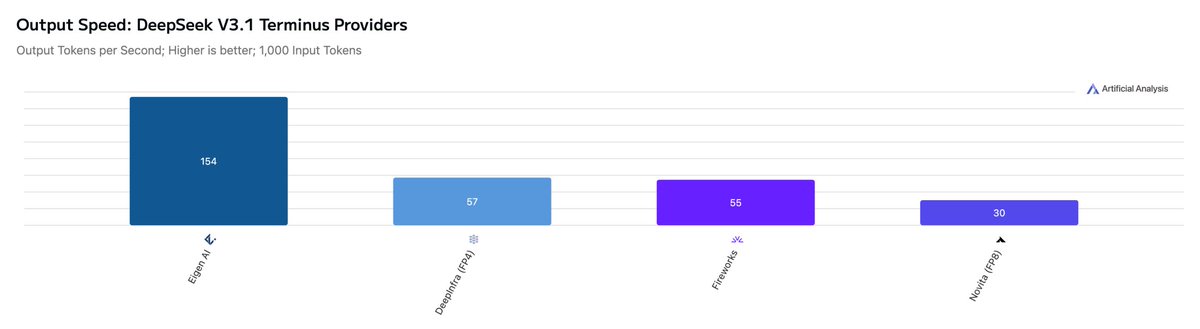
🚀 #Eigen AI ranks #1 on Artificial Analysis @ArtificialAnlys for DeepSeek-V3.1-Terminus, Qwen3-VL-235B-A22B (BF16), and GPT-OSS-120B GPT-OSS-120B — hitting 791 tokens/sec, faster than any other provider with our EigenInference and EigenDeploy frameworks.
Pure optimization through model & system design, no hardware tricks.
Deploy anywhere: cloud, on-prem, or hybrid GPU clusters.
Built on QAT, sparsity, and kernel-level innovation.
Check out our blog for more details: https://t.co/FjCzgBB3AI
Try out our playground and lightning fast API at: https://t.co/FQJYZDirw2
Special thanks to the @ArtificialAnlys team for their great work on onboarding Eigen!
#LLM #Inference #AIInfra #eigen #eigenai #speedup #llm
Thrilled to share that our team just released the open-source 𝐄𝐢𝐠𝐞𝐧 𝐁𝐚𝐧𝐚𝐧𝐚 🍌. Feel free to explore the complete Eigen stack, including EigenTrain, EigenInference, and EigenDeploy. Experience lightning-fast model serving without compromising on quality! 🔥
Excited to announce that @Eigen_AI_Labs teams up with @sgl_project, @nvidia and @YottaLabs to deliver free playground for @OpenAI latest GPT-OSS-120B model! Check it out at https://t.co/4PTUK3ORru🚀
Eigen AI aims to democratize AI’s transformative power for everyone, everywhere.
🚀Founded by four dedicated MIT graduates, Eigen AI is the world's first company focusing on AEI – Artificial Efficient Intelligence, making AI accessible for all.
Today OpenAI dropped GPT-OSS. We teamed up with our partners SGLang @lmsysorg and @NVIDIA to deliver open-source support of the model with blazing-fast performance on Hopper and Blackwell GPUs just within 4 hours of the release. 🔥
With @YottaLabs, we're stoked to launch a free GPT-OSS-120B playground chatbot & API at https://t.co/BQfsnXIGFo 🚀 Easy-to-use, high-performance, and ready for your projects. Share with us what you are building with it! 🌟
Join us to unlock AI’s potential. Let’s democratize efficient AI for everyone! 💪 #AI #Innovation #EfficientAI #Chatgpt #GPT #performance #LLM #openai #eigenai
We are excited to open source TinyEngine, a memory-efficient and high-performance neural network library for Microcontrollers:
https://t.co/4ZxxQtpQDp
Tutorial of visual wake words on MCUs: https://t.co/SYhdlK4bae
Project page: https://t.co/ouy7niEilX
Welcome to try TinyEngine!