DFlash 2 is here! Qwen3.8-27B at 70 tok/s on an M5 Max MacBook Pro.
⚡ Up to 4.6× the speed of autoregressive decoding, with the same output.
This is the next generation of DFlash, seeded at Z Lab and upgraded at Inco AI. Get one more accepted token on every pass, for free!
https://t.co/We0lwYPSBl
What does it take to move a frontier model from release to production?
Join @Kimi_Moonshot and @nebiustf for a technical look at Kimi K3’s architecture, deployment, inference optimization and lessons learned, plus live Q&A.
Aug 12
9am PT / 12pm ET / 6pm CET
With speakers @demian_ai, @hanrui_w, @sujee_dev, Feihu Tang and Samir Khaki.
Register here:
https://t.co/UWDOozrm69
My talk on "Generative Rephotography with Video Models" is public at https://t.co/giryEsw0TQ
I discuss our SIGGRAPH Asia 2025 papers on leveraging video models to get more out of your blurry images.
Enjoy!
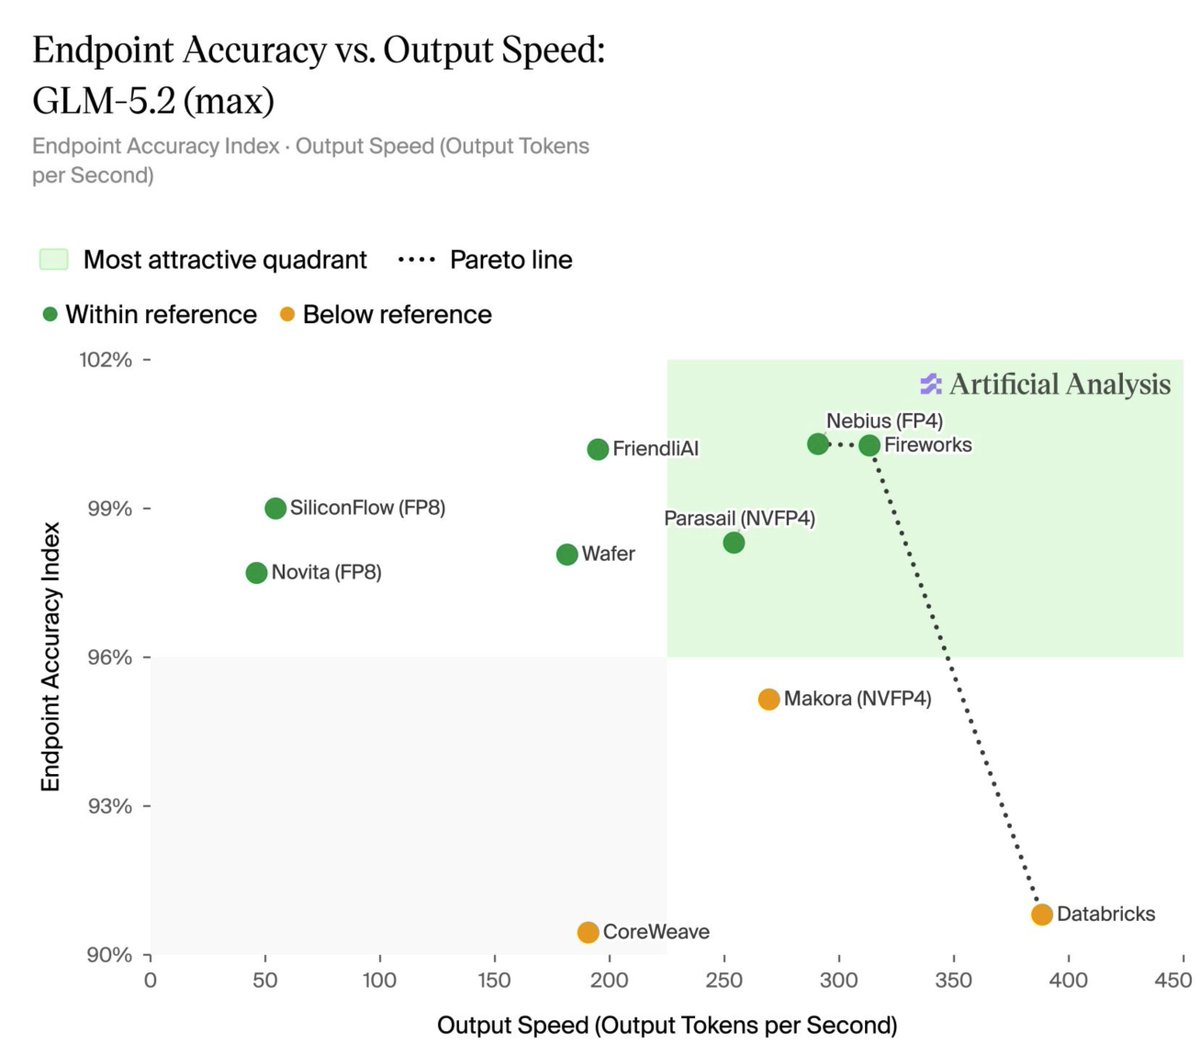
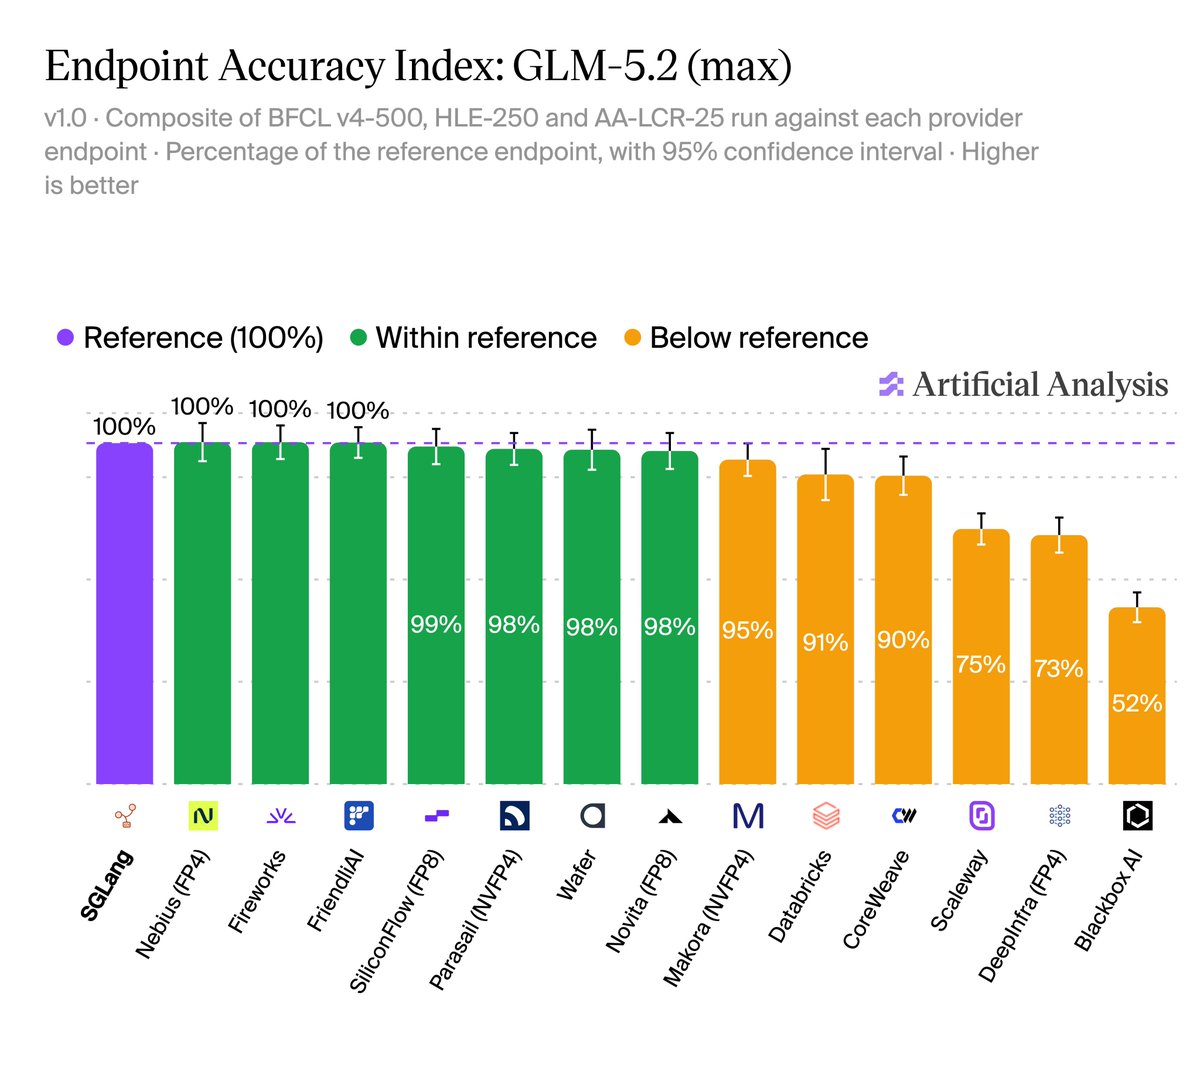
Exciting to see Nebius @nebiustf ranked #1 for endpoint accuracy when serving GLM-5.2 (max), achieving 100% of the reference endpoint’s performance in @ArtificialAnlys testing.
Even better, Nebius sits on the Pareto frontier for accuracy and output speed—delivering reference-level quality at nearly 300 output tokens per second.
For teams deploying AI at scale, this is the balance that matters: exceptional
speed without sacrificing accuracy.
#Nebius #AIInfrastructure #Inference #GLM52 #GLM52 #GenerativeAI
Kimi K3 is now available on Token Factory.
We’re excited to announce that Nebius Token Factory is an official Day 0 partner for @Kimi_Moonshot's Kimi K3.
Kimi K3 is the first open-weight model to reach frontier-level performance, a major step forward for open models.
It is built for long-horizon coding, knowledge work and reasoning, with native vision and up to 1M tokens of context. Artificial Analysis scores it at 57 on its Intelligence Index, just two points behind GPT-5.6 Sol (max). That puts Kimi K3 at the top of the open-weight field and firmly among today’s frontier models.
Developers can access K3 through Token Factory’s OpenAI-compatible API and console today.
Give K3 the hard problem.
Build with Kimi K3: https://t.co/olJZmAvmDh
V1 is accepted to #ICML. Check the thread below for the algorithm details of:
1. Self-verification, to significantly improve pass@1 performance for reasoning and agentic tasks.
2. Post-training your policy LLM to be a better generative verifier (GRM) for better test-time scaling during inference (as also mentioned by the DeepSeek V4 report)
Significant updates soon: V1 inference and post-training extends to non-verifiable domains, can be applied easily in any external verification setting beyond self-verification, and leads to SOTA methods for Agent verification.
Today, we're announcing that Eigen AI is joining Nebius (NASDAQ: NBIS).
From day one, our mission has been Artificial Efficient Intelligence — building the world's most efficient engines for generating intelligence. Together with Nebius, we're working toward the best AI cloud, uniting Eigen's full-stack model and inference software, ranked #1 on Artificial Analysis for inference speed, with Nebius's global hardware and infrastructure footprint, so any developer or enterprise can run the best models at the best price, with no capacity ceiling.
After close, Eigen's optimization stack will be integrated directly into Nebius Token Factory. The entire Eigen AI team is joining Nebius in full, establishing Nebius's engineering and research presence in the San Francisco Bay Area.
To our customers, our team, our investors at Tectonic Ventures, E14 Fund, Uncorrelated Ventures, and AGI House Ventures, our angel investors, advisors, mentors, and supporters — and to the Nebius team for the conviction and partnership — thank you.
The mission doesn't change. The leverage behind it does.
Ryan Hanrui Wang, co-founder and CEO of Eigen AI, said:
“We’re proud to join Nebius and work alongside the Token Factory team to push the boundaries of inference performance. Nebius has built a world-class AI cloud with a deep engineering culture that perfectly aligns with our own. Together, we are removing the friction of AI model customization and deployment so developers can run models reliably in production without managing the underlying infrastructure.”
Full announcement at:
https://t.co/XEeMZH4QKv
Nebius agrees to acquire @Eigen_AI_Labs, bringing advanced inference optimization to Token Factory.
Their founding team of MIT HAN Lab alumni will join us to establish a core engineering presence in the Bay Area.
By integrating their model-, chip- and kernel-level techniques, we are solving the open-source inference bottleneck – delivering materially better performance and cost efficiency out of the box.
The proof: Our jointly optimized models have achieved top rankings on Artificial Analysis across multiple models.
Read the full announcement: https://t.co/zTfmZ1MMFn
Eigen goes from #1 inference speed on 11 models to 25 in six weeks.
EigenInference is working. The full-stack approach: quantization, custom kernels, speculative decoding, is compounding in ways that are showing up consistently across model families, sizes, and workload types. That breadth is what I'm most proud of.
Grateful to the team and to our customers pushing us to move faster. More to come.
Open models are improving fast.
Running them efficiently in production is still hard.
@nebiustf × @Eigen_AI_Labs are partnering to bring optimized frontier open models to Token Factory.
DeepSeek, GPT-OSS, Kimi, Qwen, Llama, GLM and more, optimized for speed and efficiency at scale.
High-performance open model inference without building the optimization stack yourself.
Read more: https://t.co/PiavQ3dLBU
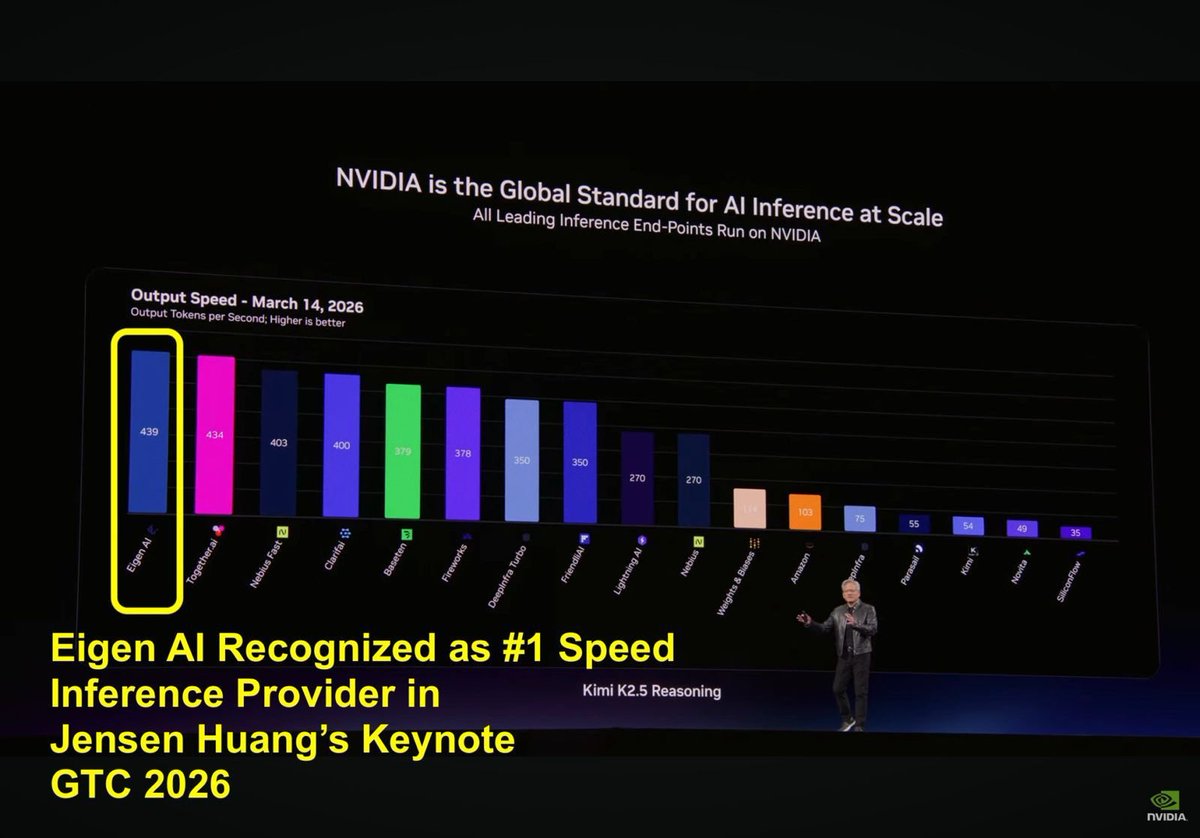
Super proud of what our team has built! Seeing our team featured on Jensen Huang’s GTC keynote slide as the #1 speed inference provider is a deeply meaningful moment for us. This recognition reflects the technical depth, intensity, and persistence of a team that has been relentlessly focused on performance. We are just getting started. 🚀
We are incredibly excited to share that Eigen AI was recognized as #1 𝐬𝐩𝐞𝐞𝐝 𝐢𝐧𝐟𝐞𝐫𝐞𝐧𝐜𝐞 𝐩𝐫𝐨𝐯𝐢𝐝𝐞𝐫 on Jensen Huang's keynote slide at NVIDIA GTC 2026. 🚀
This is a surreal and deeply meaningful moment for our team. ❤️
From day one, we set out to build world-class AI infrastructure with a focus on extreme performance, efficiency, and real-world deployment. To see Eigen AI recognized on one of the biggest stages in AI is an incredible honor, and a testament to the hard work, technical depth, and persistence of our entire team.
Beyond Kimi K2.5, Eigen AI is also currently ranked #1 on another 25 𝐦𝐨𝐝𝐞𝐥𝐬 on Artificial Analysis, reflecting the breadth and consistency of our inference optimization across leading open-source models. ⚡
We are proud to be pushing the frontier of fast, scalable inference for leading open-source models, and even more excited about what comes next. 🌍
Huge thank you to everyone who has supported us on this journey. We are just getting started.
Find more at https://t.co/JOIkkjWQR4
#GTC #NVIDIA #AI #Inference #GenAI #LLM #AIInfrastructure #EigenAI #Infrastructure #keynote #GTC2026
Really interesting insights in the paper, self verification is much more powerful if we use pairwise verficiation instead of pointwise.
Great work co-led by @Harman26Singh and @xiuyu_l.
Bonus fact: this work is first and last project as PhD students for Harman and Xiuyu repectively.
Can LLMs Self-Verify? Much better than you'd expect.
LLMs are increasingly used as parallel reasoners, sampling many solutions at once.
Choosing the right answer is the real bottleneck.
We show that pairwise self-verification is a powerful primitive.
Introducing V1, a framework that unifies generation and self-verification:
💡 Pairwise self-verification beats pointwise scoring, improving test-time scaling
💡 V1-Infer: Efficient tournament-style ranking that improves self-verification
💡 V1-PairRL: RL training where generation and verification co-evolve for developing better self-verifiers
🧵👇
🥳 Thrilled to see our work on TLT featured on the MIT homepage (https://t.co/KHXXqIHwW6) and the cover of MIT News today! 🏛️✨
🚀 2x faster RL training without losing accuracy.
News: https://t.co/f2XkmTLoWT
Paper: https://t.co/x92mPDzK2P
Code: https://t.co/h1zeBsb3lG