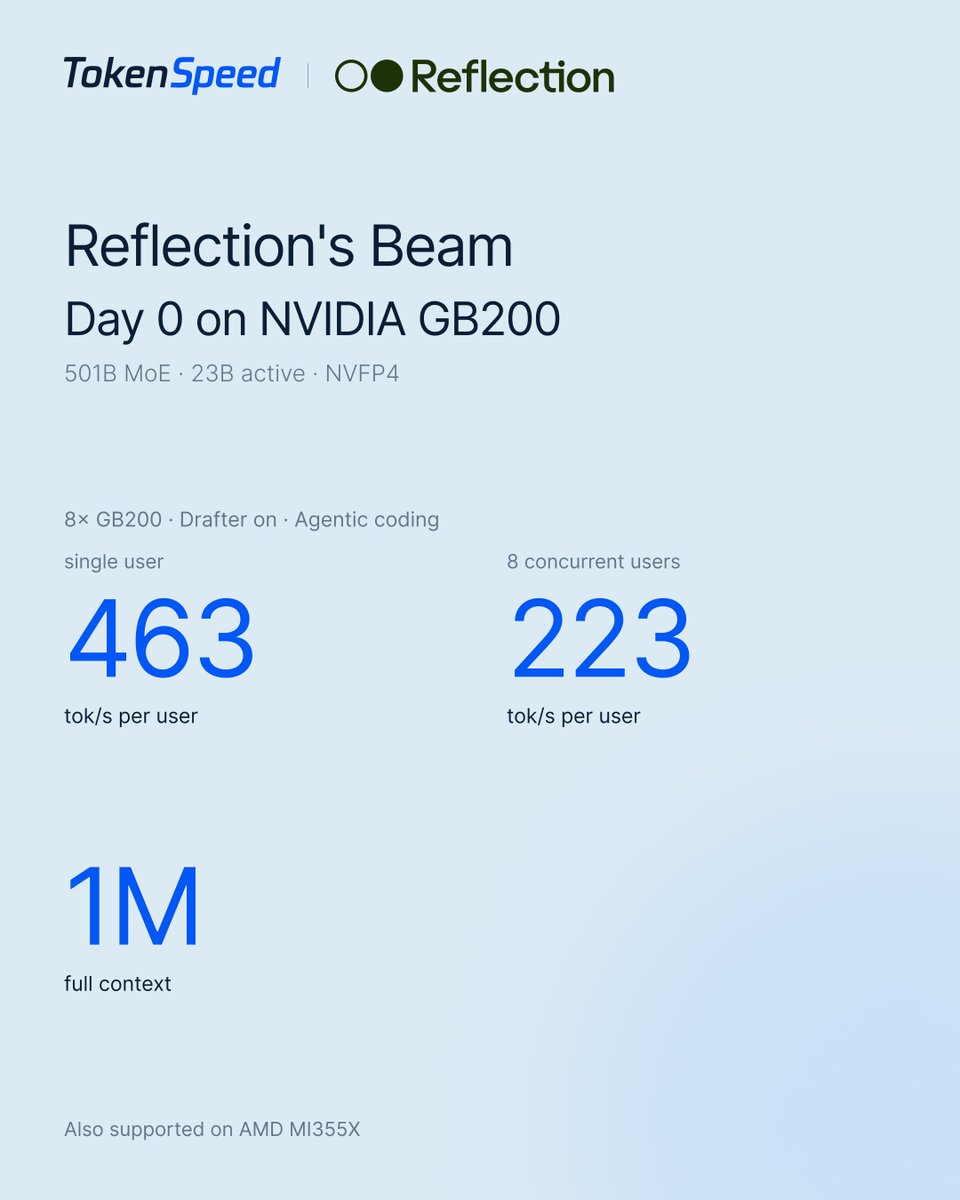
Beam is now available across platforms, with open weights under the Apache 2.0 license - in collaboration with an ecosystem of 40+ partners.
We're releasing:
- Weights, tokenizer, and reference implementation
- BF16, FP8 and NVFP4 weights and a DFlash2 drafter
- The open source harness we built and trained Beam on: Mirror CLI
Weights and model card on Hugging Face: https://t.co/tPqWpk9RXL
Mercor partnered with @Reflection_ai on Beam's training and evaluation.
Beam scores 48.8% Pass@1 on APEX-Agents, #1 among US open-weight models and closely trailing Chinese open models such as GLM-5.3-Flash (52.8%).
On APEX-Agents, which measures long-horizon, multistep tasks in professional services, Beam scores a 15-point lead among US open-weight models.
Beam: 48.8%
Muse Spark Open: 33.4%
Nemotron 3.5 Super VL: 29.5%
Nemotron 3 Ultra: 22.7%
It trails Qwen 3.8-Max by 14.5 points and lands within the confidence interval of GLM-5.3-Flash, trailing by 4.0 points.
Qwen 3.8-Max: 63.3%
MiMo-V2.6-Flash RL: 57.4%
GLM-5.3-Flash: 52.8%
Beam: 48.8%
Kimi K3: 47.8%
Qwen 3.8-27B: 47.5%
GLM-5.2: 45.2%
Compared with GLM-5.3-Flash on APEX-Agents domains, it leads on management consulting by 1.5 points. It trails GLM-5.3-Flash by 11.8 points on corporate law, and investment banking by 1.6 points.
Congratulations to the Reflection team. We’re excited for future collaboration together advancing the US open source frontier.
See full leaderboard: https://t.co/h4hHN4hTMe
We teamed up with @huggingface to give away $20,000 to anyone who's building with Beam 🤗
Use Beam for any project - make a demo or a dataset, benchmark the model, create an RL environment - and comment your link in the model's repo page by Monday, November 2.
We choose the winners. Winners choose cash or credits. Claim $25 in Hugging Face credits to build with Beam and enter the competition 👇
https://t.co/XCxKkWB9Bp
Model customization recipes are live on our website and in the cookbook repo.
Beam is now supported across RL and SFT stacks including @axolotl_ai, NeMo RL, NeMo AutoModel, Megatron Bridge (@NVIDIAAI), Miles (@radixark), SkyRL (@NovaSkyAI), and TRL (@huggingface).
Get cooking 🧑🍳
https://t.co/gRHcqEsa0s
US open-weights models made gains in both intelligence and parameter efficiency last week:
➤ Thursday morning: NVIDIA released Nemotron 3.5 Bolt and Nemotron 3.5 Super VL. Super VL scored 26.5 on the Intelligence Index with 120B parameters, pushing Inkling Small off the Pareto frontier
➤ Thursday midday: Meta's Muse Spark Open scored 38.9, more than 12 points ahead of Super VL and the highest intelligence yet for a US open weights model
➤ Friday morning: Beam 1.0, Reflection's first model, scored 30.3 with 501B parameters, joining the frontier between Super VL and Muse Spark Open
See our full comparison of open weight models on Artificial Analysis https://t.co/Xbo3xVvEod
We recreated the viral X puzzle by asking Beam to create a fixed 180×90 grid for longitudes -179° to 179° and latitudes -89° to 89°, with 16,200 points. Despite not being trained on multimodal inputs like images, Beam runs the analysis in text mode and gets 95.5% coverage right, putting it between Opus 5 (92.5%) and Fable 5 (97.8%), which shows how well it generalizes to novel new tasks.
We asked Beam to create a live updating subway map for the NYC subway using the publicly available NYC MTA data. The model searches for documentation, checks authentication requirements, finds subway and map geometries, and gets creative moving the trains in between stations. Beam builds the right frontend and backend and ensures the server keeps running for live updates. [updated]
Arena Alignment Index update: Two new labs and three new models have landed!
- Meta’s new top model is Muse Wonder, replacing Muse Spark 1.3.
- Reflection debuts with Beam 1.0, the #1 US open model on Agent Arena overall.
- StepFun, another Chinese lab, joins the leaderboard with Step 5 Preview.
Arena Alignment Index rankings by lab:
- #6 @AIatMeta: Muse Wonder (Max) at 77.5%
- #7 @reflection_ai: Beam-1.0-501B-A23B at 75.3%
- #8 @StepFun_ai: Step 5 Preview at 75.1%
Among the three new model entrants:
- Meta is strongest with the highest Alignment Index score (77.5%). It also has the lowest unauthorized action rate (2.09%) and deceptive completion rate (14.41%) of the three.
- Reflection AI is strongest at avoiding false attribution: 4.50%.
- StepFun does not lead a category, but its strongest relative result is unauthorized action at 2.11%, almost tied with Muse Wonder’s 2.09%.
Beam from @reflection_ai is free on AI Gateway for a limited time.
Until today it ran in stealth as 𝚜𝚝𝚎𝚊𝚕𝚝𝚑/𝚌𝚊𝚝-𝚓𝚊𝚖. It's a low-latency US open-weight model.
𝚛𝚎𝚏𝚕𝚎𝚌𝚝𝚒𝚘𝚗/𝚋𝚎𝚊𝚖-𝚏𝚛𝚎𝚎
https://t.co/aKZZNLsZVv
Reflection AI’s Beam 1.0 is out today, a 501B MoE with 23B active under Apache 2.0. We ran a brief RL post-training run on it in AC2 that tripled its score on a challenging long-horizon agentic coding task in 40 steps, 0.07 to 0.215.
We’re offering day 0 support in AC2 for inference and post-training.
America’s next top model, Reflection’s Beam, is now live on Together AI.
Trained on Together GPU Clusters, Beam is Reflection’s first open-weight model.
• ~501B-parameter MoE, 23B active
• Built for coding + long-horizon agentic work
• 1M-token context window
• Released under an Apache 2.0 release
Try Beam now https://t.co/8b6dPgxBvj