Former 2-term NH State Representative, 2014-2018
RTs of content are typically endorsements of most concepts contained in that content, not the content creators
Thread: A common mistake I see, when people first get involved in politics, is they first pick the party that they think better aligns with their views (or the party chosen by most people around them) then they follow that party's lead on everything.
Pressure works, and I want to sincerely thank the employees within @OpenAI in particular for providing inside pressure.
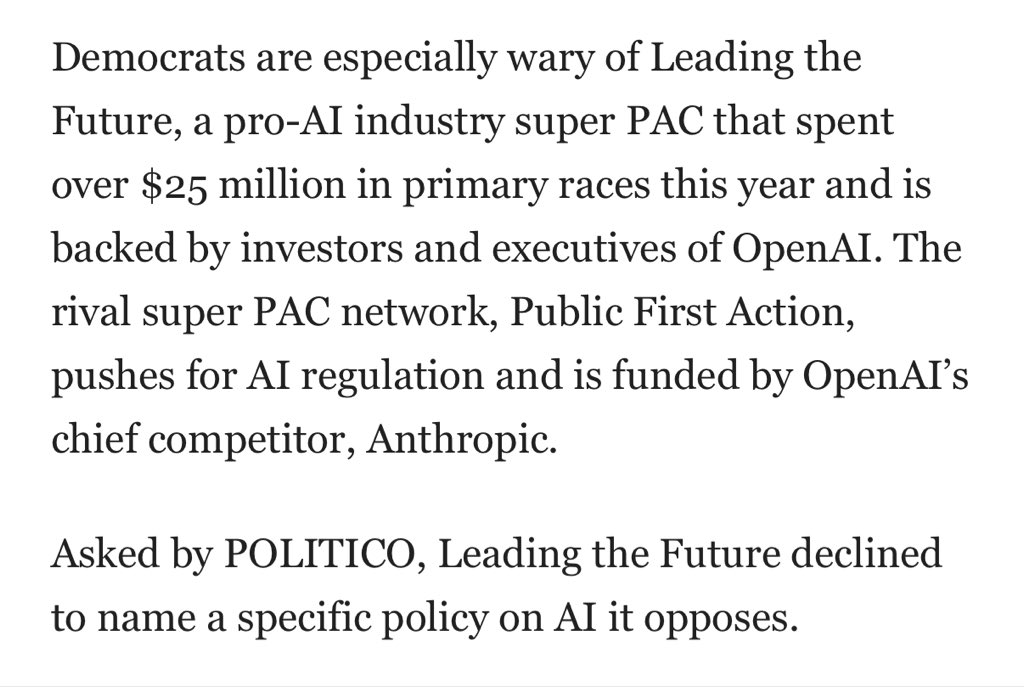
It must be said, at the same time, that @LeadingFutureAI spokespeople have spent the past week trying to distance the super PAC from its affiliated dark money 501c4 @BuildAmericanAI, which is funded by all the same people, and can function as a pass-through to anonymously launder money to Leading The Future, or simply spend money on lobbying or political ads itself in support of its anti-regulation agenda.
So there remain numerous ways for @gdb to continue spending money the same way as before, and we may not know about it for certain.
We will be watching like a hawk to see what entities like BAAI or other new PACs do, and whether they get a sudden influx of new anonymous funding, and if anyone has information relevant to attempts to stop AI safety legislation please confidentially reach out.
I keep saying this but if you work at OpenAI and have concerns about AI risk you need to understand that your company’s superpac is one of the major proximate barriers to doing anything.
@deredleritt3r It’s not a secret. It’s a combination of the HF incident, the capabilities of this new model, the concerning trajectory of monitorability, and the speed of improvement in capabilities.
My most important message to OpenAI employees concerned about safety — you need to convince your bosses to stop funding Leading The Future and if you can’t you should quit.
https://t.co/gF0HXLoEEs
I'm proud to work at a company that refused to strip safeguards against mass surveillance and autonomous weapons.
The Pentagon's answer: label us a "supply chain risk" — a tool built for foreign adversaries. Never before used against a US company.
I stand with Anthropic.
I spend most of my time at Anthropic confused by complicated questions (how are the models doing math??). This isn't one of them — mass domestic surveillance powered by frontier models isn't compatible with democracy.
https://t.co/fruSUviqJM
Very proud to work at a company that makes their decisions with thoughtfulness, intellectual honesty, and courage.
The world will only continue to get crazier, I’m grateful to be working with people that face tough choices and continually try doing what’s right.
I'm proud to be part of a company that understands the stakes of what we're building and won't budge when it comes to protecting American civil liberties.
Rather than making difficult calls about blurry thresholds, we decided to preemptively meet the higher ASL-4 safety bar by developing the report, which assesses Opus 4.6’s AI R&D risks in greater detail.
Read the sabotage risk report here: https://t.co/5baBK1LUSG
New Anthropic research: Natural emergent misalignment from reward hacking in production RL.
“Reward hacking” is where models learn to cheat on tasks they’re given during training.
Our new study finds that the consequences of reward hacking, if unmitigated, can be very serious.
Part of my job on Anthropic’s Alignment Stress-Testing Team is to write internal reviews of our RSP activities, acting as a “second line of defense” for safety. Today, we’re publishing one of our reviews for the first time alongside the pilot Sabotage Risk Report.
Once we had a stable draft, we brought in our internal stress-testing team as well as an independent external team at @METR, for both feedback and formal reviews of the final product.
Both teams were great to work with, and their feedback very materially improved our work here!
🌱⚠️ weeds-ey but important milestone ⚠️🌱
This is a first concrete example of the kind of analysis, reporting, and accountability that we’re aiming for as part of our Responsible Scaling Policy commitments on misalignment.
Technological Optimism and Appropriate Fear - an essay where I grapple with how I feel about the continued steady march towards powerful AI systems. The world will bend around AI akin to how a black hole pulls and bends everything around itself.
🧵 Haiku 4.5 🧵
Looking at the alignment evidence, Haiku is similar to Sonnet: Very safe, though often eval-aware.
I think the most interesting alignment content in the system card is about reasoning faithfulness…