Every Amber Notes meeting summary is an LLM call.
@amber_script put them all behind one Requesty integration:
> 40% lower AI cost per meeting
> 99.9% AI feature availability
> New models in minutes, not days
https://t.co/fUIcKaCXhP
Requesty is now a native provider plugin in Hermes Agent.
Add a fallback policy and when a provider goes down, your agent moves to the next model instead of stopping.
Change the chain in Requesty, not in your Hermes config.
https://t.co/jcqiUvwr9T
Claude Code. Cursor. Codex. curl.
All on your API keys. Do you know which ones?
New in Requesty: see every agent on every key, catch leaked keys, kill them in one click.
→ https://t.co/NTxNxymkx7
Keys leak. Make a leaked key useless off your network.
New on Requesty: Allowed IPs.
List the IPv4 addresses and CIDR ranges that may call Requesty for your org.
Anything else is rejected, on every endpoint, and every change lands in the audit trail.
A Jev decision through Requesty, median over the last 30 days:
Model: 241 ms
Requesty: 2.3 ms
That 2.3 ms is key auth, spend limits, approved-model and compliance checks, and rate limits. Under 1% of the request.
typesafe/jev-latest
Meta's Muse Spark Open is live on Requesty.
Open weights, 816B total / 42B active parameters, 1M context.
Meta built it for coding and long-horizon agentic work, and calls it the most capable US open-weight model to date.
model: muse-spark-open
Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio
Small one, but you kept asking for it.
Top up by card in USD, GBP, EUR, JPY or CNY, or iDEAL in EUR. It lands in your USD balance at the rate shown in checkout.
Auto top-up charges your card in its own currency too.
Morning spikes pushed NotarBot past provider quotas, and 429s stalled live calls. Rotating regions split the prompt cache.
Now: one stable endpoint, higher-limit deployments, cross-provider failover. Cache hits on nearly every turn.
https://t.co/dap6eQ9iP8
Gemini 4 Argon from @GoogleDeepMind is live on Requesty.
Google's new frontier model for coding, enterprise knowledge work and cyber defense. 1M context, up to 1M output tokens, with vision, tools and caching.
Served globally and from the EU.
Gemini 4 Argon is now globally available.
Built to solve your hardest problems from start to finish, the model brings frontier capabilities across coding, enterprise workflows, and cyber defense.
The fastest provider for a model changes all day.
Requesty's latency routing sends each new session to the fastest one, ranked on time to first token and throughput, corrected for errors.
Sessions stay pinned so your cache stays warm.
https://t.co/hzFvgjhOJS
We are happy to announce that we are now partnering with @RequestyAI 🚀
One shared conviction. European inference should be a routing decision, not a migration project.
Requesty routes 225B+ tokens a day through 600+ model endpoints. As of today, you'll be able to route GLM-5.3, GLM-5.3 Flash, DeepSeek V4.1 Flash and DeepSeek V4 Flash through the same endpoint and SDK your team already builds on, from $0.12 per 1M tokens.
Through Requesty's unified API and Melious' European infrastructure, teams can access high-performance inference while keeping their workloads in Europe.
No new integration. Just a European option.
This is what building a sovereign AI ecosystem looks like, one partner at a time.
#SovereignAI #EuropeanAI #OpenWeightModels #MeliousAI #Requesty
Meta's Muse Wonder is live on Requesty.
Built for long-running agentic work: memory across sessions, persistence through blockers, check-ins before important actions.
$4 in / $20 out per 1M tokens, $0.20 cache reads, 1M context.
model: muse-wonder-1.0
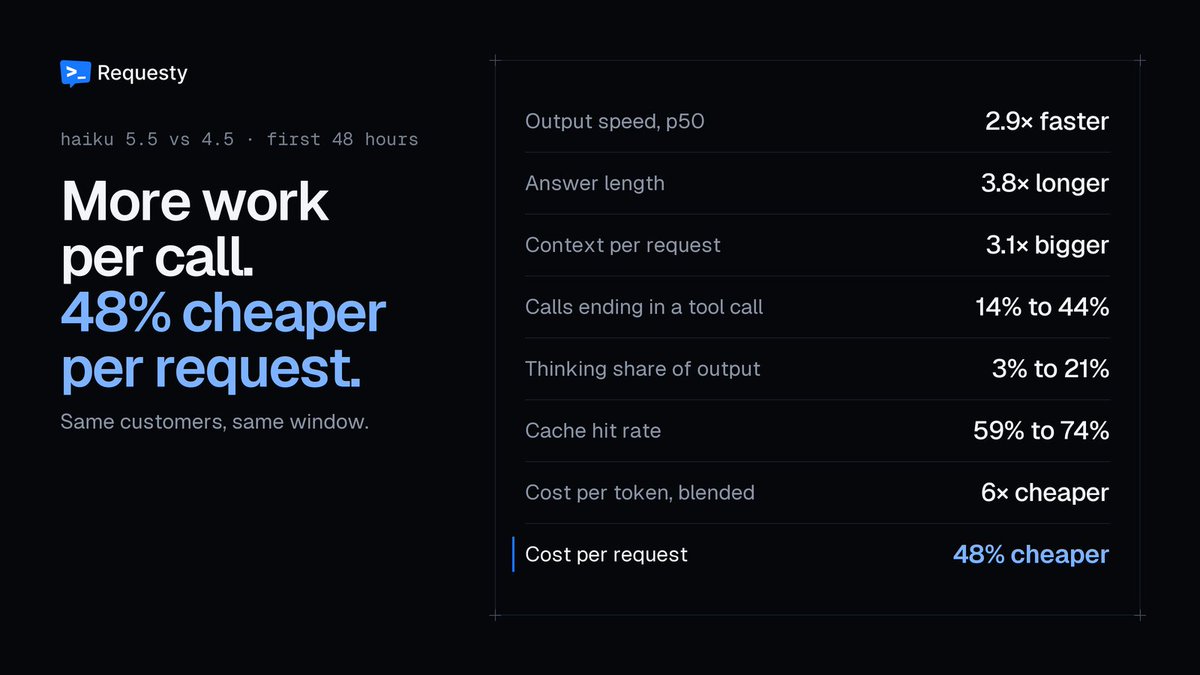
Haiku 5.5 vs Haiku 4.5, same customers, same window:
2.9x faster output
3.8x longer answers
3.1x more context per request
44% of calls end in a tool call (14% on 4.5)
21% of output is thinking (3% on 4.5)
And 48% cheaper per request.
Haiku 5.5 is the fastest Claude switch we've measured on Requesty.
It took 51% of all Haiku tokens in its first 46 hours.
Same window after launch:
> Opus 4.8: 32% of Opus tokens
> Opus 5.5: 19%
> Sonnet 5.5: 17%
> Opus 4.7: 7%
Claude 5.5 is a speed upgrade, not just a quality one.
p50 output speed on streaming Claude traffic through Requesty, Oct 8 to 11:
Haiku 5.5: 3.3x Haiku 4.5
Sonnet 5.5: 2.3x Sonnet 5
5 days after launch, Haiku 5.5 already carries 94% of Haiku tokens.
"Where did our prompts go, and who kept them?"
Requesty's new Compliance page answers that for every request: where the model was hosted, whether it retains or trains on data, and what scanning caught.
One click exports it as an evidence report.
https://t.co/FfSHuDsuBX